

Your Search Foundation Supercharged.
Your Search Foundation Supercharged.
_code_API
---
---
Start instantly—no credit card or registration needed!



































_smart\_display_How to get my API key?_groups_Our Customers
login
_key_API Key & Billing
_ _Reader
_ _Embeddings
_ _Reranker
chevron\_left chevron\_right
---
menu\_book_Docs_arrow\_drop\_down
chevron\_left chevron\_right
---
globe\_book
Use `r.jina.ai` to read a URL and fetch its content
travel\_explore
Use `s.jina.ai` to search the web and get SERP
Add `mcp.jina.ai` as your MCP server to access our API in LLMs
---
Parameters
arrow\_drop\_down
The target URL to fetch content from
Add API Key for Higher Rate Limit
Enter your Jina API key to access a higher rate limit. For latest rate limit information, please refer to the table below._open\_in\_new_Learn more
Browser Engine (Quality/Speed)
Choose the browser engine for fetching the webpage content. This affects the quality, speed, completeness, accessibility of the content._open\_in\_new_Learn more
Default
arrow\_drop\_down
Content Format
You can control the level of detail in the response to prevent over-filtering. The default pipeline is optimized for most websites and LLM input.
Default
arrow\_drop\_down
JSON Response
The response will be in JSON format, containing the URL, title, content, and timestamp (if available). In Search mode, it returns a list of five entries, each following the described JSON structure.
Timeout (seconds)
Maximum time to wait for page load. Increase for slow pages, decrease for simple static pages.
Token Budget
Limits the maximum number of tokens used for this request. Exceeding this limit will cause the request to fail.
Use ReaderLM-v2
Experimental
Uses ReaderLM-v2 for HTML to Markdown conversion, to deliver high-quality results for websites with complex structures and contents. Costs 3x tokens
Extract Only (CSS Selector)
Only extract content matching these CSS selectors. Example: article, .main-content, #post-body
body
.class
#id
Wait For (CSS Selector)
Wait until these elements appear before extracting content. Useful for dynamically loaded content.
body
.class
#id
Exclude (CSS Selector)
Remove these elements before extraction. Example: nav, footer, .sidebar, #ads
header
.class
#id
Remove All Images
Strip all images from the output. Reduces token usage when images are not needed.
OpenAI Citation Format
Format links for OpenAI's web browsing tool. Uses special citation markers compatible with GPT models._open\_in\_new_Learn more
Links Summary Section
A "Buttons & Links" section will be created at the end. This helps the downstream LLMs or web agents navigating the page or take further actions.
None
arrow\_drop\_down
Images Summary Section
An "Images" section will be created at the end. This gives the downstream LLMs an overview of all visuals on the page, which may improve reasoning.
None
arrow\_drop\_down
Browser Viewport Size
POST
Set browser window dimensions. Affects responsive layouts and content visibility._open\_in\_new_Learn more
Forward Cookie
Our API server can forward your custom cookie settings when accessing the URL, which is useful for pages requiring extra authentication. Note that requests with cookies will not be cached._open\_in\_new_Learn more
<cookie-name>=<cookie-value>
<cookie-name-1>=<cookie-value>; domain=<cookie-1-domain>
Image Caption
Captions all images at the specified URL, adding 'Image \[idx\]: \[caption\]' as an alt tag for those without one. This allows downstream LLMs to interact with the images in activities such as reasoning and summarizing.
Use a Proxy Server
Our API server can utilize your proxy to access URLs, which is helpful for pages accessible only through specific proxies._open\_in\_new_Learn more
Use a Country-Specific Proxy Server
Set country code for location-based proxy server. Use 'auto' for optimal selection or 'none' to disable.
Bypass Cached Content
Our API caches URL contents for a certain amount of time. Set it to true to ignore the cached result and fetch the content from the URL directly.
Cache Tolerance (seconds)
Accept cached content if younger than N seconds. Set to 0 for fresh content (same as Bypass Cache), or higher values to allow faster responses from cache.
Page Ready Timing
When to consider a page fully loaded. Later timings wait longer but capture more dynamic content.
Default
arrow\_drop\_down
Custom User-Agent
Override the browser User-Agent string. Useful for accessing sites that require specific browsers or block crawlers.
Custom Referer
Set the HTTP Referer header. Some sites check this to verify traffic comes from expected sources.
Preserve Base64 Images
Keep inline base64-encoded images in markdown output instead of converting them to external URLs.
Do Not Cache or Track
Prevent this request from being cached or logged on our servers. Use for sensitive URLs.
Github Flavored Markdown
Opt in/out features from GFM (Github Flavored Markdown).
Enabled
arrow\_drop\_down
Stream Mode
Stream mode is beneficial for large target pages, allowing more time for the page to fully render. If standard mode results in incomplete content, consider using Stream mode._open\_in\_new_Learn more
Customize Browser Locale
Control the browser locale to render the page. Lots of websites serve different content based on the locale._open\_in\_new_Learn more
Respect robots.txt
Check robots.txt rules before fetching. Specify which bot name to use for the check.
Include iframe Content
Extract content from embedded iframes. Enable for pages with content loaded in iframes.
Include Shadow DOM
Extract content from Shadow DOM components. Enable for pages using web components.
Use Final URL as Base
Resolve relative URLs using the final destination URL after redirects, instead of the original URL.
Local PDF/HTML file
POST
Use Reader on your local PDF and HTML file by uploading them. Only support pdf and html files. For HTML, please also specify a reference URL for better parsing related CSS/JS scripts.
upload
Run JavaScript Before Extraction
POST
Execute custom JS to modify the page before content extraction. Can be inline code or a URL to a script file._open\_in\_new_Learn more
Heading Style
Sets markdown heading format (passed to Turndown).
Hash Style
arrow\_drop\_down
Horizontal Rule Style
Defines markdown horizontal rule format (passed to Turndown).
Bullet Point Style
Sets bullet list marker character (passed to Turndown).
\*
arrow\_drop\_down
Emphasis Style
Defines markdown emphasis delimiter (passed to Turndown).
\_
arrow\_drop\_down
Strong Emphasis Style
Sets markdown strong emphasis delimiter (passed to Turndown).
\\
arrow\_drop\_down
Link Style
Determines markdown link format (passed to Turndown).
Inline
arrow\_drop\_down
EU Compliance
Experimental
All infrastructure and data processing operations reside entirely within EU jurisdiction.
---
upload
Request
GET
Bash
Language
arrow\_drop\_down
wrap\_text
curl "https://r.jina.ai/https://www.example.com" \
  -H "Authorization: Bearer jina_2623445ce8324868a5babcb734e21d5ffFb1tQzb-pewhabfvzU4D0mdtmko"
content\_copy
---
_send_GET RESPONSE
---
key
API key
visibility\_off content\_copy
---
Available tokens
10,000,000 sync
This is your unique key. Store it securely!

For Better Search
Our frontier models form the search foundation for high-quality enterprise search and RAG systems.

 ReaderConvert a URL to LLM-friendly input, by simply adding r.jina.ai in front.Get started_arrow\forward

 EmbeddingsWorld-class multimodal multilingual embeddings.Get started_arrow\forward
 RerankerWorld-class reranker for maximizing search relevancy.Get started_arrow\forward
Our Publications
Understand how our frontier search models were trained from scratch, check out our latest publications. Meet our team at EMNLP, SIGIR, ICLR, NeurIPS, and ICML!
 _arXiv May 11, 2026jina-embeddings-v5-omni: Text-Geometry-Preserving Multimodal Embeddings via Frozen-Tower Composition
 SIGIR 2026February 17, 2026jina-embeddings-v5-text: Task-Targeted Embedding Distillation
 arXiv February 11, 2026Embedding Inversion via Conditional Masked Diffusion Language Models
 ICLR 2026January 22, 2026Embedding Compression via Spherical Coordinates
 arXiv December 29, 2025Vision Encoders in Vision-Language Models: A Survey
 ICLR 2026December 04, 2025Jina-VLM: Small Multilingual Vision Language Model
 AAAI 2026October 01, 2025jina-reranker-v3: Last but Not Late Interaction for Document Reranking
 NeurIPS 2025August 31, 2025Efficient Code Embeddings from Code Generation Models
 EMNLP 2025June 24, 2025jina-embeddings-v4: Universal Embeddings for Multimodal Multilingual Retrieval
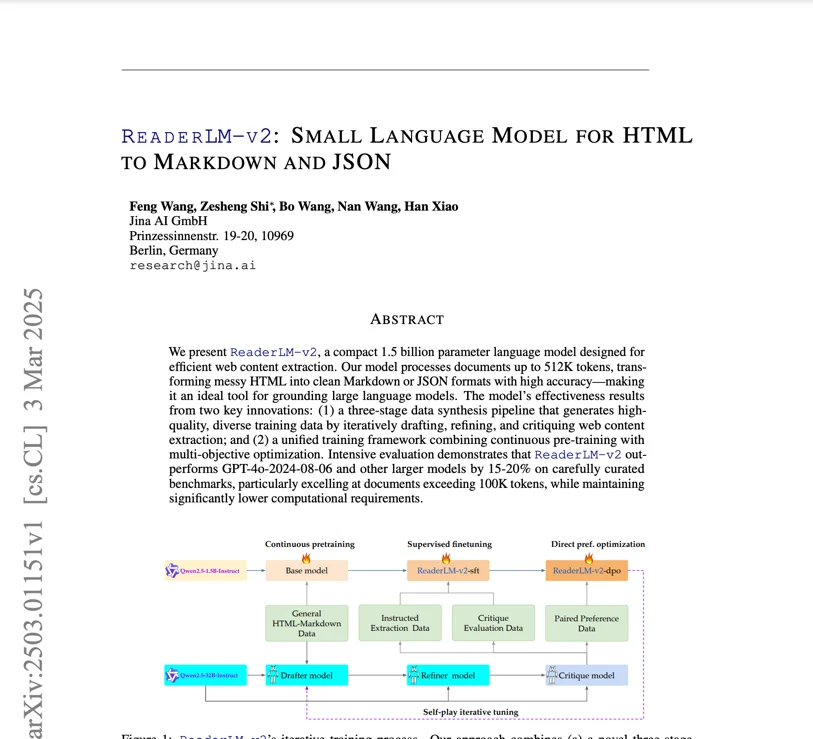 ICLR 2025March 04, 2025ReaderLM-v2: Small Language Model for HTML to Markdown and JSON
 ACL 2025December 17, 2024AIR-Bench: Automated Heterogeneous Information Retrieval Benchmark
 ICLR 2025December 12, 2024jina-clip-v2: Multilingual Multimodal Embeddings for Text and Images
 ECIR 2025September 18, 2024jina-embeddings-v3: Multilingual Embeddings With Task LoRA
 SIGIR 2025September 07, 2024Late Chunking: Contextual Chunk Embeddings Using Long-Context Embedding Models
 EMNLP 2024August 30, 2024Jina-ColBERT-v2: A General-Purpose Multilingual Late Interaction Retriever
 WWW 2025June 21, 2024Leveraging Passage Embeddings for Efficient Listwise Reranking with Large Language Models
 ICML 2024May 30, 2024Jina CLIP: Your CLIP Model Is Also Your Text Retriever
 arXiv February 26, 2024Multi-Task Contrastive Learning for 8192-Token Bilingual Text Embeddings
 arXiv October 30, 2023Jina Embeddings 2: 8192-Token General-Purpose Text Embeddings for Long Documents
 EMNLP 2023July 20, 2023Jina Embeddings: A Novel Set of High-Performance Sentence Embedding Models
20 publications in total.