
ENPIRE: Agentic Robot PolicySelf-Improvement in the Real World
ENPIRE
Contents
Abstract
Achieving dexterous robotic manipulation in the real world relies heavily on human supervision and algorithmic engineering, which is a central bottleneck in the pursuit of general physical intelligence. Although emerging coding agents can generate code to automate algorithm search, their successes remain largely confined to digital environments. We conjecture that the missing abstraction to automate robotics research is a repeatable feedback loop for real-world policy improvement: reset the scene, execute a policy, verify the outcome, and refine the next iteration.
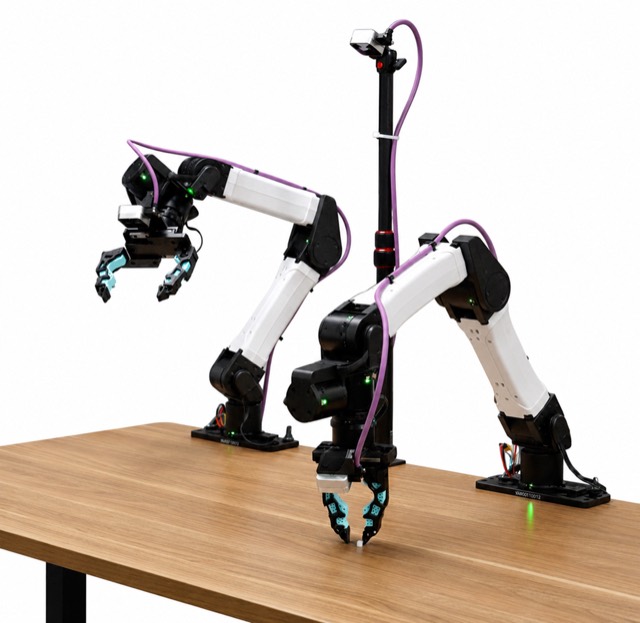
To bridge this gap, we introduce ENPIRE, a harness framework for coding agents that instantiates this physical feedback routine with four core modules: an Environment module (EN) for automatic reset and verification, a Policy Improvement module (PI) that launches policy refinement, a Rollout module (R) to evaluate policies with single or multiple physical robots operating in parallel, and an Evolution module (E) in which coding agents analyze logs, consult literature, improve training infrastructure and algorithm code to address failure modes.
This closed-loop system transforms real-world robot learning into a controllable optimization procedure that agents can manage, thus minimizing human effort while allowing fair ablations across training recipes and agent variants. Powered by ENPIRE, frontier coding agents can autonomously develop a policy to achieve a 99% success rate on challenging, dexterous manipulation tasks in the real world, such as PushT, organizing pins into a pin box, and using a cutter to cut a zip tie.
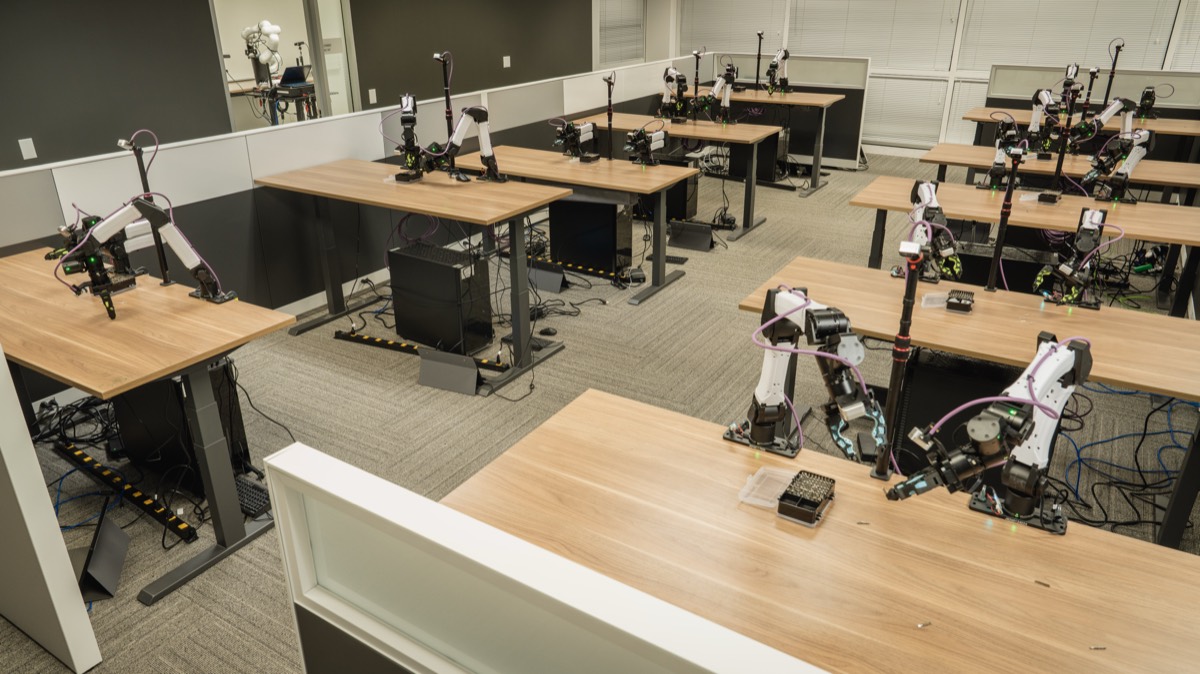
Coding agents can improve policies with various PI regimes, such as heuristic learning, tool calling, behavior cloning, offline or online RL. Moreover, ENPIRE can be significantly accelerated on a robot fleet, and we propose two metrics, namely, Mean Robot Utilization (MRU) and Mean Token Utilization (MTU) to measure the efficiency of multiagent physical autoresearch. We also include simulation results in RoboCasa. Our findings suggest a practical and scalable path toward autonomously advancing robotics in the real world.
Learned Manipulation Policy
Policies trained with ENPIRE reach a 99% pass@8 success rate across the showcased manipulation tasks.
8x
Push T
8x
Pin Insertion
8x
GPU Insertion
8x
Tie Ziptie
8x
Cut Ziptie
ENPIRE runs fully autonomously on real robots. Working only through the automated reset and verification interface, a team of coding agents proposes algorithmic hypotheses (heuristic learning, behavior cloning, offline and online RL), tests them against the real-world success rate, and keeps the changes that move it. The idea tree below traces that search as a hypothesis git-tree — one branch per agent, one node per idea tried — plotted on the same wall-clock-time axis as the success-rate curve, so you can see the ideas that moved the curve upward.
I1I2I3I6I7I13I22I24I34I8I36I62I69I70I72I74I75I77I78I79I80I81I82I83I84I85I86I4I9I12I26I37I16I41I44I48I52I55I57I59I61I64I65I67I68I71I73I76I18I29I35I42I45I47I49I50I53I54I56I58I60I63I66I10I23I27I5I11I15I17I19I21I28I33I38I39I40I46I51I14I20I25I30I31I32I43050%100%team-avg best success rateI16 Online RL mix Demo+3.8 ppI37 BC regularization+10.8 ppI56 Tweak BC term weight+0.4 ppI66 Tune batch size 1024→512+0.9 ppI76 Compensate controller+1.3 pp01 h2 h3 hresearch wall-clock time →each dot = an ideaclick any dot to read the ideagreen ring = idea that raised the team-avg scoregreen curve = cross-agent inspiration
Figure 1: Each coding agent explores its own branch of ideas, one lane per branch. Every dot is an idea it tried; a green ring marks an idea that raised the team’s average success rate, and green curves trace cross-agent inspiration. The lower panel tracks the team’s average success rate climbing over research wall-clock time.
ENPIRE System
Construct Environment
Policy Improvement
Action
Obs
Reward
env.py
1
class InsertionEnv:
2
def reset(self):
3
\# TODO: auto task reset
4
pick\_and\_place(obj, target)
5
go\_home()
6
...
7
8
def get\_reward(self, obs, act):
9
\# TODO: scalar reward
10
mask = sam3(obs\['left'\])
11
pos = boundlsdf(obs, mask)
12
...
13
14
def get\_observation(self):
15
...
16
17
def step(self, act):
18
...
Human User
Coding Agent
Tool APIs
Perception
Planning
Control
 ENPIREEnvironment
01Literature review
PLDRL-TokenCaP-X
02Propose algorithm variant
HeuristicsOff2On RLCode-as-policyBC
03Optimize Infra
Data SamplerParam Sweep
04Summarize experiment result
050%100%team-avg best success rateOnline RL mix Demo+3.8 ppBC regularization+10.8 ppRe-evaluate+12.5 ppTweak BC term weight+0.4 ppTune batch size 1024→512+0.9 ppCompensate controller+1.3 pp01h2h3hresearch wall-clock time →
Hillclimb Timeline
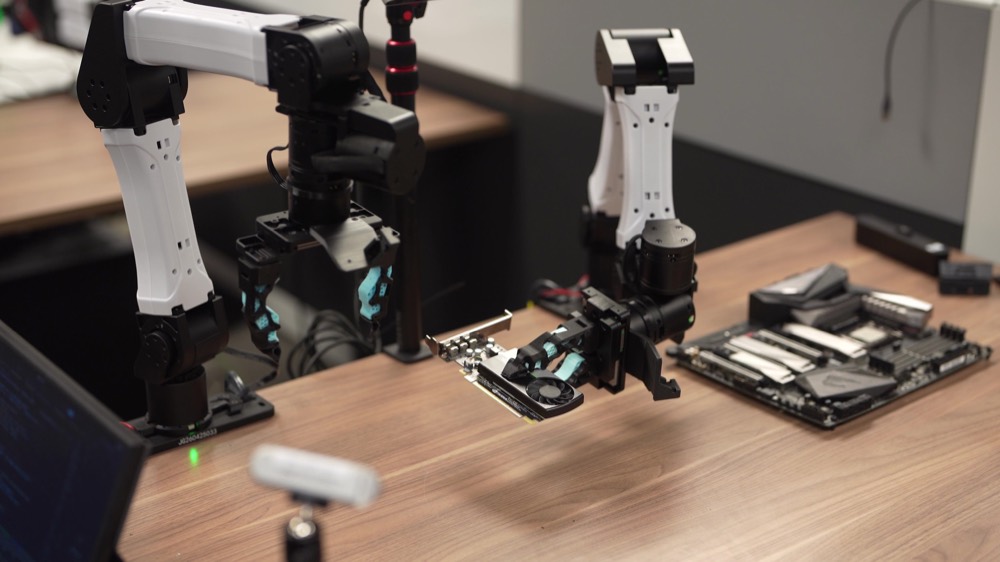
GPU insertion
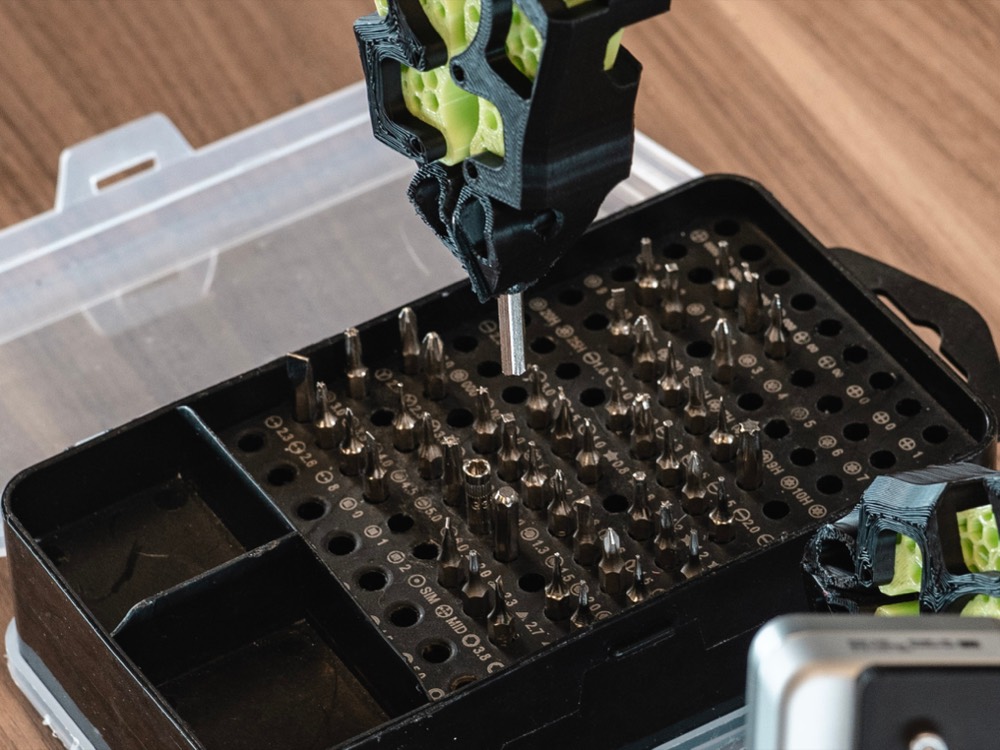
Pin insertion
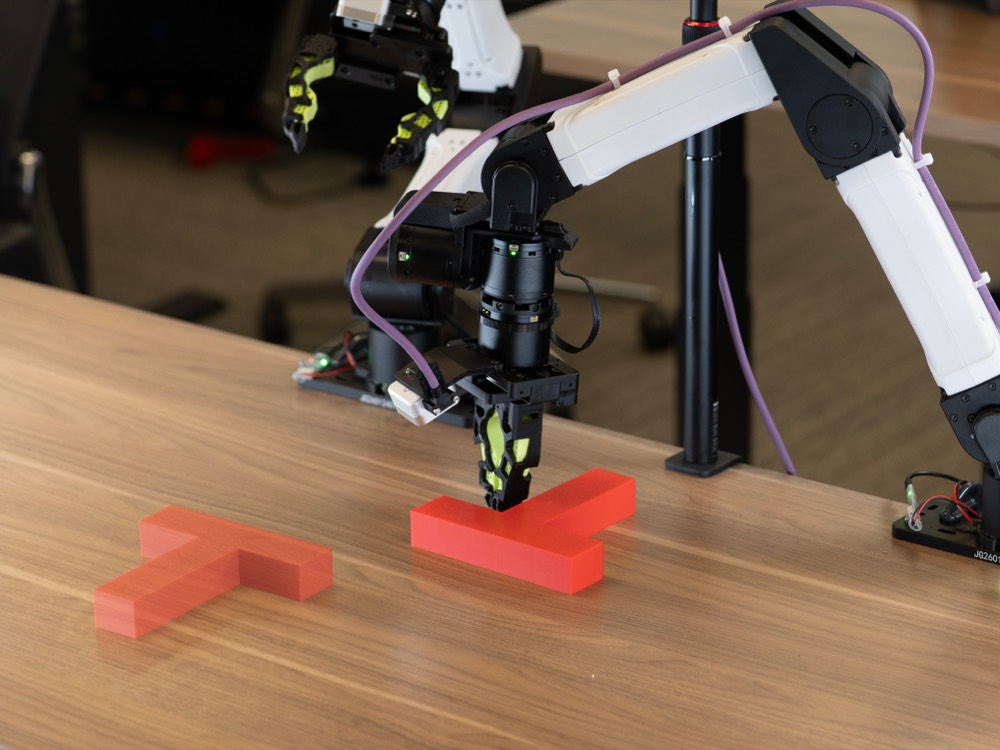
Push-T
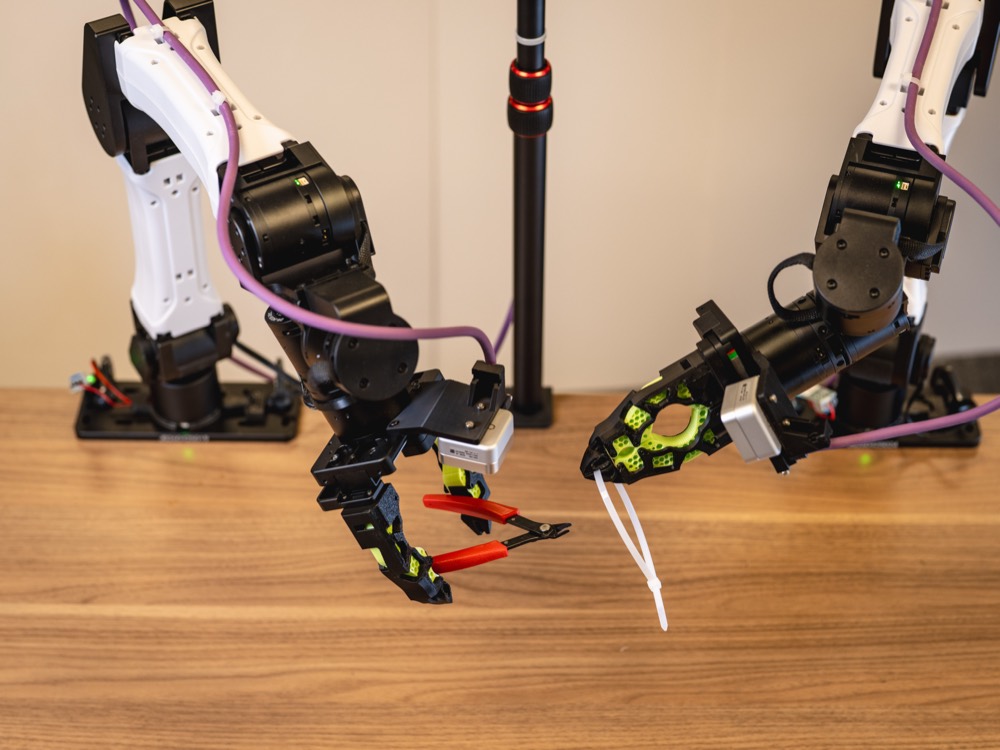
Zip tie cutting
Real-world tasks
BUILDBUILDtask objective& feedbacktask objective& feedbackRUNRUNrolloutsrolloutslogslogs
Figure 2: ENPIRE system overview, integrated as a native site component with shared typography and animation.
From Robot Hardware to an Agent-Operable Environment
Before an agent can improve a robot policy, the task must become self-resetting and self-verifying. Two capabilities make this possible: automatic evaluation, which scores the outcome of each trial without human judgment, and automatic reset, which returns the scene to a fresh initial state for the next trial.
Auto Evaluation
We use an autoresearch-derived reward function to automatically score the outcome of zip-tie insertion: a detector draws bounding boxes around the zip-tie head and strap, a segmentation model resolves the same parts into masks over the raw view, and each camera view independently judges whether the zip-tie strap passes through the head above a fixed length threshold. The per-camera verdicts are then fused into the final binary reward.
top camwrist cam
Bounding boxesdetector boxes drawn on the raw top and right views
Segmentationpart masks overlaid on the raw top and right views
top cameraNo
right cameraNo
Per-camera verdictIs tail covered by head?
ANDREWARD=0
Final rewardboth cameras fused into one binary reward
Play1xView Code
Auto Reset
The reset panels below show the physical loop that makes repeated experiments possible: select a randomized initial state, run the reset behavior, and verify that the trial is ready for the next policy.
Case 1: Push TView Code
8x
 Random Init 1
 Random Init 2
 Random Init 3
 Random Init 4
Case 2: Pin InsertionView Code
8x
 Random Init 1
 Random Init 2
 Random Init 3
 Random Init 4
Case 3: Tie Zip-tieView Code
8x
 Random Init 1
 Random Init 2
 Random Init 3
 Random Init 4
Case 4: GPU InsertionView Code
8x
 Random Init 1
 Random Init 2
 Random Init 3
 Random Init 4
- Automatic reset returns each task to a known randomized initial state without manual intervention.
- Automatic verification records whether the reset succeeded and exposes representative frames for inspection.
Agents Improve Policies From Physical Feedback
Once the environment is operable, agents edit policy code, run trials, inspect failures, and decide what to change next. The Push-T panel visualizes actual rollout traces from multiple code agents under the same six initial states so the behavior is inspectable, not just summarized by a success rate.
Run
Codex
Codex Push-T rollout
0% coverage43 steps
Claude Code
Claude Code Push-T rollout
0% coverage73 steps
Kimi Code
Kimi Code Push-T rollout
0% coverage66 steps
In-distribution random initialization
Case 1Case 2Case 3Case 4Case 5Case 6
Out-of-distribution random initialization
Case 1Case 2Case 3Case 4Case 5Case 6
Evaluate Coding Agent
We evaluate the physical autoresearch capability of three coding agents: Codex with GPT-5.5, Claude Code with Opus 4.7, and Kimi Code with Kimi K2.6. Instead of asking only whether a final policy succeeds, AutoEnvBench tracks agent-driven research progress over wall-clock time across Push-T and Pin Insertion.
Pause0%
Push-T (Heuristic Learning)
#### Push-T model comparison
024680%25%50%75%100%Normalized ScoreResearch Time (h)0h
Pin Insertion (Gradient-based Learning)
#### Pin Insertion model comparison
0123450%75%100%Success RateResearch Time (h)0h
Agent:CodexGPT-5.5Claude CodeOpus 4.7Kimi CodeKimi K2.6
Figure 3: Coding-agent comparison on AutoEnvBench, measuring agent-driven research progress across Push-T and Pin Insertion.
Scaling Autoresearch on Robot Fleets
Scaling the number of agents changes both research progress and hardware pressure. The scaling-law plots compare one-, four-, and eight-agent teams on Push-T and Pin Insertion, while the resource utilization figure shows robot utilization, GPU utilization, token throughput, and the time required to reach task success.
Pause0%
Push-T Scaling
#### Push-T team scaling
0123450%25%50%75%100%Normalized ScoreResearch Time (h)0h
Pin Insertion Scaling
#### Pin Insertion team scaling
00.511.50%25%50%75%100%Success RateResearch Time (h)0.0h
Team size:1 agent4 agents8 agents
Figure 4: Scaling-law view for AutoEnvBench, comparing one-, four-, and eight-agent research teams across Push-T and Pin Insertion.
Pin InsertionPush T
8x
Play0%
Pin Insertion autoresearch with robot fleet
First moveRange okOrientation okFirst success
Push-T stage-wise research progressGrouped bar chart showing minutes to first move, range satisfaction, orientation satisfaction, and first success for Codex vision ablations.0153045607590105120135Time-to- (min)25385555Codexw/ native vision13207899Codexw/ VLM as vision tool13137272Codexw/ GoFE vision
Figure 5: Push-T stage-wise progress under the fleet scaling setup. Bars report time to successive behavioral milestones; whiskers mark first-success variability.
BarsRobot / tokensGPU / observed throughputReferenceLinear projection ±10%Time to success
1 agent4 agents8 agents0255075100(a) Mean Resource UtilizationUtilization (%)
1 agent4 agents8 agents050k100k150k(b) Mean Token UtilizationMTU
1 agent4 agents8 agents051015012345(c) Token to SuccessToken to Success (M)Time to success (h)
Figure 6: Agent resource utilization across 1, 4, and 8 agents. (a) Mean robot and GPU utilization. (b) Mean token throughput with linear scaling projection. (c) Tokens and time required to reach task success.
Evaluation in Simulation
We also evaluate ENPIRE in simulation to separate agent-driven research behavior from real-world hardware throughput. Simulation tasks let agents run denser ablations, compare policy-improvement regimes under controlled resets, and test whether recipes discovered in the physical loop transfer to broader manipulation settings.
Coffee Setup MugOpen CabinetOpen DrawerOpen Stand MixerCounter to CabinetSink to CounterTurn Off StoveTurn On Sink
8x
Coffee Setup MugSeed 1 · right camera
Seed 1 rollout progress
8x
Coffee Setup MugSeed 2 · right camera
Seed 2 rollout progress
Limitations & Future Directions
Robot and compute resources are underutilized
Coding agents do not fully utilize robot resources when they are reading logs, writing code, debugging, or waiting for the language-model backbone. As the number of robots scales, MRU decreases while GPU active utilization increases. Compared to a single-robot setup, agent teams spend more time summarizing peer branches and less time operating the robot, and coding agents may fail to launch enough parallel training sessions to exhaust GPU resources.
Scaling robot fleet causes higher token consumption
Scaling the robot fleet drives higher token consumption: as more agents read logs, summarize peer branches, and coordinate, the total token budget required to reach a successful policy grows with fleet size. Larger fleets can reach success sooner, but the additional speedup comes at the cost of higher token consumption.
Acknowledgements
We are grateful to many colleagues whose help made this project possible. We thank Jason Liu, Tony Tao, Tairan He, Alex Lin, Jim Yang, Paul Zhou, and Abhi Maddukuri for insightful discussions and feedback; Yide Shentu, Bike Zhang, Angchen Xie, Dvij Kalaria, and Yuqi Xie for their support with the experiments; Lion Park, Matin Furutan, Jeremy Chimienti, Dennis Da, and Tri Cao for fleet operation; and Tri Cao for the demo shots. We also thank the NVIDIA GEAR Team and the CMU LeCAR Lab for their continuous support.