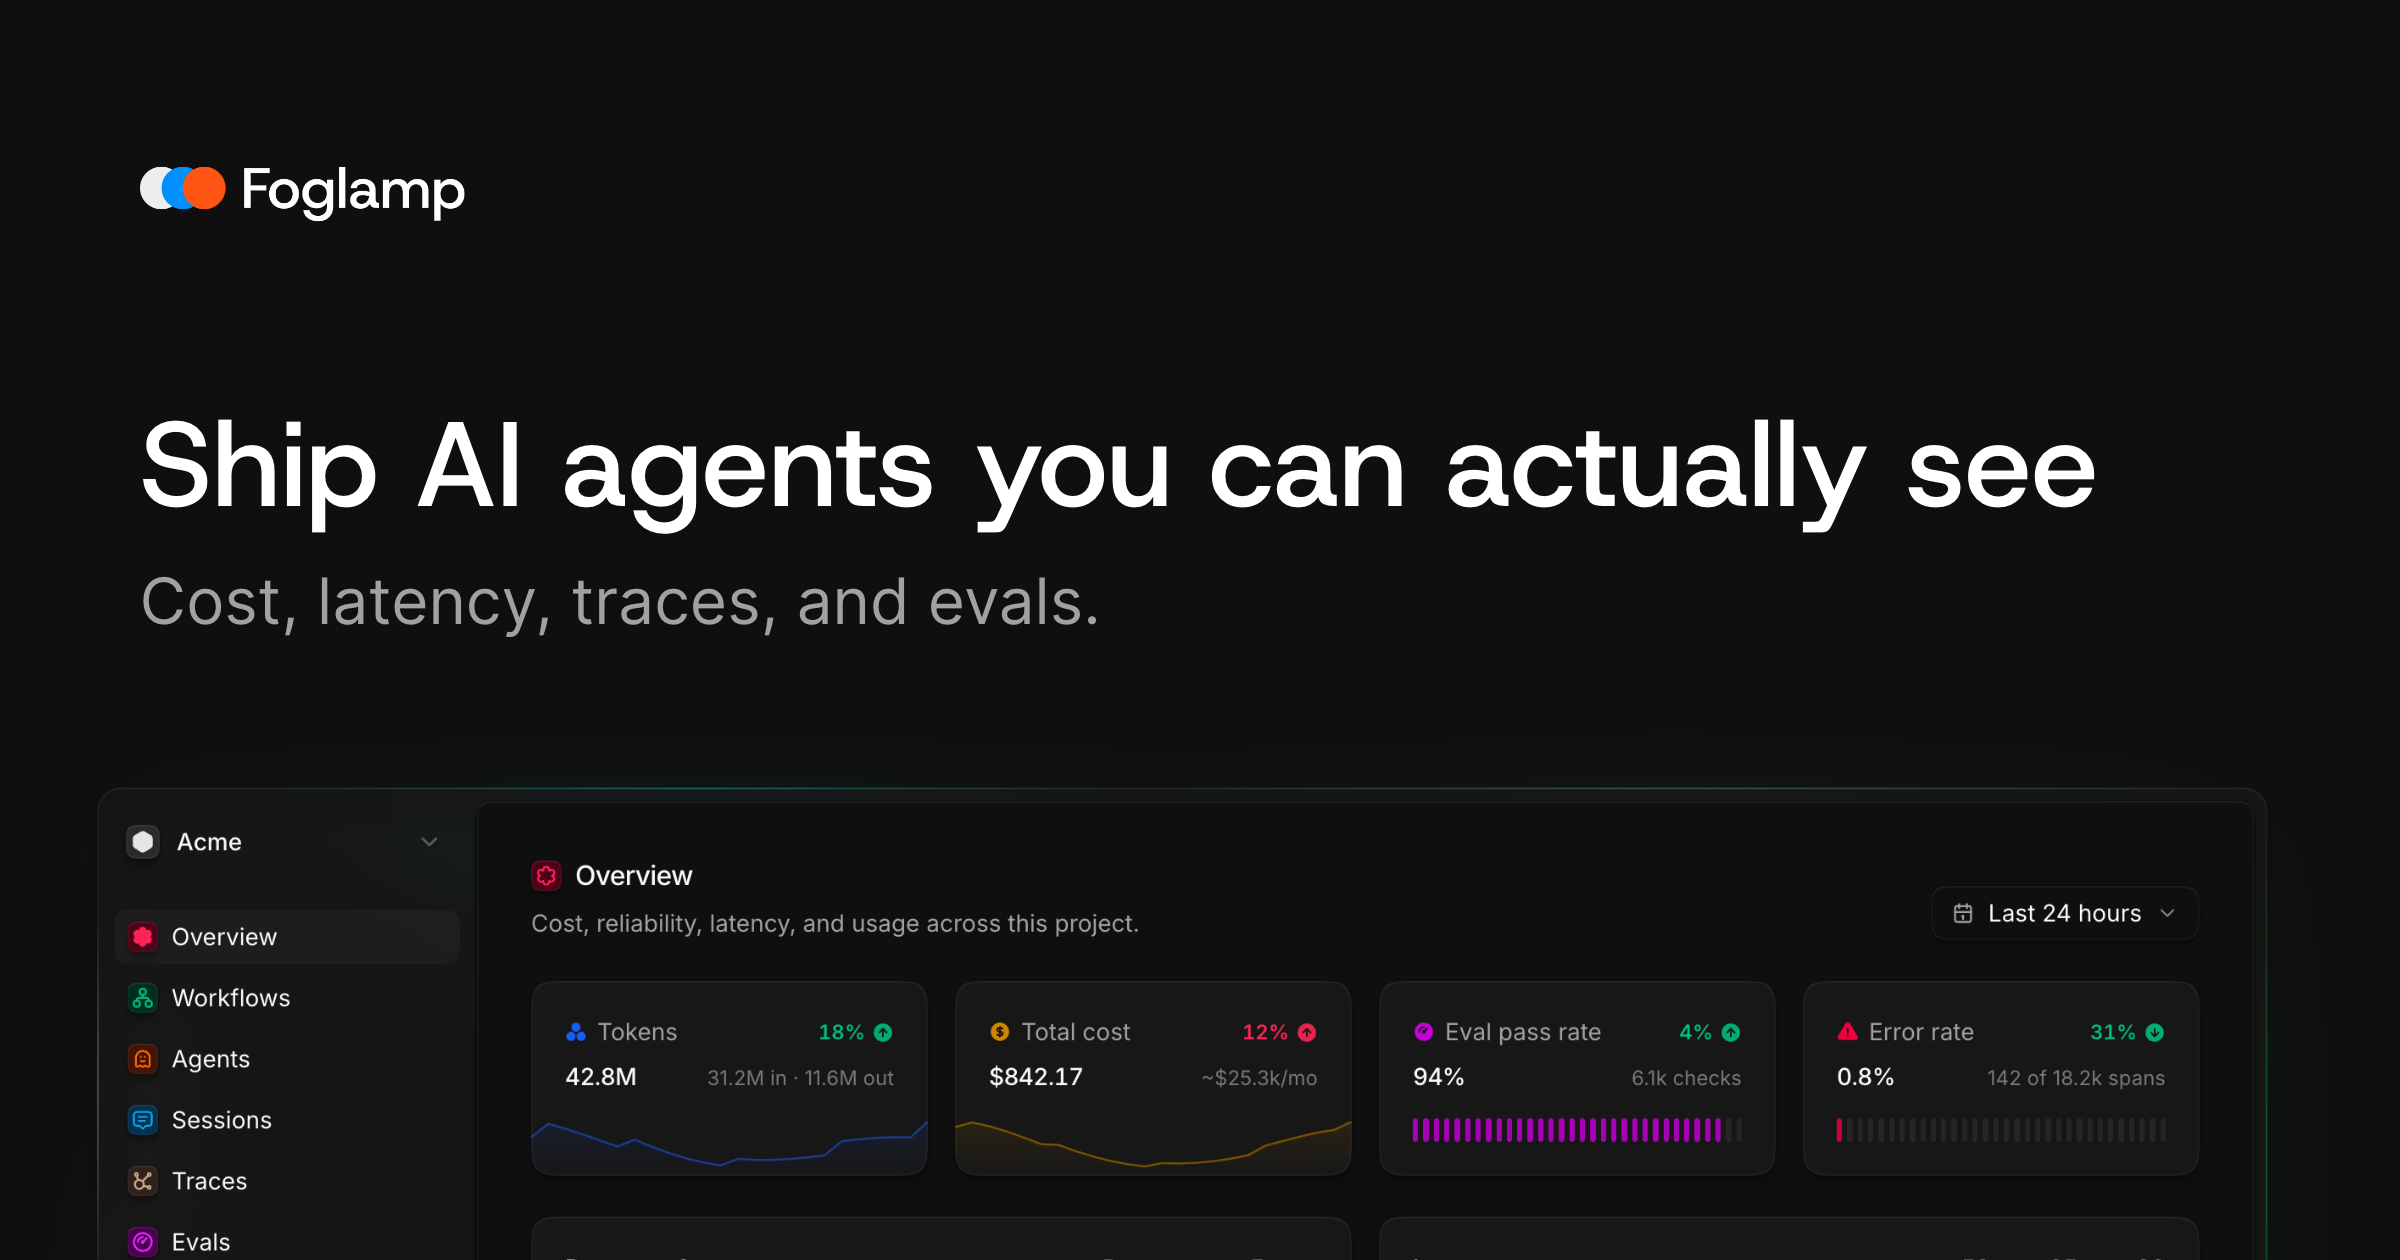
Ship AI agents you can actually see
Ship AI agents you can actually see
See the cost, latency, and quality of every LLM call. Catch bad output before your users do.
Copy agent prompt
| Tailor made for
“Caught a 10× cost regression 3 days after shipping. Foglamp paid for itself in week one.”
GGustavo Fior· Co-founder @ Foglamp yes, it's me :)
1. Week 1Ships clean. 2. Week 3Costs doubled, answers worse. 3. ThenCustomers start complaining.
Dana#support2m
the assistant just quoted a refund window we killed in March 😤
+1 (415) 555-0148Customer6m
is this a bot? it gave me an order number that doesn't exist
@jordanbuilds12.4k followers14m
@acme your “AI support” confidently invented a tracking link. yikes.
maracommunity21m
anyone else getting totally wrong answers from the bot today??
One SDK in. Everything out.
Instrument once. Get cost, traces, evals, alerts, and per-agent spend on every call.
SDK
Two lines instruments every generateText / streamText call.
import { foglamp } from "foglamp"const fog = foglamp()
Agents
Per-agent spans, latency, and spend - with the full call flow.
orchestrator2.42.4s
researchersearch()
writerqueued
criticqueued
Evals
Score production traffic with code checks and LLM judges.
No PII
Pass rate:94%94%
Distributed traces
Waterfall every run, with the exact prompt and response per span.
Alerts
Threshold rules on cost, latency, and error rate.
Latency 440440ms
Cost intelligence
Know exactly what every call costs — by model, agent, customer.
ClaudeClaude Opus 4.8$323.12
GeminiGemini 3.5 Pro$43.06
GPT-5.5 mini$85.05
Total$1,248.50$1,248.50
Your agents are running in the fog.
Cost, latency, errors, eval scores — all there, all invisible. Wrap your model and turn the light on.
Copy agent prompt