AI Research Papers
AI Research Papers
Dive into the latest AI and agent engineering research papers. Sign up to join our paper readings and author office hours, or learn from prior readings on demand.
Explore More AI Research
Stay up to date with the latest breakthroughs in AI.
[](https://arize.com/blog/cuga-agent-from-benchmarks-to-business-impact-of-ibms-generalist-agent/)
Deploying IBM Generalist Agent in Enterprise Production
IBM researchers discuss Computer Using Generalist Agent (CUGA), which has been open-sourced for the community.
[](https://arize.com/blog/google-tumix-ai-agent-paper-explained-by-its-author/)
TUMIX: Multi-Agent Test-Time Scaling with Tool-Use Mixture
Google and MIT researcher covers TUMIX; achieves significant gains over SOTA tool-augmented and test-time scaling methods
[](https://arize.com/blog/meta-ai-researcher-explains-are-and-gaia2/)
ARE: scaling up agent environments and evaluations
Meta AI Researcher Explains ARE and Gaia2: Scaling Up Agent Environments and Evaluations
[](https://arize.com/blog/servicenows-tara-bogavelli-on-agentarch-benchmarking-ai-agents-for-enterprise-workflows/)
AgentArch: Benchmarking AI Agents for Enterprise Workflows
ServiceNow’s Tara Bogavelli on AgentArch: Benchmarking AI Agents for Enterprise Workflows
[](https://arize.com/blog/meta-ai-researcher-explains-are-and-gaia2/)
Why Language Models Hallucinate
OpenAI: Why Language Models Hallucinate
[](https://arize.com/blog/nvidias-small-language-models-are-the-future-of-agentic-ai-paper/)
Small Language Models are the Future of Agentic AI
NVIDIA’s Peter Belcak distills why small language models are the future of agentic AI.
[](https://arize.com/blog/verizons-stan-miasnikov-on-his-paper-category-theoretic-analysis-of-inter-agent-communication-and-mutual-understanding-metric-in-recursive-consciousness/)
Verizon’s Stan Miasnikov Walks Through His Latest Paper On Inter-Agent Communication
Presents an extension of a recursive consciousness framework to analyze communication between agents and the inevitable loss of meaning in translation
[](https://arize.com/blog/a-watermark-for-large-language-models/)
A Watermark for Large Language Models
Proposed LLM watermark that can be embedded with negligible impact on text quality.
[](https://arize.com/blog/self-adapting-language-models-paper-authors-discuss-implications/)
Self-Adapting Language Models
A novel method for enabling LLMs to adapt their own weights using self-generated data and training directives
[](https://arize.com/blog/accurate-kv-cache-quantization-with-outlier-tokens-tracing/)
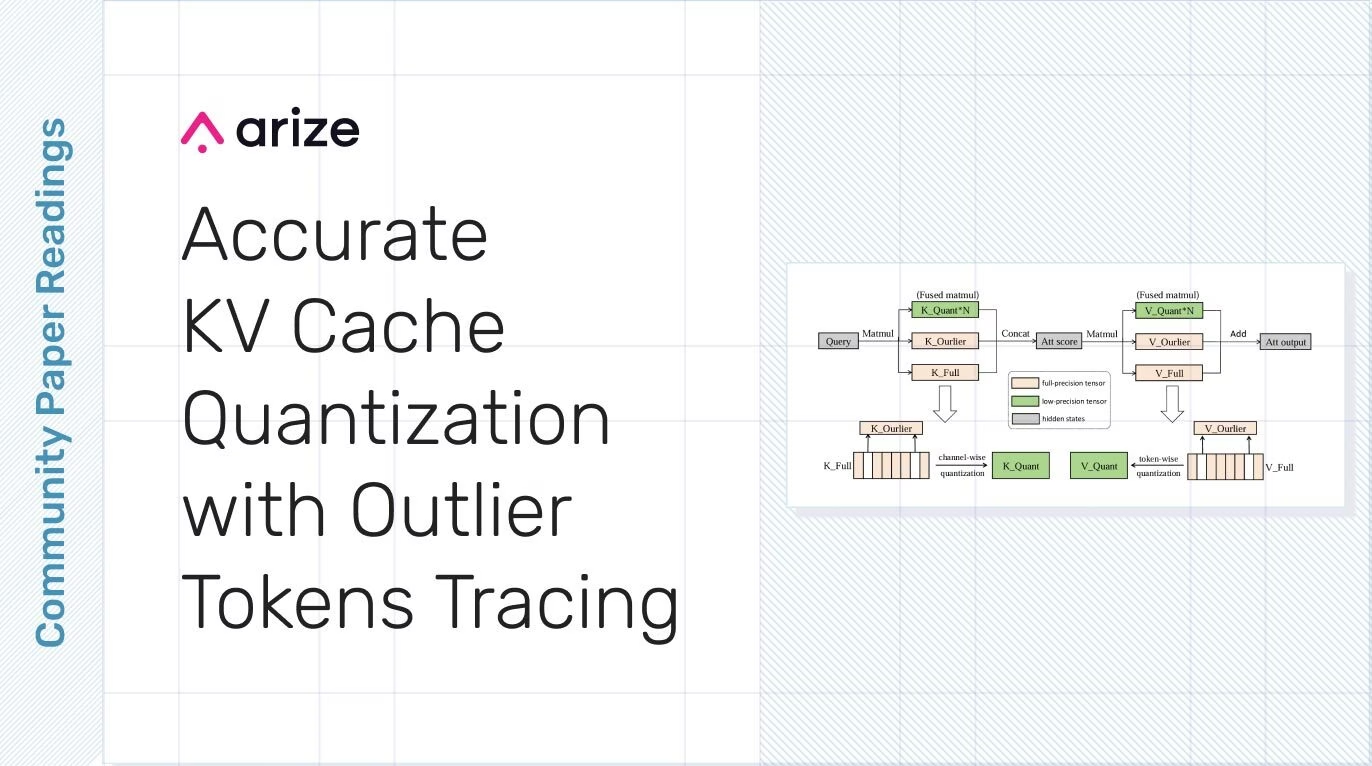
Accurate KV Cache Quantization with Outlier Tokens Tracing
Researchers propose a smarter way to compress the KV Cache while preserving model quality.
[](https://arize.com/blog/scalable-chain-of-thoughts-via-elastic-reasoning/)
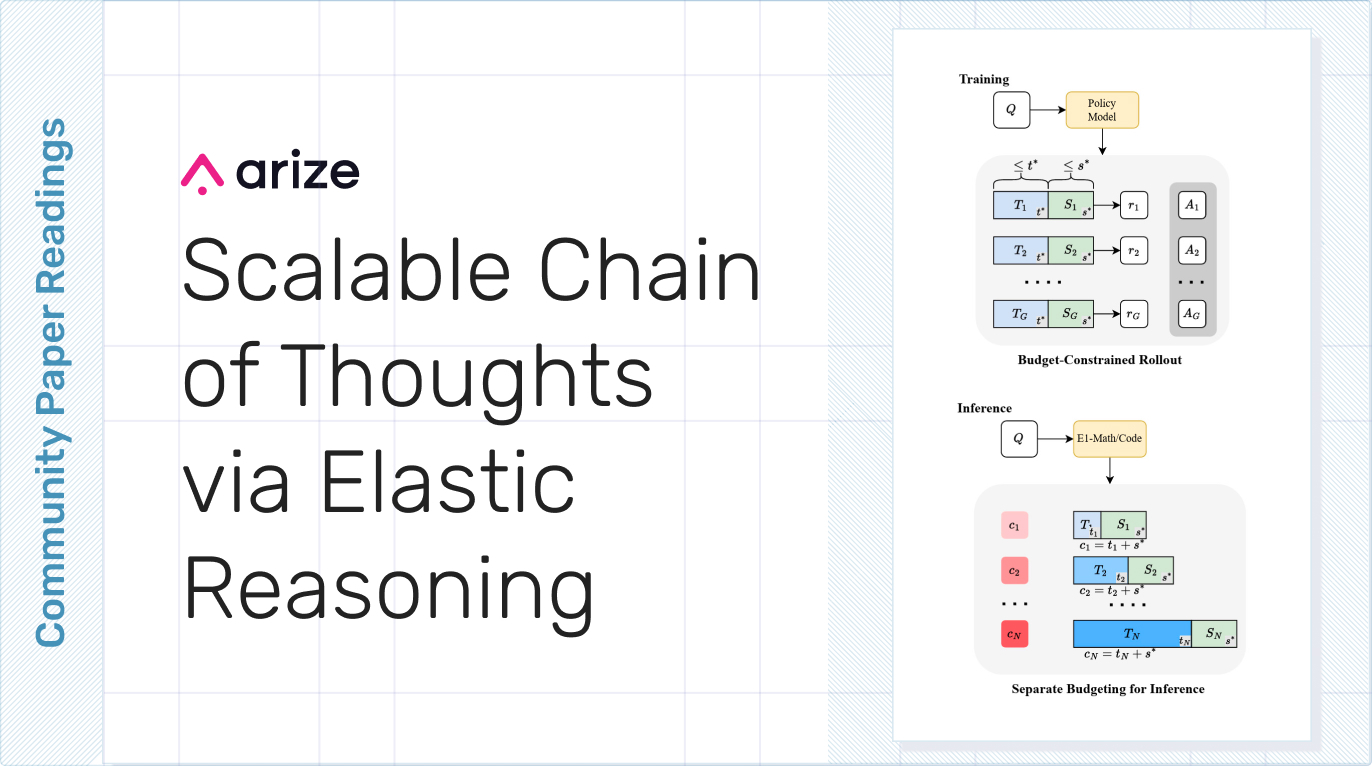
Scalable Chain of Thoughts via Elastic Reasoning
Elastic Reasoning, a novel framework designed to enhance the efficiency and scalability of large reasoning models (LRMs) by explicitly separating the reasoning process into two distinct phases: thinking and solution.
[](https://arize.com/blog/sleep-time-compute-beyond-inference-scaling-at-test-time/)
Sleep-time Compute: Beyond Inference Scaling at Test-time
We recently discussed “Sleep Time Compute: Beyond Inference Scaling at Test Time,” new research from the team at Letta.
[](https://arize.com/blog/merge-ensemble-and-cooperate-a-survey-on-collaborative-llm-strategies/)

Merge, Ensemble, and Cooperate! A Survey on Collaborative LLM Strategies
LLMs have revolutionized natural language processing, showcasing remarkable versatility and capabilities. But individual LLMs often exhibit distinct strengths and weaknesses, influenced by differences in their training corpora. This diversity poses a challenge: how can we maximize the efficiency and utility of large language models?
[](https://arize.com/blog/agent-as-a-judge-evaluate-agents-with-agents/)

Agent-as-a-Judge: Evaluate Agents with Agents
This week we dive into a paper that presents the “Agent-as-a-Judge” framework, a new paradigm for evaluating agent systems.
[](https://arize.com/blog/introduction-to-open-ai-realtime-api/)

Introduction to OpenAI’s Realtime API
We break down OpenAI’s realtime API. Sally-Ann DeLucia and Aparna Dhinakaran cover how to seamlessly integrate powerful language models into your applications for instant, context-aware responses that drive user engagement.
[](https://arize.com/blog/model-context-protocol/)
Model Context Protocol (MCP) from Anthropic
Want to learn more about Anthropic’s groundbreaking Model Context Protocol (MCP)? We break down how this open standard is revolutionizing AI by enabling seamless integration between LLMs and external data sources, fundamentally transforming them into capable, context-aware agents.
[](https://arize.com/blog/how-deepseek-is-pushing-the-boundaries-of-ai-development/)
How DeepSeek is Pushing the Boundaries of AI Development
How do you train an AI model to think more like a human? That’s the challenge DeepSeek is tackling with its latest models, which push the boundaries of reasoning and reinforcement learning.
[](https://arize.com/blog/multiagent-finetuning-a-conversation-with-researcher-yilun-du/)

Multiagent Finetuning: A Conversation with Researcher Yilun Du
This week we were excited to talk to Google DeepMind Senior Research Scientist (and incoming Assistant Professor at Harvard), Yilun Du, about his latest paper “Multiagent Finetuning: Self Improvement with Diverse Reasoning Chains.”
[](https://arize.com/blog/swarm-openai-experimental-approach-to-multi-agent-systems/)

Swarm: OpenAI’s Experimental Approach to Multi-Agent Systems
As multi-agent systems grow in importance for fields ranging from customer support to autonomous decision-making, OpenAI has introduced Swarm, an experimental framework that simplifies the process of building and managing these systems.
[](https://arize.com/blog/breaking-down-reflection-tuning-enhancing-llm-performance-with-self-learning/)

Breaking Down Reflection Tuning: Enhancing LLM Performance with Self-Learning
A recent announcement on X boasted a tuned model with pretty outstanding performance, and claimed these results were achieved through reflection tuning.
[](https://arize.com/blog/composable-interventions-for-language-models/)

Composable Interventions for Language Models
[](https://arize.com/blog/judging-the-judges-llm-as-a-judge/)

Judging the Judges: Evaluating Alignment and Vulnerabilities in LLMs-as-Judges
[](https://arize.com/blog/extending-the-context-window-of-llama-models)
Extending the Context Window of LLaMA Models Paper Reading
[](https://arize.com/blog/dspy-assertions-computational-constraints/)
DSPy Assertions: Computational Constraints for Self-Refining Language Model Pipelines
[](https://arize.com/blog/raft-adapting-language-model-to-domain-specific-rag/)
RAFT: Adapting Language Model to Domain Specific RAG
[](https://arize.com/blog/llm-interpretability-and-sparse-autoencoders-openai-anthropic/)
LLM Interpretability and Sparse Autoencoders: Research from OpenAI and Anthropic
[](https://arize.com/blog/trustworthy-llms-a-survey-and-guideline-for-evaluating-large-language-models-alignment/)
Trustworthy LLMs: A Survey and Guideline for Evaluating Large Language Models’ Alignment
[](https://arize.com/blog/breaking-down-evalgen-who-validates-the-validators/)
Breaking Down EvalGen: Who Validates the Validators?
[](https://arize.com/blog/keys-to-understanding-react/)

Keys To Understanding ReAct: Synergizing Reasoning and Acting in Language Models
[](https://arize.com/blog/demystifying-chronos-learning-the-language-of-time-series/)

Demystifying Amazon’s Chronos: Learning the Language of Time Series
[](https://arize.com/blog/anthropic-claude-3/)

Anthropic Claude 3
[](https://arize.com/blog/reinforcement-learning-in-the-era-of-llms/)
Reinforcement Learning in the Era of LLMs
[](https://arize.com/blog/rag-vs-fine-tuning)
Sora: OpenAI’s Text-to-Video Generation Model
[](https://arize.com/blog/phi-2-model)
Phi-2 Model
[](https://arize.com/blog/mistral-ai)
Mistral AI (Mixtral-8x7B): Performance, Benchmarks
[](https://arize.com/blog/how-to-prompt-llms-for-text-to-sql)

How to Prompt LLMs for Text-to-SQL
[](https://arize.com/blog/the-geometry-of-truth-emergent-linear-structure-in-llm-representation-of-true-false-datasets)

The Geometry of Truth: Emergent Linear Structure in LLM Representation of True/False Datasets
[](https://arize.com/blog/towards-monosemanticity/)

Towards Monosemanticity: Decomposing Language Models With Dictionary Learning
[](https://arize.com/blog/rank-vicuna)
RankVicuna: Zero-Shot Listwise Document Reranking with Open-Source Large Language Models
[](https://arize.com/blog/explaining-grokking-through-circuit-efficiency-paper-reading/)
Explaining Grokking Through Circuit Efficiency
[](https://arize.com/blog/large-content-and-behavior-models-paper-reading/)
Large Content And Behavior Models to Understand, Simulate, and Optimize Content and Behavior.
[](https://arize.com/blog/skeleton-of-thought-llms-can-do-parallel-decoding-paper-reading/)
Skeleton of Thought: LLMs Can Do Parallel Decoding Paper Reading
[](https://arize.com/blog/extending-the-context-window-of-llama-models)
Extending the Context Window of LLaMA Models Paper Reading
[](https://arize.com/blog/llama-2-open-foundation-and-fine-tuned-chat-models-paper-reading/)

Llama 2: Open Foundation and Fine-Tuned Chat Models Paper Reading
[](https://arize.com/blog/lost-in-the-middle-how-language-models-use-long-contexts-paper-reading/)

Lost in the Middle: How Language Models Use Long Contexts Paper Reading
[](https://arize.com/blog/orca-progressive-learning-from-complex-explanation-traces-of-gpt-4-paper-reading/)
Orca: Progressive Learning from Complex Explanation Traces of GPT-4 Paper Reading
[](https://arize.com/blog/generalized-lora-glora)
One-for-All: Generalized LoRA for Parameter-Efficient Fine-tuning
[](https://arize.com/blog/hyde-precise-zero-shot-dense-retrieval)
HyDE: Precise Zero-Shot Dense Retrieval without Relevance Labels
[](https://arize.com/blog/voyager-an-open-ended-embodied-agent-with-llms-paper-reading-and-discussion/)
Voyager: An Open-Ended Embodied Agent with LLMs Paper Reading and Discussion
[](https://arize.com/blog/retrieval-augmented-generation-paper-reading-and-discussion/)
Retrieval-Augmented Generation – Paper Reading and Discussion
[](https://arize.com/blog/lora-low-rank-adaptation-of-large-language-models-paper-reading-and-discussion/)
LoRA: Low-Rank Adaptation of Large Language Models Paper Reading and Discussion
[](https://arize.com/blog/drag-your-gan-interactive-point-based-manipulation-on-the-generative-image-manifold)
Drag Your GAN: Interactive Point-Based Manipulation on the Generative Image Manifold
[](https://arize.com/blog/lima-less-is-more-for-alignment-paper-reading-and-discussion/)
LIMA: Less Is More for Alignment – Paper Reading and Discussion
[](https://arize.com/blog/hungry-hungry-hippos-h3-state-space-models/)
Hungry Hungry Hippos (H3) and Language Modeling with State Space Models
[](https://arize.com/blog/toolformer-large-language-model-meta-ai/)

Toolformer: Training LLMs To Use Tools
[](https://arize.com/blog/openai-on-rlhf/)
OpenAI on Reinforcement Learning With Human Feedback (RLHF)
Show all
#### Top AI research papers
| Source | Why Language Models Hallucinate | Description | Shows the math and evaluation choices that underlie LLM hallucinations. | | ------ | -------------------------------------------------------------------------------------------- | ----------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------- | | Source | ARE and Gaia2 | Description | Gaia2 is a new AI agent benchmark that checks write actions — the ones that modify the world (like sending an email) — and don’t explicitly verify pure reads. |
#### Recommended resources
 Prompt Learning Playbook
 How TheFork Leverages Online Evals To Boost Conversions with Arize AX on AWS
 How Handshake Deployed and Scaled 15+ LLM Use Cases In Under Six Months — With Evals From Day One