nemotron-3-ultra
13K Downloads Updated 3 weeks ago
NVIDIA Nemotron 3 Ultra is built for high-throughput reasoning and long-running agent workflows.
Cancel
tools thinking cloud
Usage
high
Context
256K tokens
Size
550B parameters
CLI cURL Python JavaScript
ollama run nemotron-3-ultra:cloud
curl http://localhost:11434/api/chat \ -d '{ "model": "nemotron-3-ultra:cloud", "messages": [{"role": "user", "content": "Hello!"}] }'
from ollama import chat
response = chat( model='nemotron-3-ultra:cloud', messages=[{'role': 'user', 'content': 'Hello!'}], ) print(response.message.content)
import ollama from 'ollama'
const response = await ollama.chat({ model: 'nemotron-3-ultra:cloud', messages: [{role: 'user', content: 'Hello!'}], }) console.log(response.message.content)
Applications
Claude Code `ollama launch claude --model nemotron-3-ultra:cloud`
Codex App `ollama launch codex-app --model nemotron-3-ultra:cloud`
OpenClaw `ollama launch openclaw --model nemotron-3-ultra:cloud`
Hermes Agent `ollama launch hermes --model nemotron-3-ultra:cloud`
Codex `ollama launch codex --model nemotron-3-ultra:cloud`
OpenCode `ollama launch opencode --model nemotron-3-ultra:cloud`
Models
Name
1 model
Size / Usage
Context
Input
nemotron-3-ultra:cloud High Usage · 256K context window · Text · 3 weeks ago
256K
Text
Readme
NVIDIA Nemotron 3 Ultra is a 550 billion parameter (55B active) open model from NVIDIA built for long-running, agentic workflows with fast and affordable performance across hundreds of tool calls.
Model highlights
- Built for long-running agents: Tuned for agent orchestration, coding agents, deep research, and complex enterprise workflows that run across hundreds of steps.
- 1M token context: Keep entire codebases, long tool histories, and research trails in context without losing the thread.
- Frontier reasoning, high efficiency: 550B total parameters with only 55B active per token, and optimized for NVFP4, NVIDIA’s 4-bit floating point format that packs the model into less memory and runs faster.
- NVIDIA Nemotron 3 Ultra blog
Benchmarks
Nemotron 3 Ultra leads on accuracy across agent productivity, instruction following, and long-context tasks, while delivering leading throughput—saving up to 30% on costs compared to other leading open models.
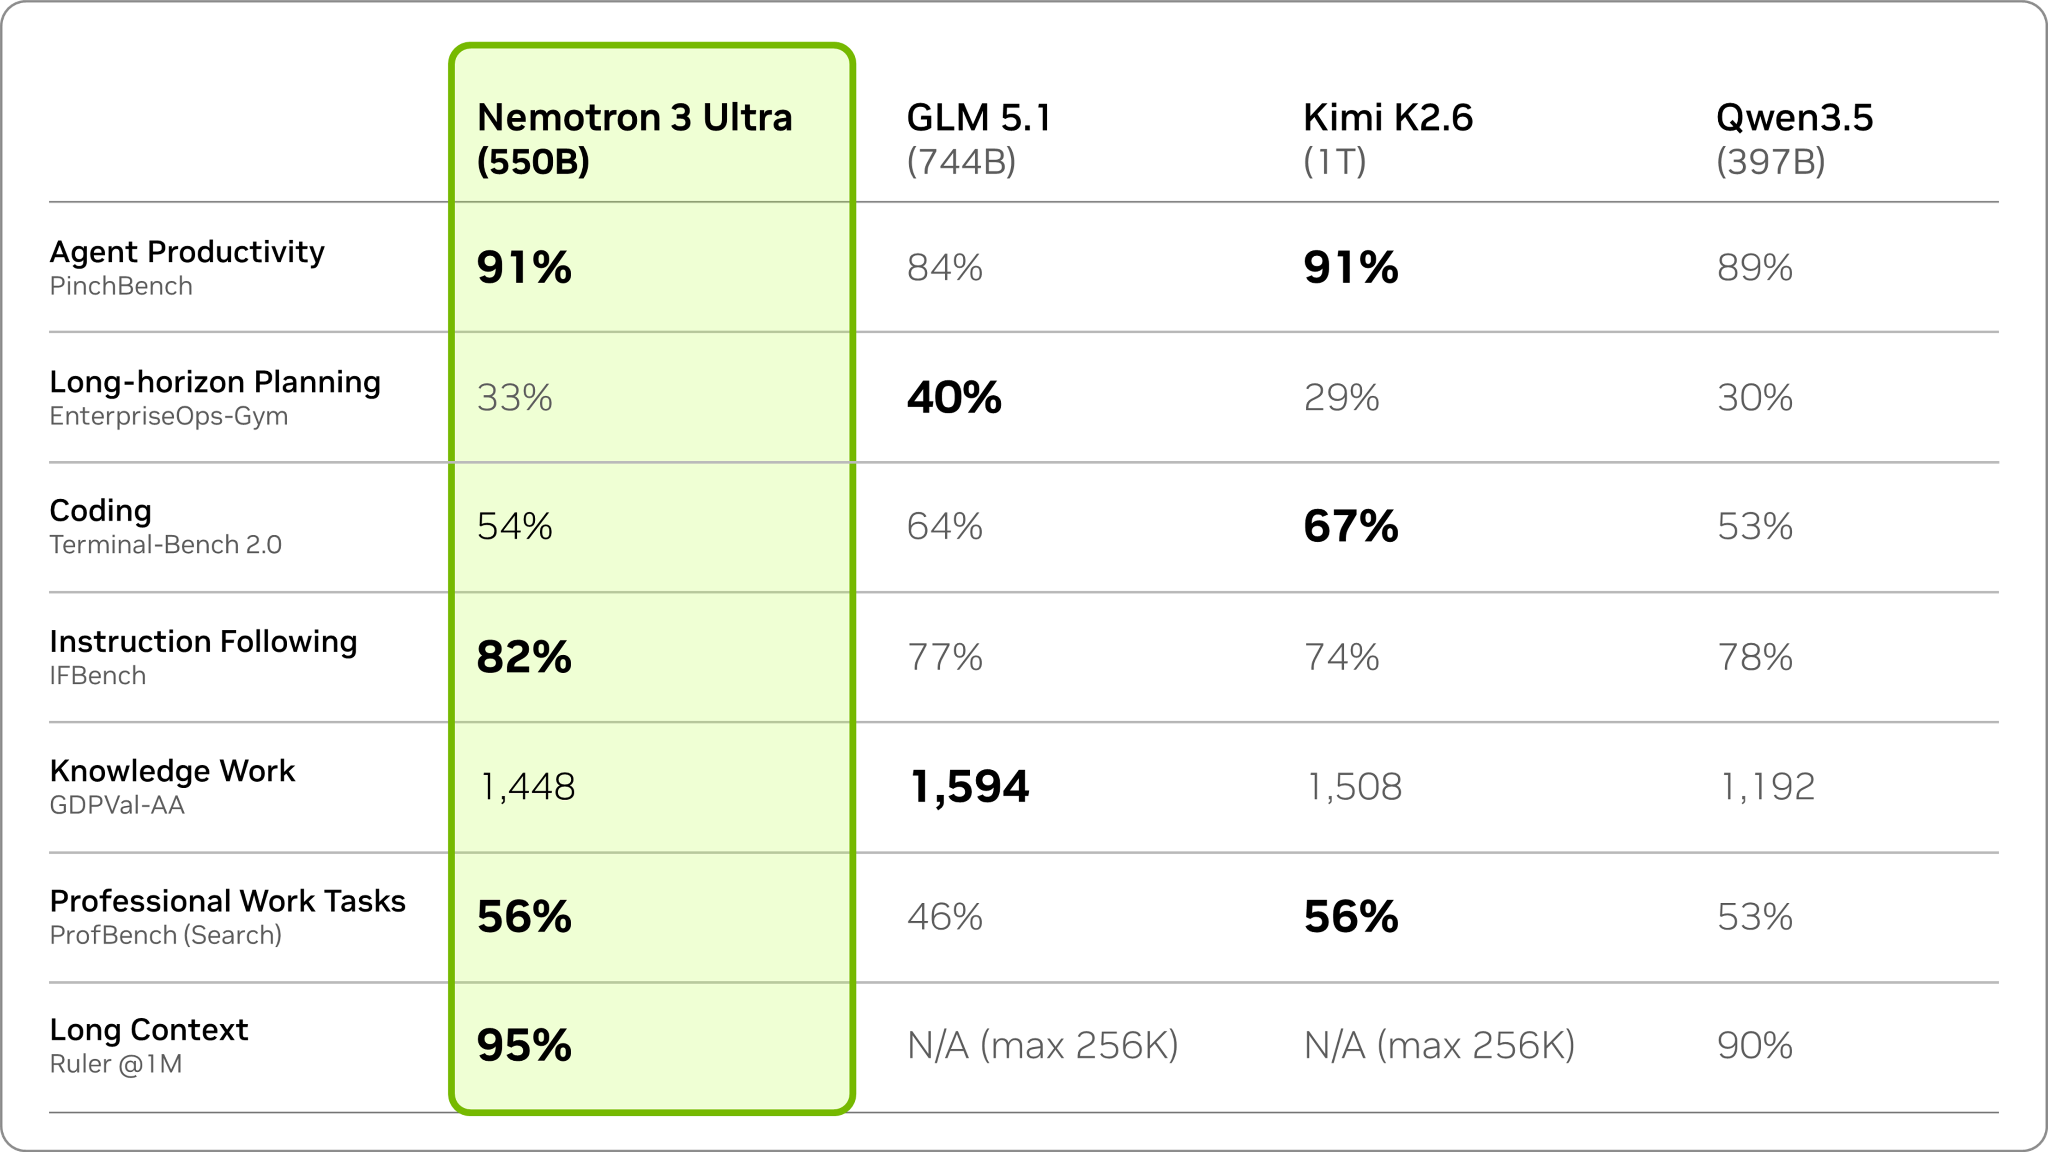 Figure 1: Nemotron 3 Ultra leads among open models on agentic benchmarks for agent productivity, coding, and instruction following.
Reference
Paste, drop or click to upload images (.png, .jpeg, .jpg, .svg, .gif)