
Oodle: Agent Observability that “just works” at scale
NewAgent Observability is live.Agent traces from $10 per million spans.→
Shipping agents is easy. Observing agents is hard.
Searching Agent Traces is slow
Agent Traces have large metadata - prompts, tool calls, etc. - search results can take minutes to load.
Storing Agent Traces is expensive
Agents fail non-deterministically - so you can't afford to miss any trace - but you can't afford to keep them all either.
Surfacing agent failures is hard
Agents fail in so many ways - fake 'I did it' messages, silent tool errors, give up mid-chat...
Oodle: Agent Observability that “just works” at scale
<1s P99 query
Fast search over traces
Columnar storage, serverless compute - find the trace in seconds, not minutes.
$10 / million spans
S3-based storage
Store 100% of traces and keep your budget too. Retain for months or years - you choose.
Every trace, analyzed
Out-of-the-box Insights
Detect user frustration, tool call optimizations, anomalies before you write a single eval
#
Customers love us!

3M+ agent traces/day. Zero sampling.>
Catch silent failures on Voice AI agents.
#
Trusted by engineering teams




Shipping agents is easy. Observing agents is hard.
Storing Agent Traces is expensive
Agents fail non-deterministically - so you can't afford to miss any trace - but you can't afford to keep them all either.
Oodle solves it
$10 / million spans
S3-based storage
Store 100% of traces and keep your budget too. Retain for months or years - you choose.
Searching Agent Traces is slow
Agent Traces have large metadata - prompts, tool calls, etc. - search results can take minutes to load.
Oodle solves it
<1s P99 query
Fast search over traces
Columnar storage, serverless compute - find the trace in seconds, not minutes.
Surfacing agent failures is hard
Fake 'I did it' messages, silent tool errors, gave up mid-way - so many ways agents can fail.
Oodle solves it
Every trace, analyzed
Out-of-the-box Insights
Detect user frustration, tool call optimizations, anomalies before you write a single eval
Battle-tested in production.
3M+ agent traces/day. Zero sampling
 Ashish Gupta, Principal Engineer
#
Trusted by engineering teams
Get Started for FreeTry in Playground
#
Flat ingestion-based pricing
#
No per query / per-user charges.
Ingested Bytes per DayTotal volume of agent trace data ingested per day.
0 GB500 GB
Retention (days)How long to keep your traces. All retained data is queryable at the same speed — no warm/cold tiers.
11825
30d90d180d1y2y5y
| Dimension | Value | Unit Price | Monthly Cost | | --------------------------- | ---------- | ------------- | ------------ | | Ingestion | 1200 GB/mo | $0.30 /GB | $360 | | Retention | 90 days | $0.001 /GB/mo | $2 | | Queries (UI, MCP, CLI, API) | unlimited | $0 | $0 | | Total | | | $362 /mo |
#
How It Works
 Blog · EngineeringHow We Achieved $10/Million Agent SpansAt Oodle we built a new high performance, low cost database backed by object storage for each kind of observability signal...
 Vijay Karthik14 Jul 2026 · 5 min read
 BlogYou Can't Sample Your Way to Reliable AgentsBuilding agents has become easy. A few lines of code and you have a working agent. But once it's in production, how do you know it's actually working...Vijay Karthik09 Jul 2026 · 4 min read
 Blog · ArchitectureHow Oodle Keeps Observability Fast at ScaleIf you've ever kept a giant observability cluster alive “just in case,” you know the vibe: half your spend goes to idle capacity, and the other half goes to hoping ...Vijay Karthik23 Mar 2026 · 7 min read

How Oodle Agent Observability Works
See how you can setup Agent Observability on Oodle to surface silent agent failures and debug your agents in production from day 1.
#
Surface issues before users notice.
#
Insights automatically detect silent failures across your agent traces - no rules to configure.
Error Recovery Failures
Agents that hit errors and fail to recover gracefully. Incomplete tool call chains, unhandled exceptions mid-conversation.
High Duration
Traces taking significantly longer than baseline. Catches stuck loops, slow tool calls, and retry storms.
Low User Satisfaction
Responses flagged by sentiment and quality scoring as negative or off-topic. Identifies patterns in poor experiences.
Model Cost Optimization
Traces where a cheaper model could produce the same result. Spots over-provisioned calls burning budget on simple tasks.
Caching Inefficiency
Repeated identical prompts that could be cached. Flags redundant LLM calls wasting tokens and adding latency.
Excessive LLM Turns
Conversations that spiral into too many turns. Detects prompt loops, circular reasoning, and agents that can't converge.
#
Complete LLMOps Platform
#
Monitor, debug, and optimize every layer of your AI stack.
Observe Agent Transcripts for Deep Dives
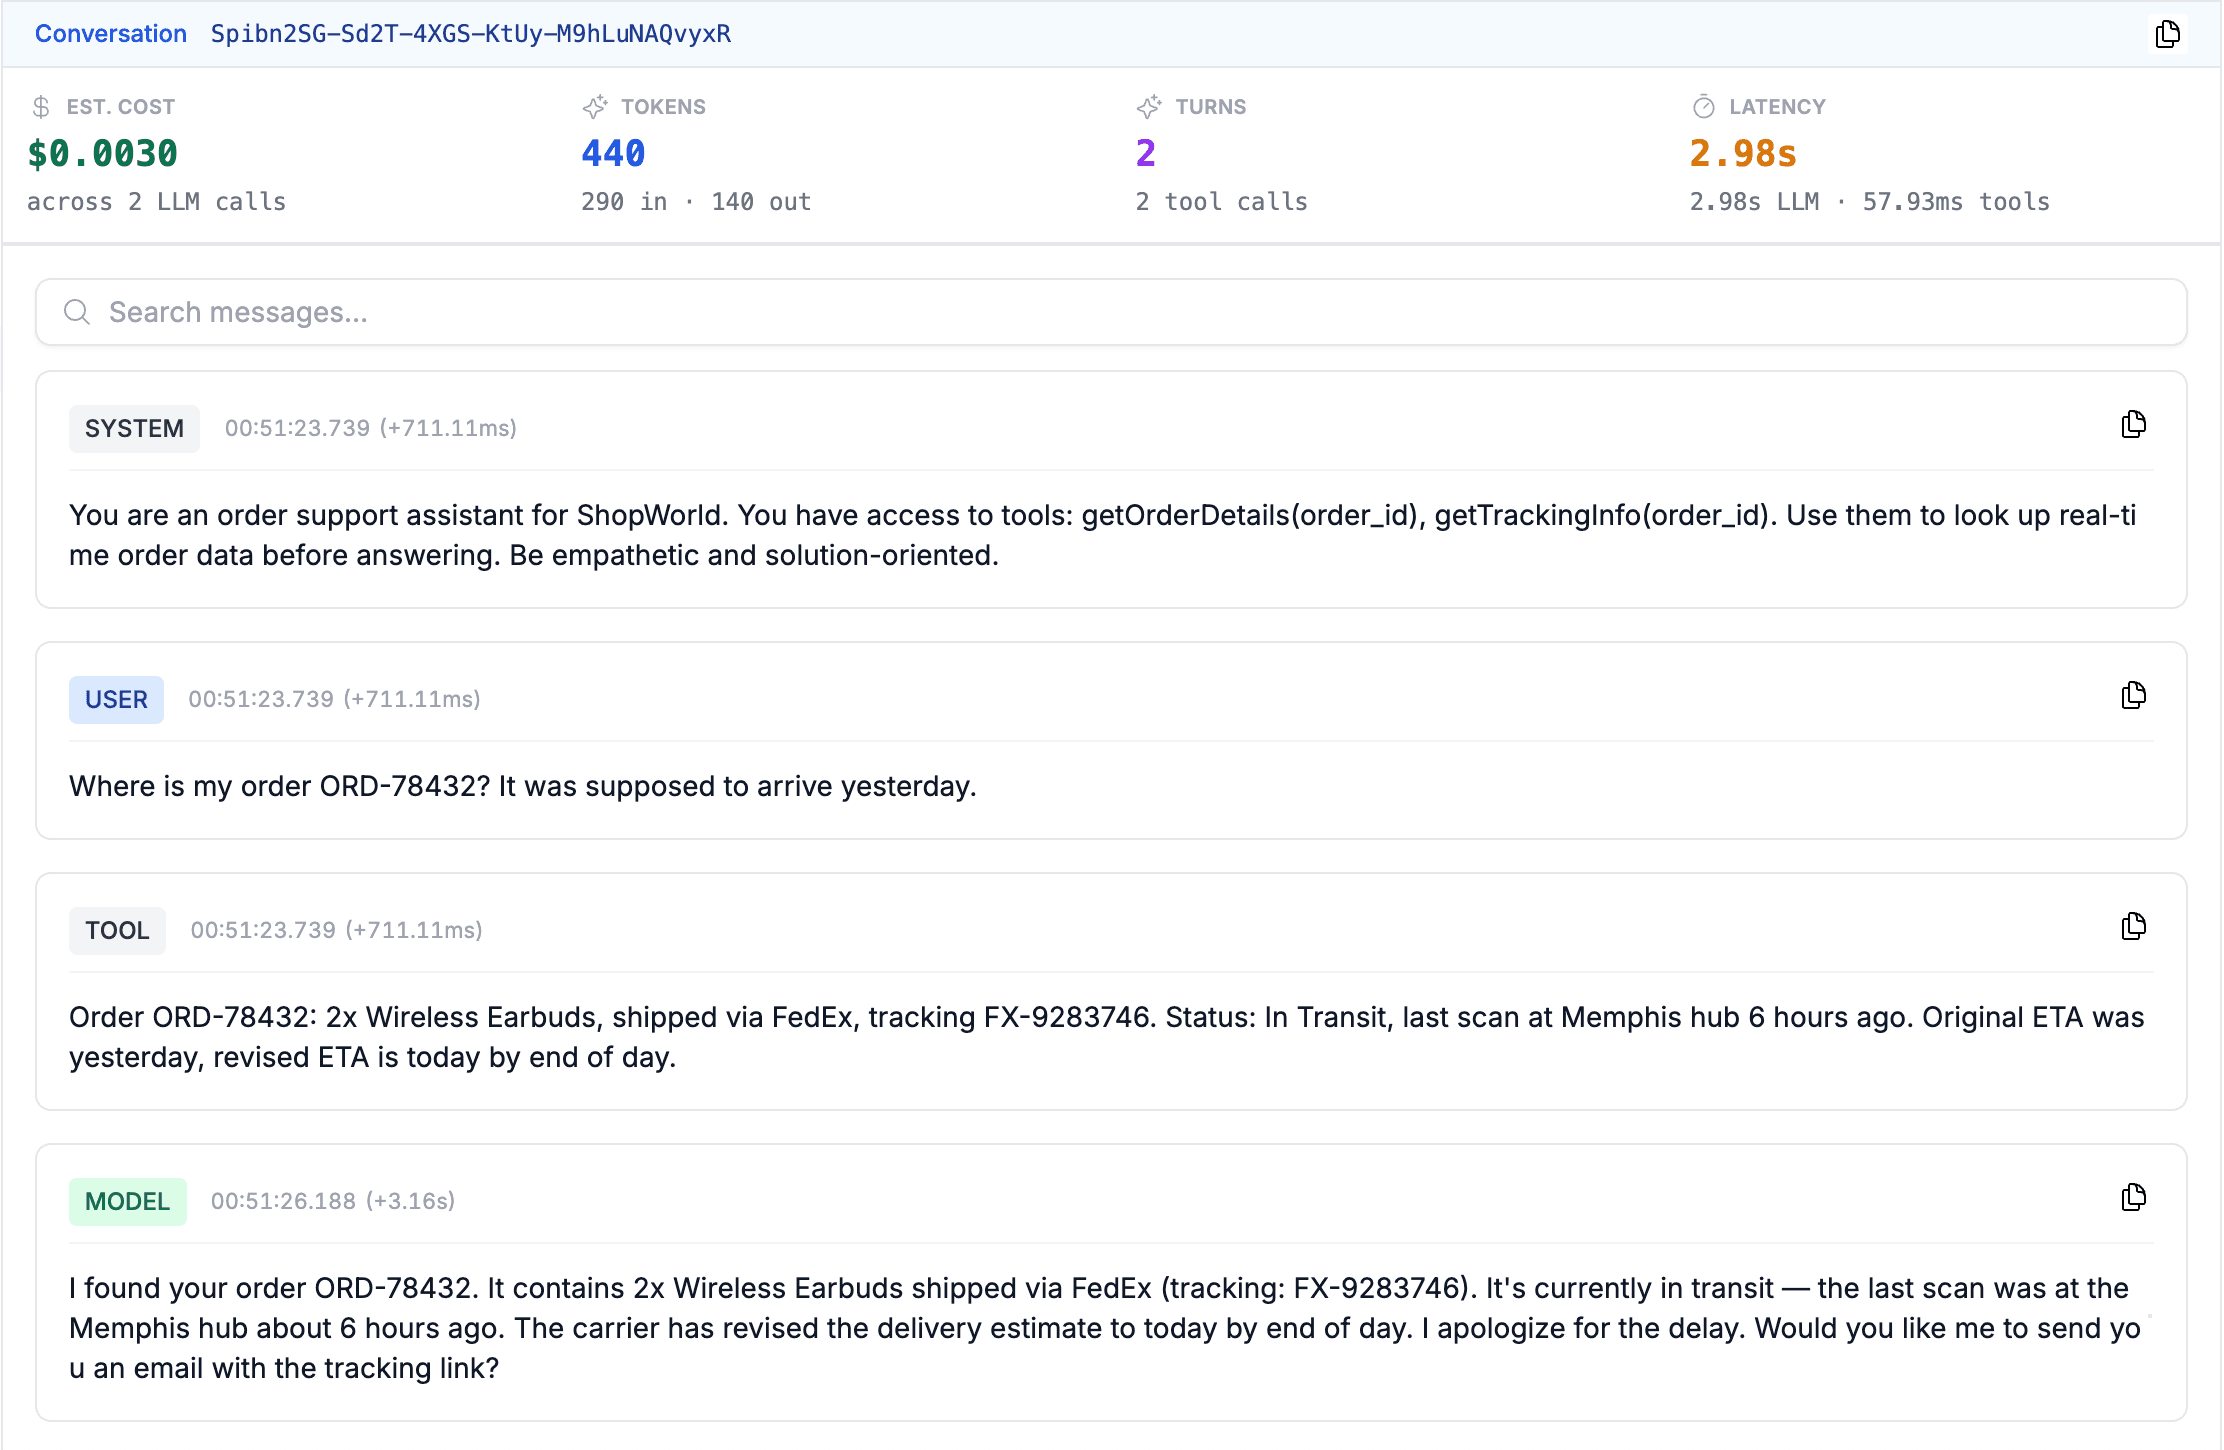
Read the exact multi-turn conversation: system prompt, tool calls, multi-agent handovers. Input, output, and reasoning tokens broken down per span - spot runaway prompts and budget overruns before they hit your bill.
Evals for Your Agents
Configure eval pipelines for accuracy, relevance, and safety. Score every response automatically - use our out-of-the-box evals or write your own.

AI-powered Insights for your Agentic stack
Surface issues on Quality, Performance, Efficiency out-of-the-box - improve your agents from day 1

Refine Your Prompts with Playground
Iterate on prompts in a live playground. Swap models, tweak parameters, and compare outputs - without redeploying.

Regression Checks for Your Agents - Datasets & Experiments
Build eval datasets from production traces or CSV imports. Run experiments against any model and compare results side-by-side.

Cost Estimation with Configurable Pricing
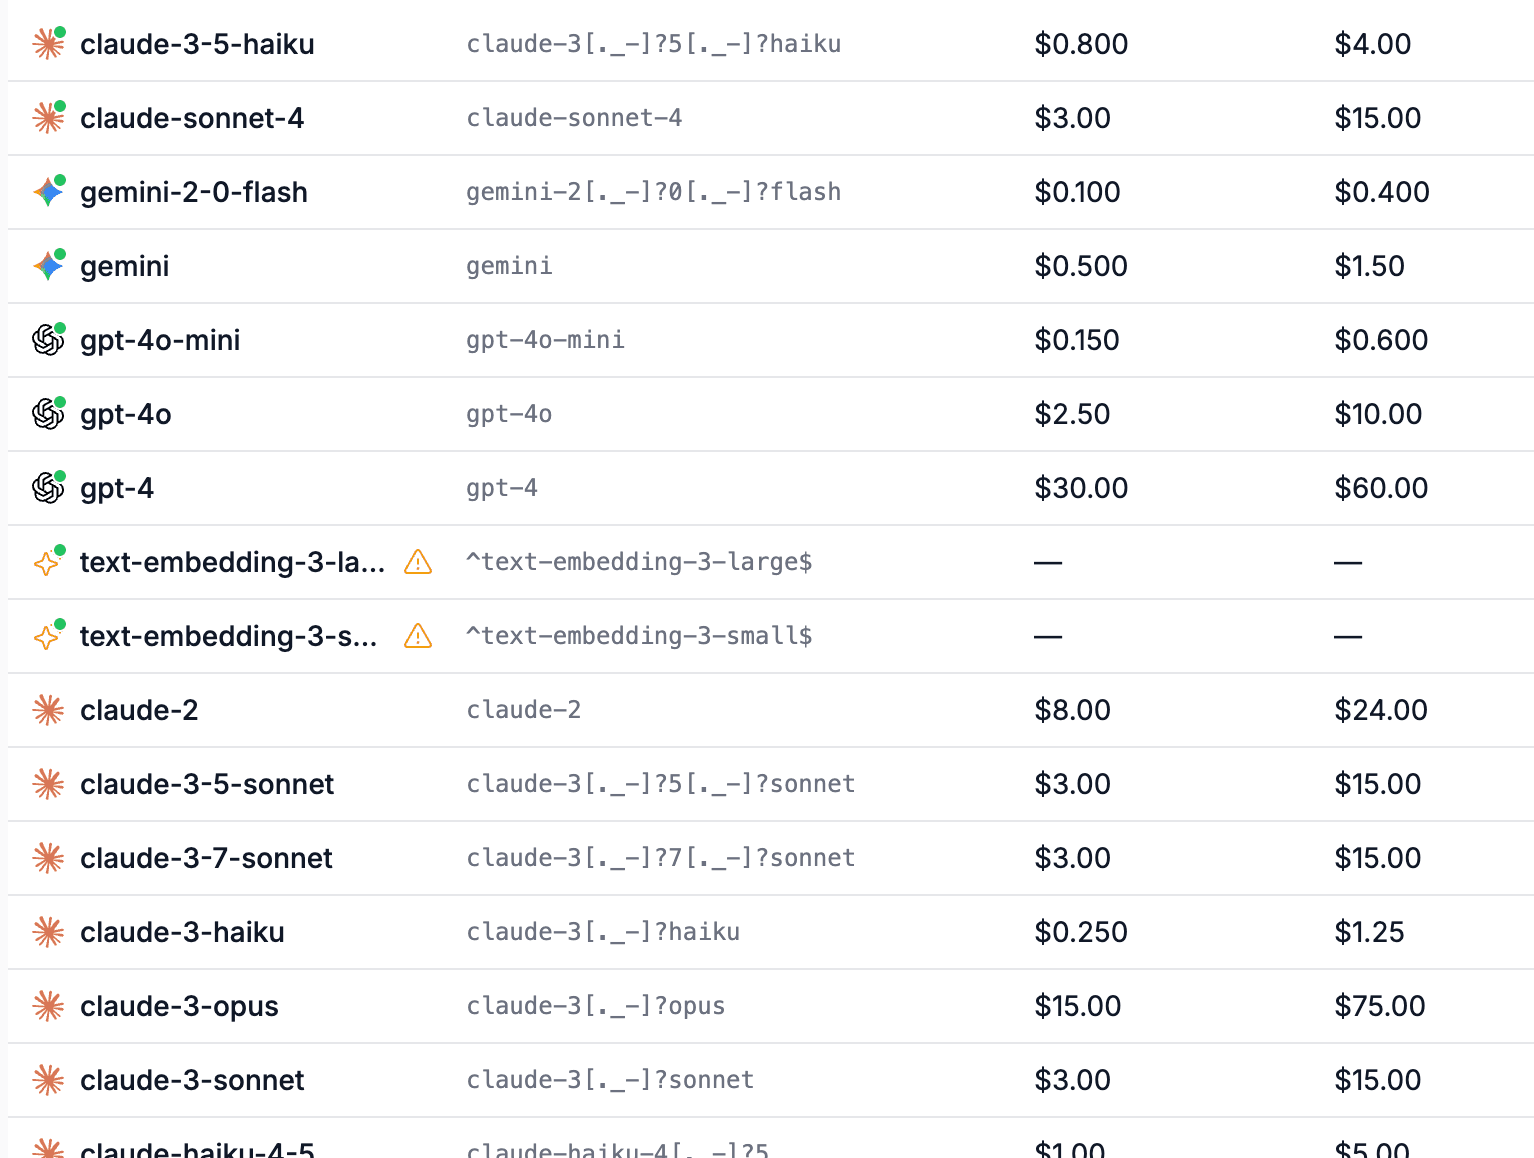
Estimated cost per trace, per model, per service. 50+ model pricing definitions shipped by default - OpenAI, Anthropic, Google, Mistral, Cohere, and more. Add custom or fine-tuned models in the UI.
#
See It In Your Environment
#
Start sending traces in under 15 minutes. Free tier included - no credit card required.
Get Started for FreeTry in Playground
#
Frequently Asked Questions
Do I need a separate SDK to instrument my LLM calls?
No. Oodle consumes standard OpenTelemetry traces using the Generative AI semantic conventions. If your instrumentation library already emits these attributes, you just point your OTLP exporter at Oodle.
Which LLM providers and models are supported?
Any provider that your code calls - OpenAI, Anthropic, Google Gemini, Mistral, Cohere, Azure OpenAI, AWS Bedrock, and self-hosted models. Cost estimation ships with 50+ model pricing definitions, and you can add custom models.
How is this different from standalone LLM observability tools?
Standalone tools create another data silo. Oodle shows your LLM spans inside the same traces as your API, database, and cache calls. When something breaks, you see the full picture - not just the prompt and response in isolation.
Does Oodle do prompt versioning or evals?
Yes. Oodle includes a full LLMOps workflow: version and label prompts, build eval datasets (or import via CSV), run experiments against any model, and score results with built-in or custom evaluators - all alongside your production traces.
Do you sample LLM traces?
No. Retain 100% of your traces with full prompt and response content.