

LiteRT.js, Google's high performance Web AI Inference
LiteRT.js, Google's high performance Web AI Inference
JULY 9, 2026
Ping Yu Software Engineer
Marko Ristić Software Engineer
Matthew Soulanille Software Engineer
Chintan Parikh Product Manager
Share
- CPU: utilizes XNNPACK, Google's highly optimized library for on-device CPU acceleration, providing robust multi-thread support and a relaxed SIMD build for enhanced performance.
- GPU: powered by ML Drift, Google's leading solution for on-device GPU acceleration. LiteRT.js leverages WebGPU to enable state-of-the-art GPU acceleration on the web.
- NPU: harnesses the emerging WebNN API (currently experimental in Chrome and Edge) to target dedicated NPUs for power-efficient, ultra low-latency inference.
We are excited to announce LiteRT.js, a JavaScript binding of LiteRT for running AI directly inside the web browser. By bringing the trusted on-device inference library LiteRT to the web, web developers can now run ML and AI models with maximum performance entirely locally. This means enhanced user privacy, zero server costs, and ultra-low latency for real-time experiences. For developers with existing .tflite models, LiteRT.js makes deployment to mobile and desktop web browsers smoother than ever, serving as a powerful evolution from TensorFlow.js for executing .tflite models.
While prior web AI solutions like TensorFlow.js relied on less performant JavaScript-based kernels, we are now making our native, cross-platform runtime with all its optimizations directly available to web developers through WebAssembly. LiteRT.js unlocks impressive performance by running your .tflite models directly in the browser leveraging the state-of-the-art hardware acceleration of LiteRT, including XNNPACK for CPU, ML Drift for GPU, and the upcoming WebNN for NPUs.
Our initial release provides all the tools needed to get started, including the new LiteRT.js npm package and a collection of demos showcasing real-world implementation.
Sorry, your browser doesn't support playback for this video
Vector search right in the browser, powered by LiteRT.js and EmbeddingGemma. Try it here.
How LiteRT.js benefits web developers
With LiteRT.js, web developers can integrate models into their apps written in JavaScript or TypeScript to handle complex tasks like text generation, object detection, and audio processing entirely client-side. As LiteRT.js shares a unified cross-platform stack with LiteRT, your web applications automatically benefit from the latest performance upgrades, quantization improvements, and hardware optimizations developed for Android, iOS, and desktop.
By leveraging LiteRT's lowering flow and runtime, you get simple conversion of models from a variety of Python ML frameworks and native hardware acceleration across all major accelerators (CPU / GPU / NPU). To help you unlock these AI capabilities easily, here are the main highlights of LiteRT.js:
1.PyTorch conversion & tailored quantization
With LiteRT Torch, PyTorch models can be converted in a single step, making them instantly ready to leverage advanced browser-based hardware acceleration. Get started today by following the LiteRT Torch guide.
For further optimization, AI Edge Quantizer allows you to configure tailored quantization schemes across different model layers. This achieves substantial size reductions and performance gains while preserving overall model quality. Explore the quantization colab to see this in action.
2.Native hardware acceleration across CPU, GPU, and NPU
LiteRT.js enables high-performance AI inference for a diverse variety of hardware backends.
Ready to accelerate your web applications? Dive into the LiteRT.js documentation to get started.

LiteRT.js Architecture Overview
Performance and real-world impact
To demonstrate the real-world impact of the unified runtime and hardware-accelerated backends, we evaluated LiteRT.js against existing web solutions. Across classical computer vision and audio processing models, LiteRT.js delivers significant speedups—outperforming other web runtimes by up to 3x across both CPU and GPU inference.
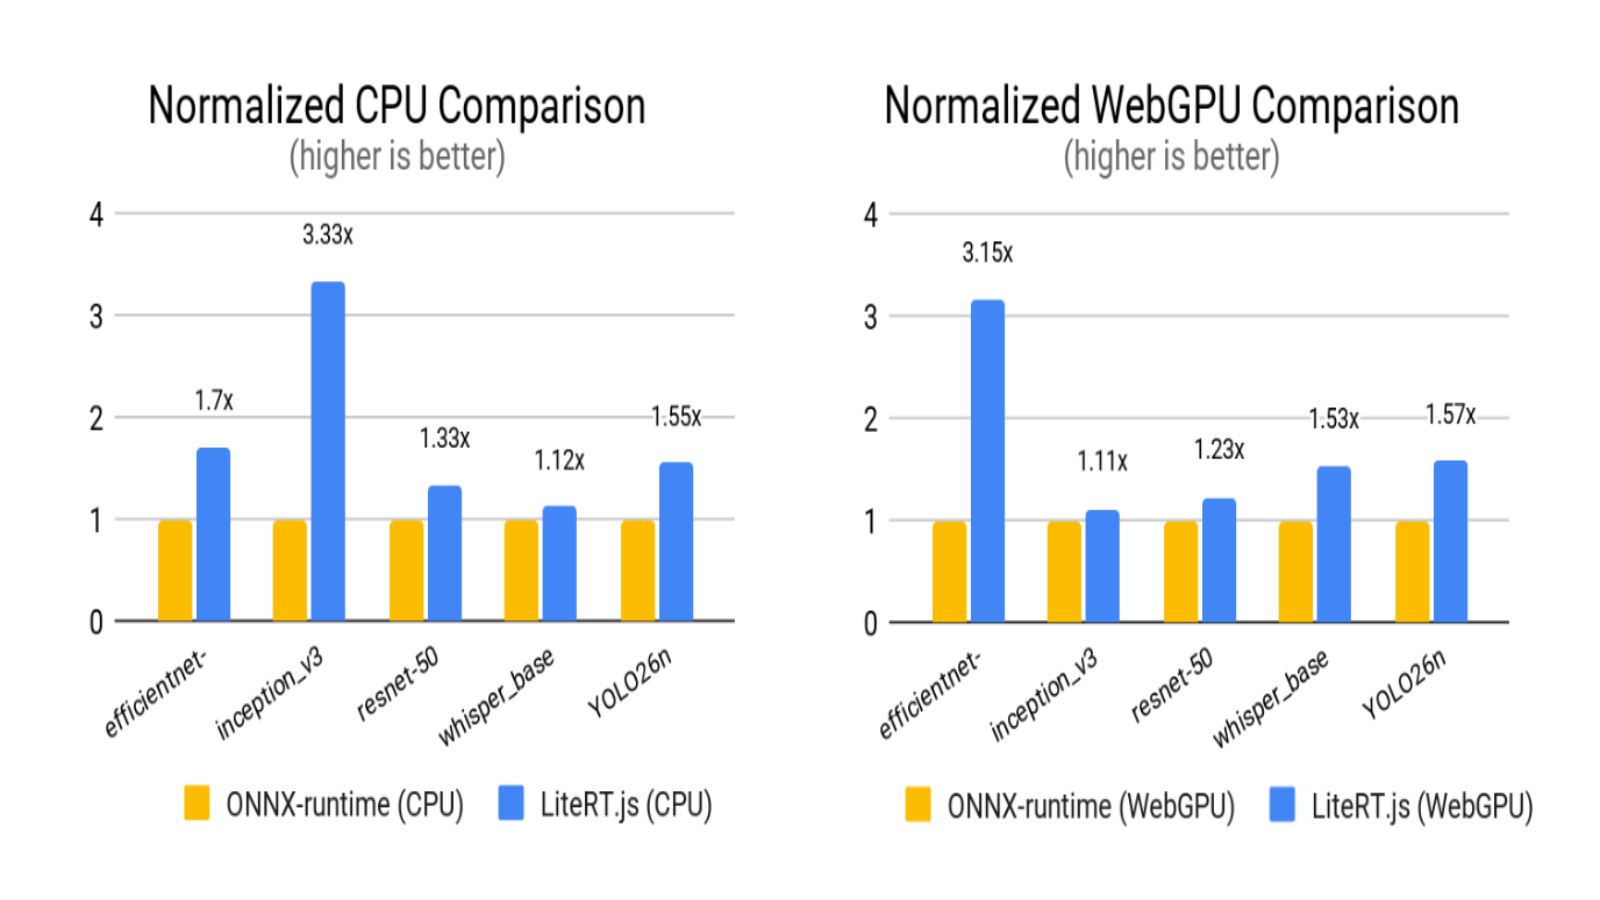
Note: Performance benchmarks conducted on a 2024 Apple MacBook Pro with M4 Apple Silicon in a controlled browser environment. Individual user performance may vary based on local GPU capabilities, thermal throttling, and browser driver optimization.
To ground these claims in real-world efficiency, we benchmarked popular AI models using LiteRT.js across three distinct web execution backends: CPU (via XNNPACK), WebGPU, and WebNN (via Apple CoreML). For demanding real-time applications like object tracking, audio transcription, or image manipulation, leveraging the GPU or NPU via WebGPU or WebNN delivers 5-60x speedup compared to standard CPU execution, ensuring lower latency without compromising performance.
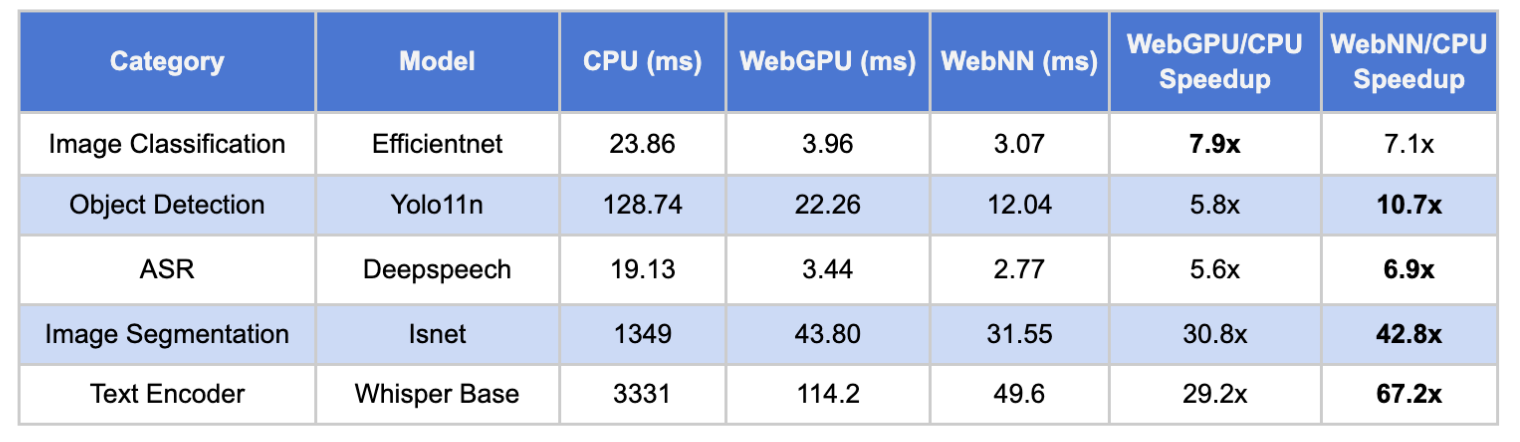
Note: Performance benchmarks conducted on a 2024 Apple MacBook Pro with M4 Apple Silicon in a controlled browser environment. Individual user performance may vary based on local GPU capabilities, thermal throttling, and browser driver optimization.
See it in action
To see LiteRT.js in action, explore our live implementations. LiteRT.js demo source code is available on the LiteRT GitHub repository and via Ultralytics.
LiteRT Ultralytics YOLO integration
Ultralytics is an artificial intelligence company that specializes in building computer vision tools and models. It is best known as the creator of the YOLO (You Only Look Once) framework, family of real-time object detection and image segmentation models.
We are excited to share official LiteRT export support built directly into the Ultralytics Python package. Easily deploy Ultralytics YOLO models across mobile, edge, and browsers—and go from compilation to runtime in just a few lines of code.
Sorry, your browser doesn't support playback for this video
Demo: YOLO26, family of real-time vision models
Depth Estimation
Depth Anything - monocular depth estimation showcases how to transform a standard webcam feed into an interactive 3D point cloud in real-time. Powered by LiteRT.js via WebGPU, it uses the Depth-Anything-V2 model to instantly calculate depth data and map video pixels into a responsive 3D space.
Sorry, your browser doesn't support playback for this video
Demo: Monocular depth estimation using DepthAnything and WebGPU.
Image Upscaling
Upscale images by 4x in the browser using the Real-ESRGAN model with LiteRT.js, which works by upscaling 128x128 pixel patches to 512x512 which are then reassembled into the final image.
Sorry, your browser doesn't support playback for this video
Get started with LiteRT.js
Integrating LiteRT.js into your development workflow is straightforward, whether you’re launching a fresh implementation or migrating an existing application to our high-performance runtime. LiteRT.js abstracts the complexities of hardware-level optimization, enabling you to deliver responsive, privacy-focused experiences without the overhead of manual platform tuning.
The following snippet highlights the streamlined process for initializing, compiling, and running a `.tflite` model with GPU acceleration. Using clean, modern JavaScript, you can load your model, feed input tensors, and capture high-speed inference results in real-time. For more detailed instructions, demos, and guidance, please refer to our documentation here.
import { loadLiteRt, loadAndCompile, Tensor } from '@litertjs/core';await loadLiteRt('path/to/wasm/directory/');
const model = await loadAndCompile('path/to/your/model.tflite',{ accelerator: webgpu });
const inputTypedArray = new Float32Array(1 3 244 * 244);
const inputTensor = new Tensor(inputTypedArray, [1, 3, 244, 244]);
const results = await model.run(inputTensor);
// results is a Tensor stored on GPU. To move it to CPU & convert to a typedArray we use
const resultArray = (await results[0].moveTo('wasm')).toTypedArray();
JavaScript
Copied
What’s next
We are committed to continually expanding LiteRT.js performance, model coverage, and developer tooling. Looking ahead, our development roadmap centers on advancing WebNN integration for native NPU performance and delivering highly optimized support for on-device generative AI.
Acknowledgements
Ultralytics, for providing YOLO26 media and performance data. Jason Mayes for LiteRT.js demos.
posted in:
Related Posts
 Mobile AI Case Studies Announcements Unlocking the Next Era of On-Device AI with Google Tensor and Pixel JULY 13, 2026
 Mobile Web Case Studies Community Bridging the Domain Gap: AI Race Coach built with Antigravity and Gemini JULY 8, 2026
 Web AI Case Studies Learn Measuring What Matters with Jules JUNE 22, 2026
 AI Cloud Tutorials Announcements We terminated a TPU mid-training and it recovered in seconds: Introduction to elastic training with MaxText JULY 6, 2026