
What I got wrong about ClickHouse as a Kafka Person
Jul 9, 2026
What I got wrong about ClickHouse as a Kafka Person
All the things that tripped me up while trying to get a Kafka topic’s data into ClickHouse.
Stuart Mould |
Staff Product Manager, Data Streaming
- [](https://www.linkedin.com/shareArticle?mini=true&url=https%3A%2F%2Faiven.io%2Fblog%2Fwhat-i-got-wrong-about-clickhouse-as-a-kafka-person "Share on LinkedIn")
- [](https://www.facebook.com/sharer/sharer.php?u=https%3A%2F%2Faiven.io%2Fblog%2Fwhat-i-got-wrong-about-clickhouse-as-a-kafka-person "Share on Facebook")
- [](https://twitter.com/intent/tweet?text=What%20I%20got%20wrong%20about%20ClickHouse%20as%20a%20Kafka%20Person&url=https%3A%2F%2Faiven.io%2Fblog%2Fwhat-i-got-wrong-about-clickhouse-as-a-kafka-person "Share on Twitter")
- [](mailto:?subject=What%20I%20got%20wrong%20about%20ClickHouse%20as%20a%20Kafka%20Person&body=Check%20out%20this%20page%20https://aiven.io/blog/what-i-got-wrong-about-clickhouse-as-a-kafka-person "Share via email")
- The setup looks familiar, until this one word
- 1. The materialized view is not a view
- 2. Nothing happens until you attach the view
- 3. The primary key isn't what you think it is
- The pattern behind the surprises
- Sep 4, 2025Getting Started with Iceberg Topics for Apache Kafka®: A Beginner's GuideUnderstand how Kafka can write directly to Apache Iceberg and experiment locally with Docker and SparkRead more
- Mar 20, 2025Apache Kafka® Tiered Storage in Depth: How Writes and Metadata FlowA detailed end-to-end overview of how Kafka writes and stores metadata with KIP-405.Read more
- Aug 14, 2025Iceberg Topics for Apache Kafka®: Zero ETL, Zero Copy Open Source Kafka users get native Apache Iceberg™ topics that collapse ETL and reduce costs - one write to the data lake, many reads - zero copies.Read more
Kafka is brilliant at moving events around, but sooner or later someone wants to actually query those events, perhaps aggregations, dashboards, or ad-hoc analytics over billions of rows. That is where ClickHouse comes in. It's the option for when stream processing is more than you need, but warehouse query latency is more than you'll tolerate. It’s an open-source column store built for fast analytical reads, and it sits naturally downstream of Kafka, the two forming a clean, fully open source pipeline for processing event data. Kafka moves the stream, ClickHouse makes it queryable. So when I started reading up on ClickHouse, the obvious first move was to build a demo wiring a Kafka topic into it and watch the data land. A lot of my streaming instincts carried over, but several were flawed assumptions.
Here are all the things that tripped me up while trying to get a Kafka topic’s data into ClickHouse.
[](https://aiven.io/blog/what-i-got-wrong-about-clickhouse-as-a-kafka-person#the-setup-looks-familiar-until-this-one-word)The setup looks familiar, until this one word
ClickHouse reads from Kafka with a three-part pipeline: a table backed by the Kafka engine consumes the topic, a materialized view moves the data across, and a table (MergeTree table) is where it actually lands and gets queried.
Loading code...
The Kafka engine table joins a consumer group, the one named in its `Kafka(...)` settings, so this feels familiar. However, when you hit the words "materialized view" you've now probably been led astray.
[](https://aiven.io/blog/what-i-got-wrong-about-clickhouse-as-a-kafka-person#1-the-materialized-view-is-not-a-view)1. The materialized view is not a view
Coming from Flink, or honestly any SQL engine, a view is a query you read from: a continuously updated result you can `SELECT` against. In a previous post about getting started with Flink, a `VIEW` like `items_per_cart` always reflected the current state of the stream. That's stream-table duality, and it's a clear mental model.
ClickHouse's materialized view is not quite that. It's an insert trigger. It doesn't store a query result you go and refresh; it fires on each block (a ClickHouse concept for a collection of data to be inserted) of rows inserted into its source table, runs its `SELECT` over just that block, and writes the output into a separate destination table (the one named in the `TO` clause). You never query the MV itself. You query the destination. Same two words, almost the opposite behaviour. This is a key part of the ClickHouse design philosophy, shifting the computation from query time to insert time. This makes sense as the technology emerged from building Yandex Metrica, a Google Analytics like product. It's expected to ingest huge volumes of data (think millions of rows per second) while still answering queries in milliseconds.
The MV isn't a live query sitting over the stream, it's glue that runs at write time. That write-time angle is also how ClickHouse lets you pre-aggregate as data arrives. Pair an MV with a different table type like `AggregatingMergeTree` and the rollups are maintained on insert. Out of scope for this simple copy-through example, but worth knowing it's there.
[](https://aiven.io/blog/what-i-got-wrong-about-clickhouse-as-a-kafka-person#2-nothing-happens-until-you-attach-the-view)2. Nothing happens until you attach the view
This is the one that confused me for longer than I care to admit. I created the Kafka engine table, pointed it at a populated topic, and… nothing. No consumption, no offsets moving, no errors. Just an `OK.` response from the CLI. 😐
The thing is, the Kafka table doesn't consume anything on its own. On creation it checks whether anything depends on it. In this case, it finds nothing depends on it, and goes back to sleep. Creating the materialized view is what registers a dependency, and that is what starts the background poll loop: pull a batch, push it through the view into the destination, commit the offset, repeat.
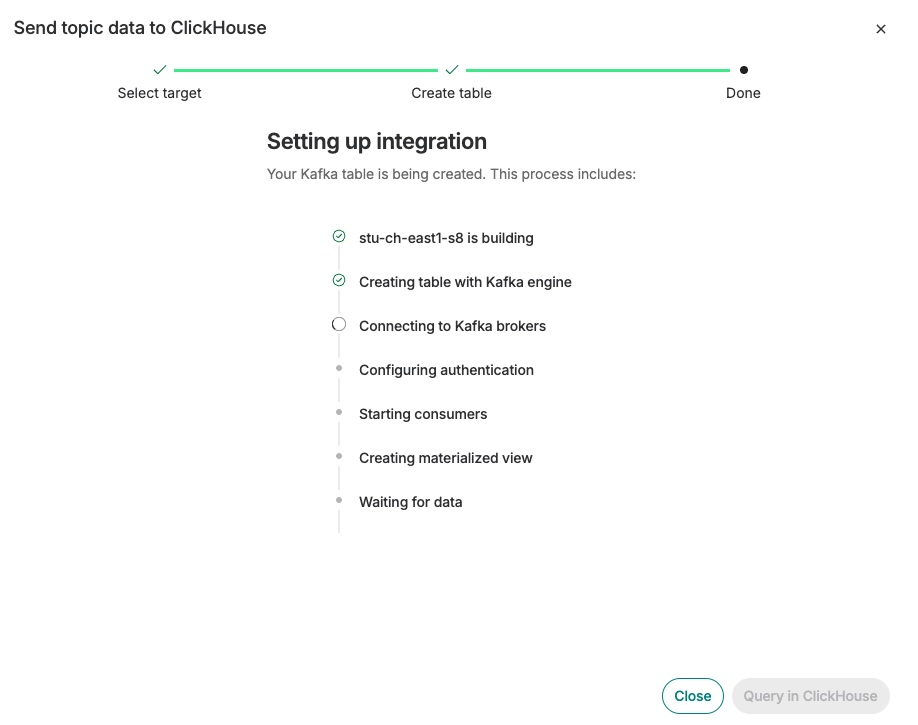
So in ClickHouse, consumption is dependency-driven, not creation-driven. This is more clearly visible when having the connection setup for you, like you can build on Aiven. On Aiven the wizard quietly exposes this: its progress checklist creates the Kafka-engine table first, then "Creating materialized view", then "Waiting for data", in that order.
One Kafka habit that does carry over cleanly: the offset is committed after the insert, so delivery is at-least-once. This pipeline requires planning for the occasional duplicate, but you can always consider a `ReplicatedMergeTree` destination to help dedupe identical blocks.
[](https://aiven.io/blog/what-i-got-wrong-about-clickhouse-as-a-kafka-person#3-the-primary-key-isn-t-what-you-think-it-is)3. The primary key isn't what you think it is
This one isn't really a Kafka thing. It's a "coming from Postgres" thing, and it catches almost everyone new to ClickHouse. Understanding primary keys in ClickHouse is … key.
I originally assumed a primary key meant uniqueness. It does not. There's no constraint and no enforcement; you can insert the same key a million times and ClickHouse won't blink.
A ClickHouse primary key defines how rows are sorted on disk and builds a sparse index over those sorted rows. (Technically you can declare `PRIMARY KEY` separately, but it defaults to your `ORDER BY` columns and is almost always the same thing, not the point here.) It's a tool for making range scans fast, not for identifying a row. So you choose it to match how you query, the columns you filter and group by, not how you'd uniquely identify a record. Get it wrong and queries scan far more than they should; get it right and ClickHouse feels, as it is meant to, crazy fast. Choosing an ordering key is therefore important, I understood this more deeply after reading the Aiven docs on this exact subject.
[](https://aiven.io/blog/what-i-got-wrong-about-clickhouse-as-a-kafka-person#the-pattern-behind-the-surprises)The pattern behind the surprises
None of this is ClickHouse being weird for the sake of it. It's a column store built for cheap inserts and fast analytical reads, and each surprise falls out of that design once you stop projecting OLTP and stream-processing definitions onto familiar-looking words. The trigger-style "view", the deferred consumption, the sort-key "primary key", they're all consistent once you see the shape of the thing.
If you come from Kafka, you already have most of the instincts you need to get data flowing. Just hold them loosely. The words are the same, the behaviour isn't.
Getting started with ClickHouse can be tricky, but it doesn’t need to be: check out the Aiven ClickHouse documentation to get started.
Stay updated with Aiven
Subscribe for the latest news and insights on open source, Aiven offerings, and more.
Loading...
---
Table of contents