GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best?
/
/
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best?
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best?
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best?
Date Published
Jul 20, 2026
Contributors
Share
Date Published
Jul 20, 2026
Contributors
Share
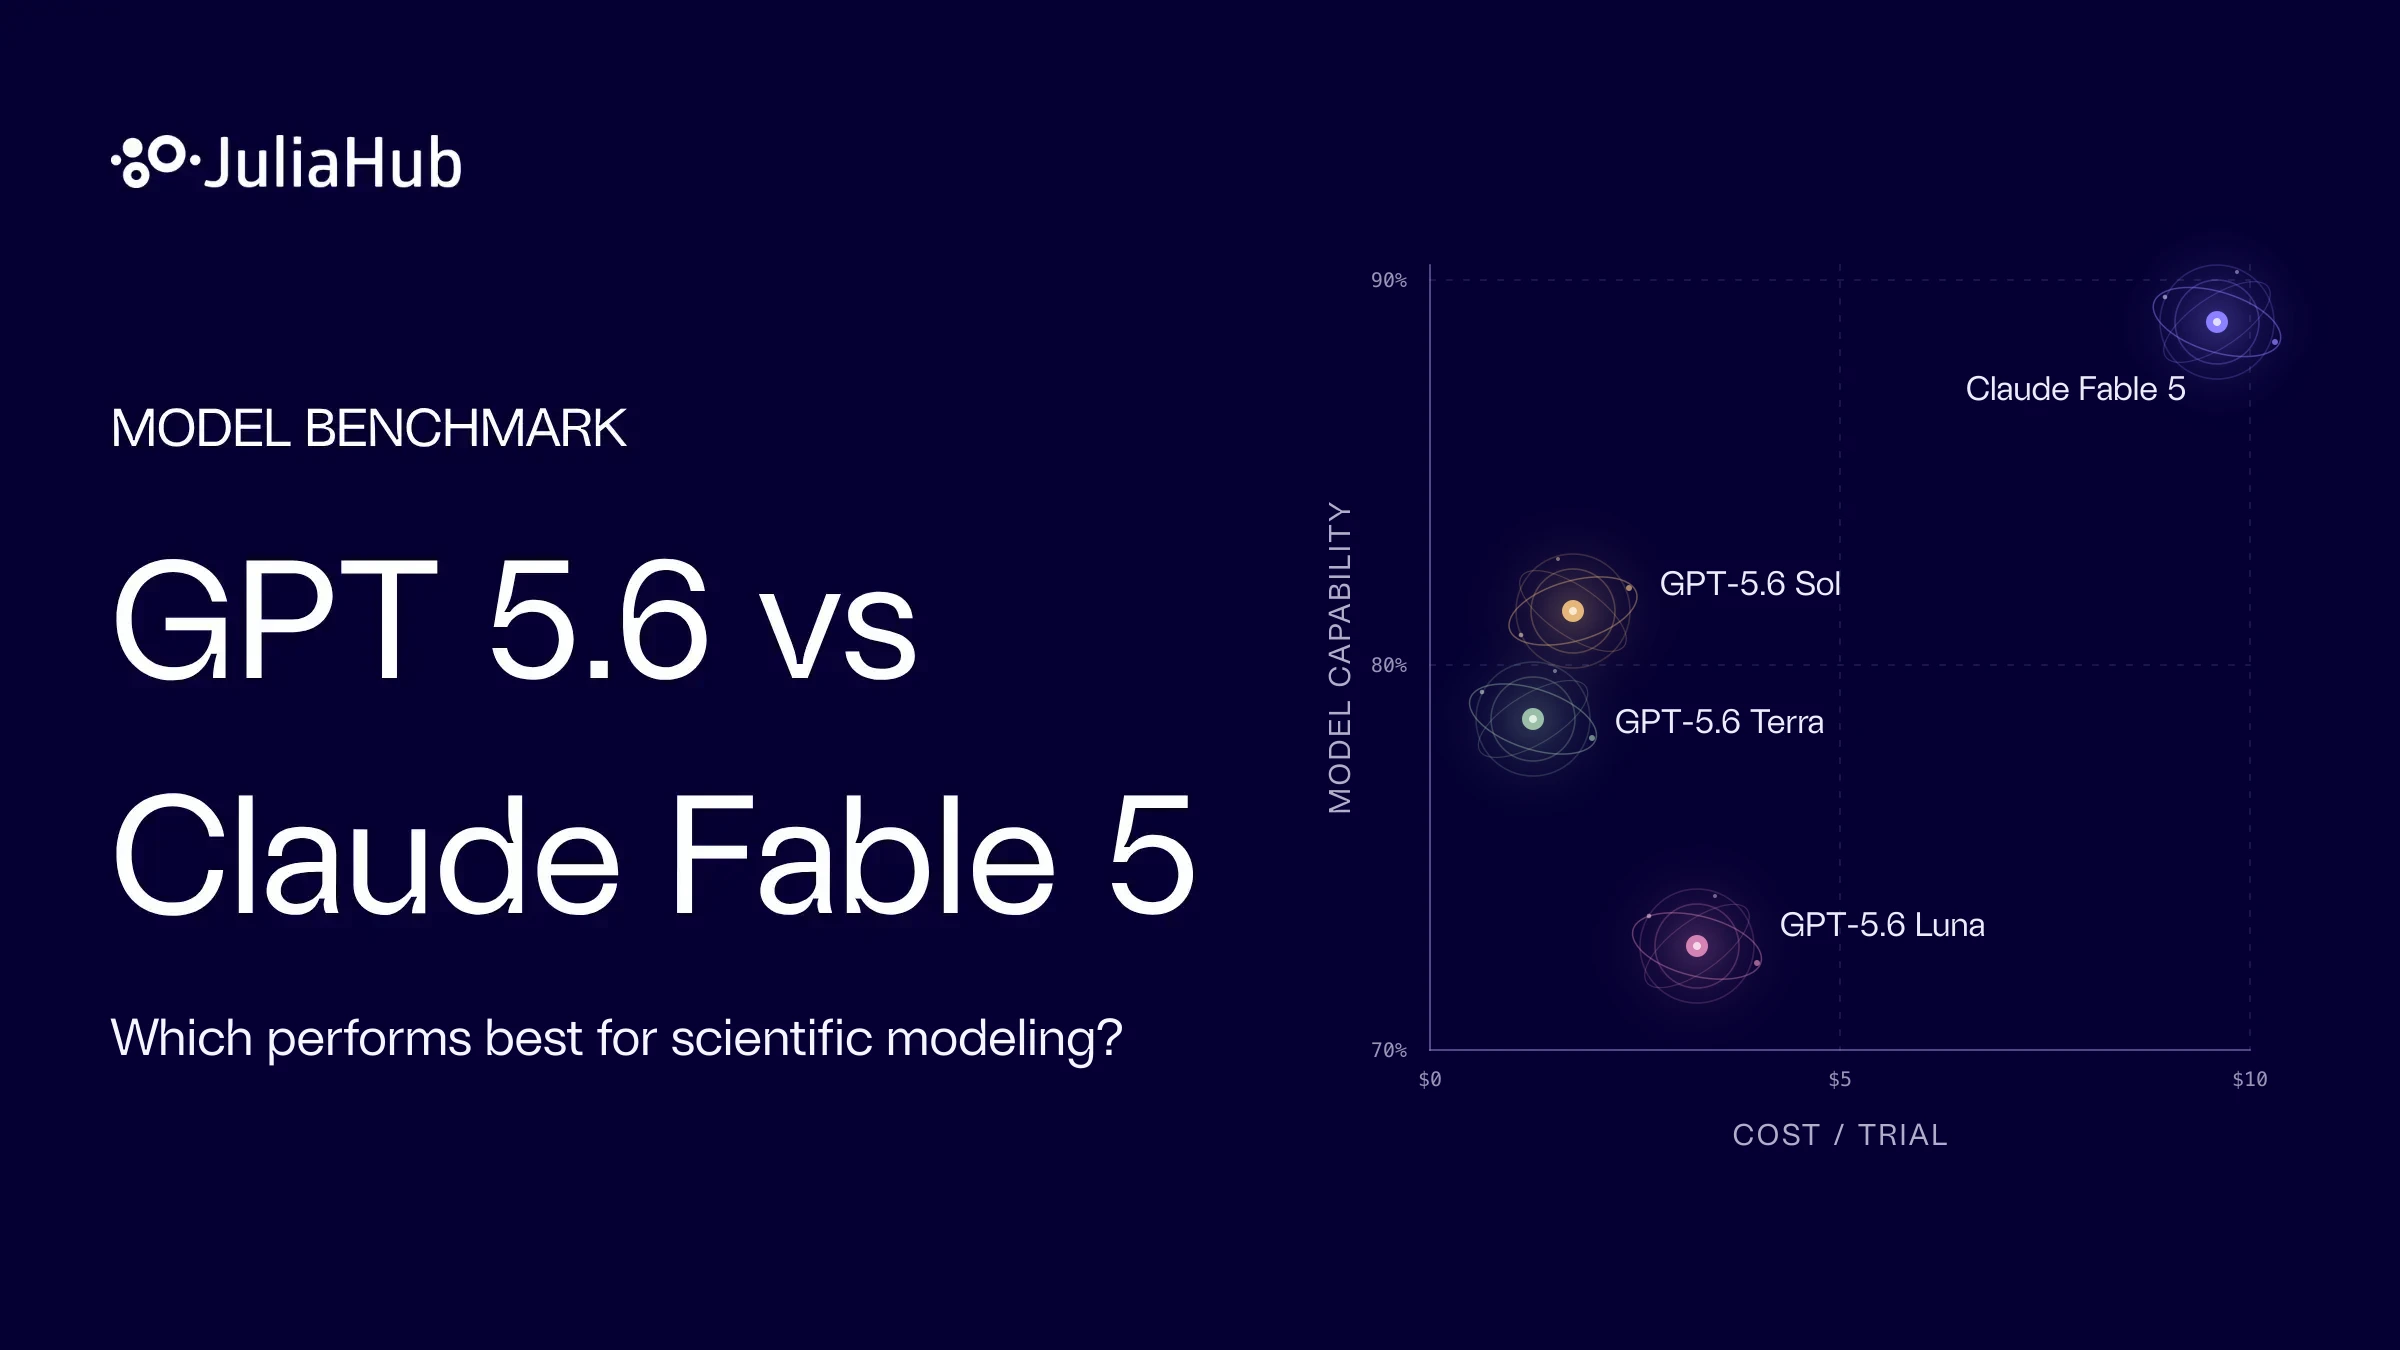
We tested the latest frontier models gpt-5.6-terra in our agent, on five modeling and simulation problems of varying difficulty. Here are the results:
claude-fable-5
0.889
weighted score $9.60 / trial · 16.1 min
gpt-5.6-sol
0.814
weighted score $1.74 / trial · 13.4 min
gpt-5.6-terra
0.786
weighted score $1.25 / trial · 12.6 min
gpt-5.6-luna
0.727
weighted score $3.26 / trial · 25.0 min
A container combines a model, the Dyad harness, pinned configuration, and a sealed problem. The agent derives, compiles, simulates, and verifies a model before a grader compares it with sealed ground truth.
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHubTHE CONTAINERPROBLEM · SEALEDworkspace + ground truthCONFIGxhigh · 1M ctx · 128kHARNESSDyad AgentMODELgpt-5.6-terrasolveTHE AGENT▸ read problem▸ derive physics▸ write dyad/model.dyad▸ compile▸ simulate · verify ▌grade itTHE GRADER — SIMULATE BOTH, THEN COMPAREtime →ground truthsubmittedscoreGRADE1.000.96
1 · the container
MODEL
gpt-5.6-terra
HARNESS
Dyad Agent
CONFIG
xhigh · 1M ctx · 128k
PROBLEM · SEALED
workspace + ground truth
↓
2 · the agent
▸ read problem▸ derive physics▸ write dyad/model.dyad▸ compile▸ simulate · verify
↓
3 · the grader
Simulate both, then compare
↓
4 · grade
trajectory match
0.96
A container combines a model, the Dyad harness, pinned configuration, and a sealed problem. The agent derives, compiles, simulates, and verifies a model before a grader compares it with sealed ground truth.
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHubTHE CONTAINERPROBLEM · SEALEDworkspace + ground truthCONFIGxhigh · 1M ctx · 128kHARNESSDyad AgentMODELgpt-5.6-terrasolveTHE AGENT▸ read problem▸ derive physics▸ write dyad/model.dyad▸ compile▸ simulate · verify ▌grade itTHE GRADER — SIMULATE BOTH, THEN COMPAREtime →ground truthsubmittedscoreGRADE1.000.96
1 · the container
MODEL
gpt-5.6-terra
HARNESS
Dyad Agent
CONFIG
xhigh · 1M ctx · 128k
PROBLEM · SEALED
workspace + ground truth
↓
2 · the agent
▸ read problem▸ derive physics▸ write dyad/model.dyad▸ compile▸ simulate · verify
↓
3 · the grader
Simulate both, then compare
↓
4 · grade
trajectory match
0.96
A container combines a model, the Dyad harness, pinned configuration, and a sealed problem. The agent derives, compiles, simulates, and verifies a model before a grader compares it with sealed ground truth.
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHubTHE CONTAINERPROBLEM · SEALEDworkspace + ground truthCONFIGxhigh · 1M ctx · 128kHARNESSDyad AgentMODELgpt-5.6-terrasolveTHE AGENT▸ read problem▸ derive physics▸ write dyad/model.dyad▸ compile▸ simulate · verify ▌grade itTHE GRADER — SIMULATE BOTH, THEN COMPAREtime →ground truthsubmittedscoreGRADE1.000.96
1 · the container
MODEL
gpt-5.6-terra
HARNESS
Dyad Agent
CONFIG
xhigh · 1M ctx · 128k
PROBLEM · SEALED
workspace + ground truth
↓
2 · the agent
▸ read problem▸ derive physics▸ write dyad/model.dyad▸ compile▸ simulate · verify
↓
3 · the grader
Simulate both, then compare
↓
4 · grade
trajectory match
0.96
Physical AI lives or dies on whether the modeled physics is correct. A model of an aircraft, a separation column or a charged particle can compile and run cleanly while the physics it encodes is impossible. Agentic AI makes this failure mode worse, because agents steer by feedback from tests, and the tests are often written by the same agent. In domains like web development or compilers that loop works well enough, since correct behavior is contained and checkable. In engineering, the real question is “does this match the real world?”, and that is much harder to close: the agent can pass every test it wrote while those tests rest on simplifications that don’t hold in the regime where the model will actually be used.
There is also a trust problem with the numbers that already exist. Nobody takes the model providers’ self-reported benchmarks at face value, and for good reason: the provider publishing the score is the same party with every incentive to tune for it. Our incentives point the other way. JuliaHub ships Dyad with multiple agent backends across vendors, and we win when our users get the best possible Dyad experience, whichever lab’s model delivers it. If one model is better at physical modeling, it is in our interest to find that out and recommend it. So we investigated: which one actually is?
To measure which frontier model handles that work best, we hold everything else still. The Dyad AI agent harness - purpose-built for modeling & simulation workflows - is pinned across every trial, along with the problems, the reasoning effort (xhigh), the context window (1M) and the token budget (128k). The only variable is the model: OpenAI’s GPT 5.6 family (terra, sol, luna) against Anthropic’s claude-fable-5. Three trials per model on each of the four core problems, one long-horizon trial each on the fifth: 52 graded runs in all.
#### 01 · The problems
How Physical AI Evaluation Works.
We ground our exploration in a subset of our internal evals: five sealed problems drawn from the daily work of modeling & simulation. We order them by difficulty, defined in terms of the stages a correct solution must chain through, the careful details where a small slip is fatal, the easy shortcuts within reach, and the engineering work around the modeling itself - from parsing specs to repairing harnesses. We selected each for the same property: they admit solutions that compile and run green while being physically wrong. Grading therefore ignores the code and scores the full simulated trajectory against sealed ground truth. The hardest of the five is NASA’s HL-20 flight vehicle. An easier version of the problem is walked through in detail in this video; the study runs a harder, sealed variant.
P1Constitutive consistencyP2Constrained consistencyP3Relativistic dynamicsP4Steady-state linearizationP5Long-horizon flight vehicleEvery previous problem at onceRead the engineering spec and aerodynamic data, derive six-degree-of-freedom motion, simulate, verify, and iterate.
P1Constitutive consistencyP2Constrained consistencyP3Relativistic dynamicsP4Steady-state linearizationP5Long-horizon flight vehicleEvery previous problem at onceRead the engineering spec and aerodynamic data, derive six-degree-of-freedom motion, simulate, verify, and iterate.
P1Constitutive consistencyP2Constrained consistencyP3Relativistic dynamicsP4Steady-state linearizationP5Long-horizon flight vehicleEvery previous problem at onceRead the engineering spec and aerodynamic data, derive six-degree-of-freedom motion, simulate, verify, and iterate.
#### 02 · The scoreboard
What they scored.
We run every model through the full suite - three trials on each of P1–P4, one on the long-horizon P5 - and grade every trial against sealed ground truth. Per-problem scores fold into a single number through a difficulty-weighted average, the hardest weighing the most. Cost and time carry no weighting: average cost per trial and average wall-clock per trial each get a tab:
A toggleable comparison of difficulty-weighted score against cost or wall-clock time for four frontier models.
costtime
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHub$2$4$6$8$100.700.750.800.850.90cost per trial (USD)difficulty-weighted scoregpt-5.6-terra0.786 · $1.25gpt-5.6-sol0.814 · $1.74gpt-5.6-luna0.727 · $3.26claude-fable-50.889 · $9.60
gpt-5.6-terraweighted score0.786
cost per trial$1.25
gpt-5.6-solweighted score0.814
cost per trial$1.74
gpt-5.6-lunaweighted score0.727
cost per trial$3.26
claude-fable-5weighted score0.889
cost per trial$9.60
A toggleable comparison of difficulty-weighted score against cost or wall-clock time for four frontier models.
costtime
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHub$2$4$6$8$100.700.750.800.850.90cost per trial (USD)difficulty-weighted scoregpt-5.6-terra0.786 · $1.25gpt-5.6-sol0.814 · $1.74gpt-5.6-luna0.727 · $3.26claude-fable-50.889 · $9.60
gpt-5.6-terraweighted score0.786
cost per trial$1.25
gpt-5.6-solweighted score0.814
cost per trial$1.74
gpt-5.6-lunaweighted score0.727
cost per trial$3.26
claude-fable-5weighted score0.889
cost per trial$9.60
A toggleable comparison of difficulty-weighted score against cost or wall-clock time for four frontier models.
costtime
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHub$2$4$6$8$100.700.750.800.850.90cost per trial (USD)difficulty-weighted scoregpt-5.6-terra0.786 · $1.25gpt-5.6-sol0.814 · $1.74gpt-5.6-luna0.727 · $3.26claude-fable-50.889 · $9.60
gpt-5.6-terraweighted score0.786
cost per trial$1.25
gpt-5.6-solweighted score0.814
cost per trial$1.74
gpt-5.6-lunaweighted score0.727
cost per trial$3.26
claude-fable-5weighted score0.889
cost per trial$9.60
The single number above has anatomy. Per problem, averaged across trials, the same three lenses:
A toggleable per-problem comparison of score, cost, and time for each model across five problems in difficulty order.
scorecosttime
fablesolterraluna
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHub0.40.60.81.0P1P2P3P4P5score (avg over trials)easier → harder
P1easy
fable1.000
sol1.000
terra1.000
luna1.000
P2
fable1.000
sol1.000
terra1.000
luna0.667
P3
fable1.000
sol0.667
terra1.000
luna1.000
P4
fable1.000
sol1.000
terra0.667
luna1.000
P5very hard
fable0.690
sol0.660
terra0.590
luna0.383
A toggleable per-problem comparison of score, cost, and time for each model across five problems in difficulty order.
scorecosttime
fablesolterraluna
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHub0.40.60.81.0P1P2P3P4P5score (avg over trials)easier → harder
P1easy
fable1.000
sol1.000
terra1.000
luna1.000
P2
fable1.000
sol1.000
terra1.000
luna0.667
P3
fable1.000
sol0.667
terra1.000
luna1.000
P4
fable1.000
sol1.000
terra0.667
luna1.000
P5very hard
fable0.690
sol0.660
terra0.590
luna0.383
A toggleable per-problem comparison of score, cost, and time for each model across five problems in difficulty order.
scorecosttime
fablesolterraluna
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHub0.40.60.81.0P1P2P3P4P5score (avg over trials)easier → harder
P1easy
fable1.000
sol1.000
terra1.000
luna1.000
P2
fable1.000
sol1.000
terra1.000
luna0.667
P3
fable1.000
sol0.667
terra1.000
luna1.000
P4
fable1.000
sol1.000
terra0.667
luna1.000
P5very hard
fable0.690
sol0.660
terra0.590
luna0.383
#### 03 · Work-style fingerprints
Each model has its own approach.
We analyze the transcripts behind every trial. Each tool call is bucketed by what the agent was doing at that moment - orienting in the problem, deriving and testing physics, editing the model, compiling, or hunting for something to copy - then counted per trial and averaged per model. The result is a work-style fingerprint:
Stacked bars compare how each model divides tool activity by call count or by time, with hover and focus tooltips.
by callsby time
orient & readderive & testedit the modelcompilehunt
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHub102030405060tool calls per trial (mean)terra50%28%12%10%0%41 callssol49%26%14%12%0%33 callsluna56%27%9%7%1%59 callsfable38%39%12%11%0%28 calls
orient & readderive & testedit the modelcompilehunt
terra
50%28%12%
41 calls
sol
49%26%14%
33 calls
luna
56%27%9%
59 calls
fable
38%39%
28 calls
102030405060
tool calls per trial (mean)
Stacked bars compare how each model divides tool activity by call count or by time, with hover and focus tooltips.
by callsby time
orient & readderive & testedit the modelcompilehunt
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHub102030405060tool calls per trial (mean)terra50%28%12%10%0%41 callssol49%26%14%12%0%33 callsluna56%27%9%7%1%59 callsfable38%39%12%11%0%28 calls
orient & readderive & testedit the modelcompilehunt
terra
50%28%12%
41 calls
sol
49%26%14%
33 calls
luna
56%27%9%
59 calls
fable
38%39%
28 calls
102030405060
tool calls per trial (mean)
Stacked bars compare how each model divides tool activity by call count or by time, with hover and focus tooltips.
by callsby time
orient & readderive & testedit the modelcompilehunt
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHub102030405060tool calls per trial (mean)terra50%28%12%10%0%41 callssol49%26%14%12%0%33 callsluna56%27%9%7%1%59 callsfable38%39%12%11%0%28 calls
orient & readderive & testedit the modelcompilehunt
terra
50%28%12%
41 calls
sol
49%26%14%
33 calls
luna
56%27%9%
59 calls
fable
38%39%
28 calls
102030405060
tool calls per trial (mean)
The bars say how the work divides; the transcripts show the temperament behind it. Four portraits, drawn from where each model was tested hardest:
Fable verifies by trying to fail. In one trial on the relativistic dynamics problem it swept solver tolerances across three decades, watching the mass-shell invariant u·u drift, before committing the run at 1e-10. It checked its fields against an independent reimplementation at 200 random points - then deliberately sign-flipped a field component to prove the check could fail (residual 2.0 wrong, 0.066 right). It refused to treat the time component of the initial four-velocity as a free input, deriving it from the mass-shell constraint instead. Twenty-eight calls per trial is not haste: it is a model that writes once because it has already tried to break what it is about to write. The bill for that conviction arrives later, in tokens.
Sol specifies more than the task asks. The habit cuts both ways. On the constitutive problem it built one of only two genuinely independent oracles in the cohort, closing a quadrature check of the constitutive identity to 3.7e-12 under the session title “Falsify the update against the independent bulk-modulus definition.” On the relativistic problem the same instinct manufactured its slip: the problem pins the z-component of the initial four-velocity at -0.62, and sol renormalized the state so the coordinate velocity came out at -0.62 instead, handing the particle 27% excess longitudinal momentum. Its own consistency check then blessed the misreading: mass-shell exactly one, velocity exactly as read, every downstream check self-consistent and wrong. Precision is not the same thing as fidelity to the spec.
Luna iterates where it should investigate. It carries the least configuration into a run and reads more of the problem than anyone, which serves it well on the easier problems. When the physics pushed back on the constrained-consistency problem, the same temperament turned into churn: 68 tool calls in a single trial, and a committed solution still 30% off. That trial was also the most-validated in the cohort - 22 checks, every one verifying its own equations against themselves - and the pattern repeats: on the constitutive problem, luna was the only model that never tested against anything independent of its committed equations. Validation without an external reference isn’t validation.
Terra economizes. It spends the smallest share of its clock on derivation and testing and the largest on editing - more trial and error against the file - and it broadly gets away with it: correct formulations, the cheapest and fastest trials in the study. Its slip on the steady-state linearization problem is the study’s narrowest miss, and its strangest: the physics was exact, but terra rewrote the required simulation horizon (`stop = 5.0` became `stop = 3.0`), and the comparison drifts to 1.34% past the truncated run. The cruel twist: terra was the only model to build a nonlinear reference to validate its reduction - and it gave the reference the same truncated horizon, blinding its own check. The temperament that saves the money is the same one that trims the margins.
#### 04 · The frontier problem
The hardest problem, up close.
P5 asks for a complete flight vehicle: NASA’s HL-20 lifting body on approach, with six-degree-of-freedom rigid-body dynamics, aerodynamics from roughly 170 wind-tunnel tables, a standard atmosphere, and the control-surface mixer described in two NASA technical memos. Eight physics scenarios grade the result, from a gravity-only sanity check to a ten-second closed-loop flight. No model solved it. This is where the frontier separates:
Eight weighted HL-20 physics tests are shown for each model, including gravity, longitudinal and lateral dynamics, and full flight.
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHubgravity5%aero sweep15%subsonic10%trim15%pitch15%dutch roll10%energy10%full flight20%weightedfable1.0.50.92.69.770.69.920.69sol1.0.50.92.69.770.69.770.66terra1.0.50.85.69.770.69.460.59luna1.0.50.540.5400.610.38
gravity1.0
5% weight
aero sweep.50
15% weight
subsonic.92
10% weight
trim.69
15% weight
pitch.77
15% weight
dutch roll0
10% weight
energy.69
10% weight
full flight.92
20% weight
gravity1.0
5% weight
aero sweep.50
15% weight
subsonic.92
10% weight
trim.69
15% weight
pitch.77
15% weight
dutch roll0
10% weight
energy.69
10% weight
full flight.77
20% weight
gravity1.0
5% weight
aero sweep.50
15% weight
subsonic.85
10% weight
trim.69
15% weight
pitch.77
15% weight
dutch roll0
10% weight
energy.69
10% weight
full flight.46
20% weight
gravity1.0
5% weight
aero sweep.50
15% weight
subsonic.54
10% weight
trim0
15% weight
pitch.54
15% weight
dutch roll0
10% weight
energy0
10% weight
full flight.61
20% weight
Eight weighted HL-20 physics tests are shown for each model, including gravity, longitudinal and lateral dynamics, and full flight.
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHubgravity5%aero sweep15%subsonic10%trim15%pitch15%dutch roll10%energy10%full flight20%weightedfable1.0.50.92.69.770.69.920.69sol1.0.50.92.69.770.69.770.66terra1.0.50.85.69.770.69.460.59luna1.0.50.540.5400.610.38
gravity1.0
5% weight
aero sweep.50
15% weight
subsonic.92
10% weight
trim.69
15% weight
pitch.77
15% weight
dutch roll0
10% weight
energy.69
10% weight
full flight.92
20% weight
gravity1.0
5% weight
aero sweep.50
15% weight
subsonic.92
10% weight
trim.69
15% weight
pitch.77
15% weight
dutch roll0
10% weight
energy.69
10% weight
full flight.77
20% weight
gravity1.0
5% weight
aero sweep.50
15% weight
subsonic.85
10% weight
trim.69
15% weight
pitch.77
15% weight
dutch roll0
10% weight
energy.69
10% weight
full flight.46
20% weight
gravity1.0
5% weight
aero sweep.50
15% weight
subsonic.54
10% weight
trim0
15% weight
pitch.54
15% weight
dutch roll0
10% weight
energy0
10% weight
full flight.61
20% weight
Eight weighted HL-20 physics tests are shown for each model, including gravity, longitudinal and lateral dynamics, and full flight.
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHubgravity5%aero sweep15%subsonic10%trim15%pitch15%dutch roll10%energy10%full flight20%weightedfable1.0.50.92.69.770.69.920.69sol1.0.50.92.69.770.69.770.66terra1.0.50.85.69.770.69.460.59luna1.0.50.540.5400.610.38
gravity1.0
5% weight
aero sweep.50
15% weight
subsonic.92
10% weight
trim.69
15% weight
pitch.77
15% weight
dutch roll0
10% weight
energy.69
10% weight
full flight.92
20% weight
gravity1.0
5% weight
aero sweep.50
15% weight
subsonic.92
10% weight
trim.69
15% weight
pitch.77
15% weight
dutch roll0
10% weight
energy.69
10% weight
full flight.77
20% weight
gravity1.0
5% weight
aero sweep.50
15% weight
subsonic.85
10% weight
trim.69
15% weight
pitch.77
15% weight
dutch roll0
10% weight
energy.69
10% weight
full flight.46
20% weight
gravity1.0
5% weight
aero sweep.50
15% weight
subsonic.54
10% weight
trim0
15% weight
pitch.54
15% weight
dutch roll0
10% weight
energy0
10% weight
full flight.61
20% weight
Terra shipped a flight vehicle without reading the flight manual. Its one attempt to extract the NASA memos failed at minute 3.5 and it never tried again - so it invented the control mixer, reverse-engineering gains from the scenario tables. It ran the full flight four times and never looked past the return code; its own log shows a control surface settling eleven degrees from the spec’s stated value, unremarked. Cheapest attempt in the cohort, worst full flight.
Sol read everything and verified the parts. It extracted both memos by minute three, built its aerodynamics as an interpreter over the supplied tables, and locked them against the 24 check cases NASA embedded in the data file - all 24 passing by minute 27 of the fastest run in the cohort. What it never verified was a trajectory: its dutch-roll run ends below sea level in a 48-degree dive, and its conclusion was that “the rudder’s behavior seems correct.”
Luna never got the airplane to fly. It fought one compile error twenty-three times across eighty minutes, then resolved it by rewiring the vehicle’s vertical aerodynamic force and pitch torque to zero and shipping scenarios it only ever ran for a tenth of a second. Its committed vehicle descends without ever rotating: the attitude quaternion never moves. Two and a quarter hours, 544 tool calls, last place.
Fable spent a third of its run reading before it wrote a line. Spec, tables, both memos - it rendered PDF pages as images to settle one ambiguous constant - then wrote sixteen files that compiled on the first try, ran all eight scenarios, and closed with a falsification battery against every oracle it could find. Where an external reference existed, it scored highest in the cohort; where none did, it fell with everyone else.
Ten seconds of closed-loop flight compare every model's committed altitude trajectory with the sealed reference.
fablesolterraluna
sealed referencecommitted model
ends 0.4 m high
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHub200022502500275030002s4s6s8s10saltitude (m)ends 0.4 m high
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHub2000250030000s5s10sends 0.4 m high
Ten seconds of closed-loop flight compare every model's committed altitude trajectory with the sealed reference.
fablesolterraluna
sealed referencecommitted model
ends 0.4 m high
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHub200022502500275030002s4s6s8s10saltitude (m)ends 0.4 m high
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHub2000250030000s5s10sends 0.4 m high
Ten seconds of closed-loop flight compare every model's committed altitude trajectory with the sealed reference.
fablesolterraluna
sealed referencecommitted model
ends 0.4 m high
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHub200022502500275030002s4s6s8s10saltitude (m)ends 0.4 m high
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHub2000250030000s5s10sends 0.4 m high
A time-aligned event timeline shows each model's reading, derivation, editing, compilation, simulation, and verification activity.
derive & testedit the modelcompile
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHub020406080100120140wall-clock minutesfablescored 0.69 · $56.74solscored 0.66 · $8.87terrascored 0.59 · $6.08lunascored 0.38 · $24.28
fable
63 min0.69 score$56.74
73 derive · 20 edit · 6 compile
sol
32 min0.66 score$8.87
44 derive · 33 edit · 7 compile
terra
38 min0.59 score$6.08
107 derive · 36 edit · 17 compile
luna
138 min0.38 score$24.28
101 derive · 225 edit · 74 compile
A time-aligned event timeline shows each model's reading, derivation, editing, compilation, simulation, and verification activity.
derive & testedit the modelcompile
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHub020406080100120140wall-clock minutesfablescored 0.69 · $56.74solscored 0.66 · $8.87terrascored 0.59 · $6.08lunascored 0.38 · $24.28
fable
63 min0.69 score$56.74
73 derive · 20 edit · 6 compile
sol
32 min0.66 score$8.87
44 derive · 33 edit · 7 compile
terra
38 min0.59 score$6.08
107 derive · 36 edit · 17 compile
luna
138 min0.38 score$24.28
101 derive · 225 edit · 74 compile
A time-aligned event timeline shows each model's reading, derivation, editing, compilation, simulation, and verification activity.
derive & testedit the modelcompile
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHub020406080100120140wall-clock minutesfablescored 0.69 · $56.74solscored 0.66 · $8.87terrascored 0.59 · $6.08lunascored 0.38 · $24.28
fable
63 min0.69 score$56.74
73 derive · 20 edit · 6 compile
sol
32 min0.66 score$8.87
44 derive · 33 edit · 7 compile
terra
38 min0.59 score$6.08
107 derive · 36 edit · 17 compile
luna
138 min0.38 score$24.28
101 derive · 225 edit · 74 compile
#### 05 · The verdict
The Verdict.
On demonstrated capability - the proportion of the problem set an agent can solve - the answer is not close. Anthropic’s Fable posts the highest difficulty-weighted score in the study, is the only model to sweep all twelve trials on the four core problems, and leads the field on the unsolved HL-20 - top marks on every graded test where an external reference existed. It charges for the conviction: $9.60 a trial, $124.76 for the study, three to eight times the GPTs.
OpenAI’s GPT 5.6 family owns the value frontier. Sol is second on merit at a fifth of Fable’s price and built some of the study’s best independent verification along the way. Terra is the cheapest and fastest route to a credible score, trimming margins to get there. Luna trails on every axis: last on score, second-highest cost, and twice its siblings’ wall-clock.
| model | weighted score | P1–P4 trials | P5 (HL-20) | avg $ / trial | study total | avg min / trial | | -------------- | -------------- | ------------ | ---------- | ------------- | ----------- | --------------- | | claude-fable-5 | 0.889 | 12 / 12 | 0.69 | $9.60 | $124.76 | 16.1 | | gpt-5.6-sol | 0.814 | 11 / 12 | 0.66 | $1.74 | $22.56 | 13.4 | | gpt-5.6-terra | 0.786 | 11 / 12 | 0.59 | $1.25 | $16.24 | 12.6 | | gpt-5.6-luna | 0.727 | 11 / 12 | 0.38 | $3.26 | $42.41 | 25.0 |
So: if best means the most physics per dollar, it’s sol. If best means the highest probability that the committed model is actually right - the standard physical AI ultimately answers to - it’s claude-fable-5. But note what every row of that table has in common. Each model hit these numbers with the same instrument at its back: a harness that fed it compiler feedback, simulation tooling and a grader that refuses to be charmed by code that merely runs.
The model is the variable. The harness is the multiplier.>
Dyad AI · Eval Infrastructure
#### 06 · The bigger lever
How the harness changes things.
Everything above varied the model and held the harness still, and the honest summary of that experiment is smaller than the marketing around frontier releases would suggest: choosing the best model over the worst was worth 0.162 weighted points, 0.727 to 0.889. Our companion study ran the inverse experiment - model pinned, harness varied - sending the same frontier model at the same sealed problems through the Dyad AI harness and through a stock general-purpose coding agent: Claude Code, given the same tailored documentation and a Dyad compile tool.
The same frontier model scores 0.899 in the Dyad AI harness and 0.533 in a stock coding agent at nearly identical cost.
costtime
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHub$2$4$6$8$100.500.600.700.800.90cost per trial (USD)difficulty-weighted scoreDyad AI0.899 · $4.20Claude Code0.533 · $4.65
Dyad AI0.899
weighted score$4.20
Claude Code0.533
weighted score$4.65
Dyad leads by 0.366 weighted points
The same frontier model scores 0.899 in the Dyad AI harness and 0.533 in a stock coding agent at nearly identical cost.
costtime
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHub$2$4$6$8$100.500.600.700.800.90cost per trial (USD)difficulty-weighted scoreDyad AI0.899 · $4.20Claude Code0.533 · $4.65
Dyad AI0.899
weighted score$4.20
Claude Code0.533
weighted score$4.65
Dyad leads by 0.366 weighted points
The same frontier model scores 0.899 in the Dyad AI harness and 0.533 in a stock coding agent at nearly identical cost.
costtime
GPT-5.6 vs Claude Fable 5 for Physical AI, which performs best? - Blog | JuliaHub$2$4$6$8$100.500.600.700.800.90cost per trial (USD)difficulty-weighted scoreDyad AI0.899 · $4.20Claude Code0.533 · $4.65
Dyad AI0.899
weighted score$4.20
Claude Code0.533
weighted score$4.65
Dyad leads by 0.366 weighted points
That inverse experiment moves the score by more. Same model, same problems, nearly identical spend: 0.533 in the stock agent, 0.899 inside the Dyad harness - a 0.366-point gap, more than double the 0.162 separating the best and worst frontier models above. And the stock agent didn’t lose on style points: on the relativistic dynamics problem it scored zero in every trial it ran. Put plainly: swapping the model changes who wins; swapping the harness changes whether the physics is right at all.
Both agents are graded identically - the physical model each one commits is simulated and compared against sealed reference trajectories neither can see. What differs is what each harness enforces before the grade. A general coding agent can derive equations and behaviour too, and it can even verify - nothing stops it, but nothing makes it do so either.
The Dyad harness is specifically meant to guide the LLM it wraps down the ideal path for physical modeling. Verification is not something the model has to feel like doing; it happens by construction. That is the difference between “my code compiles” and “my physics survived contact with a solver,” and no amount of model quality substitutes for it.
So the ranking of frontier models above is real - inside a single harness. But it is the second-order term. If demonstrated capability - the proportion of the problem set the agent can solve - is what you care about, the first decision is the instrument - Dyad \- and the second is the best frontier model you can afford inside it. The harness-versus-harness study is its own write-up, coming next: stay tuned.
The agent stack behind this study is the one that ships with Dyad 3.0, which adds a modular skills system so engineers can extend the agent with custom workflows of their own. The documentation covers the language, the component libraries and the agent; the Dyad 3.0 launch party is the guided tour.
- Dyad
- Docs
- Dyad 3.0 release notes
- Video · PDF-to-simulation with the Dyad agent
- Video · Dyad 3.0 launch party
#### 07 · Conclusion
Conclusion.
1. Fable demonstrates the broadest capability. The highest difficulty-weighted score in the study (0.889), the only clean sweep of the four core problems, and the best result on the unsolved HL-20 - leading every graded test where an external reference existed. If the committed model being physically right is the requirement, Fable is the model to buy.
2. GPT 5.6 Sol wins on value. Second on merit at 0.814 for $1.74 a trial, roughly a fifth of Fable’s price, with some of the study’s best independent verification habits. For the bulk of day-to-day modeling work, Sol is the rational default.
3. The harness is the bigger lever. The gap between the best and worst frontier model here is 0.162 weighted points; the gap between harnesses is more than double that. The sharpest version of the point: the same frontier model scores 0.899 inside the Dyad harness and 0.533 in a stock coding agent. Swapping the frontier model changes the ranking by tenths of a point; swapping the instrument changes whether the physics is right at all. Pick the harness first, then the best model you can afford inside it.
Tags
Authors
 Dr. Chris RackauckasVP of Modeling & Simulation - JuliaHub
Dr. Chris Rackauckas is the VP of Modeling and Simulation at JuliaHub, the Director of Scientific Research at Pumas-AI, Co-PI of the Julia Lab at MIT, and the lead developer of the SciML Open Source Software Organization. He is the lead developer of the Pumas project and has received a top presentation award at every ACoP in the last 3 years for improving methods for uncertainty quantification, automated GPU acceleration of nonlinear mixed effects modeling (NLME), and machine learning assisted construction of NLME models with DeepNLME. For these achievements, Chris received the Emerging Scientist award from ISoP.
Anas Abdelrehim is the team lead for AI at Dyad - he builds next generation tools for engineers and scientists to make possible the technologies of tomorrow. His work includes building and scaling surrogate model generation platforms for engineers and industry experts alike, as well as workflows that augment modeling, discovery and simulation of physics using SciML machine learning and Agentic systems"
 Anshul SinghviSoftware Engineer - JuliaHub
Anshul Singhvi is a contributor to Julia's plotting (Makie.jl), geospatial (JuliaGeo) and documentation ecosystems, and a developer on the Dyad team.
Authors
Dr. Chris RackauckasVP of Modeling & Simulation - JuliaHub
Dr. Chris Rackauckas is the VP of Modeling and Simulation at JuliaHub, the Director of Scientific Research at Pumas-AI, Co-PI of the Julia Lab at MIT, and the lead developer of the SciML Open Source Software Organization. He is the lead developer of the Pumas project and has received a top presentation award at every ACoP in the last 3 years for improving methods for uncertainty quantification, automated GPU acceleration of nonlinear mixed effects modeling (NLME), and machine learning assisted construction of NLME models with DeepNLME. For these achievements, Chris received the Emerging Scientist award from ISoP.
Anas Abdelrehim is the team lead for AI at Dyad - he builds next generation tools for engineers and scientists to make possible the technologies of tomorrow. His work includes building and scaling surrogate model generation platforms for engineers and industry experts alike, as well as workflows that augment modeling, discovery and simulation of physics using SciML machine learning and Agentic systems"
Anshul SinghviSoftware Engineer - JuliaHub
Anshul Singhvi is a contributor to Julia's plotting (Makie.jl), geospatial (JuliaGeo) and documentation ecosystems, and a developer on the Dyad team.
Authors
Dr. Chris RackauckasVP of Modeling & Simulation - JuliaHub
Dr. Chris Rackauckas is the VP of Modeling and Simulation at JuliaHub, the Director of Scientific Research at Pumas-AI, Co-PI of the Julia Lab at MIT, and the lead developer of the SciML Open Source Software Organization. He is the lead developer of the Pumas project and has received a top presentation award at every ACoP in the last 3 years for improving methods for uncertainty quantification, automated GPU acceleration of nonlinear mixed effects modeling (NLME), and machine learning assisted construction of NLME models with DeepNLME. For these achievements, Chris received the Emerging Scientist award from ISoP.
Anas Abdelrehim is the team lead for AI at Dyad - he builds next generation tools for engineers and scientists to make possible the technologies of tomorrow. His work includes building and scaling surrogate model generation platforms for engineers and industry experts alike, as well as workflows that augment modeling, discovery and simulation of physics using SciML machine learning and Agentic systems"
Anshul SinghviSoftware Engineer - JuliaHub
Anshul Singhvi is a contributor to Julia's plotting (Makie.jl), geospatial (JuliaGeo) and documentation ecosystems, and a developer on the Dyad team.
‹ JuliaHub at JuliaCon Global 2026
Tradespace Exploration with the Dyad Agent ›
Learn about Dyad
Get Dyad Studio – Download and install the IDE to start building hardware like software.
Read the Dyad Documentation – Dive into the language, tools, and workflow.
Join the Dyad Community – Connect with fellow engineers, ask questions, and share ideas.
Contact Us
Want to get enterprise support, schedule a demo, or learn about how we can help build a custom solution? We are here to help.
Recent Blog Posts
Read More Jul 21, 2026•Company NewsJuliaHub at JuliaCon Global 2026
Read More Jul 17, 2026•Technical TutorialsTradespace Exploration with the Dyad Agent
Read More Jul 15, 2026•NewsletterThe Dyad Dispatch - July Edition
Recent Posts
Read MoreJul 21, 2026•Company NewsJuliaHub at JuliaCon Global 2026
Read MoreJul 17, 2026•Technical TutorialsTradespace Exploration with the Dyad Agent
Recent Blog Posts
Read MoreJul 21, 2026•Company NewsJuliaHub at JuliaCon Global 2026
Read MoreJul 17, 2026•Technical TutorialsTradespace Exploration with the Dyad Agent
Read MoreJul 15, 2026•NewsletterThe Dyad Dispatch - July Edition