Try unrolling a thread yourself!
Share this page!
×
Enter URL or ID to Unroll
×
Unroll Thread You can paste full URL like: https://x.com/threadreaderapp/status/1644127596119195649 or just the ID like: 1644127596119195649
How to get URL link on X (Twitter) App
1. On the Twitter thread, click on or icon on the bottom 2. Click again on or Share Via icon 3. Click on Copy Link to Tweet 4. Paste it above and click "Unroll Thread"! 5. More info at Twitter Help

#### Zhengyao Jiang
Subscribe
Jul 14 •8 tweets • 3 min read • Read on X
Bookmark Gift Link Save as PDF
The first experimental evidence of recursive self-improvement (RSI).
Autoresearching the autoresearch agent for eight days.
The result beats the harness we hand-tuned for two years, on held-out benchmarks: 🧵(1/7)

Our RSI system AIDE² has two autoresearch loops.
An inner loop, just like a normal autoresearch agent, optimizing code against an eval.
An outer loop, optimizing the inner-loop agent's harness code against the inner loop's average score across different benchmarks. (2/7) 
After 100 iterations, the outer loop discovered seven improvements over the baseline.
Including a new search policy, a memory system that compresses prompt by 16x, and a layered defense against reward hacking. (3/7) 
We test the discovered agents on held-out benchmarks the outer loop never saw.
They generalize. They beat the agent we hand-tuned for two years, on all three.
Two sit inside its training task families. The farthest sits outside, improving a physics-based weather model.
(4/7) 
We also see an emergent phenomenon where the outer loop pushes the inner-loop agent's reward hacking rate lower, with a combination of prompting and rule-based checks.
This was benchmarked on OOD GPU kernel engineering tasks that suffered from reward hacking.
(5/7) 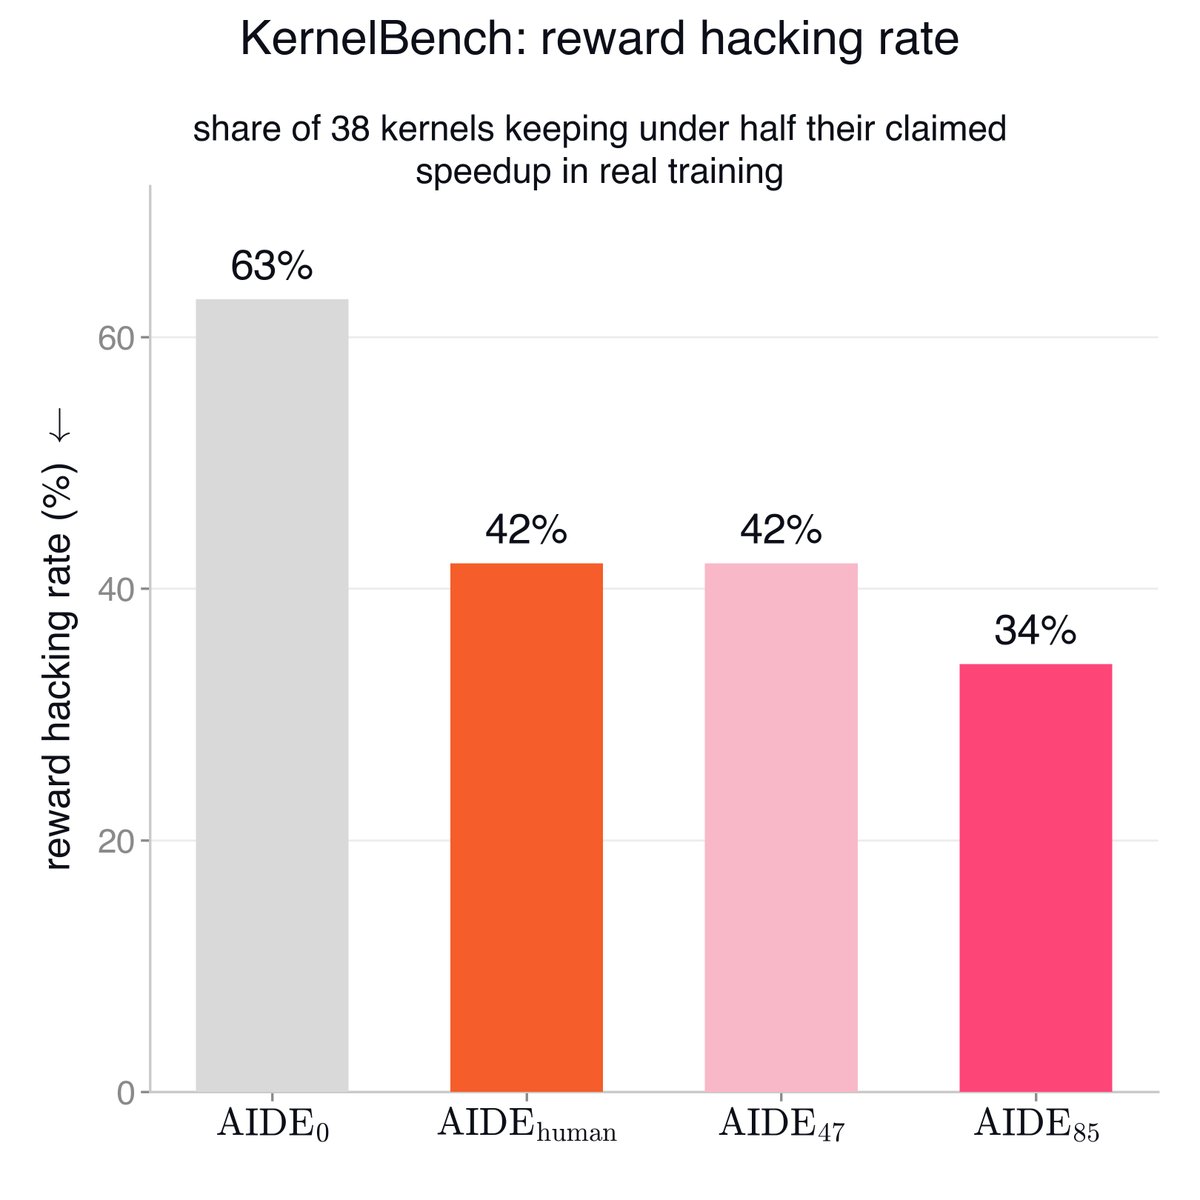
On our RSI ladder, AIDE² is Level 1.
Its self-improvement efficiency went beyond manual R&D with general AI tools, on held-out benchmarks.
We also tested Level 2, whether the improved inner agent makes a better outer loop. Results are mixed, and we do not claim ignition. (6/7) 
More in the blog post: \- a breakdown of the discovered algorithms \- the rejected ideas AIDE² tried, covering a surprising share of the search literature \- the dead code it shipped (7/7)weco.ai/blog/first-evi…
Very proud of the team, @DhruvSrikanth, @yuxiangwu\_, @dexhunt3r, and @BingchenZhao, for shipping such an ambitious project spanning nearly a year with relatively few resources. Also, a huge thank you to everyone who provided feedback on the draft, including @jeankaddour, @MinqiJiang, @morgymcg, @odysseus0z, @rosstaylor90, @OfirPress and many others!
• • •
Missing some Tweet in this thread? You can try to force a refresh
Keep Current with Zhengyao Jiang
Stay in touch and get notified when new unrolls are available from this author!
Add to "My Authors" Read all threads
This Thread may be Removed Anytime!
Twitter may remove this content at anytime! Save it as PDF for later use!
Save this thread as PDF
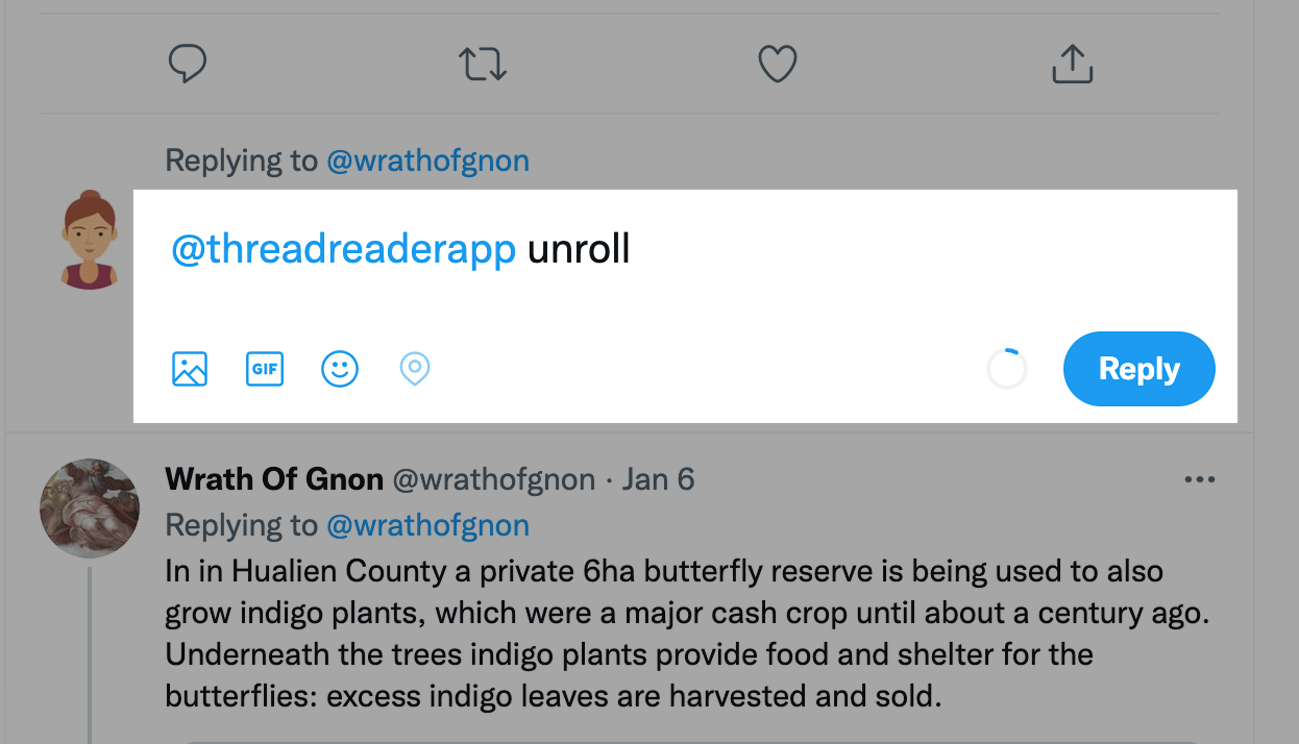
1. Follow @ThreadReaderApp to mention us! 2. From a Twitter thread mention us with a keyword "unroll" `@threadreaderapp unroll`
Practice here first or read more on our help page!
#### Zhengyao Jiang
Apr 2
Is autoresearch really better than classic hyperparameter tuning?
We did experiments comparing Optuna & autoresearch.
Autoresearch converges faster, is more cost-efficient, and even generalizes better: 🧵(1/6) 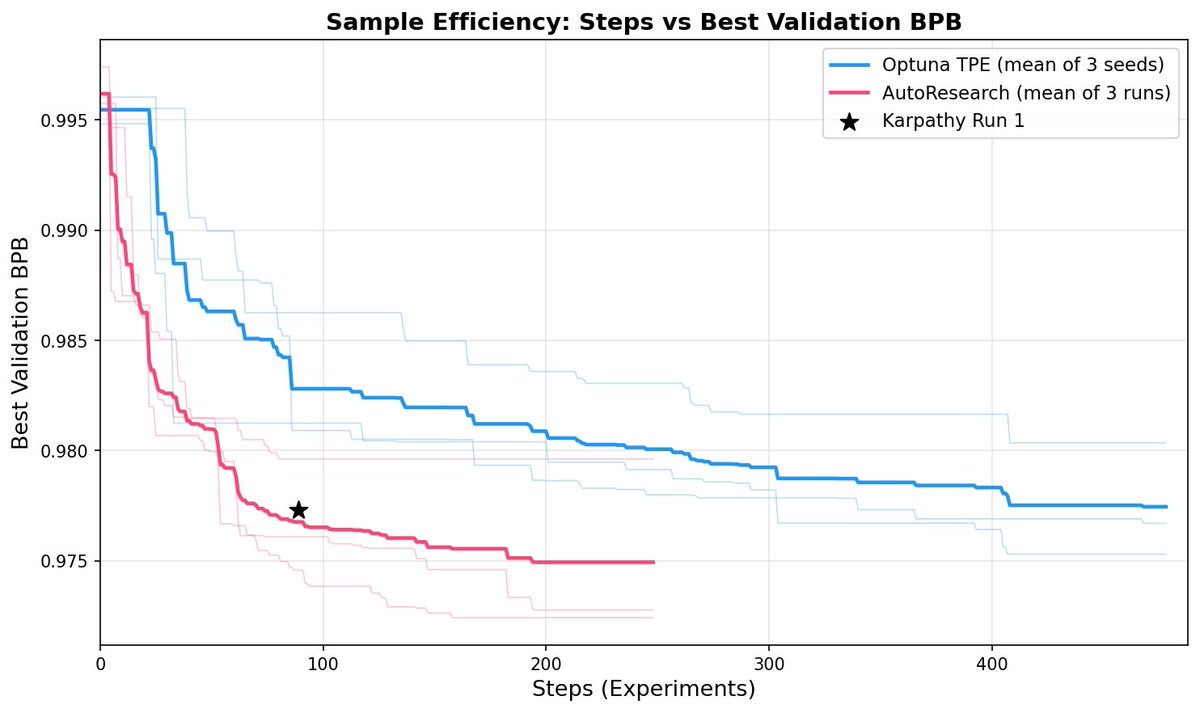
Experiments were done on NanoChat: we let Claude define Optuna’s search space to align the priors between methods.
Both optimization methods were run three times.
Autoresearch is far more sample-efficient on average: (2/6) 
In 5 min training setting, LLM tokens cost as much as GPUs, but despite a 2× higher per-step cost, AutoResearch still comes out ahead across all cost budgets: (3/6) 
Read 6 tweets
#### Zhengyao Jiang
Jan 29, 2025
Training LLMs with Reinforcement Learning (RL) isn’t a new idea.
So why does it suddenly seem to be working now (o1/DeepSeek)?
Here are a few theories and my thoughts on each of them: (1/N) 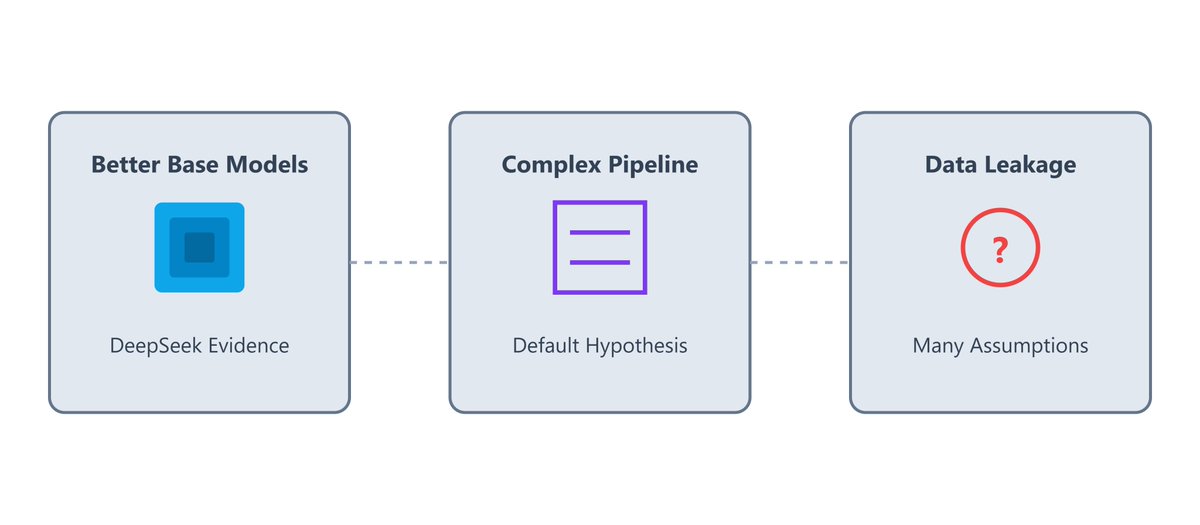
Better Base Models
The most plausible hypothesis in my opinion. There’s evidence in the DeepSeek R1 report:
Even if you want a small reasoning model, it’s much better to train a larger LM first and distill it back into smaller ones, rather than train a smaller one directly with RL. (2/N)
It Takes Time to Find the Right Pipeline
Yes, DeepSeek R1 adopted a rather simple RL algorithm. But the whole training pipeline is actually quite complex.
Barebones RL (R1-Zero) produces unreadable chain-of-thought and degrades general capabilities on non-STEM tasks. Eventually, they found a multi-stage approach, mixing different reward types in the final phase. It took strong conviction (and plenty of trials) to get here.
And actually, it might have taken the o1 team even more effort since they didn’t have proof of existence. (3/N)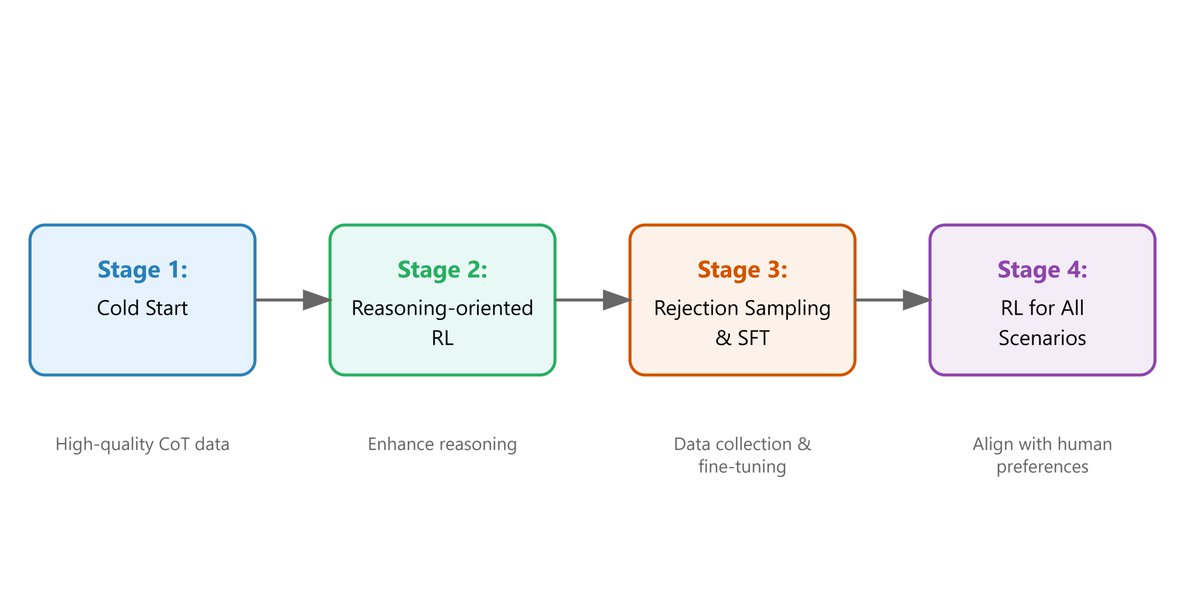
Read 5 tweets
#### Zhengyao Jiang
Jan 1, 2025
As a RL research myself, I once doubted Reinforcement Learning (RL) because massive self-supervised LLMs were dominating.
But now I see how RL can bring us closer to super-intelligent (ASI) systems—far beyond board games.
Here’s what changed my mind: (1/5) 
1) Why I Was Pessimistic About RL
RL soared to ASI levels in games like Go. But in real-world tasks, its poor data efficiency often makes it less economical than simply gathering more supervised examples. (2/5)
2) RLHF & O1 Reasoning
Fast-forward: RLHF and advanced reasoning models like O1 proved that RL can fine-tune beyond imitation learning by a large margin.
Read 5 tweets
#### Zhengyao Jiang
Feb 28, 2023
I finally find an explanation for why RL is needed for RLHF that satisfied me. It's actually like playing board games.
The reward model can only judge a full answer and a "critic" is needed to efficiently improve the intermediate moves (earlier tokens in the answer) 1/4 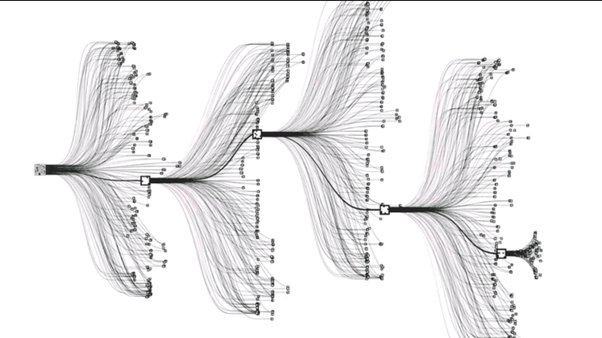
One question I always had about RLHF is why we bother to use approximate gradients coming from RL if both the reward function and the model are differentiable. And the key is in the auto-regressive sampling. The reward model is not connected to the language model directly. 2/4
Instead, it takes a full answer sampled from the language model as input. The autoregressive sampling process is not differentiable. Every single step of sampling is followed by many forking futures, forming a tree. 3/4
Read 5 tweets
#### Zhengyao Jiang
Aug 23, 2022
I'm excited to announce Trajectory Autoencoding Planner (TAP), a novel planning-based sequence modelling method that can scale to high dimensionality state-action space. (1/N)
🕸️Website: sites.google.com/view/latentplan
📜Paper: arxiv.org/abs/2208.10291
💻Code: github.com/ZhengyaoJiang/… 
Compared to Trajectory Transformer (TT), the planning of TAP is fast and its decision latency won't increase along with the state-action dimensionality. On high-dimensional offline control tasks, TAP shows strong performance, surpassing model-based and model-free baselines.(2/N) 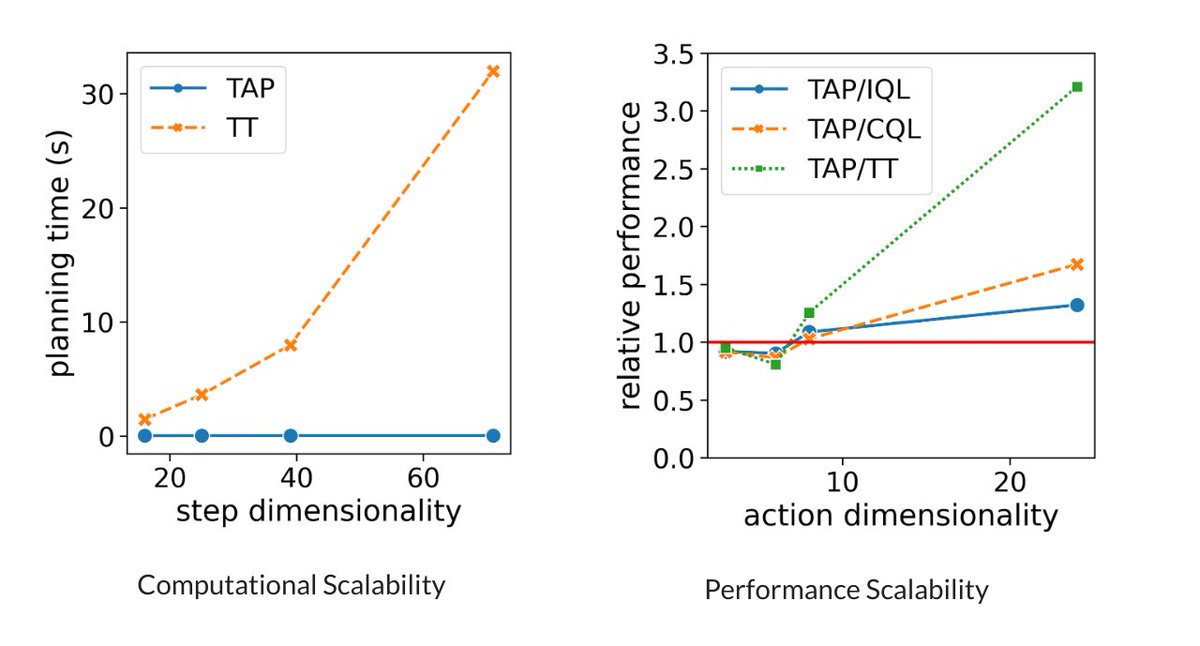
Using a state conditional VQ-VAE, TAP builds a map between possible future trajectories and latent code sequences, where each latent code corresponds to multiple steps of the potential complement of the existing trajectory. (3/N) 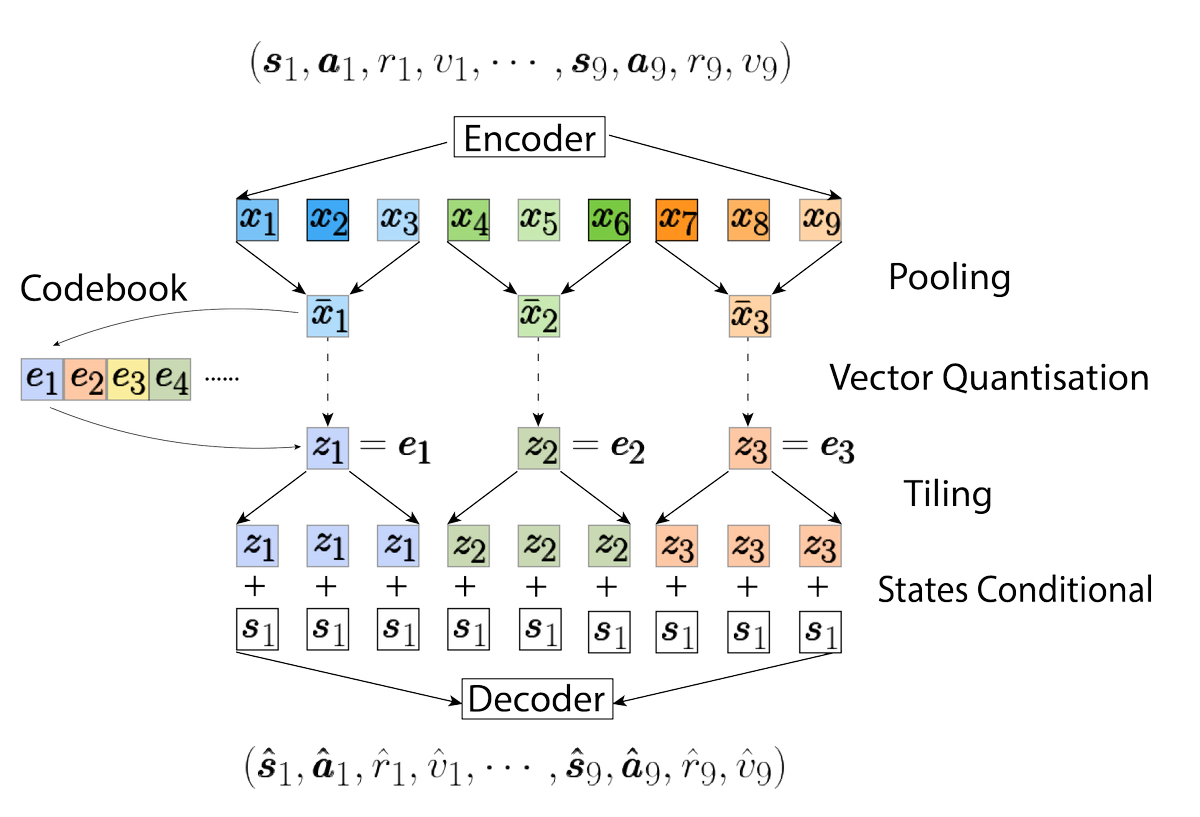
Read 8 tweets
Support us! We are indie developers!
---
This site is made by just two indie developers on a laptop doing marketing, support and development! Read more about the story.
Become a Premium Member ($3/month or $30/year) and get exclusive features!
Make a small donation by buying us coffee ($5) or help with server cost ($10)
Or Donate anonymously using crypto!
Ethereum
`0xfe58350B80634f60Fa6Dc149a72b4DFbc17D341E` copy
Bitcoin
`3ATGMxNzCUFzxpMCHL5sWSt4DVtS8UqXpi` copy
Thank you for your support!
Send Email!
×
Email the whole thread instead of just a link!
Separate emails with commas Message Send Thread As Email!
Email Successfully Sent!