Benchmark GenAI image models
What are you building?
Start from the job, not the model. Each path weights the same measurements for what actually decides success in that use case.
“I want to generate print-ready files”
“I want to create merch and stickers”
“I want designs with real text”
“I want to generate product ads”
“I want my users to create designs in my app”
“I want to personalize creatives at scale”
“I want to generate product imagery”
Same prompt. Every model. Side by side.
Identical text, default parameters, fixed seeds, no per-model tuning. Every result ships with its seed, latency, cost and native resolution, so you compare models, not prompt engineering.
Logo wordmark for a company called "Aurelia", geometric sans-serif, flat black on white, perfectly spelled, centered.
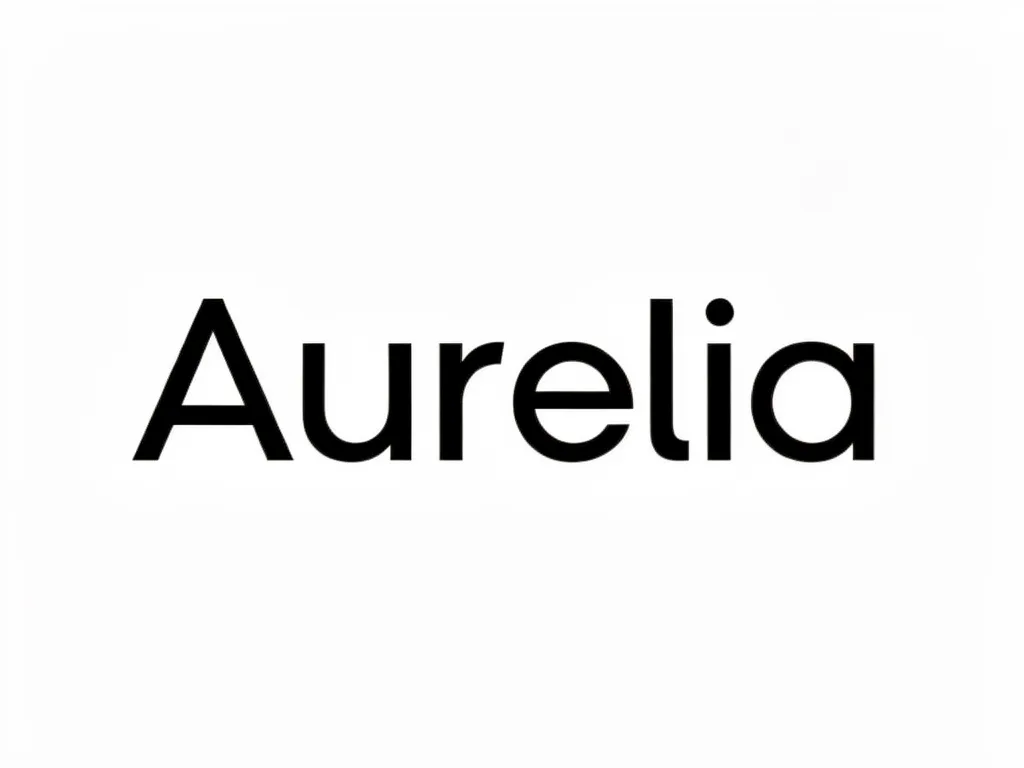 FLUX.2 [  FLUX.2 \[pro\] ](https://img.ly/ai-benchmarks/ai-benchmarks/prompts/t04-wordmark/)[ 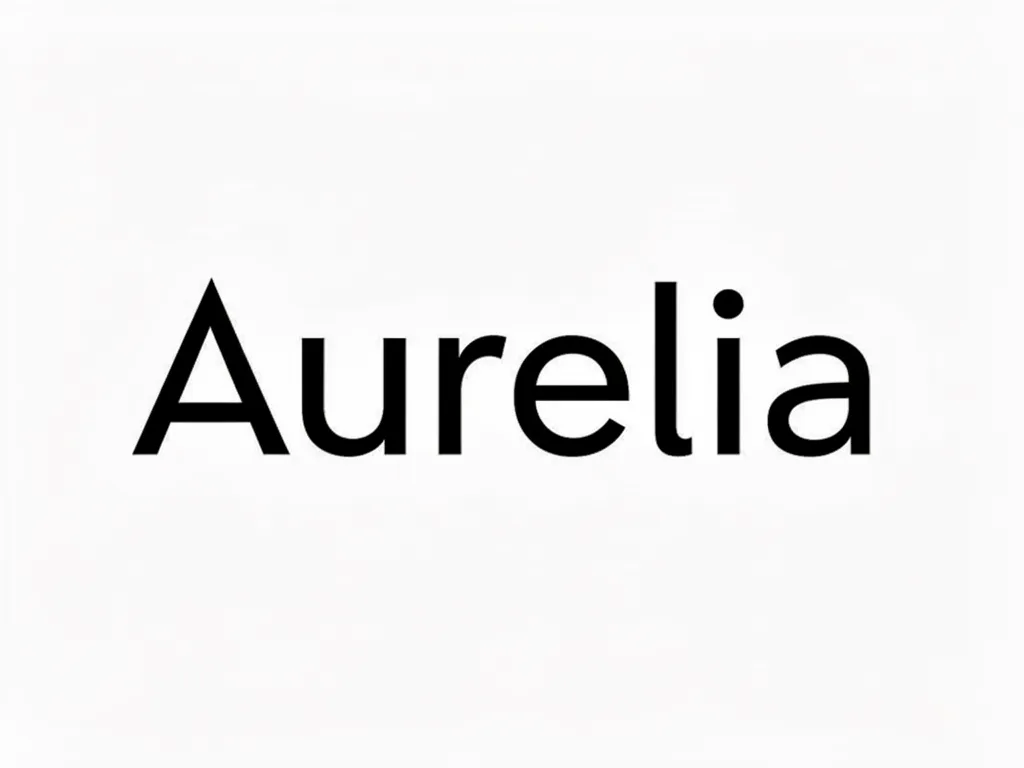 FLUX.2 \[dev\] Turbo ](https://img.ly/ai-benchmarks/ai-benchmarks/prompts/t04-wordmark/)
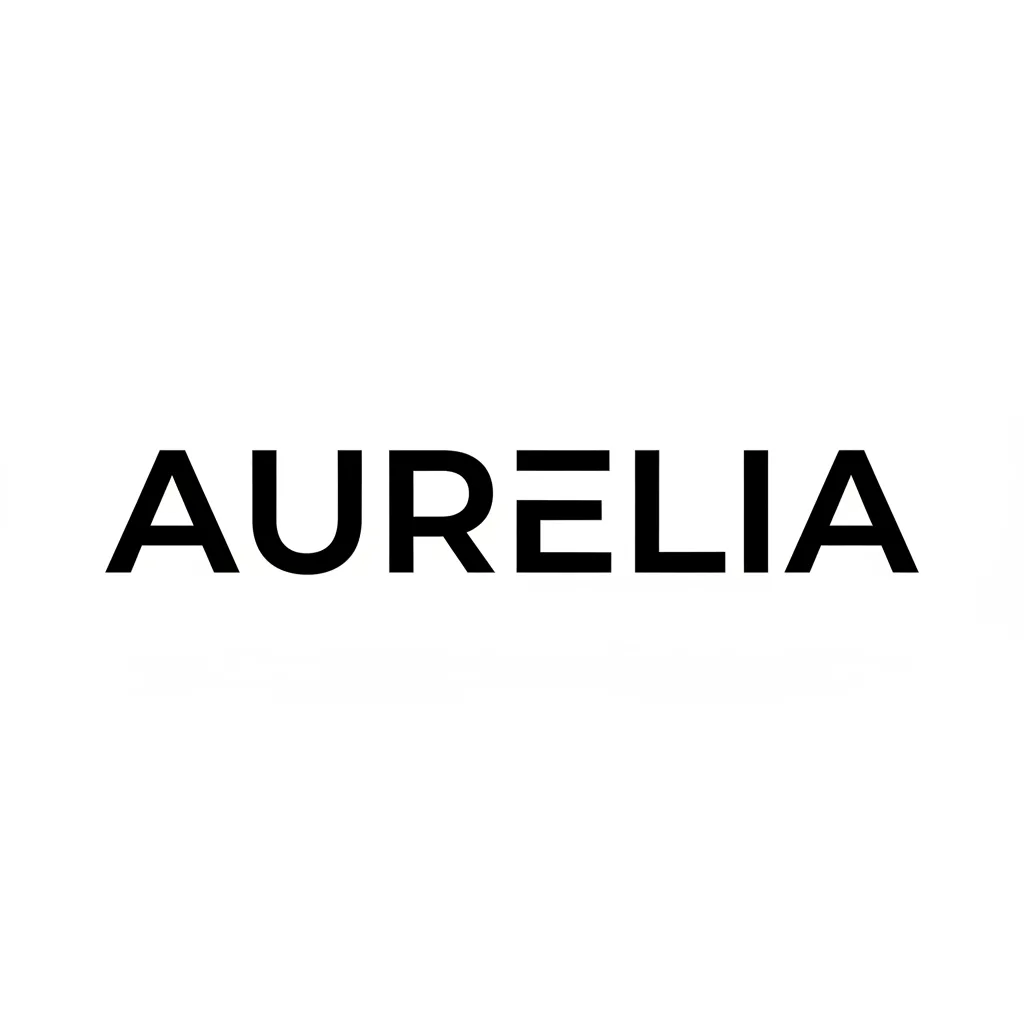 Gemini 2.5 Flash Image
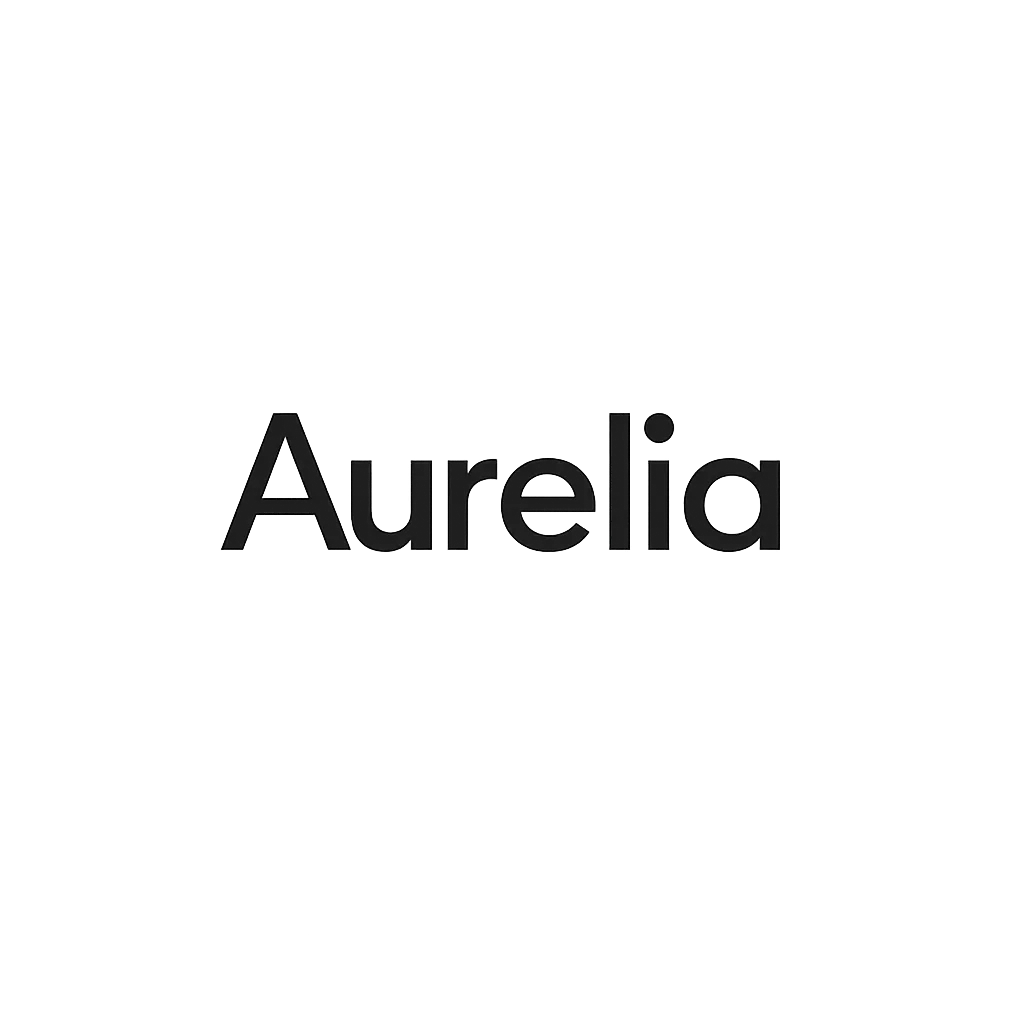 GPT Image 1.5
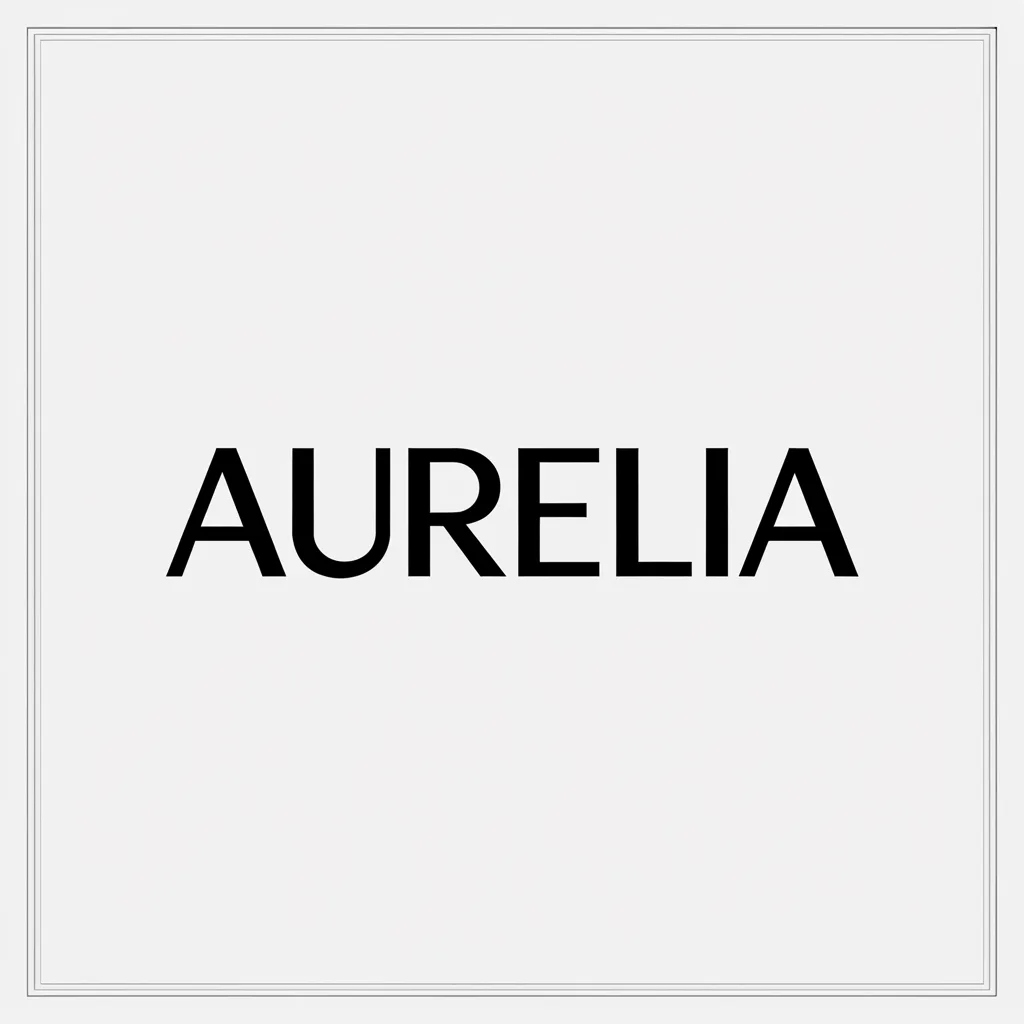 Ideogram 3.0
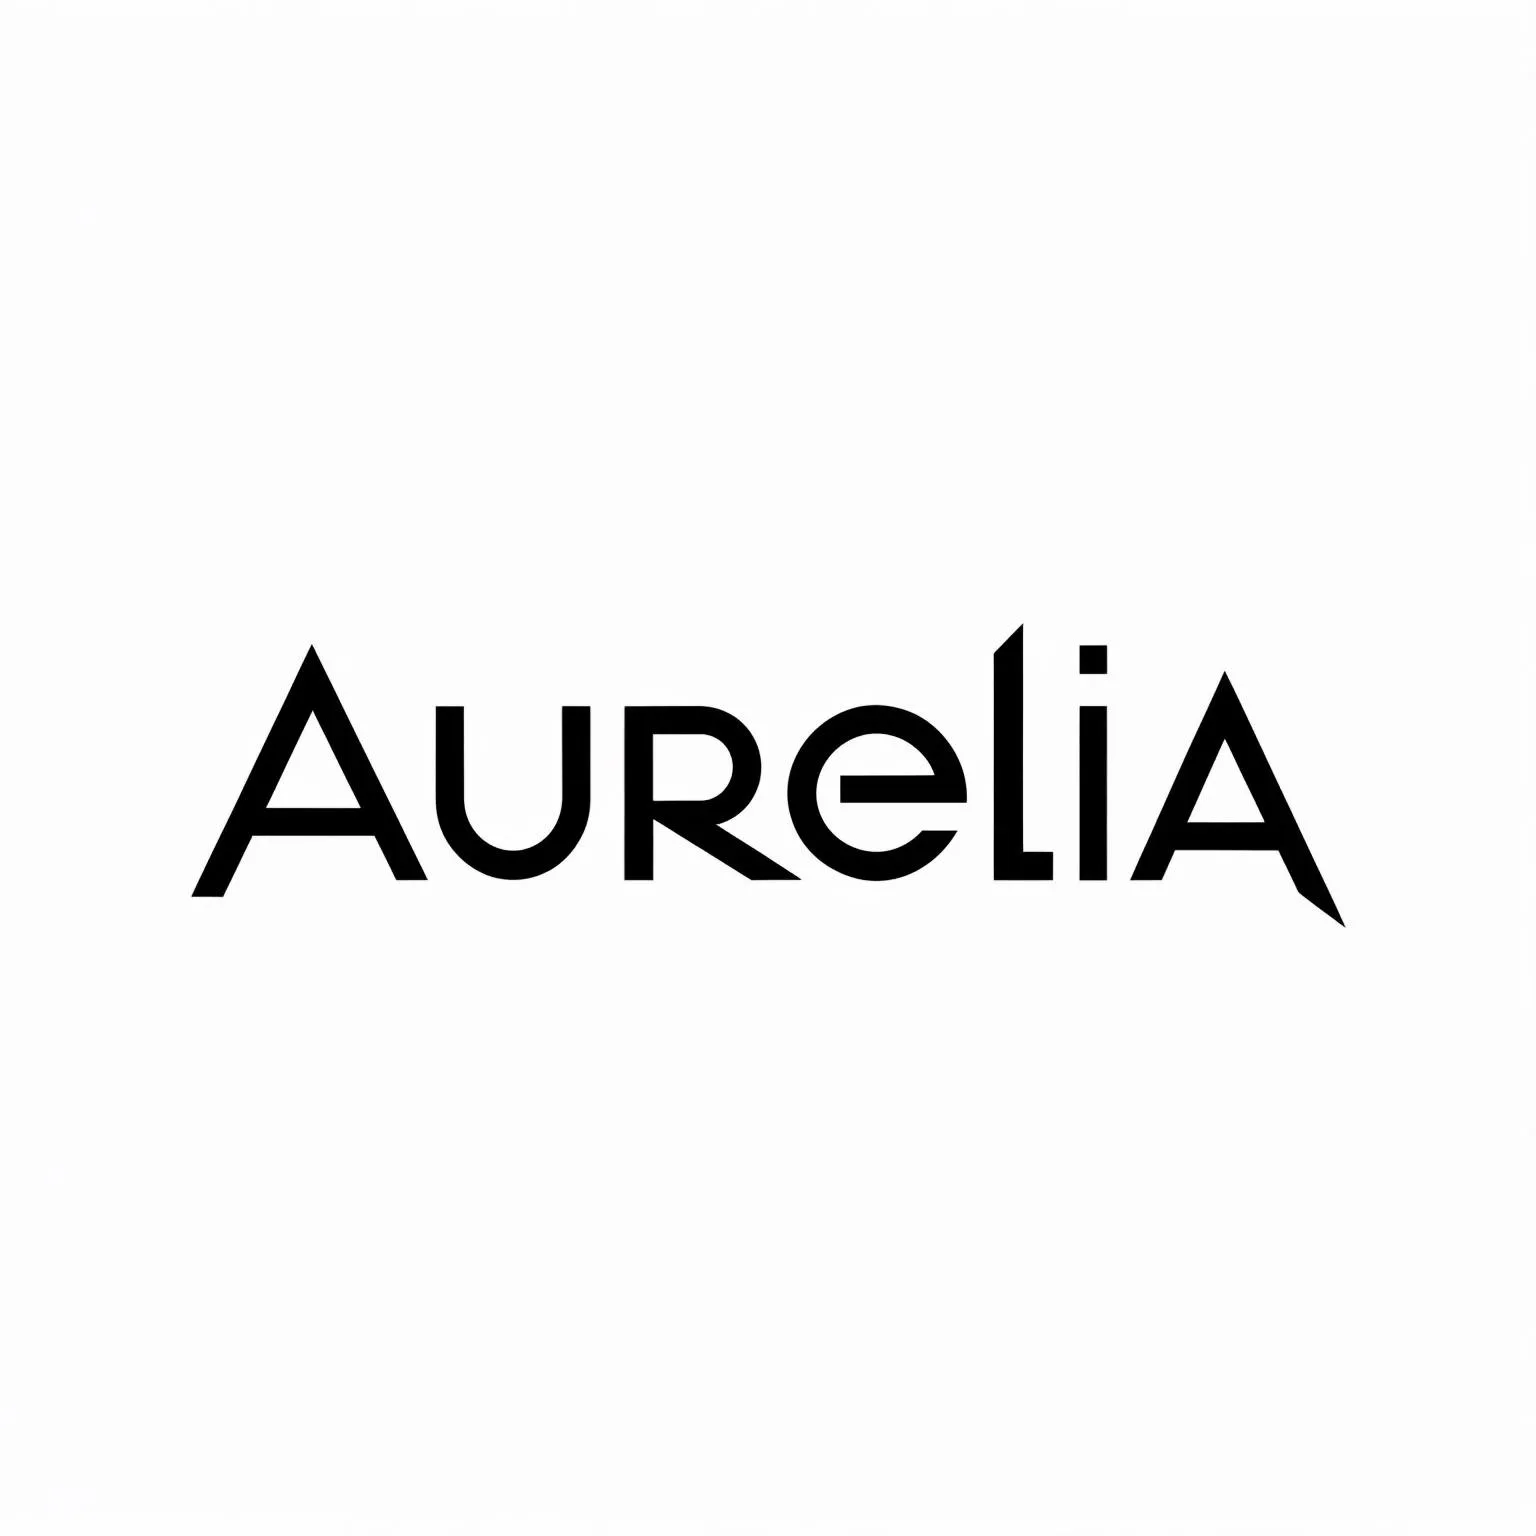 Luma Photon
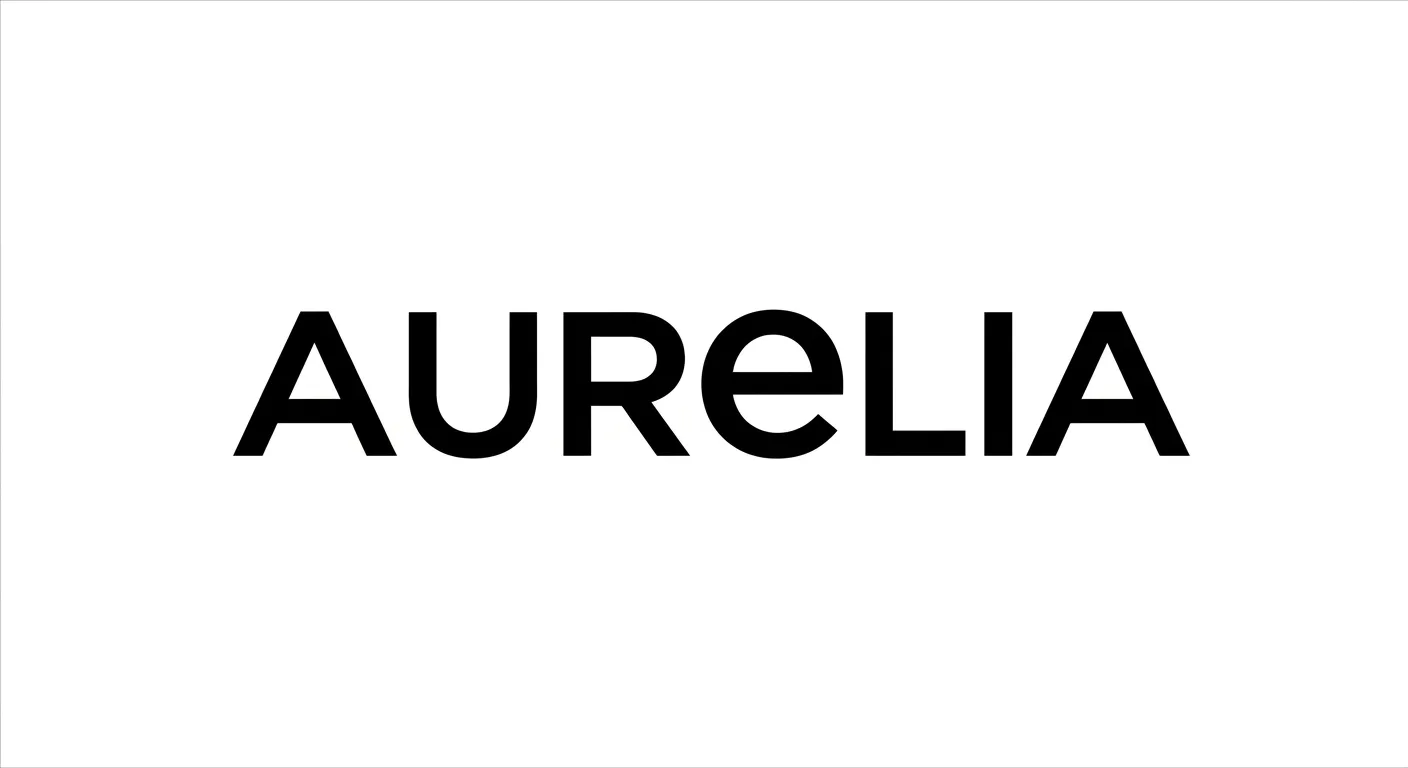 Nano Banana 2
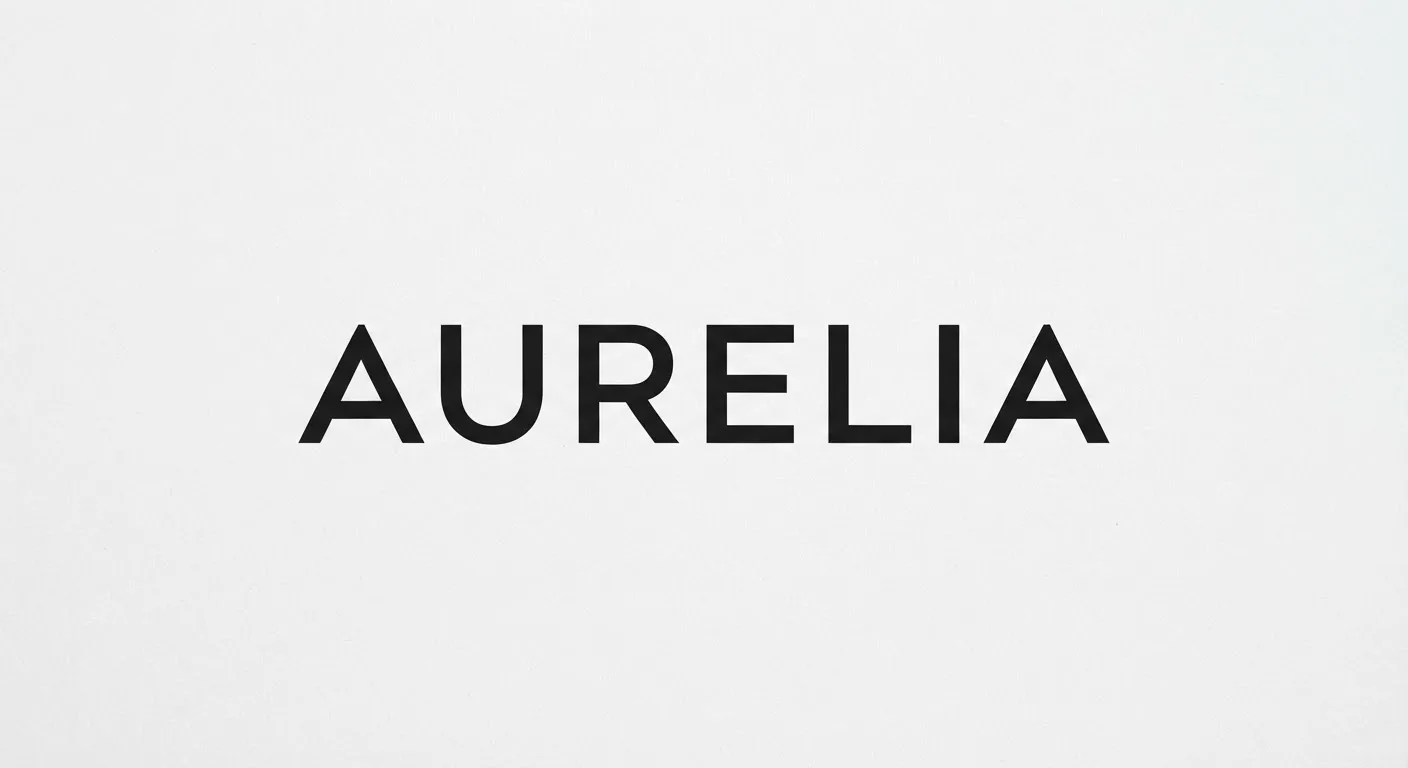 Nano Banana 2 Lite
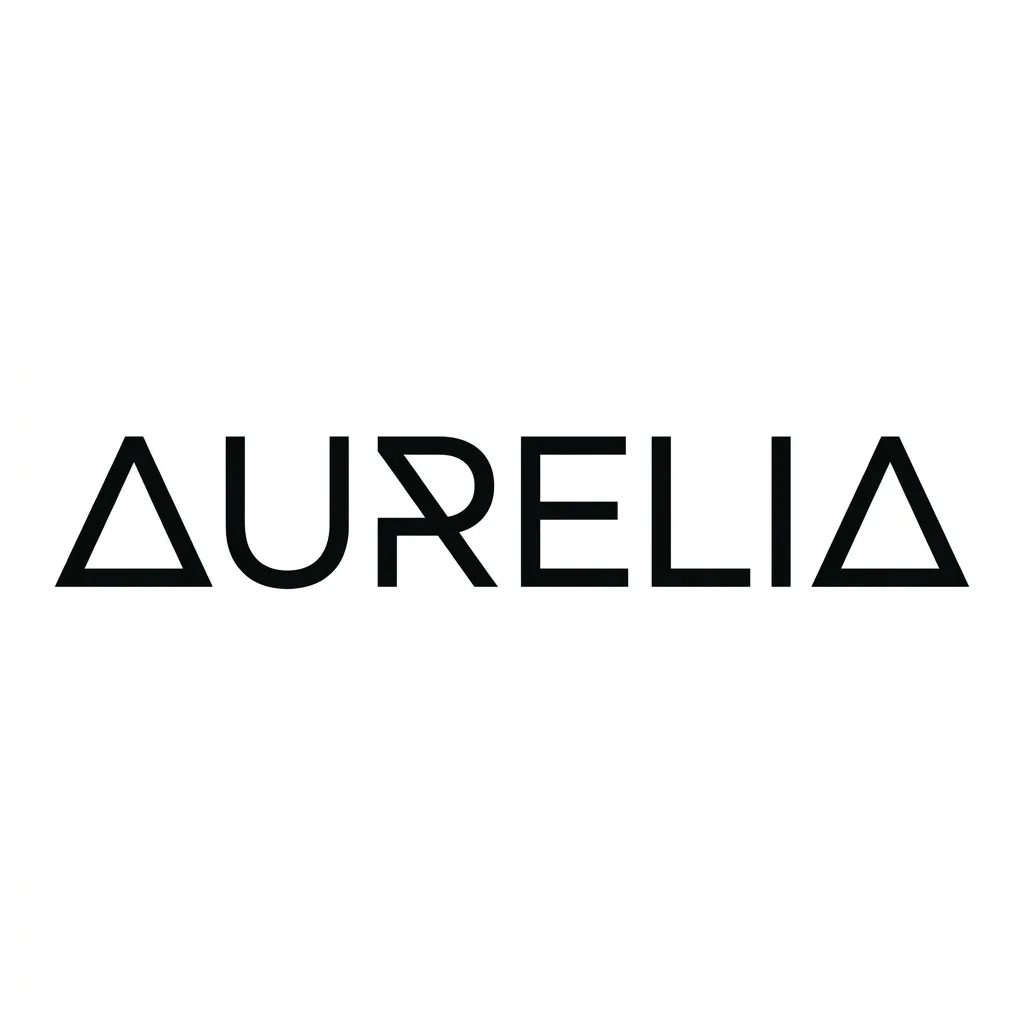 Nano Banana Pro
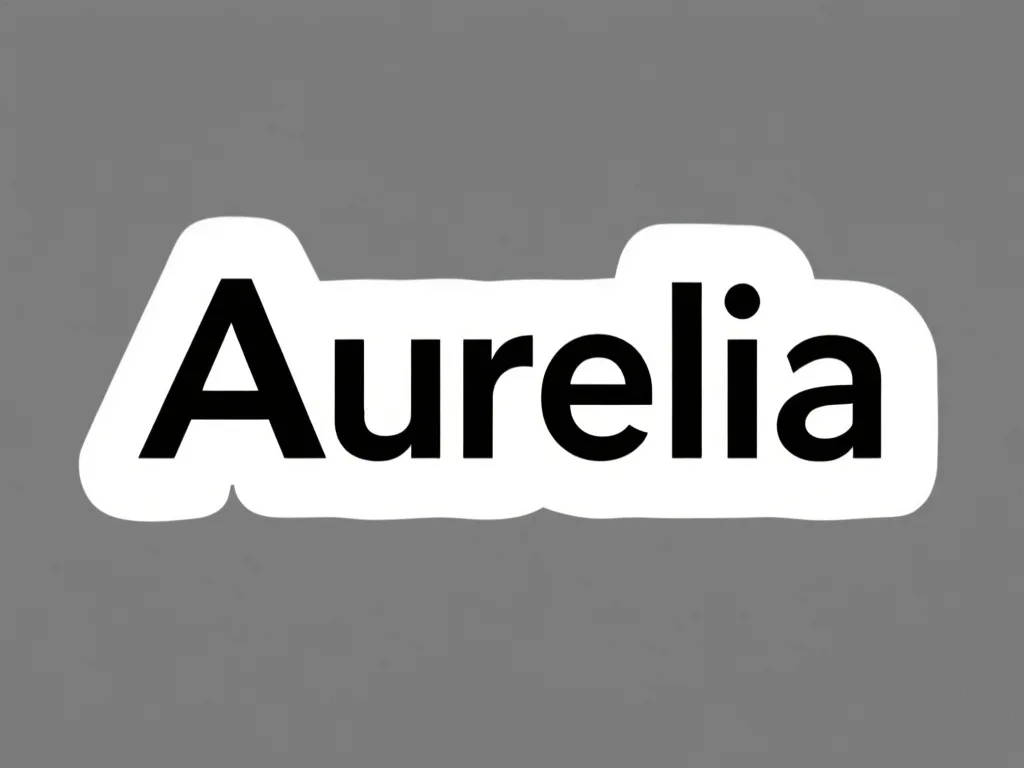 Qwen-Image
 Recraft V3
 Seedream 4.5
 Seedream 5.0 Lite
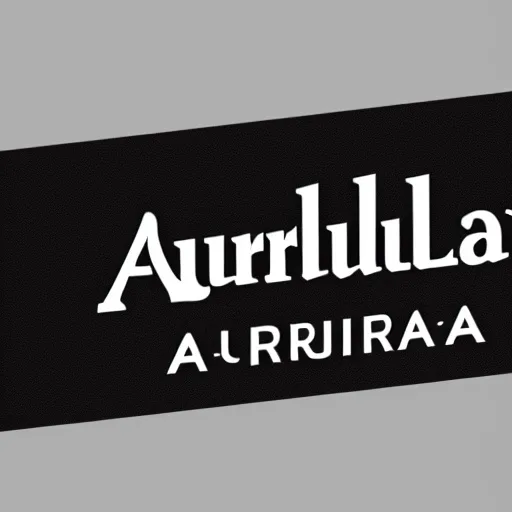 Stable Diffusion 1.5
Close
One benchmark of 37: the flagships spell "Aurelia"; the 2022 baseline shows how far text rendering has come. See the full comparison and scores
Rankings
Which model should you build on?
Every model side by side: cost per image, latency, native resolution and per-criterion scores, with a full result gallery and per-category breakdown on every model profile.
Prompts
The canonical prompt suite
Typography, vector style, brand color, transparency, composition and spatial adherence: each prompt stresses a criterion that decides whether an asset ships, and each has a result grid across all models.
Compare
Head to head
Pick two or three models and see every canonical prompt side by side, with per-criterion winners marked.
Full 15-model run (suite pilot-0, last run Jul 6, 2026). Quality criteria are scored by an automated Claude vision tier; scores stay provisional until the expert-reviewed suite freeze.
What the data says
The findings that matter if you are integrating AI imagery into a product: where models fall short of production requirements, measured.
Transparency
13 of 15 models fail at transparency
We asked every model for transparent PNGs and measured the alpha channel of what came back. Almost none of it survives contact with a real sticker, merch or cut-out pipeline.
Brand color
No model hits your exact hex
Measured with CIEDE2000 against required brand colors, the best model scores 3.67 of 5 and most of the field lands below 3. Close-enough color is not the color in your brand book.
Text
Rendered text: close is not shippable
Even the best model occasionally breaks a headline, and the model famous for text lands mid-field. One wrong character means regenerating the whole image, unless the words are editable layers.
Consistency
No model holds a character across scenes
The same described character drifts between scenes on every model we tested. Series work needs identity as a reusable asset, not a regeneration lottery.
Get the 2026 Benchmark Report
15 models, 37 prompts, 1,662 measured images. Every finding and ranking from this benchmark, with the methodology behind the numbers, as a PDF in your inbox.
Send me the report
I agree to receive other communications from IMG.LY.
By submitting, you agree to let IMG.LY store and process your personal data. See our Privacy Policy. Unsubscribe anytime.
Something went wrong sending your request. Please try again, or email us at contact@img.ly.
Check your inbox.
Your report is on the way.
How we score, and why you can trust it
Every criterion is scored by the cheapest tier that is reliable for it. Numbers a machine can measure are measured; judgments that need eyes get them. Methodology is published in full, models get zero special treatment, and scores are never silently restated.
Auto
Measured
Resolution, latency, cost, alpha-channel quality and brand-color drift (CIEDE2000 against the requested hex values): computed from every generation, reproducible from the recorded originals.
VLM
Judged
Prompt adherence checklists and composition checks run through a vision-language judge, calibrated against the expert panel. Pending in the pilot dataset and always labeled as such.
Expert
Rated
Design-readiness and aesthetics come from a blind expert panel: model names hidden, three raters per cell, agreement reported. Arrives with the frozen suite.
AI Editor
No model on this page scores 5/5. Your product still has to.
The IMG.LY AI Editor closes the gap: your users refine whatever a model generates into production quality, with background removal, brand kits and editable text on a real canvas.
Explore the AI Editor Open Demo