


Safe Lock-free Primitives with iceoryx2's ByteAtomic
Safe Lock-free Primitives with iceoryx2's ByteAtomic
Marika Lehmann - 28/07/2026
Data Races and Sequence Lock
In multithreaded programming, a common scenario involves multiple threads reading from and modifying shared data concurrently. If this read and write operations are not atomic, a data race occurs. In languages like Rust and C++, which have almost the same memory model, this results in undefined behavior. To prevent this, locks can be used to protect the data from being modified while it is being read. However, traditional locking mechanisms carry the risk of deadlocks which is unacceptable, especially in safety-critical and high-reliability systems.
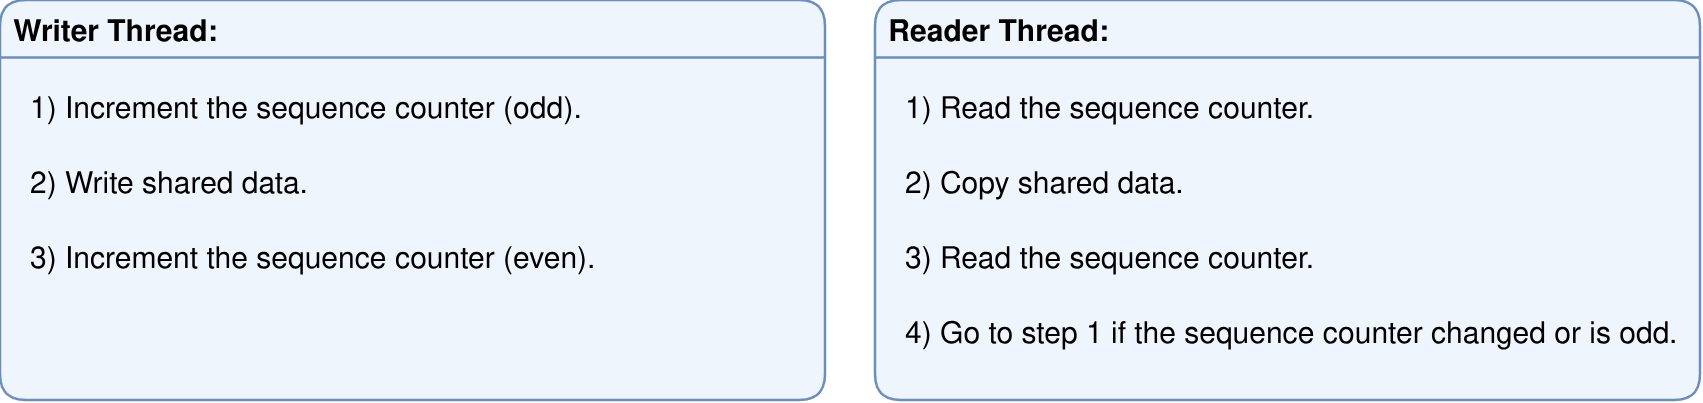
A common approach to mitigating the described data race without using blocking locks is to utilize a sequence lock. The sequence lock contains the shared data and an atomic counter that has an odd value whenever the data is being updated:
rust
struct SequenceLock<T: Copy + Send> {
    counter: AtomicUsize,
    data: UnsafeCell<T>, // Provides the necessary interior mutability for the writer.
}
Using a sequence lock, a writer thread increments the sequence counter to an odd value, updates the data, and then increments the counter to an even value. A reader thread reads the sequence counter both before and after copying the shared data. If the counter has changed or is currently odd, it indicates that the data was concurrently modified. The reader then discards the corrupted copy and retries.

The Problem: Even if the reader detects that the data was modified and discards the copy before use, the act of copying the non-atomic data itself still triggers undefined behavior. While a sequence lock can detect that a data race occurred, it does not prevent it. Consequently, it is currently not possible to implement a correct sequence lock in Rust or C++ without decomposing the data into smaller, individually atomic parts. This is a known problem, and while there are ongoing proposals to introduce an "atomic memcpy"12 to the Rust and C++ standard libraries, we cannot rely on that feature yet.
Targeting safety-critical and high-reliability systems, iceoryx2 provides a library of lock-free constructs that are based on mechanisms similar to a sequence lock. To make these constructs safe and correct, we need a way to perform memory copies that are atomic at the byte level, ensuring no data races occur. This is why we implemented the byte-wise atomic wrapper ByteAtomic, which we will describe in the following sections. While its concept is simple, achieving true safety required overcoming a subtle but critical issue with uninitialized memory.
Solution: A Byte-wise Atomic Wrapper
To prevent the aforementioned data race and thus the undefined behavior, the `ByteAtomic` in iceoryx2 provides byte-wise atomic read and write operations on its inner type. This wrapper only guarantees that each byte is updated/read atomically; it does not provide higher-level thread-safety guarantees. Users must still enforce proper synchronization (such as a sequence lock) to prevent torn reads or writes. The wrapper only ensures that the memory copy is not undefined behavior, but it does not guarantee data integrity on its own.
Implementation
The wrapper's implementation has undergone some refinement as we addressed the complexities of memory safety. The initial version of our `ByteAtomic` wrapper looked like this:
rust
/// A compile-time fixed-size, shared-memory compatible ByteAtomic.
#[repr(C)]
pub struct FixedSizeByteAtomic<T: Copy, const SIZE: usize> {
    data: [AtomicU8; SIZE],
    _inner_type: PhantomData<T>,
}impl<T: Copy, const SIZE: usize> FixedSizeByteAtomic<T, SIZE> {
    pub fn new(value: T) -> Self {
        // create a new ByteAtomic containing the passed value
    }
    pub fn read(&self) -> MaybeUninit<T> {
        // copy the stored value byte-wise atomically into a MaybeUninit<T>
    }
    pub fn write(&self, value: T) {
        // store the passed value byte-wise atomically
    }
}
It is named `FixedSizeByteAtomic` because the array size must be provided at compile time, as Rust does not yet allow using `core::mem::size_of::<T>()`directly in a struct definition. Once this becomes possible, we plan to remove the `SIZE` generic parameter, remove the runtime fixed-size version `RelocatableByteAtomic`, and rename the struct to `ByteAtomic`.
#### Padding Bytes
To understand why the implementation had to evolve, let's take a look at the initial, naive implementation of `new()`:
rust
pub fn new(value: T) -> Self {
    let bytes: [u8; SIZE] = unsafe { transmute_copy(&value) };
    Self {
        data: bytes.map(AtomicU8::new),
        _inner_type: PhantomData,
    }
}
This version of `new()` accepts a copyable value, performs a `transmute_copy`into a byte array, and stores every byte as an `AtomicU8` into the ByteAtomic's `data` field. This works fine - unless `T` contains uninitialized memory, such as a `MaybeUninit` or padding bytes:
rust
#[repr(C)]
struct Foo {
    bar: u8,
    // 7 padding bytes
    baz: u64,
}
transmute\_copy assumes that the value being copied is a valid representation of the destination type, in our case a valid `u8`. This assumption fails for padding bytes because they are uninitialized memory; reading them leads to undefined behavior3. Therefore, we have to ensure that we only copy the fields (i.e., the initialized bytes) of the passed value. This led to the current, correct implementation of `new()`:
rust
#[repr(C)]
pub struct FixedSizeByteAtomic<T: AtomicCopy, const SIZE: usize> {
    data: [AtomicU8; SIZE],
    _inner_type: PhantomData<T>,
}impl<T: AtomicCopy, const SIZE: usize> FixedSizeByteAtomic<T, SIZE> {
  pub fn new(value: T) -> Self {
      static_assert_size_of!(T, SIZE); // check whether SIZE and value size match
      let value_ptr = (&raw const value).cast::<u8>();
      // The passed value may contain padding bytes. Reading these padding bytes
      // would lead to undefined behavior. Therefore, we first set all bytes to
      // zero and then copy only the fields of the passed value.
      let mut bytes = [0u8; SIZE];
      // for_each_field applies a callback to each offset-size pair of every
      // field in T
      value.for_each_field(0, &mut |offset, size| {
          for (i, byte) in bytes.iter_mut().enumerate().skip(offset).take(size) {
              *byte = unsafe { *value_ptr.add(i) };
          }
      });
      Self {
          data: bytes.map(AtomicU8::new),
          _inner_type: PhantomData,
      }
  }  pub fn read(&self) -> MaybeTorn<T> {
      // ...
  }
  pub fn write(&self, value: T) {
      // ...
  }
}
We now require the inner type `T` to implement the AtomicCopy trait from iceoryx2 for types that can be atomically copied. It provides `for_each_field()`, a field-wise accessor for byte-wise copying. This method applies the provided callback to each offset-size pair of every field in `T`. With this, `new()` copies only the initialized bytes of `value` into the `data`field, effectively skipping potential padding bytes. Of course, implementations of the `AtomicCopy` trait must ensure that the offset and size of each field are calculated correctly; otherwise, undefined behavior may still occur.
Note that the return type of `read()` has also evolved. In its initial version, `read()` returned a `MaybeUnint<T>` to alert the user that, while the `ByteAtomic` prevents undefined behavior during memory copies, torn reads can still occur. To emphasize this risk, we changed the return type to MaybeTorn<T>. This type wraps a `MaybeUninit<T>` and serves as a constant reminder that the data integrity is not yet guaranteed. Only after verifying that no concurrent writes occurred can the user safely call `assume_consistent()` to extract the read value. Otherwise, the returned `T`may be logically invalid and its use could lead to undefined behavior.
Usage
The manual implementation of `AtomicCopy` for `Foo` would look like this:
rust
use iceoryx2_bb_elementary_traits::atomic_copy::AtomicCopy;#[repr(C)]
#[derive(Clone, Copy)]
struct Foo {
bar: u8,
baz: u64,
}
// manually implement AtomicCopy for Foo
unsafe impl AtomicCopy for Foo {
fn for_each_field<F>(&self, base_offset: usize, callback: &mut F)
where
F: FnMut(usize, usize),
{
callback(
base_offset + core::mem::offset_of!(Self, bar),
core::mem::size_of::<u8>(),
);
callback(
base_offset + core::mem::offset_of!(Self, baz),
core::mem::size_of::<u64>(),
);
}
}
For convenience, we have implemented `AtomicCopy` for all scalar types and provided a derive macro. This macro automatically implements the trait for all structs whose fields also implement `AtomicCopy`. This is how it looks like in use for `Foo`:
rust
use iceoryx2_bb_container::byte_atomic::FixedSizeByteAtomic;
use iceoryx2_bb_derive_macros::AtomicCopy;
use iceoryx2_bb_elementary_traits::atomic_copy::AtomicCopy;#[repr(C)]
#[derive(AtomicCopy, Clone, Copy)] // derive AtomicCopy
struct Foo {
bar: u8,
baz: u64,
}
// ...
const SIZE: usize = core::mem::size_of::<Foo>();
let wrapper = FixedSizeByteAtomic::<Foo, SIZE>::new(Foo { bar: 0, baz: 0 });
let new_value = Foo { bar: 4, baz: 6 };
wrapper.write(new_value);
// read() returns a MaybeTorn<Foo> to alert the user of potential torn reads
let read_value = wrapper.read();
// ... check that no concurrent write has happened
let read_value = unsafe { read_value.assume_consistent() };
assert_eq!(read_value.bar, new_value.bar);
assert_eq!(read_value.baz, new_value.baz);
Conclusion
Writing correct lock-free code is difficult. Even the "simple" and well-known sequence lock, which often forms the basis for more complex lock-free constructs, entails data races and undefined behavior. While a future standard library "atomic memcpy" would be the ideal and efficient solution, the byte-wise atomic wrapper provided by iceoryx2 enables developers to implement a correct and safe sequence lock and other lock-free primitives today. We are working to integrate this wrapper into our existing lock-free constructs to finalize their transition to a fully safe implementation.
Discuss on Social Media
Footnotes
Footnotes
1. <https://github.com/rust-lang/rfcs/pull/3301> ↩ 2. <https://www.open-std.org/jtc1/sc22/wg21/docs/papers/2022/p1478r7.html> ↩ 3. Using `copy_nonoverlapping` would shift the problem to the `AtomicU8` creation. ↩