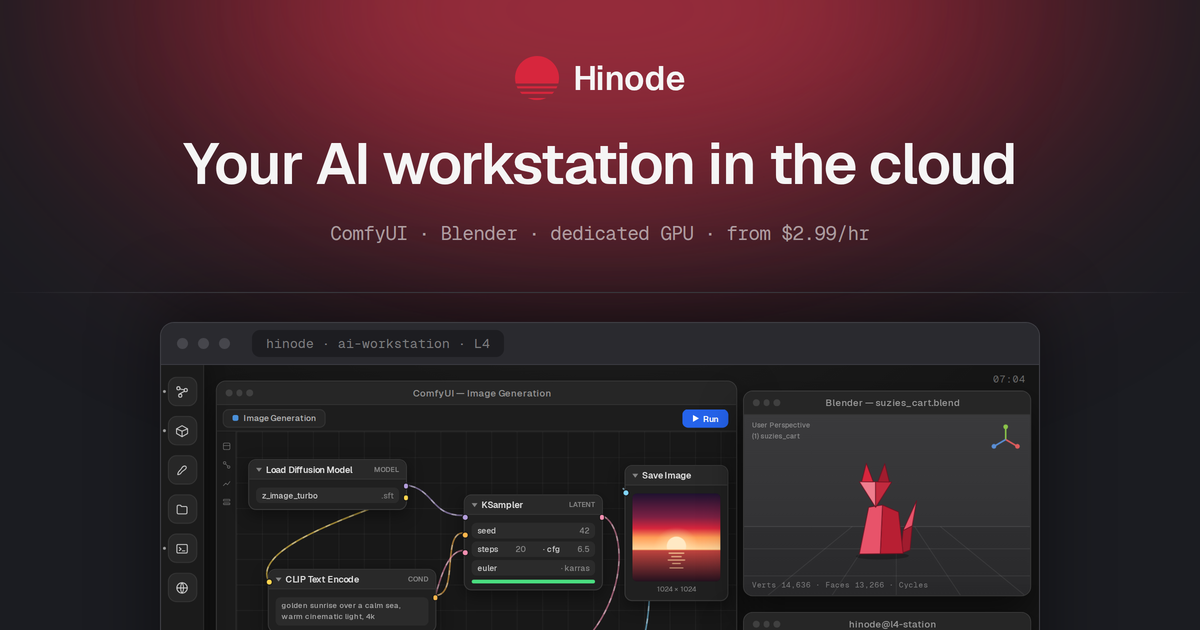
Your AI workstation in the cloud
Your AI workstation in the cloud
A Linux desktop with a dedicated GPU — in your browser or the native Mac and Windows apps. Your files and environment stay put. Boost to a bigger GPU in one click.
From $3.99/hr · Auto-pause when idle · Native Mac & Windows apps
hinode · ai-workstation · L4
07:04
ComfyUI — Image Generation
Image Generation
Run
Load Diffusion ModelMODEL
z\_image\_turbo.sft
CLIP Text EncodeCOND
golden sunrise over a calm sea, warm cinematic light, 4k
Empty Latent Image
1024 × 1024 batch 1
KSamplerLATENT
seed 42
steps 20 · cfg 6.5
euler · karras
VAE DecodeIMAGE
samples → image
Save Image
1024 × 1024
Blender — suzanne.blend
User Perspective (1) Suzanne
Verts 518 · Faces 999 · Cycles
hinode@l4-station
$ comfy run sunrise\_workflow.json \[comfy\] z\_image\_turbo loaded · L4 · 24 GB \[comfy\] sampling 20 steps · 1.9 it/s \[comfy\] saved → output/sunrise\_0042.png
The problem
GPU rental wasn't built for daily work
Rented pods are disposable. Your work isn't. The same evening, two ways.
Raw GPU pod
pod-7f3a · H100
$ rsync -r checkpoints/ loras/ pod-7f3a: sent 3.2 GB · done $ python generate.py --batch 24 done · 24 images · 214 s Terminating instance and cleaning up...
checkpoints/loras/outputs/
Pods tear down when you stop. Your models, nodes and files go with them. The next day, you start over from scratch.
Hinode workstation
✓ resumed
Files — \~/projects
checkpoints/ loras/ outputs/
ComfyUI — Image Generation
paused · $0.00/hr
Hinode auto-pauses instead. Close the lid — files, apps and processes wait intact. Open it and continue where you left off.
Boost
When the model doesn't fit
The same job on the same 24 GB card — with and without a way out.
Raw GPU pod
pod-9c21 · L4
$ comfy run flux\_portrait.json loading flux-dev · 23.8 GB CUDA out of memory — job killed
VRAML4 · 24 GB
Fixed VRAM is a wall. The model needs more than the card has, and the job dies. Creating a new pod means starting over from scratch.
Hinode workstation
hinode · ai-workstation
$ comfy run flux\_portrait.json loading flux-dev · 23.8 GB ✓ loaded · 23.8 / 96 GB VRAM
VRAML4 · 24 GBRTX Pro 6000 · 96 GB
⚡ Boosted
Boost raises the ceiling. Boost to the Power tier when you need it, and pay only for the time you use it.
Features
One workstation, always ready
Everything an AI creator needs in a single environment that follows you across devices.
Persistent state + auto-pause
Your workstation hibernates after 15 minutes idle and wakes with everything intact. You don't pay for idle time.
Boost
One click swaps in a bigger GPU for a single training run, billed by the hour. It reverts automatically when you're done.
Hybrid billing
One product, two ways to pay. Monthly subscription if you work daily, hourly pay-as-you-go if you don't. Switch any time.
H.265 60fps streaming
Every tier streams 1440p60 with modern compression. Upgrades buy GPU power, not resolution.
AI-ready image
The AI Workstation image ships with CUDA, PyTorch, JupyterLab, VS Code, and the common ML libraries. Open it and start.
Browser or native app
Run it in your browser, or get the native Mac and Windows apps — the same live session either way.
No lock-in
Your tools, your data
A full Linux desktop with the tools you already use, preinstalled. Import your data from any source and export it to any destination. No vendor lock-in, no closed ecosystems.
ComfyUIBlenderPyTorchHugging FaceOllamaCUDALangChainvLLMJupyter
Pricing
Pay monthly, or by the hour
Same workstation either way. Switch anytime.
SubscriptionPay-as-you-go
Standard
Dedicated L4
$3.99/hr
- 24 GB VRAM
- 32 GB RAM
- Billed by the active minute
- Persistent state + auto-pause
- 48 GB VRAM
- 64 GB RAM
- Billed by the active minute
- Persistent state + auto-pause
- 96 GB VRAM
- 128 GB RAM
- Billed by the active minute
- Persistent state + auto-pause
- Pay-as-you-goSubscription
- Standard$347$299
- Pro$434$399
- Power$608$599
Most popular
Pro
Dedicated L40S
$4.99/hr
Power
Dedicated RTX Pro 6000
$6.99/hr
What a month actually costs
Pay-as-you-go bills active time by the minute — auto-pause stops the meter when you step away.
Active work20 h/week
≈ 87 active hours a month
Subscriptions include 100 active hours per workstation. Extra active time uses the lower subscriber rate shown above.
Storage billed separately by allocated GB-minute · Boost billed per hour at the delta rate
How we compare
The same GPU. A full desktop.
Pro, our most popular tier, is a dedicated L40S — the same card RunPod rents — with a full desktop that stays put instead of a terminal you rebuild.
| | RunPod | Vast | Lambda | HF Pro | Hinode Pro | | ---------- | ------------- | ----------------- | ----------------- | ---------------- | ----------------------- | | GPU | L40S · 48 GB | RTX A6000 · 48 GB | A100 · 40 GB | ZeroGPU · shared | L40S · 48 GB | | GPU access | Dedicated | Dedicated | Dedicated | Quota + queue | Dedicated | | Interface | SSH / Jupyter | SSH / Jupyter | SSH / Jupyter | Spaces (web) | Native desktop | | Session | Lost on stop | Tied to one host | Lost on terminate | Ephemeral | Persistent + auto-pause | | Devices | Browser | Browser | Browser | Browser | Browser + native apps |
How it works
From signup to GPU in minutes
1. 01
Sign up
Create an account in seconds. No time-limited trial. 2. 02Launch your workstation
It boots AI-ready: CUDA, PyTorch, and the everyday tools preinstalled. 3. 03Connect anywhere
Open the desktop in your browser, or in the native Mac and Windows apps. 4. 04Boost when you need it
Jump to a bigger GPU for a heavy run, then drop back automatically.FAQ
Questions, answered
What is Hinode?
A cloud Linux desktop with a dedicated GPU, in your browser or the native Mac and Windows apps. Your environment persists between sessions, so you never set it up twice.
How does billing work?
Pick a monthly subscription or hourly pay-as-you-go at signup, and switch any time. Auto-pause means you're not charged while the workstation is idle.
What is Boost?
A one-click upgrade to stronger hardware for a single task. Run a job on a bigger GPU, then drop back to your tier automatically. You pay the hourly delta.
Do I pay while idle?
No. Your workstation hibernates after 15 minutes of inactivity and wakes with everything intact.
Which devices can I use?
Any supported browser, plus native Mac and Windows apps. The same live session follows you across all of them.
Which browsers work?
Chrome, Edge, and other recent Chromium browsers. The client needs WebTransport and WebCodecs, which Safari and Firefox don't fully support yet.
What about my data?
Active workstations run on encrypted volumes; paused ones are snapshotted to object storage. Export your data anytime.
Start building on Hinode
Sign up and launch your first GPU desktop.