Can LLMs find the same bugs twice?
Current releaseSnyk VulnBench JS 1.0
A Snyk benchmark initiative
Can LLMs find the same bugs twice?
A repeatability and Snyk-reference agreement study
We ran the same agentic security review five times against inspectable JavaScript projects to measure what recurs, what varies, and how model findings align with a deterministic Snyk Code reference set.
Explore the resultsRead the paper
300scans
10projects
6configurations
5repetitions
Headline evidence · 5 identical reviews
Same review. Different results.
JS 1.0
300 scans · 10projects · 6 configurations
Reference-matched findings seen in all five runs84.8%
Unmatched findings seen in all five runs13.7%
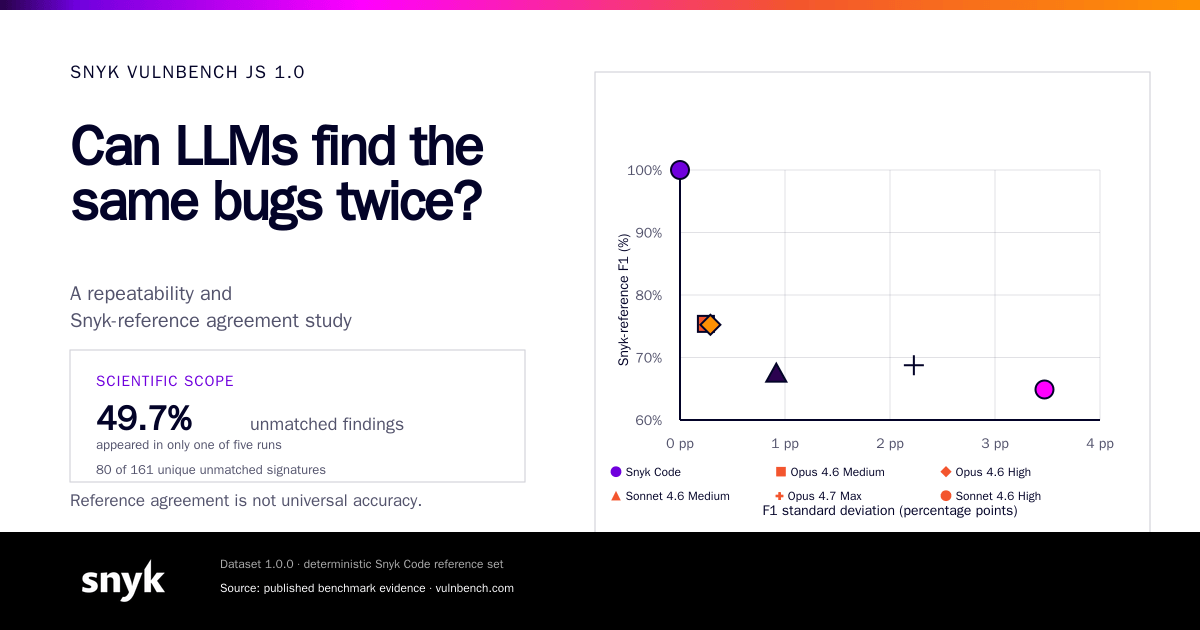
Unmatched findings seen in only one run49.7%
- 134 of 158Reference-matched findings seen in all five runsInspect
- 22 of 161Unmatched findings seen in all five runsInspect
- 80 of 161Unmatched findings seen in only one runInspect
134 of 158 · Reference-matched findings seen in all five runs
View exact recurrence values
| Finding group | Count | Share | | ------------------------------------------------ | ---------- | ----- | | Reference-matched findings seen in all five runs | 134 of 158 | 84.8% | | Unmatched findings seen in all five runs | 22 of 161 | 13.7% | | Unmatched findings seen in only one run | 80 of 161 | 49.7% |
Dataset 1.0.0Snyk VulnBench JS 1.0Unique signatures · recurrence across 5 identical runsSource: published JS 1.0 paper
Latest evidence · JS 1.0
Same code. Same prompt. Different findings.
Across five identical runs, 84.8% of reference-matched findings recurred every time. Nearly half of unmatched reports appeared only once—evidence to inspect, not dismiss.
5.67×Opus 4.7 Max cost more and scored lower than Opus 4.6 Medium: 68.8% vs 75.4% Snyk-reference F1.Inspect evidence →49.7%Nearly half of unmatched reports surfaced in just one run.Inspect evidence →13.7%Only 13.7% of unmatched reports recurred in all five runs.Inspect evidence →
What the results mean in practice
An AI review is a measurement—not a verdict.
Repeat the same task and the story sharpens: many reference-matched findings hold steady; AI review and deterministic SAST reveal different blind spots; and more spend does not reliably improve Snyk-reference agreement.
1. 01
Repeatability makes confidence visible
134 of 158 reference-matched findings appeared in every one of five identical reviews. Repetition shows which reported patterns persist instead of relying on a single run.Interpret with care: A reference match measures agreement with Snyk Code, not independent ground-truth accuracy. Open the evidence 2. 02
AI review and SAST expose different blind spots
Models surfaced high-signal exploit shapes, while deterministic Snyk Code consistently enumerated repeated data-flow sinks. Their differing results are useful evidence—not a reason to declare one a universal winner.Interpret with care: Unmatched findings require case-level inspection before they can be classified. Open the evidence 3. 03
Paying more did not reliably improve the result
In this benchmark, higher session cost did not consistently yield higher Snyk-reference F1. Spend alone is a poor shortcut for choosing a configuration.Interpret with care: Cost estimates reflect the tested small fixtures and publication assumptions. Open the evidence
Benchmark anatomy
How VulnBench measures behavior
Repeat the conditions, preserve the evidence, and separate observed agreement from claims the protocol cannot support.
1. 1
Select inspectable projects
Ten small JavaScript and Express fixtures make every run and reference finding reviewable. 2. 2Repeat the same task
Each configuration sees the same code, prompt, harness, and task five times. 3. 3Normalize findings
Reported issues become documented signatures suitable for recurrence analysis. 4. 4Match the reference set
The scorer compares vulnerability type against deterministic Snyk Code findings. 5. 5Measure behavior
Agreement, recurrence, variance, coverage, cost, tokens, and duration stay distinct. 6. 6Inspect divergence
Unmatched reports remain evidence to investigate—not automatic false positives.Research principles
Evidence before ranking
VulnBench is a versioned research initiative, not a universal leaderboard. Every release defines what it measured and what it did not prove.
Transparent reference setsDefinitions and limitations stay visible.
Repeated measurementVariance is a result, not a footnote.
Inspectable casesHeadline claims link toward underlying evidence.
Reproducible dataVersioned source artifacts remain downloadable.
Explicit limitationsAgreement is never relabeled as accuracy.
Release history
Snyk VulnBench JS 1.0Published 11 June 2026 · Current
Further releases are planned. Unpublished results will not appear as speculative rankings or empty release cards.
Publication
Read, reproduce, and cite the work
The paper, reviewed methodology, source snapshot, and release data use stable public links.
Preferred citation
@misc{tal2026snykvulnbenchjs10,
  author = {Tal, Liran and Kloos, Johannes and Rudich, Arsenii and Thoemmes, Stephen and Nair, Manoj},
  title = {Snyk VulnBench JS 1.0: Can LLMs Find the Same Bugs Twice?},
  year = {2026},
  url = {https://arxiv.org/abs/2606.15762}
}
Copy BibTeX
Liran Tal · Johannes Kloos · Arsenii Rudich · Stephen Thoemmes · Manoj Nair