SlimSpec: faster speculative decoding without cutting the vocabulary
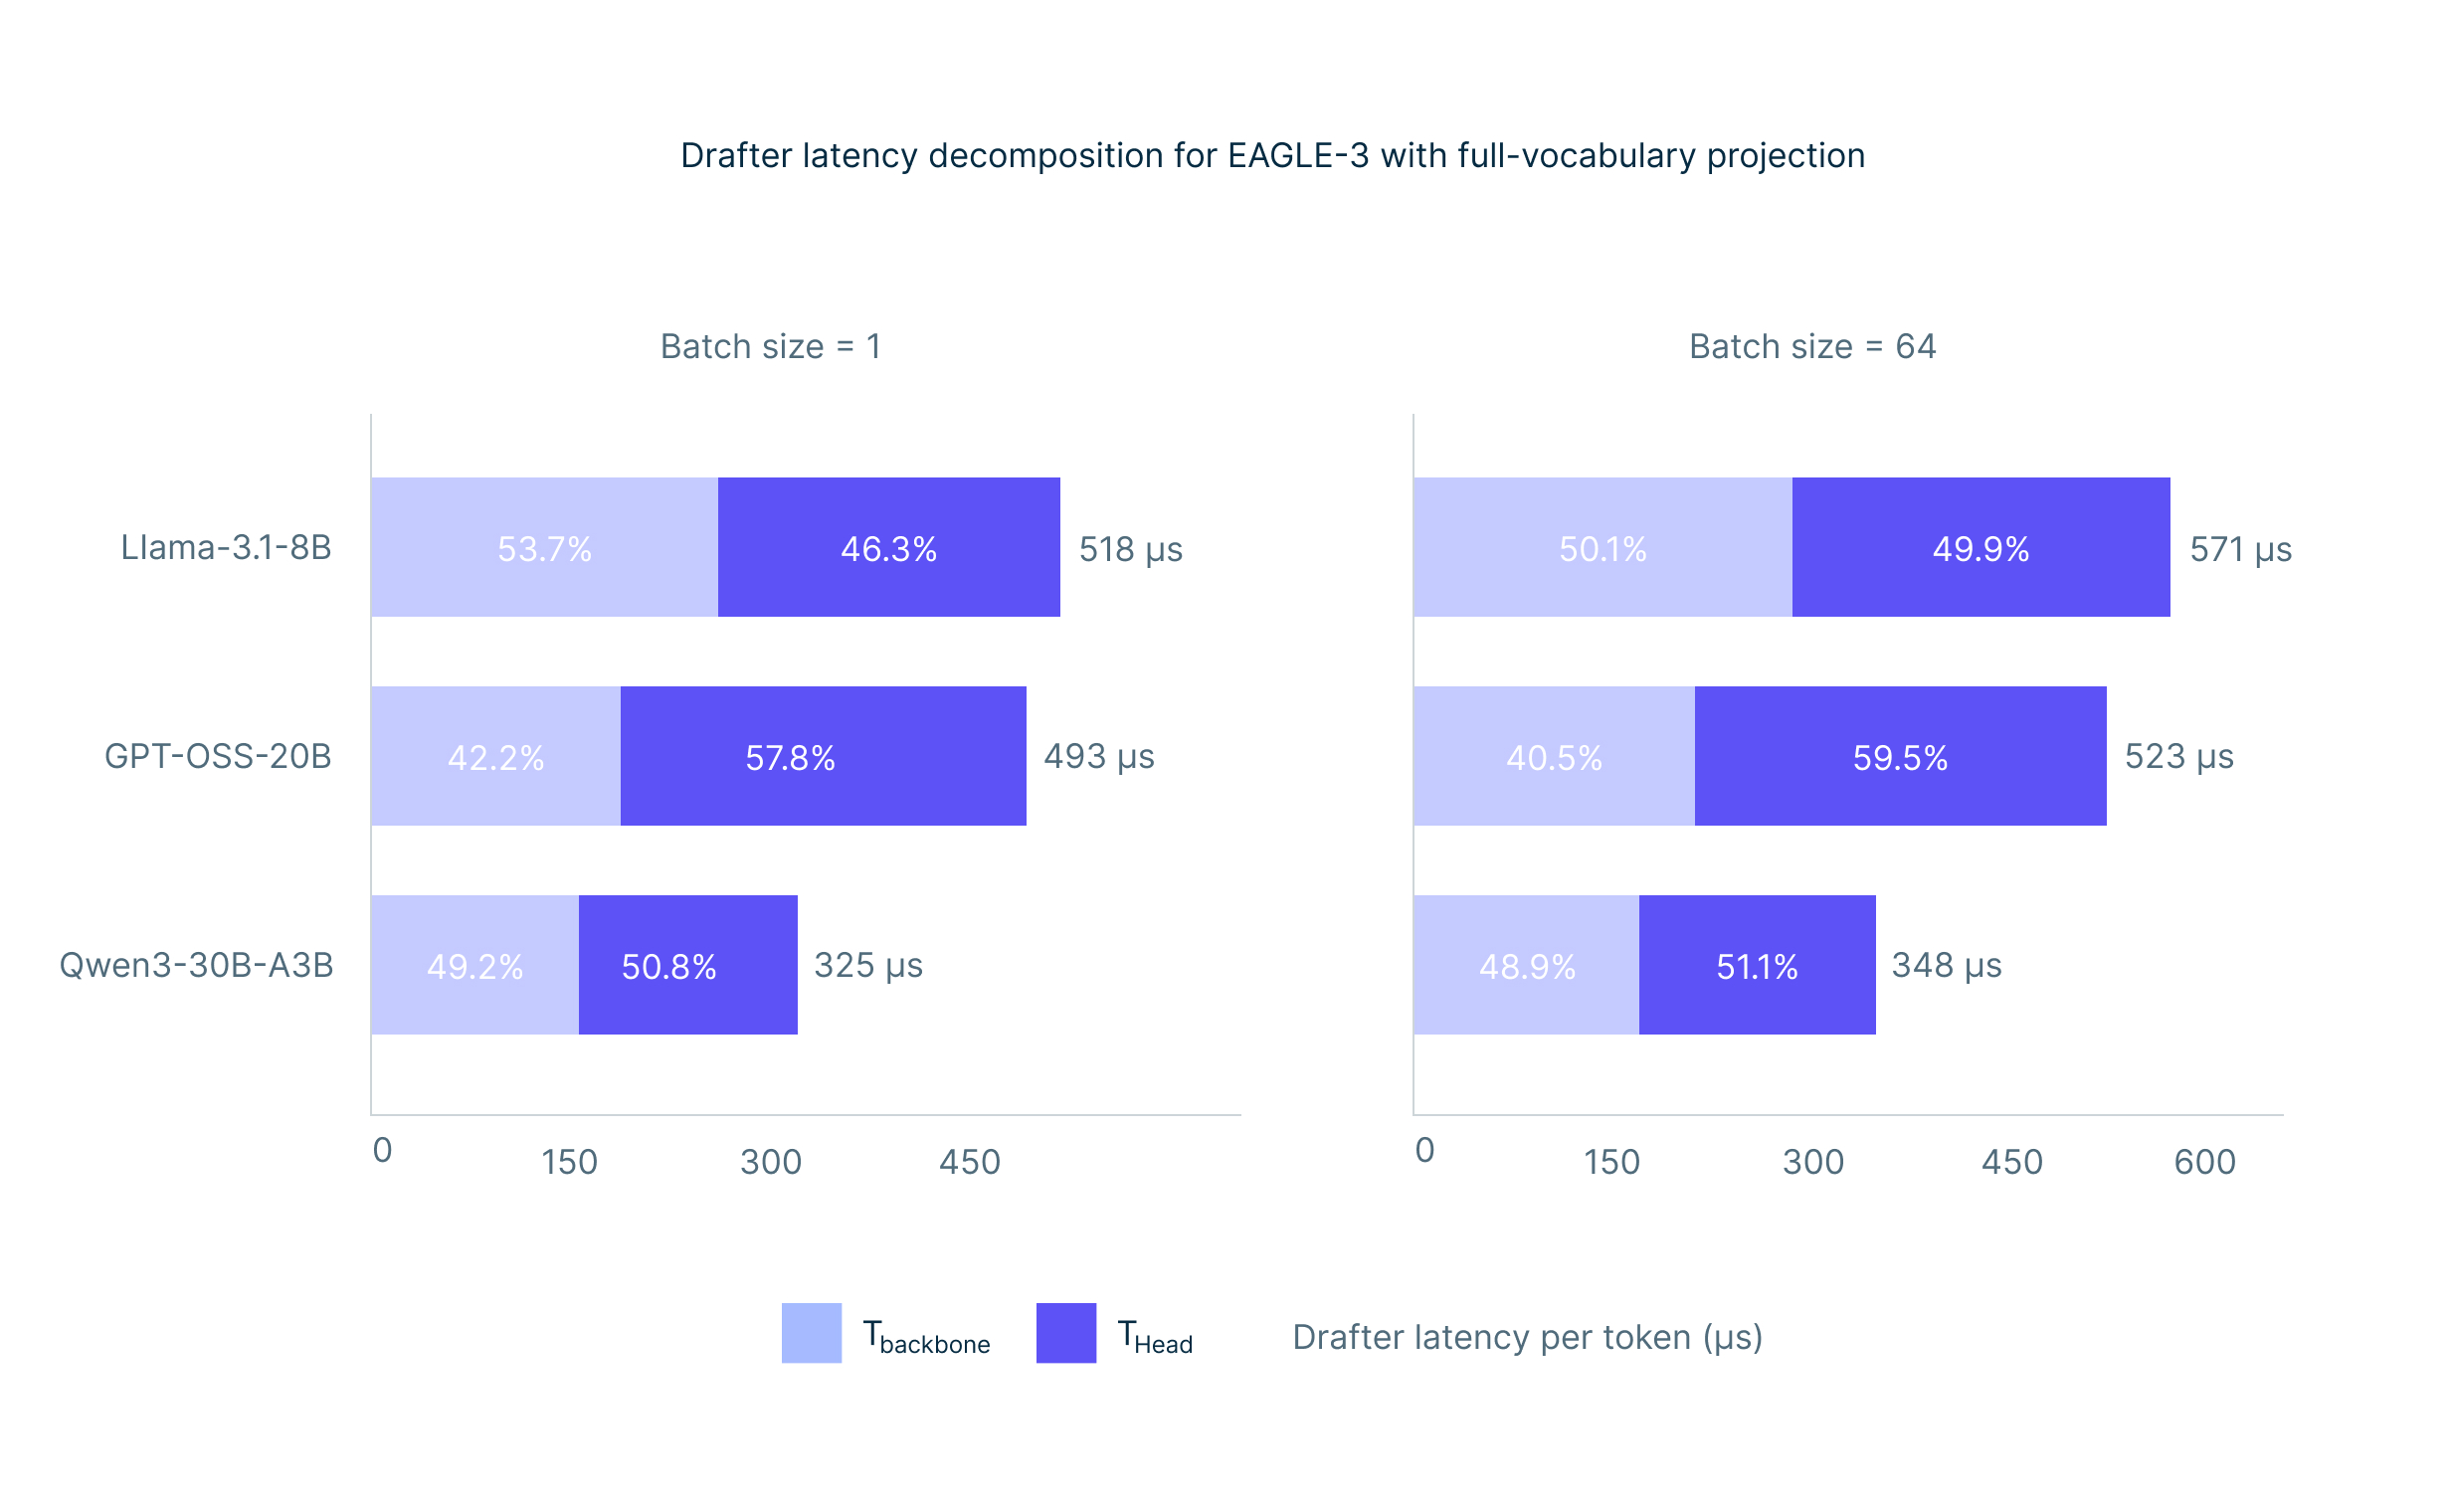
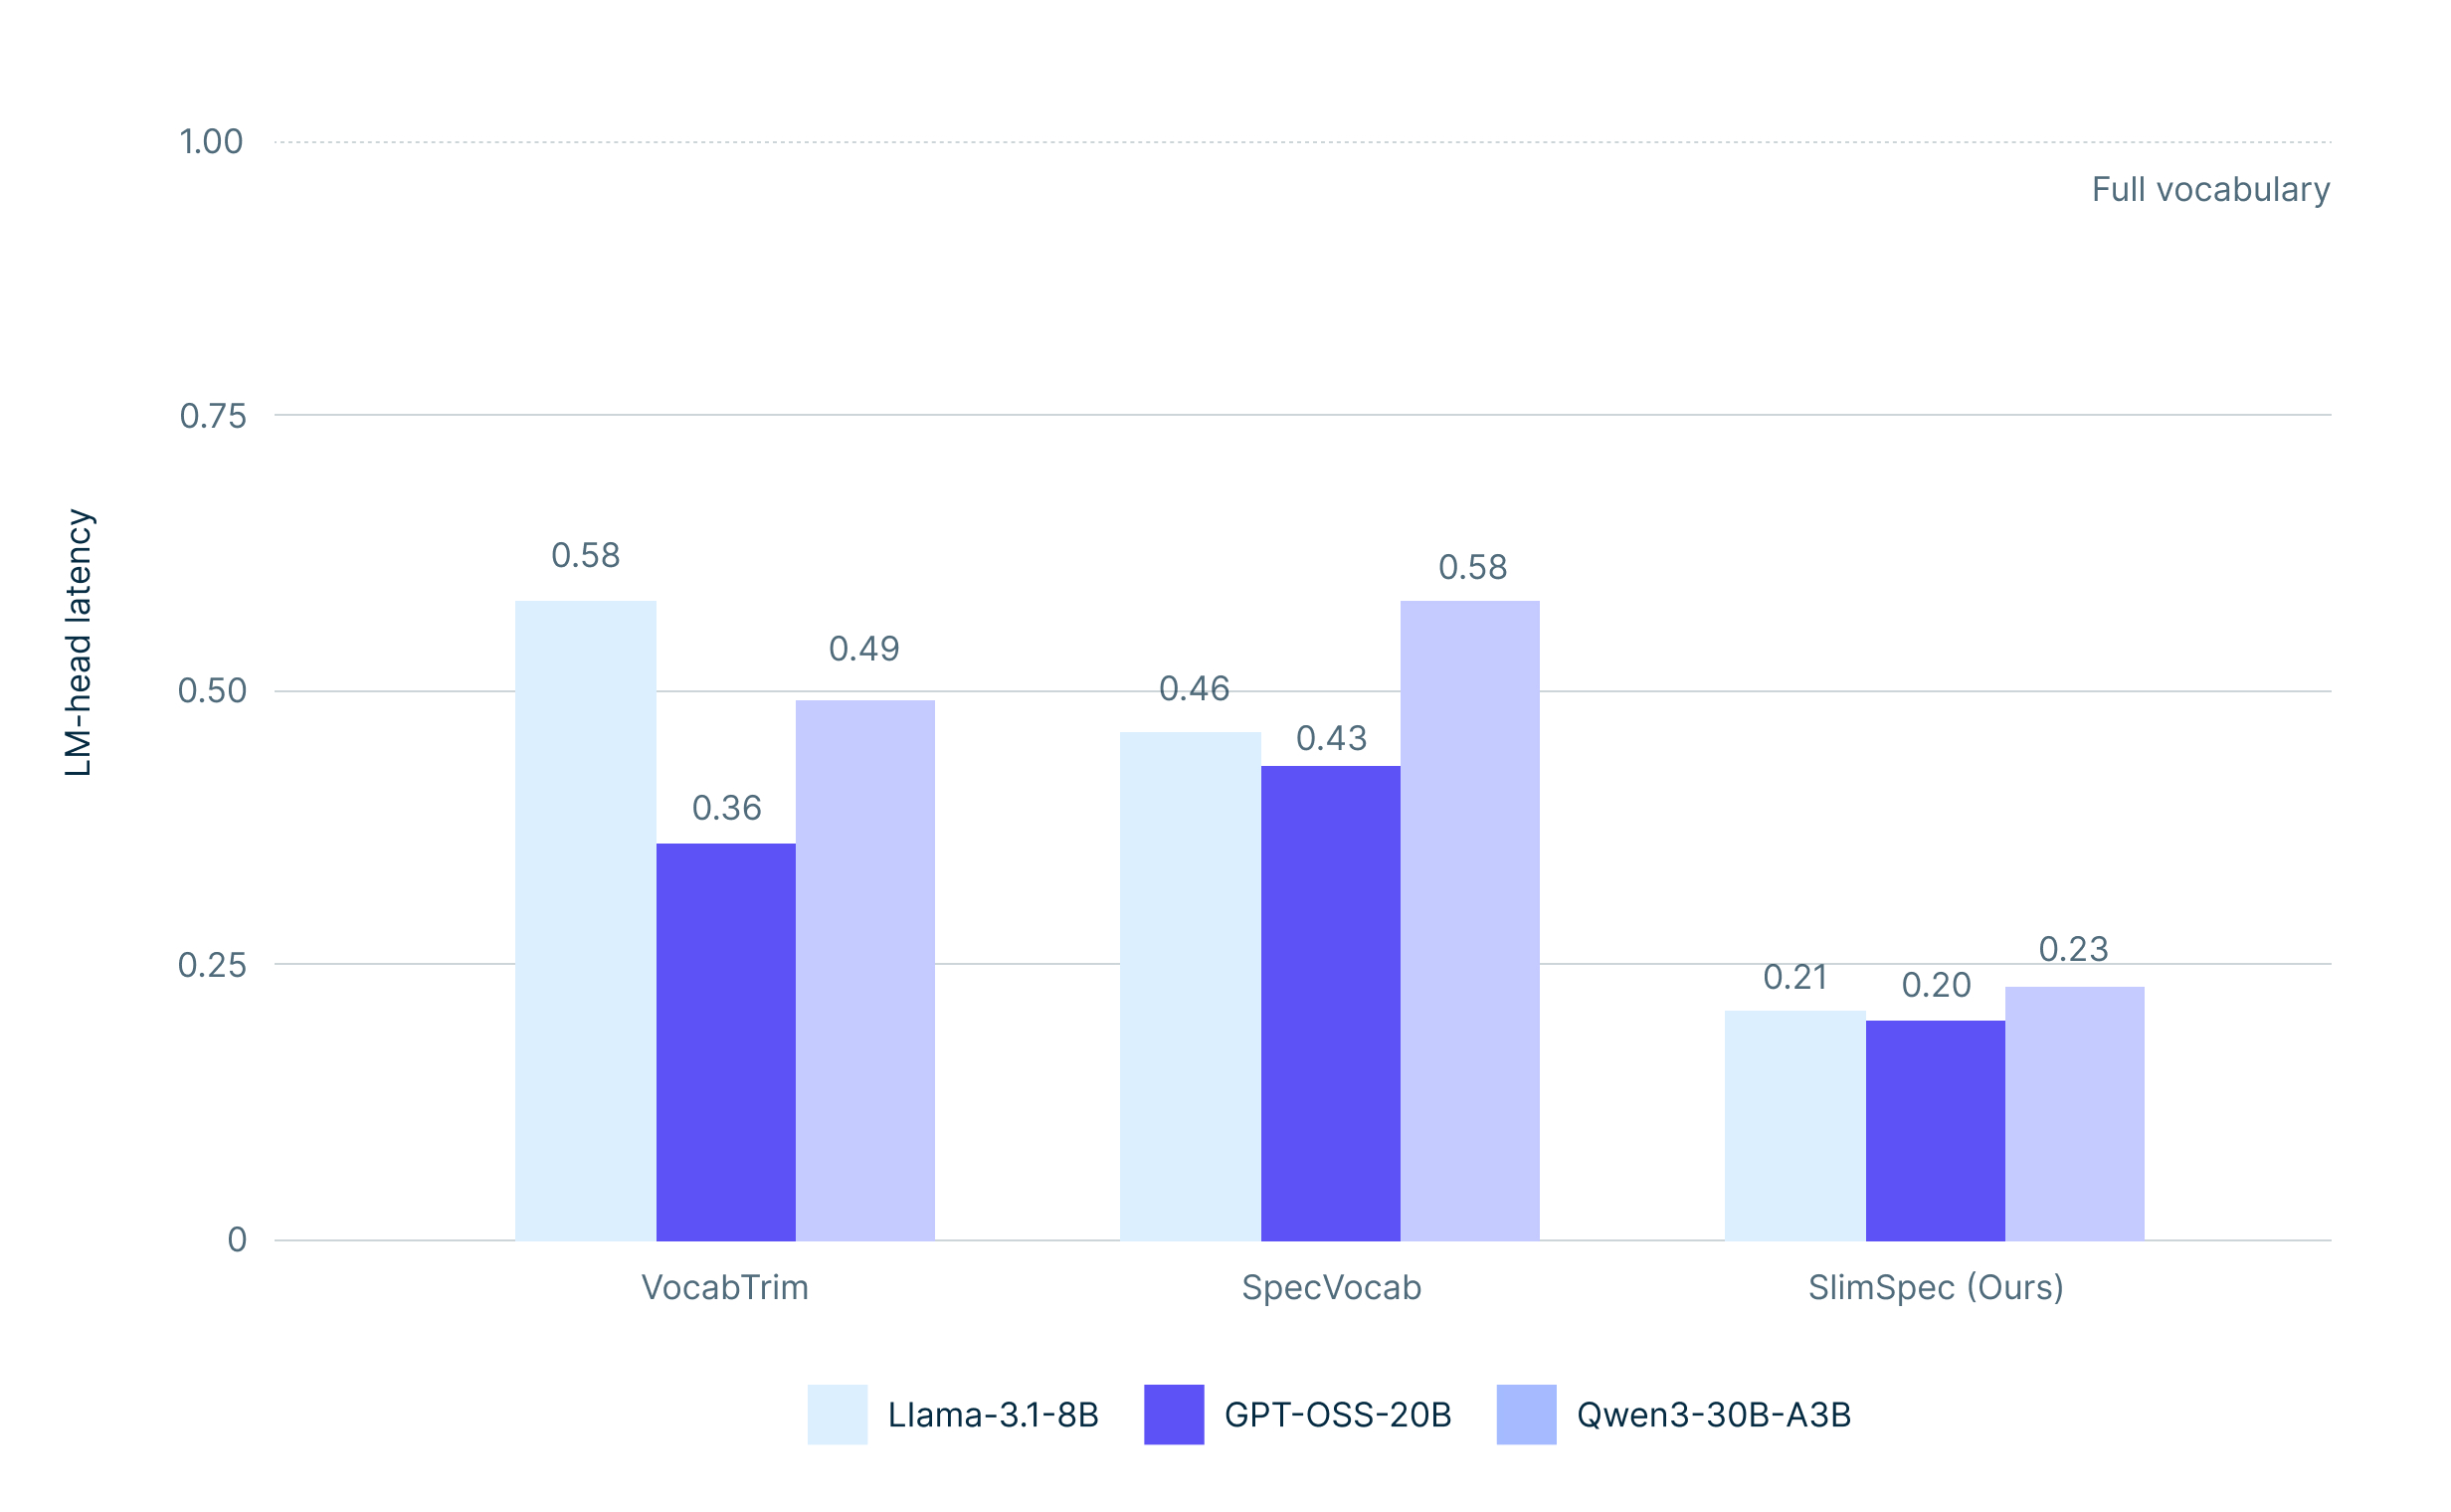
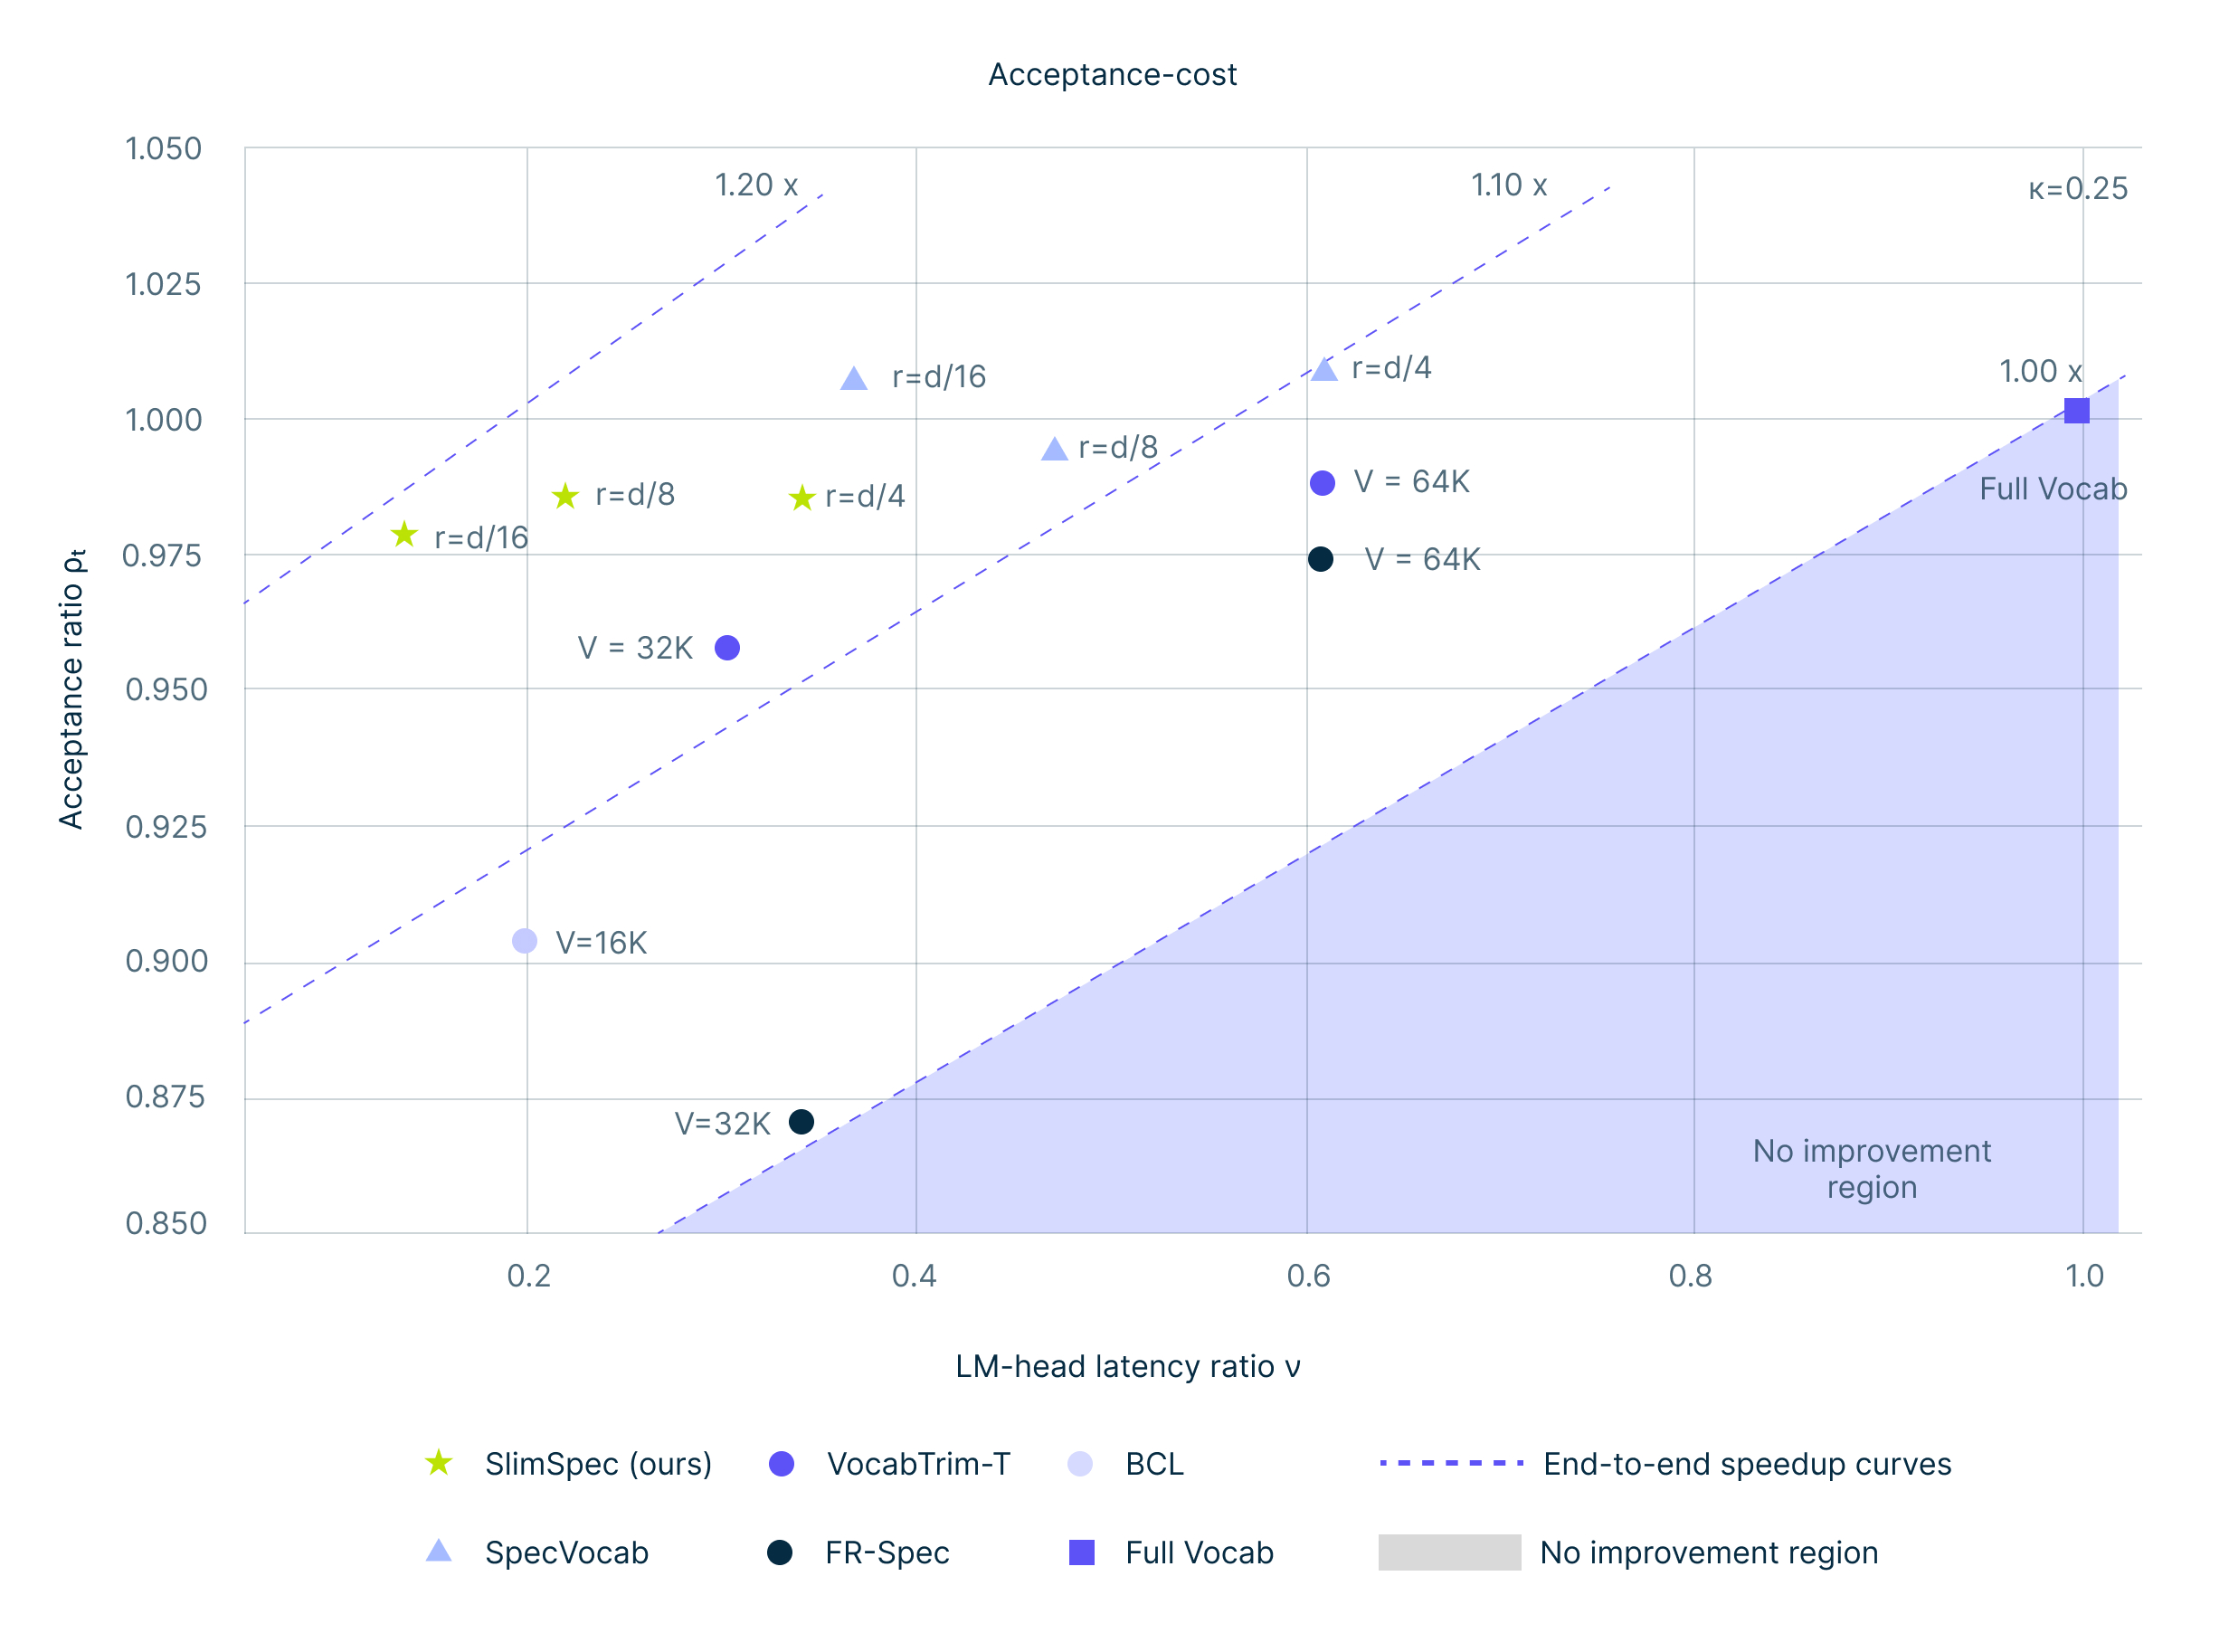
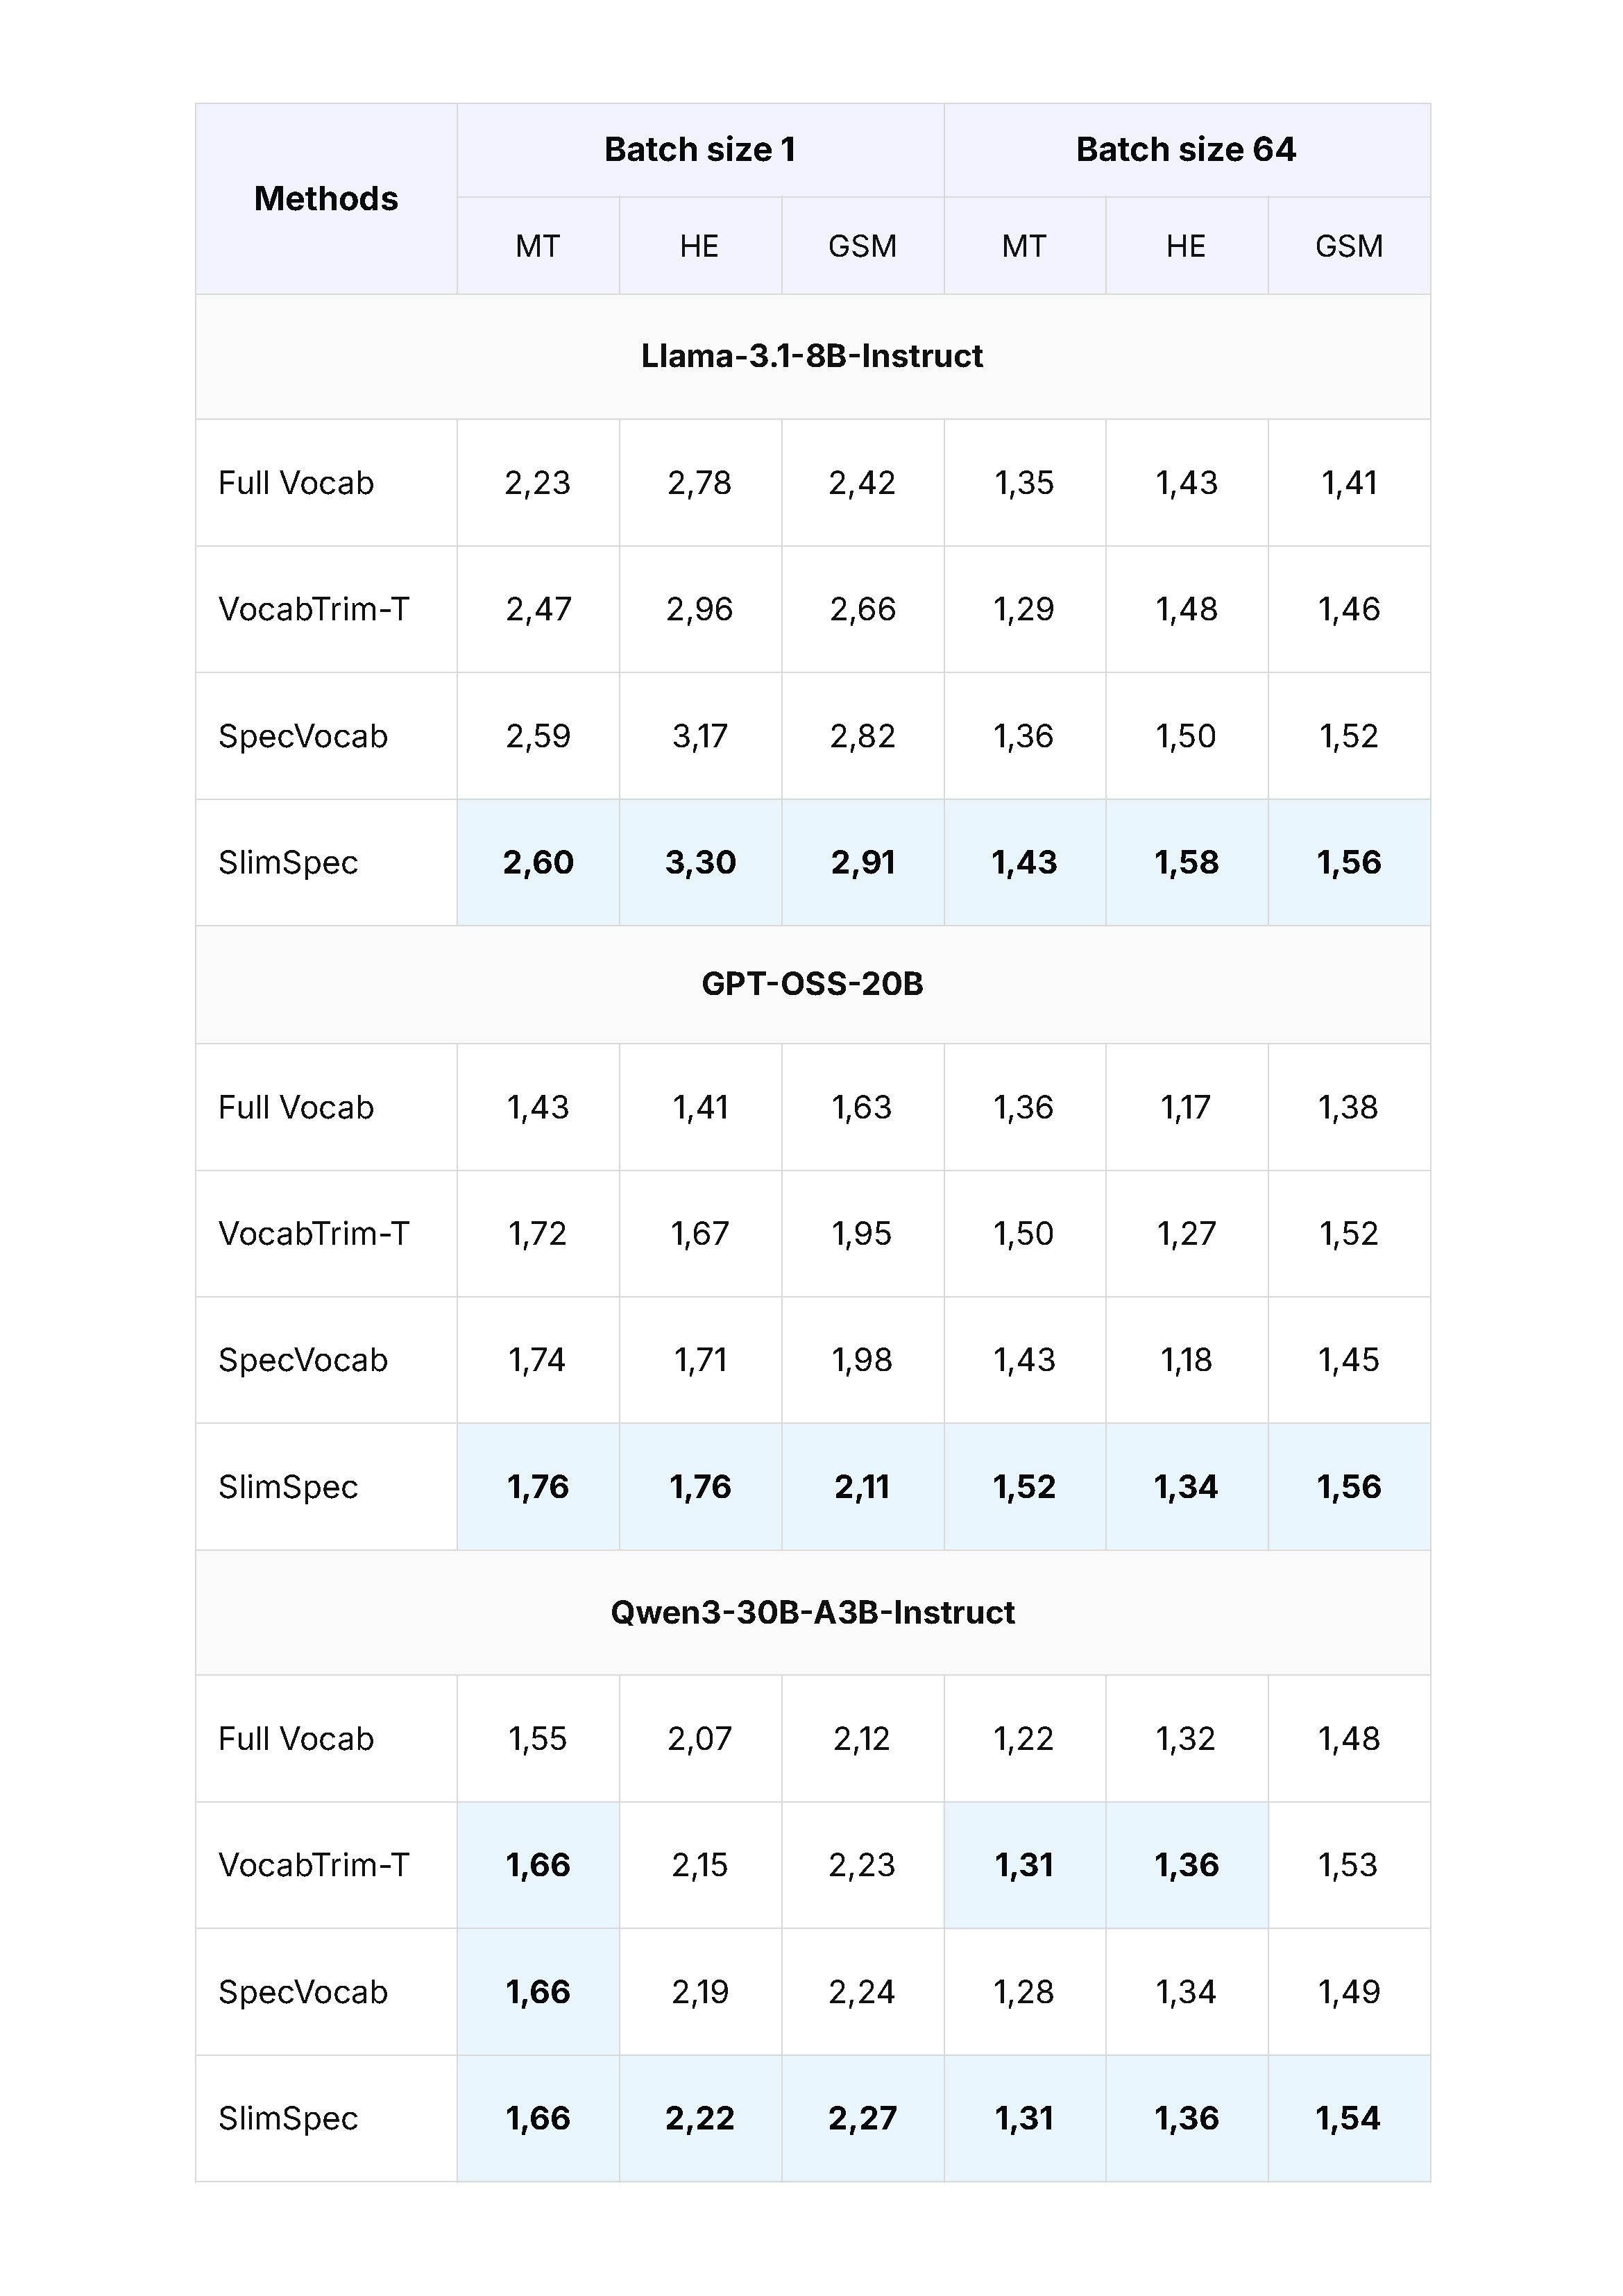
SlimSpec is a low-rank draft LM-head architecture for speculative decoding that reduces projection cost while preserving full-vocabulary support. In this article, we examine why the draft LM head becomes a bottleneck, how SlimSpec differs from vocabulary-truncation methods and what our EAGLE-3 experiments show about end-to-end decoding performance.


Comments (0)
No comments yet