Optimize youragents at scale.
Scanning traces Analyzing runs Recommendations Traces Traces Traces Traces Redundant retries Cost −33% Latency −12% Excessive tool calls Latency −55% Cost −41% Missing context Quality +7% Cost −23% Oversized prompts Cost −38% Latency −19% Uncached embeddings Cost −52% Latency −34% Serial API calls Latency −61% Cost −7% Over-broad retrieval Quality +9% Cost −31% Model overkill Cost −47% Latency −22% Unbounded loop Cost −44% Latency −37% Chatty sub-agents Latency −29% Cost −26% Stale tool schema Quality +11% Cost −6% Verbose system prompt Cost −24% Latency −9%
Find and ship agent improvements.›
Optimize your
agents at scale.Papaya proactively monitors your agents, finds the optimizations you didn't know to look for, and opens the PR — every fix ranked by quality, latency, and cost impact.
Why Papaya
Observability shows you what happened.
Papaya ships thehighest impact fixes.We thoroughly analyze your workflows to uncover quality gains and cost wins, using evidence from your own production runs.
< 15 min
Time to first improvement
From SDK install to a ranked, evidence-backed finding.
+10%
Success rate improvement
Typical quality increase with first workflow analysis.
$25K+
annualized savings per workflow
For large scale workflows.
One line— wraps any LLM or agent client.
Async— no request-path latency.
In your control— human-in-the-loop on every change.
How it works
Papaya scans your agentic traces.And finds what’s holding you back.
Papaya reads production traces across prompts, context, tools, models, and outcomes. It connects recurring behavior across thousands of runs and shows you which improvements matter most.
Request
Understand
Context
Plan
Next action
Use tool
Observe
Draft
Verify
Outcome
Request
Understand
Context
Plan
Next action
Use tool
Observe
Draft
Verify
Outcome
Context bloat builds up when the same history is sent on every turn.
18.0% of runs−$2.1K/mo
Prompt caching fails when context is ordered incorrectly.
62.4% cost reduction−$1.4K/mo
Tool schema drift causes valid requests to fail.
11.4% of runs−$840/mo
Retry loops persist because the agent is not configured to recover.
1,422 affected runs+8.2s latency
What you get
The full improvement loop in one place.
Papaya ingests traces in any shape, builds your quality rubric, ranks every improvement by impact, and delivers fixes where you work — from Slack alert to opened PR.
01
01 / 05
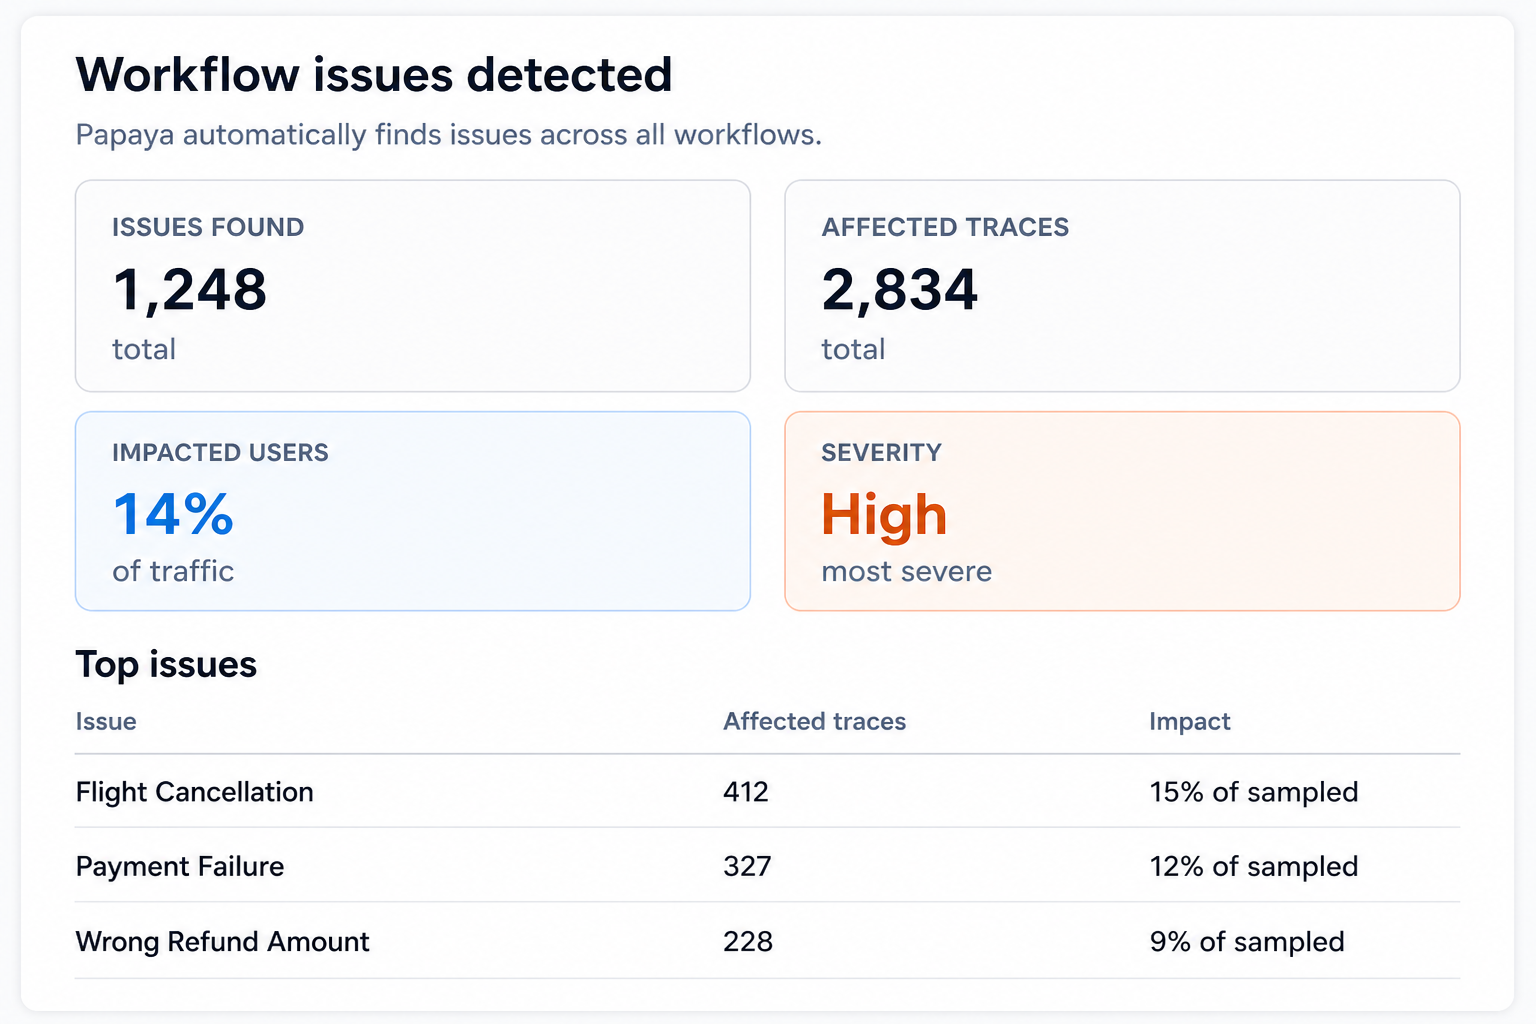
Automated trace detection and workflow identification
Papaya will read your data no matter the shape and automatically detect what is happening in your workflows.
02
02 / 05
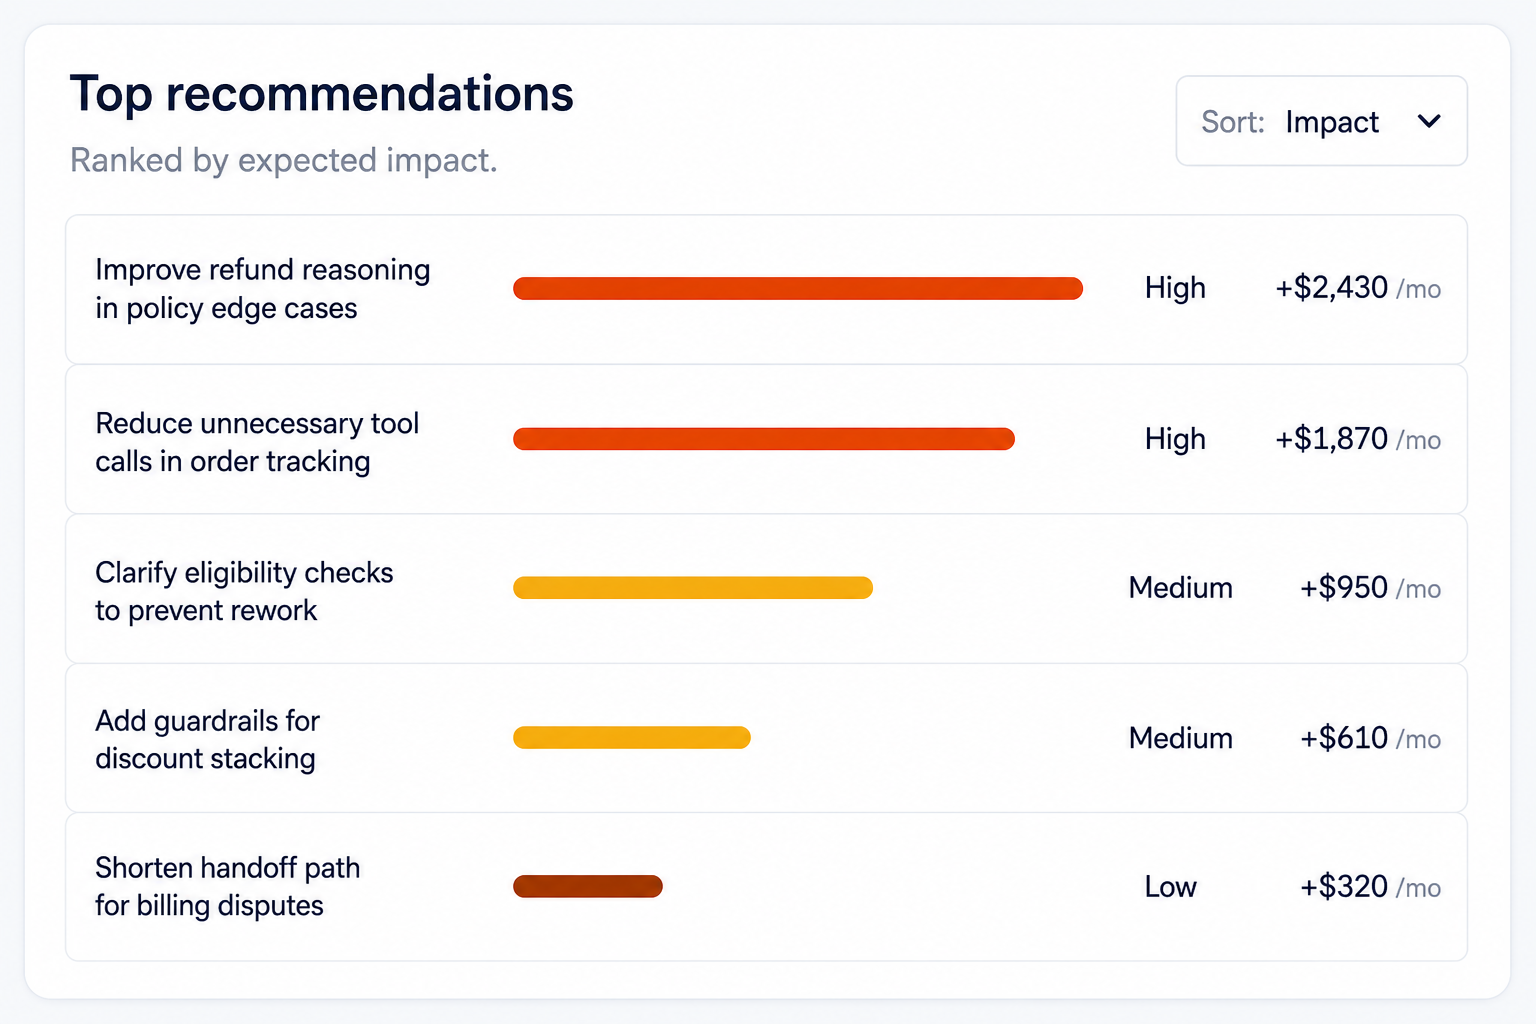
Ranked recommendations to improve your agents
Know which improvements will have the highest impact on quality, latency, and cost. Implement the ones you choose.
03
03 / 05
Use Papaya where you work
Get alerts to Slack sharing improvements and failures, and deploy those to your code.
Search Acme Corp
P
PapayaAPP10:42 AM
2 new high-impact improvements found for flight-cancellation
Flight Cancellation failures overuse code evaluation P0
+10pp quality −$284.12
Review & deployView evidence
View all 34 improvements in Papaya →
Message #papaya-alerts
04
04 / 05
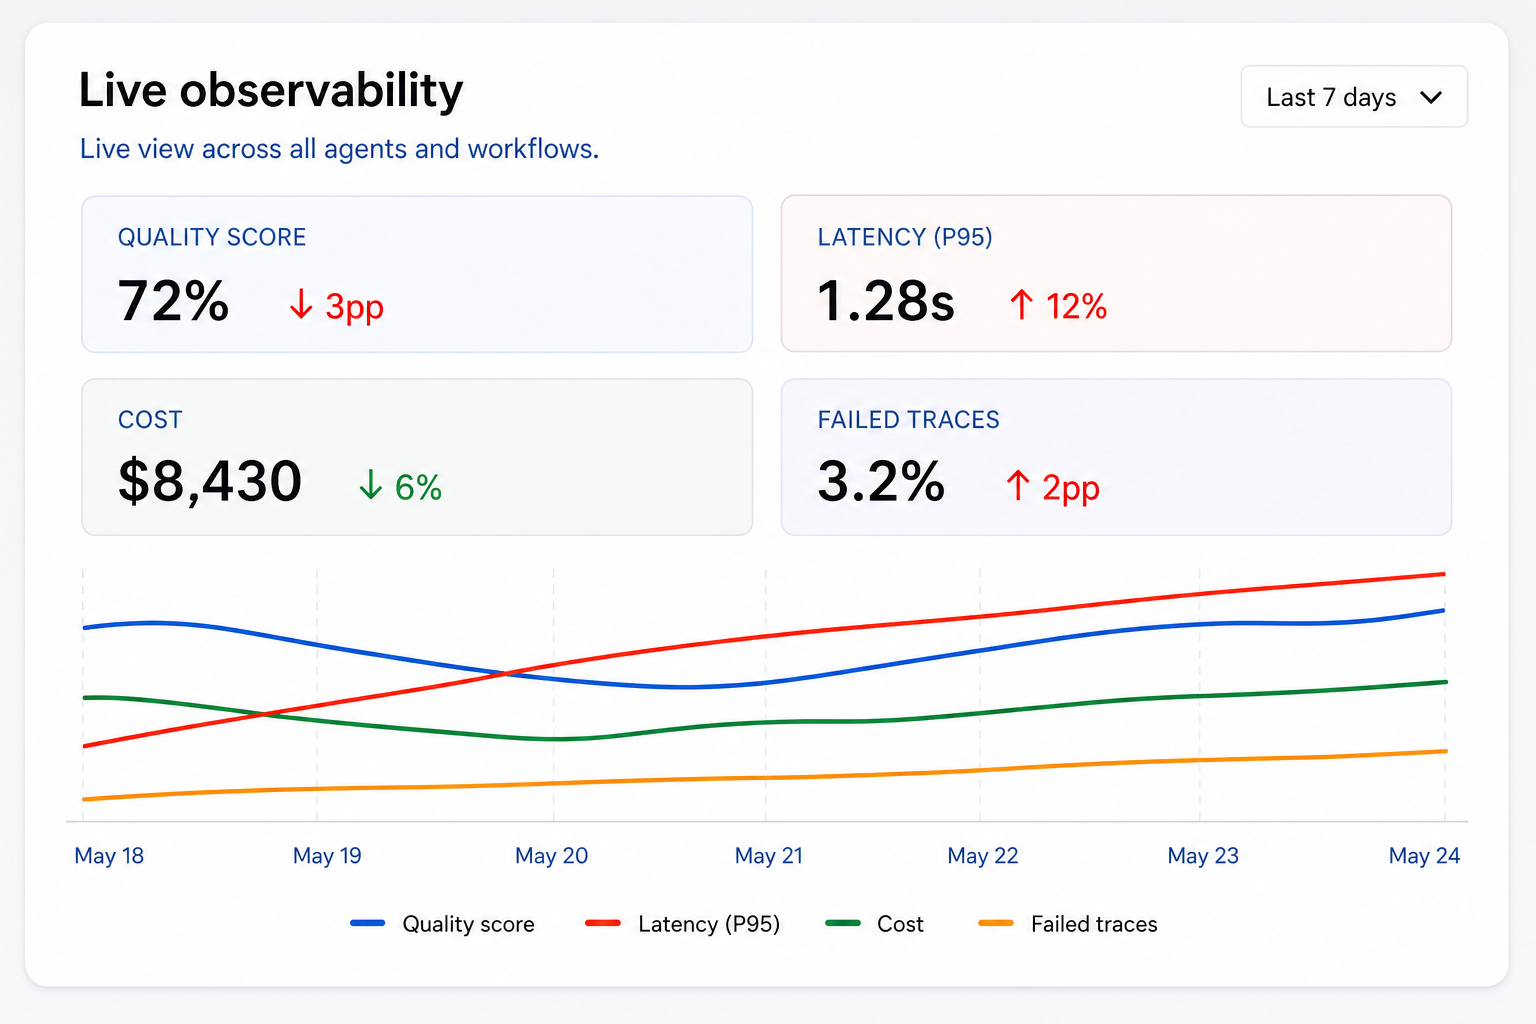
Live observability across every workflow
Get an overall picture of performance of your agents with top recommendations for improvement.
05
05 / 05
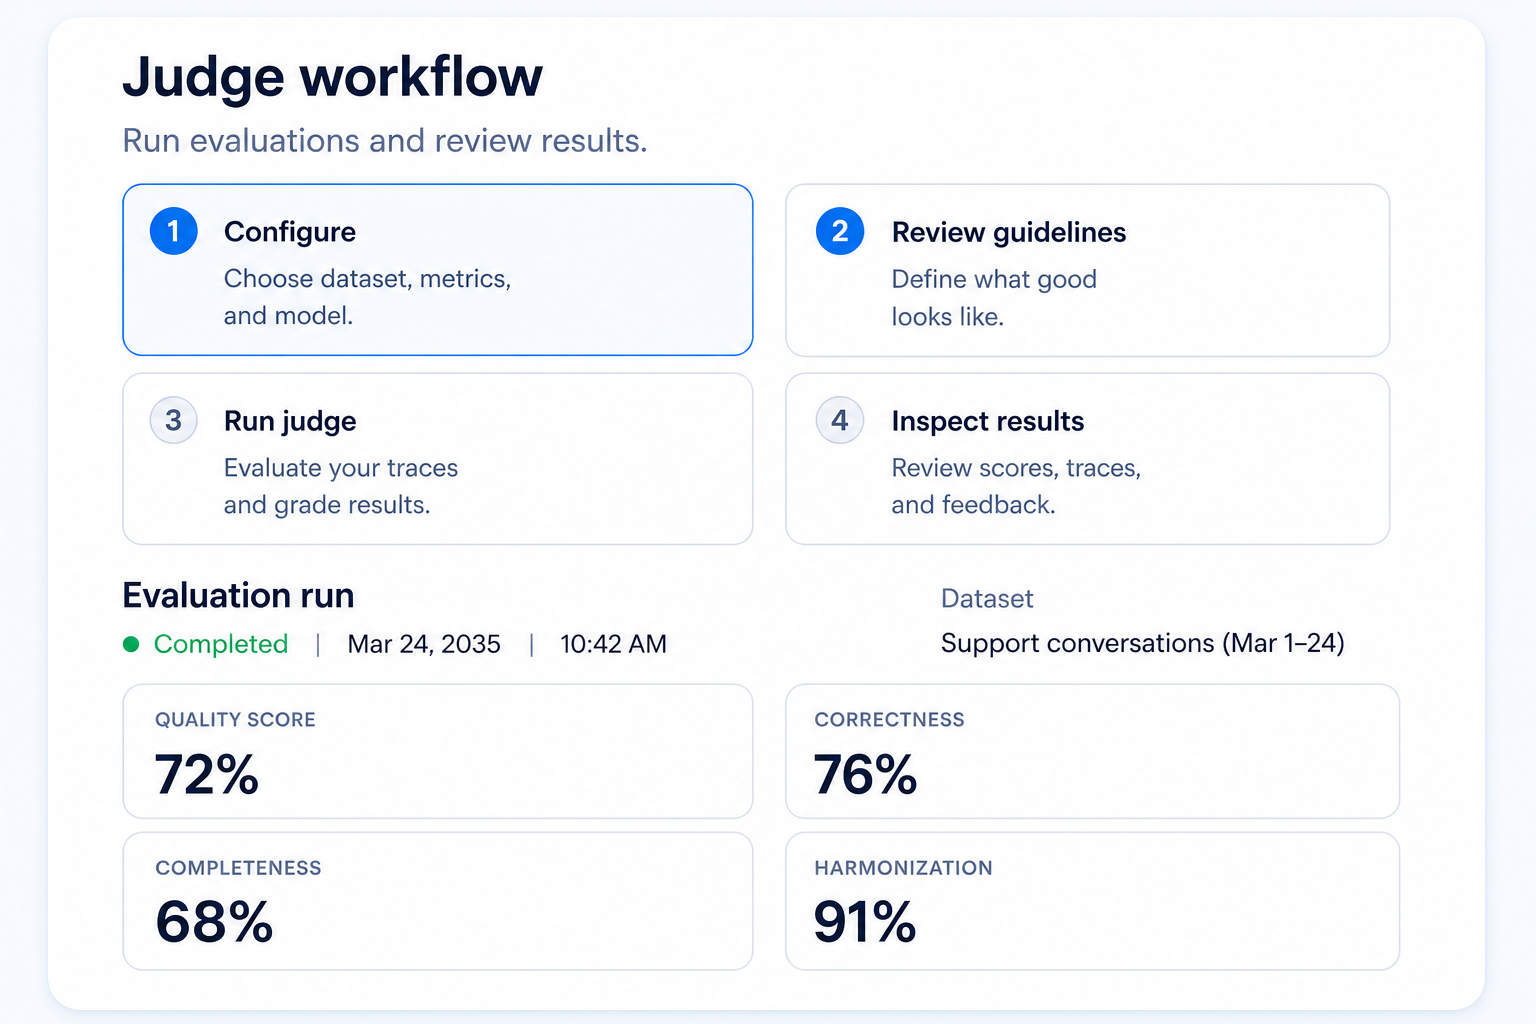
Interactive LLM Judge
Build an evaluation rubric automatically from trace data and customer signals. Tell it what edits you want to make.
From traces to fixes
Three steps from raw traces to a fix you can merge.
Wrap your LLM calls and then spend your time building the new features customers want, not on agent maintenance.
Step 01
Connect your production traces
Using the Papaya SDK, you can wrap any LLM or agent client with a single line of code. Alternatively, connect Papaya directly to your observability tool or share a dataset in any format. Papaya will automatically detect the shape of the data.

Step 02
Papaya analyzes and finds improvements
Papaya runs 200+ research-backed analyses against your traces. It identifies the improvements that matter most and ranks them by expected impact.
Outcome & Trajectory
Prompt & Planning
Context, Memory & Retrieval
Tool Execution Reliability
Cost & Model Routing
Evidence-Backed Validation

Step 03
Review and implement suggestions.
Understand the exact runs that are producing a recommendation and then choose to implement. Automatic alerts in your tool of choice when a new optimization is found.
- The exact run that produced the finding
- The prompt, tools, and context as the model saw them
- Estimated impact, risk, and confidence

How it operates
Every recommendation comes
from your own traffic.Papaya runs 200+ research-backed analyses around the clock and flags the fixes worth making — with proof.
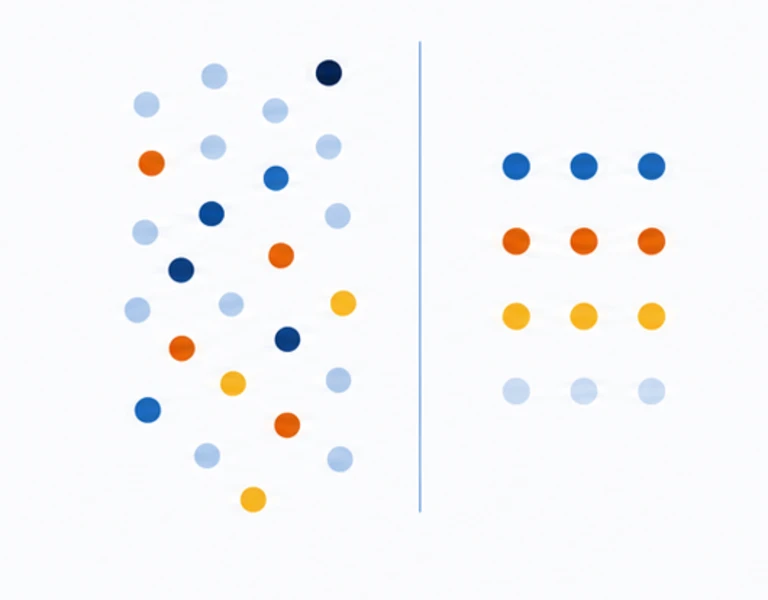
Finds recurring patterns
Findings cluster across thousands of sampled runs by root cause — not one trace at a time. Each one tells you how many runs it affects.
Catch drift before customers do
Live alerts when quality metrics drift — before a customer escalates. You learn when it matters, not when you remember to check.
Tied to real outcomes
Drop-off, thumbs-down, Slack replies, and support tickets — all tied to the runs and workflows that actually produced them.
Compounds over time
Every fix you ship and every new run feeds the next analysis. The system doesn't start from zero — findings get sharper as you go.
Backed by the best
Get started
Start with one workflow — get a full audit in 24 hours.
Share your traces in whatever form you have, even a raw export — no integration needed. You'll get back a ranked set of improvements with the evidence behind each one, and what every fix is worth in quality, latency, and cost. No commitment: the audit is yours to keep either way.