Is your gpt-6-astra real?
Is your gpt-6-astra real?
An informal investigation into Codex sessions · September 2026 · not affiliated with OpenAI
- We asked Codex (`gpt-6-astra`) to draw the same SVG pelican dozens of times. About half came out polished. The rest were crude cartoon birds that an image classifier mostly took for ducks or gulls.
- Which one you got followed the ChatGPT account. Prompt, settings, client version and time of day didn't explain it.
- On affected accounts, responses run at a different speed, are shorter, and write and draw like `gpt-5.6-luna`. The server still reports `gpt-6-astra`.
- In our data it started abruptly on 2026-09-20 around 09:00 UTC.
- We can't see the server side, so we can't say why, or confirm which model it is. You can check your own account.
- Why. The data fits a per-account experiment or routing cohort, an account-level policy, or capacity routing. We can't tell these apart from the client side.
- Exactly which model. The identification is statistical, from speed, drawing style and phrasing.
- Whether it affects typical users. Our data comes from one team using many ChatGPT Pro accounts one after another, with heavy daily usage. Ordinary single-account users may or may not see this. That's the main reason we're sharing the script.
- YES (exit 1): at least 2 of 3 runs in a round streamed clearly faster or slower than real gpt-6-astra.
- NO (exit 0): three rounds looked normal. Affected accounts are intermittent, so a NO lowers the odds but isn't proof. Re-run later if things feel off.
- UNKNOWN (exit 2): Codex failed, or too few runs gave a clear measurement.
- Pelicans: the drawings were scored with an off-the-shelf image model (CLIP): "is it a pelican" × "is it a good illustration". Scores split into two groups with a clear gap.
- Speed: the history analysis uses tokens/s per long response, compared with the expected speed for its size. The check script times only the answer text streaming after reasoning ends, so network, queueing and startup delays don't count. Real gpt-6-astra streamed at 32.5–33.8 tok/s in every run; anomalous means outside 30.5–36.5.
- Accounts: counted as affected when ≥30% of their long responses are anomalous. Accounts fall clearly on one side or the other.
- Ruled out: reasoning effort, quota used, time since the account was first used, Codex version and settings, prompt and context.
- Reference runs: the same prompts run with each available model requested explicitly, compared by drawing style, phrasing, and a 12-question text benchmark.
- Caveat: in the live side-by-side test the affected account ran in a container and the normal one on the host.
The pelicans
Same request (minor wording differences), same model name, same Codex settings:
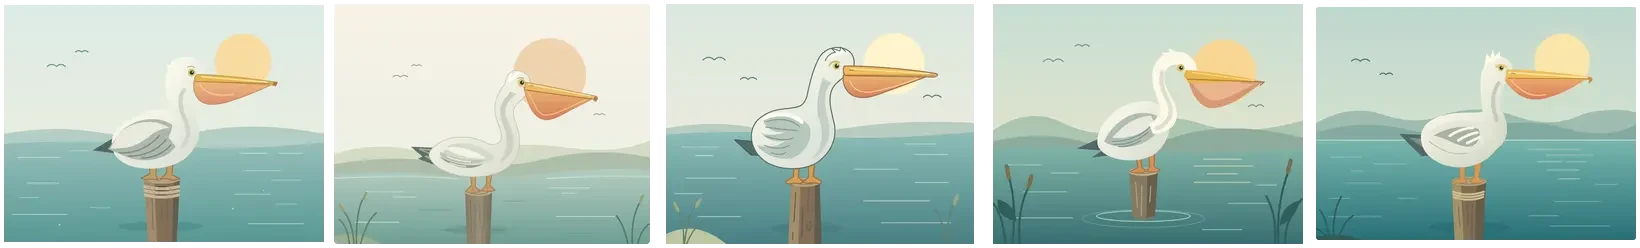
Normal accounts, labelled gpt-6-astra

Affected accounts, also labelled gpt-6-astra
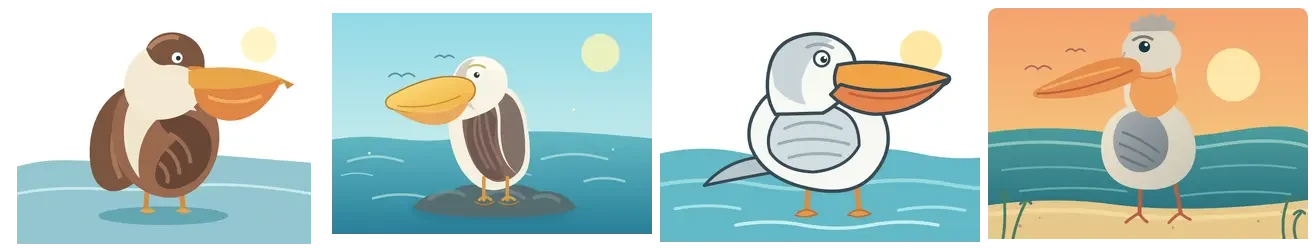
For comparison: gpt-5.6-luna, requested explicitly
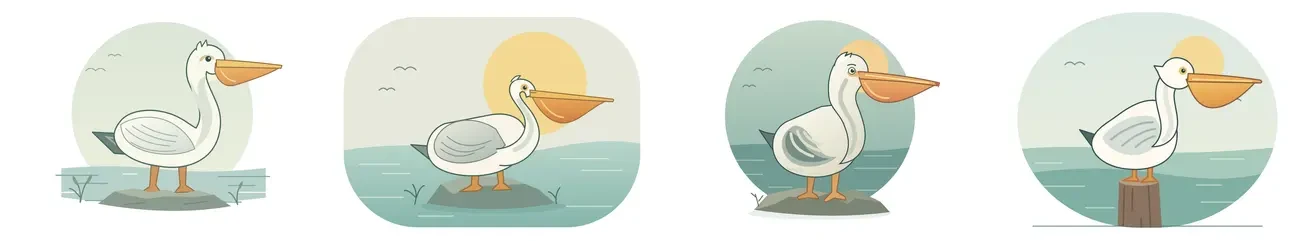
For comparison: gpt-6-astra, requested explicitly on a normal account
What we found
| Finding | Evidence | Strength | | ---------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------ | ------------------------------ | | A change on Sep 20 | No accounts affected before; more than half of those used after (Fisher p = 2·10⁻¹²) | strong | | It's per account and mostly stable | An account's first half predicts its second half (ρ = 0.79). Accounts in the same hour can differ. | strong | | Real work is affected, not just pelicans | Per account: about 25% less output per response (p = 3·10⁻⁵); turns interrupted by the user roughly 20× as often (p = 0.009) | strong | | Reproducible on demand | Same machine setup, prompt and settings; only the account changed: every run normal on one account, most runs anomalous on the other | significant (one account each) | | Output isn't gpt-6-astra's | 12-question text benchmark: affected answers are less astra-like on 12/12 questions (Wilcoxon p = 0.0005) | strong | | It's gpt-5.6-luna | Closest by drawing style, phrasing and speed. The luna comparison was chosen after a preview (p = 0.016). | suggestive |
0%2.5%5%7.5%10%2026-09-05: 0.0%052026-09-06: 0.0%2026-09-07: 0.0%072026-09-08: 0.0%2026-09-09: 0.0%092026-09-10: 0.0%2026-09-11: 0.0%112026-09-12: 0.0%2026-09-13: 0.0%132026-09-14: 0.0%2026-09-15: 0.0%152026-09-16: 0.0%2026-09-17: 0.0%172026-09-18: 0.0%2026-09-19: 0.0%192026-09-20: 2.8%202026-09-21: 9.7%212026-09-22: 2.8%2026-09-23: 8.0%23Sep 20September 2026 (day) — share of long gpt-6-astra responses faster than normal serving allows
Normal `gpt-6-astra` serving tops out around 34 tok/s. In the two weeks before Sep 20, essentially none exceeded that. After, some did every day.
normal range15202530354045505560answer streaming speed, tokens/s (real gpt-6-astra ≈ 33.4)normal accountaffected account
Answer streaming speed in repeated check-script runs on normal and affected accounts. Real gpt-6-astra is very steady. Affected accounts are intermittent, and one round of three looked normal.
What we can't tell you
Check your own account
Download is\_my\_astra\_fake.py
python3 is_my_astra_fake.py
Needs the `codex` CLI, logged in, and Python 3.8+ (standard library only). It sends 3–9 short `gpt-6-astra` requests through your own Codex, which use a little of your quota. It then reads the timing from Codex's local session logs and compares how fast the answer streams with what real `gpt-6-astra` produces. A slow connection doesn't affect this. It doesn't send anything anywhere else. The `Account` line comes from your local login file and is only printed to your terminal.
$ python3 is_my_astra_fake.py Account: you@example.com (pro) Benchmark: up to 3 rounds of 3 parallel gpt-6-astra runs (1-4 minutes)
round tok/s normal reasoning 1 51.0 30.5-36.5 120 ANOMALOUS 1 28.0 30.5-36.5 90 ANOMALOUS 1 33.4 30.5-36.5 40 normal
Is my gpt-6-astra fake? YES (2/3 runs anomalous) # illustrative output
If you post your result, a YES/NO, the date and whether you use a single account is plenty. Please don't share emails or session logs.
Method details