
C's Flexible Integer Sizes were Not a Design Mistake
C's Flexible Integer Sizes were Not a Design Mistake
Word sizes, strange machines, and why int was never meant to mean 32 bits. C's flexible integer types were not a design mistake. They were how the language achieved portability in a world of 12, 18, 36, and 60-bit computers.

25 Septeober 2026 · 15 min read
Here at the school, we work with a lot of retro machines and old game consoles, so it's no surprise that we are often the first point of contact for many developers learning the C programming language. Many of our students come come from languages like Python, JavaScript, Java, C#, Swift, and others.
It does not take long for beginners to realize that many aspects they took for granted in their primary language are not necessarily a given in C. Fairly often, we find ourselves asking questions such as:
- How many bits does this variable occupy in memory?
- What is the padding in this structure?
- Is this field properly aligned in RAM?
- `int8_t`: signed integers of exactly 8 bits
- `uint8_t`: unsigned integers of exactly 8 bits
- `int16_t`: signed integers of exactly 16 bits
- `uint16_t`: unsigned integers of exactly 16 bits
- `int32_t`: signed integers of exactly 32 bits
- `uint32_t`: unsigned integers of exactly 32 bits
- etc.
- 8-bit bytes
- Byte-addressable memory
- 32 or 64-bit registers
- Two's-complement integers
- A flat, conventional memory model
Integers are Not 32-bits
Another rite of passage for C beginners is to learn how to use and to make sense of the operator `sizeof`.
Observing their program output 4 when they ask for the `sizeof(int)` seems reasonable enough, given that in most modern machines, a signed integer occupies, indeed, 4 bytes in memory.
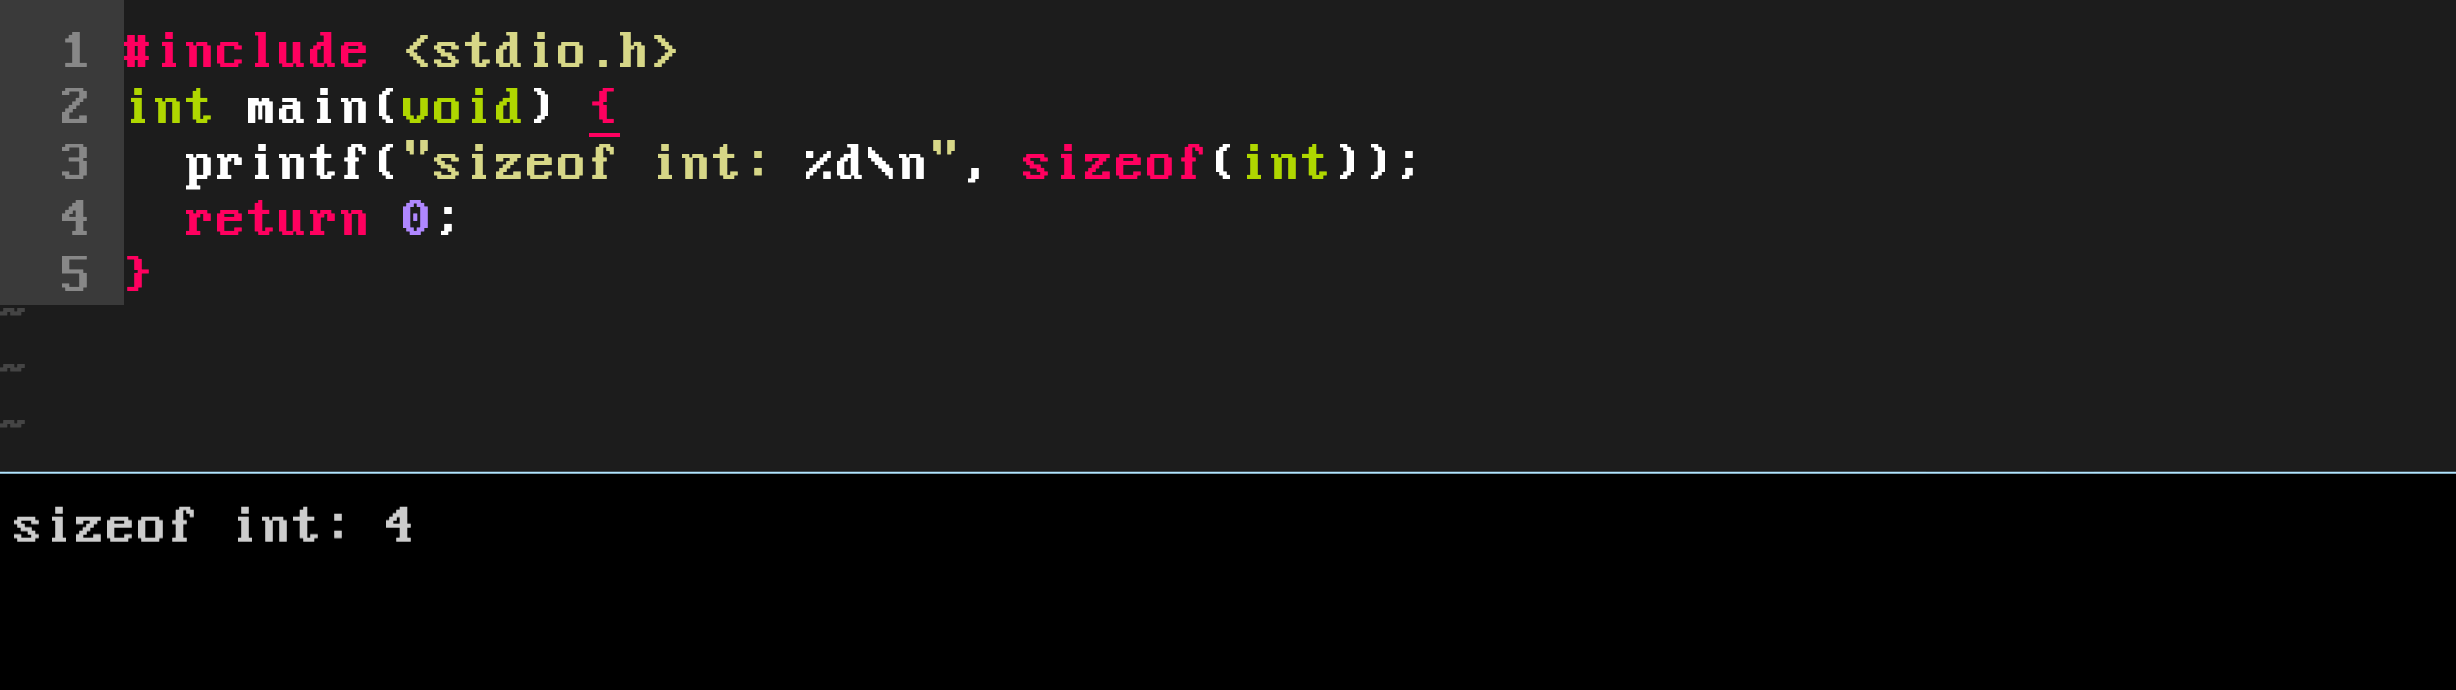
sizeof int: 4 bytes
Unfortunately, I must also tell my students that, when I first started learning how to code, if I asked for the `sizeof(int)`, my old 386 machine would output 2 bytes!
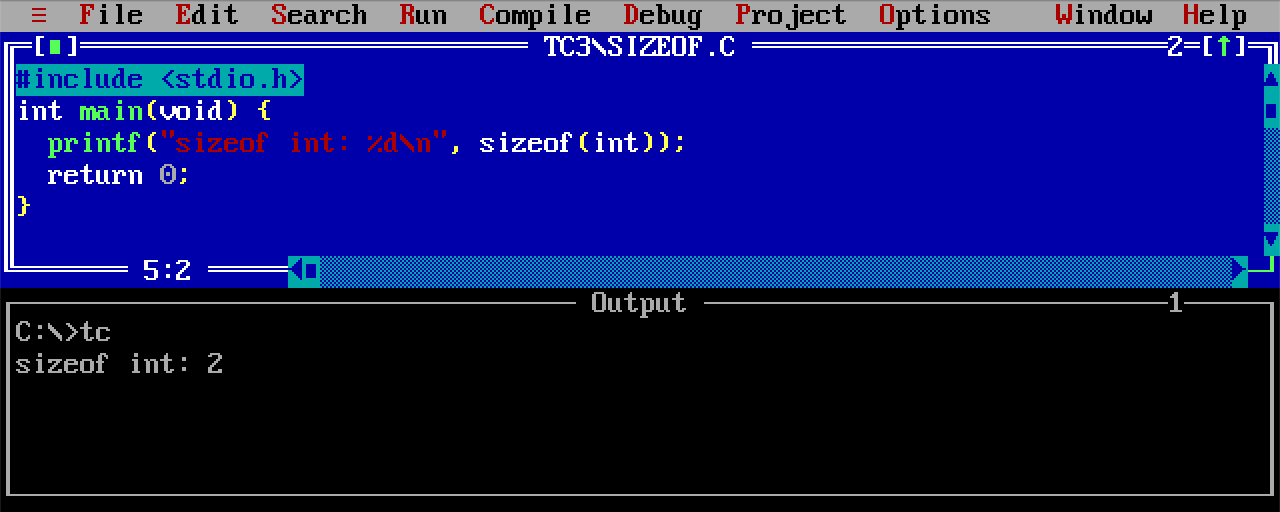
sizeof int: 2 bytes
And right about here is where we start a discussion on how native C integer types do not have a fixed size. Language types such as `char`, `int`, `short`, and `long` do not come with a guarantee of how many bytes they occupy in memory.
Since we usually want fixed sizes in our code, we tend to suggest students to use the `STDINT.H` header to take advantage of actual fixed-size types, such as:
The header `<STDINT.H>` was introduced as part of the C99 standard (published in 1999), and it helps programmers guarantee that their variables are declared to occupy an exact number of of bytes, regardless of the compiler and regardless of the machine architecture we are compiling against.
Are Non-Fixed Integer Sizes a Design Mistake?
A fairly common take in programming circles is that C's platform-dependent integer types were a design mistake.
To be fair, this is not wrong. Most programmers that use C with modern systems would argue exactly that. An `int` is 16 bits on one machine and 32 on another, `long` is 64 bits on Linux but 32 on 64-bit Windows, and all of this has caused decades of portability bugs. So, given that today almost every CPU is a 64-bit machine that handles 8, 16, 32, and 64-bit arithmetic... why didn't C just fix the sizes from the start?
This is basically us trying to judge a 1970s design decision by 2020s conditions! C was built to be a portable systems programming language that could map efficiently onto very different computer architectures. The flexible type sizes weren't an oversight; they were how C achieved that portability.
Keep in mind that C's goal for "portability" meant something different than Java's portability promise of "write once, run anywhere." And to understand why, you have to remember what "a computer" meant when C was designed.
The World Before 8-bit Bytes Won
Today we take a lot for granted. Almost every machine you'll touch has:
None of this was guaranteed in the 1960s and 70s. The industry had not converged, and machine word sizes were all over the map:
| Machine | Word size | Notes | | ------------------------------------------------------------------------ | --------- | --------------------------------------------------------------------------------- | | DEC PDP-8 | 12 bits | Hugely popular minicomputer | | DEC PDP-7 | 18 bits | Where UNIX was born, in assembly | | DEC PDP-11 | 16 bits | Byte-addressed; where C grew up | | DEC PDP-10 / DECSYSTEM-20 | 36 bits | Characters were often packed 7 or 9 bits at a time | | Honeywell 6000 series | 36 bits | 9-bit characters; an early C target | | UNIVAC 1100 / Unisys 2200 | 36 bits | Ones'-complement arithmetic, 9-bit chars; still has a C compiler today | | IBM 7090 / 7094 | 36 bits | 6-bit character codes | | SDS 940, ICL 1900, Harris | 24 bits | ICL used 6-bit characters | | Burroughs B5000 family | 48 bits | Tagged, stack-oriented architecture | | CDC 6600 | 60 bits | 6-bit characters, no byte addressing at all | | Cray-1 | 64 bits | Word-addressed; in C, short, int, and long could all be 64 bits | | Data General Nova | 16 bits | Word-addressed; byte pointers had a different representation than word pointers | | Intel 8086 | 16 bits | Segmented memory; near and far pointers |
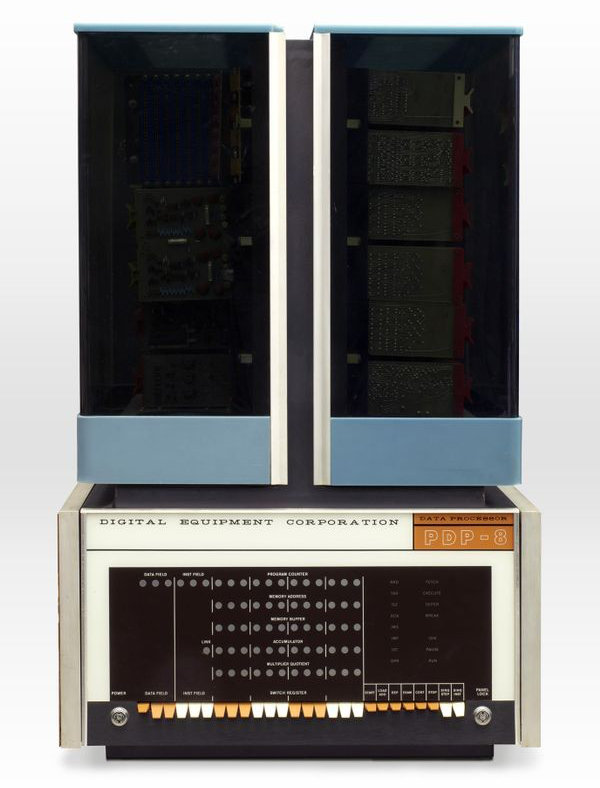
DEC's PDP-8 minicomputer
Characters weren't consistent either. There were 6-bit character sets, 7-bit ASCII, 9-bit bytes on 36-bit machines, and EBCDIC on IBM mainframes. Negative numbers could be stored as two's complement, ones' complement, or sign-magnitude. Some machines could address individual bytes. Others could only address whole words, so a "pointer to a character" had to be a word address plus an offset.
A language that wanted to be both efficient and portable across these machines couldn't assume much.
Where C's Types Came From
C's integer philosophy makes more sense once you look at its ancestors.
BCPL (Martin Richards, 1967) and B (Ken Thompson, around 1969) were typeless languages. There was only one kind of value: the machine word. A variable held a word. You could treat it as an integer, an address, or a bit pattern depending on the operator you applied. On the word-addressed machines these languages targeted, that was elegant and efficient.
Then Bell Labs got a PDP-11. The PDP-11 was byte-addressed, with 16-bit words, and was about to get floating-point hardware. Dennis Ritchie describes in The Development of the C Language (1993) how badly B's "everything is a word" model fit that machine. Handling characters was clumsy, pointers had to be scaled between word and byte addresses, and floating-point values didn't fit in a word.
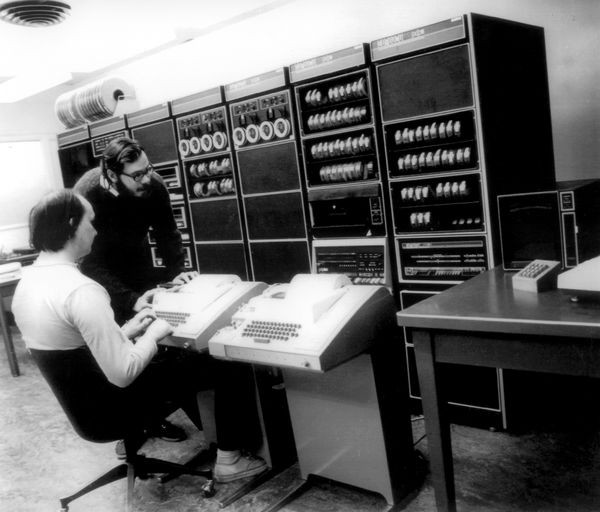
Dennis Ritchie & Ken Thompson working on a PDP-11/20 at Bell Labs.
C's type system was created to fix that mismatch. `char` gave you the byte. `int` kept the spirit of BCPL's word: the natural integer of the machine. That idea became part of the language. Even today, the C standard (C11 §6.2.5) says:
"A 'plain' `int` object has the natural size suggested by the architecture of the execution environment."
This is a deliberate design statement. `int` was never meant to be "32 bits". It meant "whatever this machine is fastest and most comfortable with".
C Escapes the PDP-11
The real test came in 1977 and 1978, when Ritchie and Steve Johnson ported UNIX and C to the Interdata 8/32, a 32-bit machine that was quite different from the PDP-11. They wrote about it in Portability of C Programs and the UNIX System (Bell System Technical Journal, 1978). Around the same time, Johnson's Portable C Compiler (pcc) made retargeting C to new architectures practical, and C spread to a wide range of hardware.
The first edition of The C Programming Language (Kernighan & Ritchie, 1978) includes a table I like to point people to. It lists the type sizes on four machines C already ran on:
| Type | DEC PDP-11 | Honeywell 6000 | IBM 370 | Interdata 8/32 | | ------ | ---------- | -------------- | ------- | -------------- | | char | 8 bits | 9 bits | 8 bits | 8 bits | | short | 16 | 36 | 16 | 16 | | int | 16 | 36 | 32 | 32 | | long | 32 | 36 | 32 | 32 | | float | 32 | 36 | 32 | 32 | | double | 64 | 72 | 64 | 64 |
In 1978 C already ran on machines with 16-bit ints, 32-bit ints, and 36-bit ints, with 8-bit and 9-bit chars. The flexible sizes were there from the start, and they worked. The same language, and largely the same programs, ran natively and efficiently on all of these machines.
Why Flexible Sizes Were Useful
Suppose C had required `int` to be exactly 32 bits, two's complement, wrapping on overflow, the way many modern languages do. Here is what that would have cost.
##### 1. On a 16-bit Machine (PDP-11, 8086)
Every `int` operation would need two machine instructions instead of one. Adding two 32-bit values on a PDP-11 means an `ADD` on the low words followed by an `ADC` (add with carry) on the high words. Comparisons, shifts, and multiplications all get worse. Every array index and every loop counter would cost twice the registers and twice the instructions.
int i;
for (i = 0; i < n; i++) {
  total += table[i];
}
With a "natural" `int`, this loop compiles to single-register operations on a PDP-11, an IBM 370, a Honeywell 6000, or a Cray. With a mandated 32-bit `int`, the PDP-11 version is roughly twice as slow, and the PDP-11 was the machine C was written for.
##### 2. On a 36-bit Machine (PDP-10, Honeywell, UNIVAC)
A fixed 32-bit `int` is arguably worse here, because the hardware is bigger than the type. To keep exact 32-bit wraparound, the compiler would have to mask after nearly every arithmetic operation:
/ what "a = a + b" would need to become for exact 32-bit semantics /
a = (a + b) & 0xFFFFFFFF;
/ ...plus manual sign-extension from bit 31 if a is signed /
That's extra instructions on every add, subtract, and multiply, and 4 bits wasted in every word. Letting `int` be 36 bits costs nothing.
##### 3. On a Ones'-Complement Machine (UNIVAC 1100 / Unisys 2200, CDC 6600)
If the language required two's-complement wraparound, every signed operation on a ones'-complement machine would need software emulation. C avoided this by allowing all three signed representations (two's complement, ones' complement, sign-magnitude) and by making signed overflow undefined behavior.
Note: People today often read that undefined behavior as a gift to optimizers. It started as a way of not forcing one machine's overflow behavior onto every other machine.
##### 4. On Machines Without 8-bit Bytes (CDC, PDP-10, Word-Addressed DSPs)
C requires `char` to have at least 8 bits (`CHAR_BIT >= 8`), not exactly 8. On a 36-bit machine, 9-bit chars pack four to a word with nothing left over. On a machine that can only address whole words, `char` can simply be the word.
This is also why C never promised that all pointers have the same representation. On the Data General Nova, a `char ` and an `int ` pointing to the same place held different bit patterns. C's rules on pointer conversion (and the need for `void *` and explicit casts) exist because of machines like that.
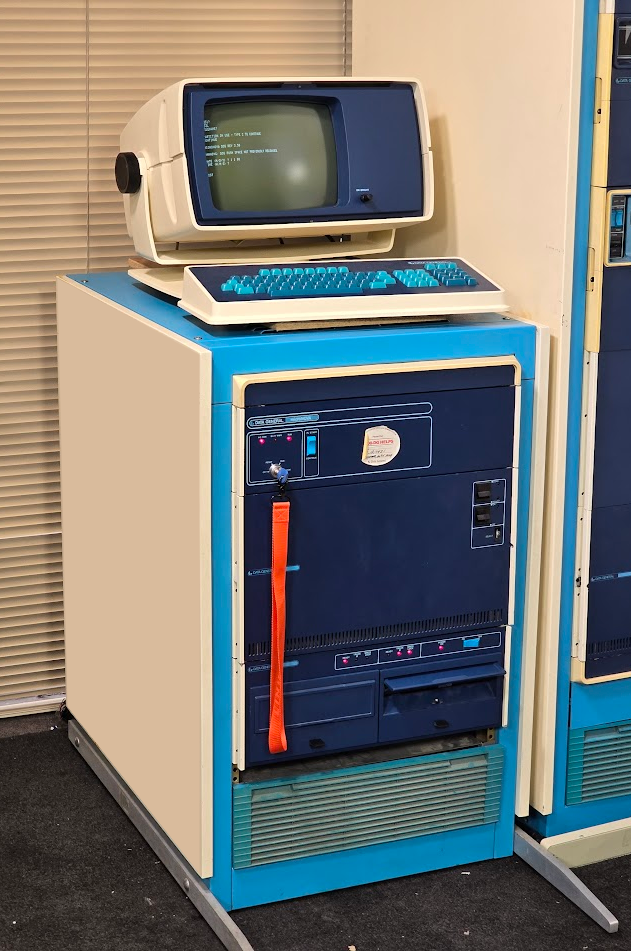
Data General Nova minicomputer
##### 5. On Small 8-bit Micros (Z80, 6502, 8080)
C doesn't let `int` be as small as the machine's 8-bit registers. The standard sets a minimum range of -32767 to 32767, so `int` must be at least 16 bits. This shows the balance the design struck: the size adapts to the machine, but there is a floor so programs can rely on something.
##### The Design Pattern: Minimums, Not Exact Sizes
When ANSI standardized C in 1989, it wrote this philosophy down. You don't get exact sizes, you get guaranteed minimum ranges, exposed through `<limits.h>`:
| Type | Minimum guaranteed | | --------------- | ----------------------- | | char | 8 bits (CHAR\_BIT >= 8) | | short | 16 bits | | int | 16 bits | | long | 32 bits | | long long (C99) | 64 bits |
A portable C program asks "what's the smallest type guaranteed to hold my range?", not "what type is exactly N bits?". If you need values up to 100,000, you use `long`, because `long` is guaranteed to hold them everywhere. If your values fit in ±32767, `int` is fine and will be the fastest choice on every machine.
The ANSI C Rationale summed up the "spirit of C" in a few principles, and two of them apply directly here:
C tried to be portable and fast by letting each implementation map the language onto its hardware in the cheapest way possible. That's a trade-off... not a blunder.
A Case Study in Portable C: Lua
If you want to see this philosophy used well in a modern repository, you should check out the Lua source code. Lua runs on everything from 64-bit servers to microcontrollers and old/unusual toolchains. Lua is written in what its authors call "Clean C", which is the common subset of ANSI C (C89). For a long time, Lua avoided depending on `<stdint.h>` entirely, and it still follows the older approach:
Ask the compiler what it has, using <limits.h>, and choose types based on guaranteed ranges.
Here are a few examples from Lua 5.4:
##### Detecting Whether int is Big Enough, Without int32\_t
In luaconf.h:
/*
@@ LUAI_IS32INT is true iff 'int' has (at least) 32 bits.
*/
#define LUAI_IS32INT	((UINT_MAX >> 30) >= 3)
This is pure C89. It doesn't ask "is int exactly 32 bits?", because on a 36-bit machine that would be the wrong question. It asks "does unsigned int hold at least 32 bits of range?". It works on 16-bit, 32-bit, 36-bit, and 64-bit ints alike.
##### VM Instructions: "At Least 4 Bytes", Not "Exactly 4 Bytes"
In llimits.h:
/*
** type for virtual-machine instructions;
** must be an unsigned with (at least) 4 bytes (see details in lopcodes.h)
*/
#if LUAI_IS32INT
typedef unsigned int l_uint32;
#else
typedef unsigned long l_uint32;
#endiftypedef l_uint32 Instruction;
The type is named `l_uint32`, but look at the comment: it only needs to be at least 32 bits. On a 16-bit-`int` machine it falls back to `long`, which the standard guarantees is at least 32 bits. The instruction decoder in `lopcodes.h` extracts fields with shifts and masks, so any extra high bits on wider machines are simply ignored.
##### Small Numbers and Memory Counts
/ chars used as small naturals (so that 'char' is reserved for characters) /
typedef unsigned char lu_byte;
typedef signed char ls_byte;
Lua uses `unsigned char` where a modern codebase would write `uint8_t`. That's correct everywhere, including on machines where a byte is 9 or 16 bits. `uint8_t` wouldn't even exist on those machines.
The memory accounting types follow the same pattern: `size_t`/`ptrdiff_t` when `int` is 32 bits or more, and `unsigned long`/`long` on 16-bit machines where `size_t` might be too small to count total memory usage.
##### Choosing lua\_Integer From What the Platform Offers
Lua's integer type is configurable in `luaconf.h` (`LUA_INT_INT`, `LUA_INT_LONG`, `LUA_INT_LONGLONG`), with a `LUA_32BITS` option for small targets:
#if defined(LUA_32BITS)		/ { /
/*
** 32-bit integers and 'float'
*/
#if LUAI_IS32INT  / use 'int' if big enough /
#define LUA_INT_TYPE	LUA_INT_INT
#else  / otherwise use 'long' /
#define LUA_INT_TYPE	LUA_INT_LONG
#endif
#define LUA_FLOAT_TYPE	LUA_FLOAT_FLOAT
The default uses `long long` when the compiler provides it (checked via `LLONG_MAX`) and falls back to `long` for strict C89 compilers that don't.
##### Binary Serialization With CHAR\_BIT
The most instructive example may be `string.pack` and `string.unpack` in lstrlib.c. They read and write binary integers byte by byte, and they don't assume a byte is 8 bits:
/ number of bits in a character /
#define NB	CHAR_BIT/ mask for one character (NB 1's) /
#define MC	((1 << NB) - 1)
Integers are packed by repeatedly taking `n & MC` and shifting right by `NB`. Endianness is handled explicitly in the code instead of by casting a pointer and hoping. This is how you write binary I/O that works on any conforming C implementation.
"No fixed-size types" doesn't mean "no control over sizes". You express what you need (a range, a minimum width, a byte), check it with `<limits.h>`, and let the implementation choose the most efficient type that satisfies it.
This is the discipline C's design expected from programmers.
Being Fair: What Hurt
I don't want to pretend flexible sizes came free. Some pain points are real:
People didn't write code the way Lua does. Much C code assumed `int` was 16 bits (in the DOS era) or 32 bits (later), assumed `sizeof(int) == sizeof(void )`, or stored pointers in `int`s. Moving to 32-bit and then 64-bit machines broke that code. The language allowed portability but didn't enforce it.
Even `<stdint.h>` kept C's original philosophy. The exact-width types (`int8_t`, `uint32_t`, etc.) are optional: an implementation provides them only if it actually has a type of that exact width with no padding bits and two's-complement representation. The mandatory types are `int_least32_t` ("the smallest type with at least 32 bits") and `int_fast32_t` ("the fastest type with at least 32 bits"). These are the ANSI minimum-range idea with clearer names. The committee still refused to pretend every machine has an 8-bit byte.
Note: This isn't just history. Many DSPs still in production today have a `CHAR_BIT` of 16 or 32 (some TI and Analog Devices parts, for example), and C compilers exist for the 36-bit, ones'-complement Unisys 2200 line. On those systems `uint8_t` doesn't exist, and code written like Lua's still compiles and runs.
How Modern Languages Differ (and Why They Can)
Languages designed from the 1990s onward had a different starting point. The architecture wars were over. The 8-bit byte, byte-addressable memory, and two's-complement arithmetic had effectively won. Designers could build those assumptions into the language:
The last three points are telling. Even modern languages kept the idea of a natural, platform-sized integer: Rust's `isize`/`usize`, Go's `int`, Swift's `Int`, Zig's `usize`. The concept didn't go away. It narrowed from "the machine's natural word" to "the size of a pointer", because indexing memory is where word size still matters.
C's core intuition turned out to be correct. Modern languages kept it and pinned down everything else.
Even C has followed the hardware's convergence. C23 finally requires two's-complement representation for signed integers (C++20 did the same). The committee could do this in the 2020s because the ones'-complement and sign-magnitude machines that justified the old rule had become extremely rare. That's the right order of events: the standard followed reality once reality had settled.
Portability Is Not Always a Requirement
Keep also in mind that some projects do not require extreme portability. For example, when we write C in our PlayStation Programming course, we know exactly what the target machine is! There's no guessing sizes. The CPU is always the MIPS R3000, the memory alignment is always the one required by the MIPS RISC CPU, the compiler we use is the one provided by the original Sony SDK, and we always know with absolute certainty how big are our `int`s, `short`s, and `long`s.
PlayStation Programming lectures at pikuma.com.
A lot of the C code we write in our projects follows exactly this reality. In cases like this, it does not hurt to simply rely on the native C types.
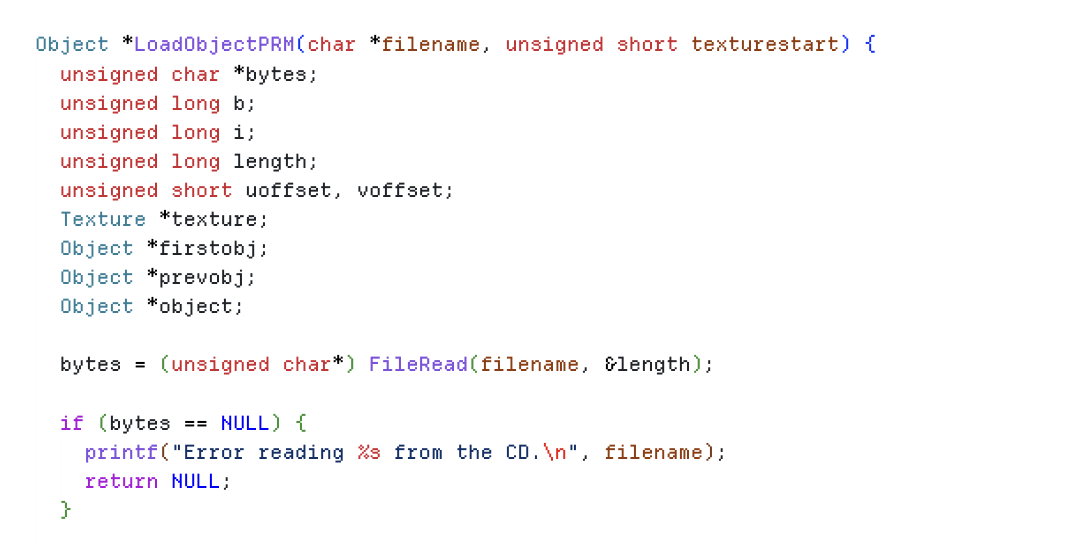
Given that this project is being designed to run exclusively on the original PlayStation console, every programmer working on this project should know exactly the number of bytes that each one of those integer types hold.
Unless, of course, you decide to use the same C code when porting the game to other platforms. Which was exactly what happened with Wipeout's PS1 source code when Psygnosis ported the game to DOS and Windows PC. 😂
Conclusion
A design decision should be judged by the problem it was solving and the world it was made for. C's problem in the 1970s was to be a systems language that could replace assembly on machines with 12, 16, 18, 24, 32, 36, 48, 60, and 64-bit words, with 6, 7, 8, and 9-bit characters, and with three different ways of representing negative numbers, while still generating code nearly as good as hand-written assembly.
Fixed integer sizes would have made C slow or impractical on many of those machines. Leaving the sizes open, backed by guaranteed minimum ranges, made C run nearly everywhere. That's a big part of why UNIX could be ported, and a big part of why C became the language nearly all later systems software was built on.
If you know for sure you'll only target modern 64-bit, 8-bit-byte, two's-complement machines, use a language designed for that world, or use `<stdint.h>` in C. But if, like me, you still write code for old and unusual machines, C's flexible integers are still doing the job they were designed for.
It wasn't a mistake. Portability was the whole point!
##### Further Reading
---