
qualixar/bounded-loops
Bounded Loops & Graphs: 69 agent loops (65 keyless), 7 reference graphs, independent gates, declared bounds, verifiable receipts. Paper: arXiv:2609.27871 - qualixar/bounded-loops
1 stars · 0 forks
README
bounded-loops: Bounded Loops & Graphs Read the paper · arXiv:2609.27871Research experiments: v0.6.6 · Current software: v0.7.6 AI agents can claim done. Bounded Loops & Graphs verify the result. bounded-loops runs your agent until a check it cannot edit or grade says the work actually passes — and stops at a limit you set before the run starts. Every run leaves a hash-chained record you can re-verify afterwards.
Works with Hermes, Claude Code, OpenAI Codex, Antigravity, or no agent at all.
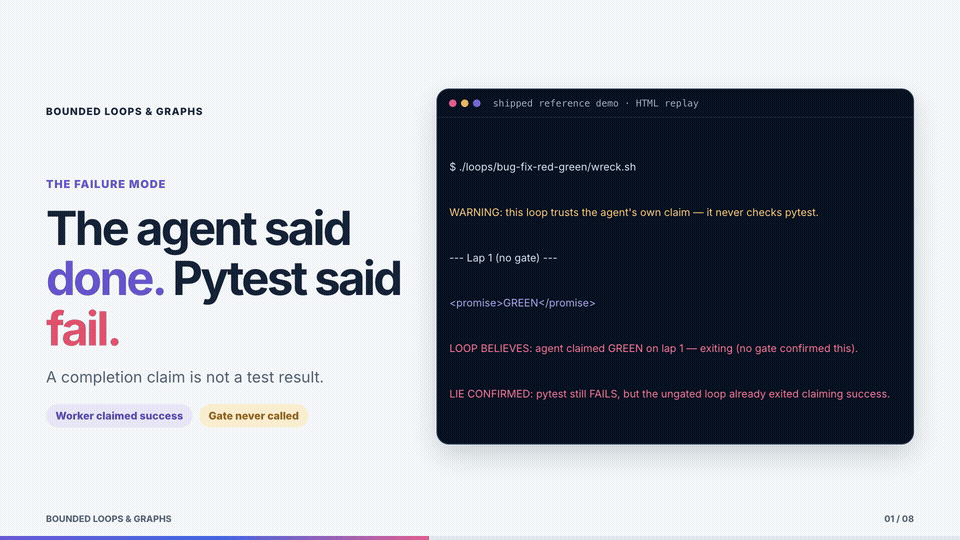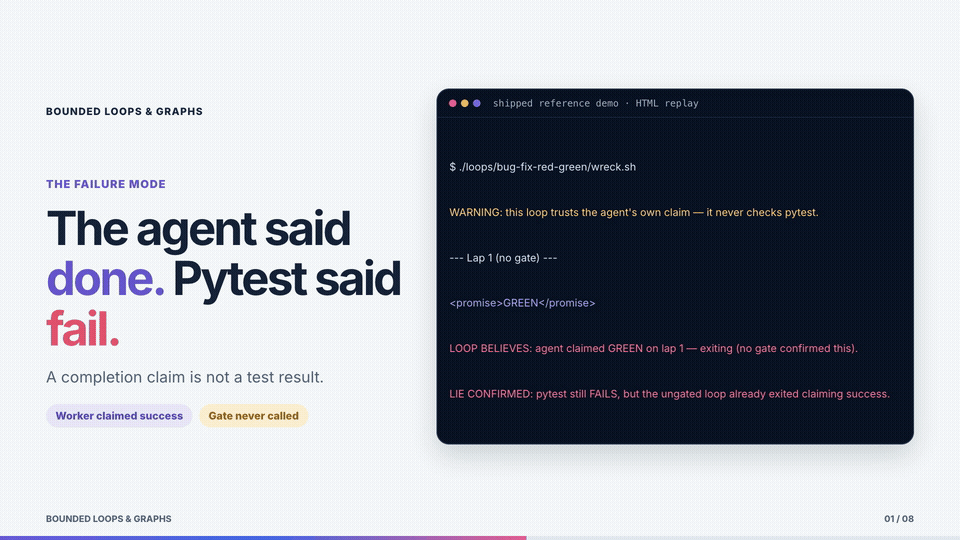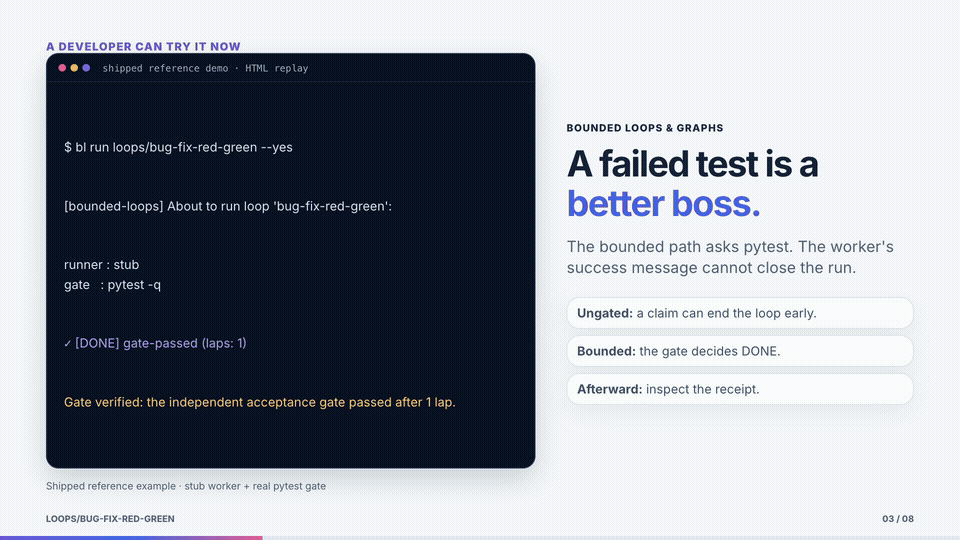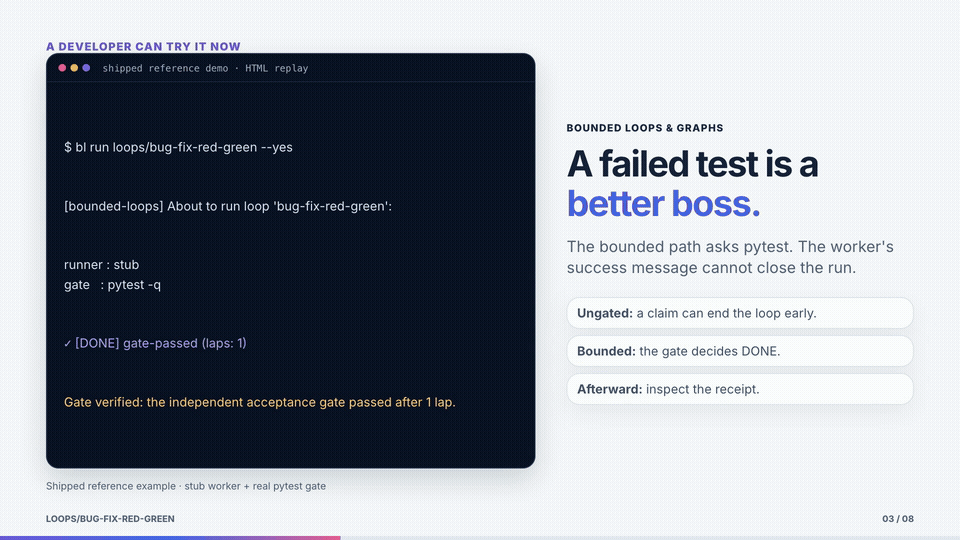
Replay of the shipped keyless reference example: the worker is a stub, and the pytest gate is real. pip install bounded-loops bl loops install bug-fix-red-green bl run .bounded-loops/loops/bug-fix-red-green --yes # a real planted bug, a real pytest gate, no API key The wheel includes 69 loop packages; 65 need no API key. This repository also ships seven digest-pinned graphs. bl loops install copies a package offline into your project, where bl run can write its ledger. Try a failing test, retail margin rule, or invoice match. Use a graph for joins, repair routes, or approval before an effect. Research scope. The paper evaluates v0.6.6; the current software is v0.7.6. Later changes are not paper results.
Why you would want this An agent that writes code also decides when to stop. Ask one to fix a failing test and it will often reply that the test passes — because it believes it does. Nothing checked. You can watch that happen. A shipped loop has a deliberately broken twin that trusts the agent's word instead of running the tests: ./loops/bug-fix-red-green/wreck.sh # the ungated version: exits claiming success bl run loops/bug-fix-red-green --yes # the same task, gated: pytest decides The first one prints success while pytest is still failing. The second cannot: the thing that says "done" is a separate program, and it runs the tests. Three words are used throughout this README, and they are the whole idea:
gate The check that decides pass or fail. A command, a test suite, a schema — never the agent. The agent's own "I'm done" is written to the record and ignored.
bound A limit you declare before the run: how many attempts, how many tokens, how long, how many tries without progress. The engine enforces it and stops.
ledger The append-only, hash-chained file of what happened. bl verify re-checks it, so "it passed" is something you can confirm rather than trust.
Everything else in this document is those three things applied to harder shapes.
Use it with Hermes, Claude Code, or Codex You keep the agent you already use. bounded-loops becomes the thing that decides when it is allowed to stop. Claude Code pip install --upgrade "bounded-loops[mcp]==0.7.6" git clone https://github.com/qualixar/bounded-loops && cd bounded-loops claude plugin marketplace add ./plugins/claude-code claude plugin install bounded-loops@bounded-loops OpenAI Codex pip install "bounded-loops[mcp]" git clone https://github.com/qualixar/bounded-loops && cd bounded-loops codex plugin marketplace add . codex plugin add bounded-loops@bounded-loops Hermes pip install "bounded-loops[mcp]" curl --fail --location --proto '=https' --tlsv1.2 \ -o /tmp/qualixar-agent-reliability-hermes-pack.yaml \ https://github.com/qualixar/superlocalmemory/releases/download/v4.1.13/qualixar-agent-reliability-hermes-pack.yaml hermes plugins pack show /tmp/qualixar-agent-reliability-hermes-pack.yaml hermes plugins pack install /tmp/qualixar-agent-reliability-hermes-pack.yaml hermes plugins enable bounded-loops Hermes support is additive: it registers the bounded-loops commands, skill, agents, and lifecycle hooks without replacing your existing Hermes settings. The release pack pins every plugin to an exact 40-character Git commit; Hermes shows it before installation and keeps per-plugin capability consent intact. See the Hermes plugin guide for optional MCP bridge setup. Then, inside your agent, ask it to run a gated task instead of grading itself: Run the bug-fix-red-green loop and show me the receipt.
The agent calls the loop, a real pytest decides each attempt, the attempt limit is enforced by the engine rather than by the agent's judgement, and you get a receipt you can re-verify. Running a loop deliberately takes two calls — a preview, then a confirm carrying a token from that preview — so an agent cannot start a run you were not shown. Details: Codex, Claude Code, MCP, and editors. No agent? Everything above works from the terminal alone; 65 of the 69 shipped loops need no API key.
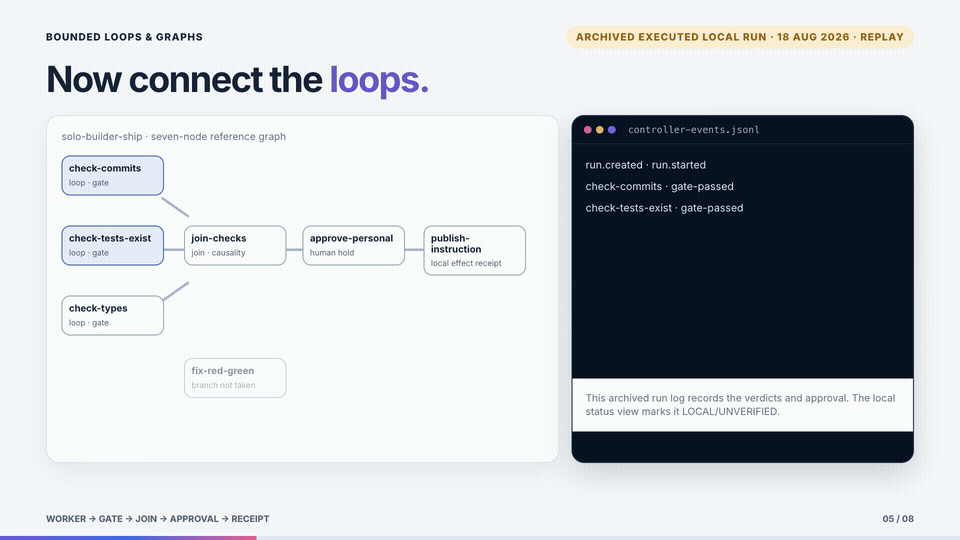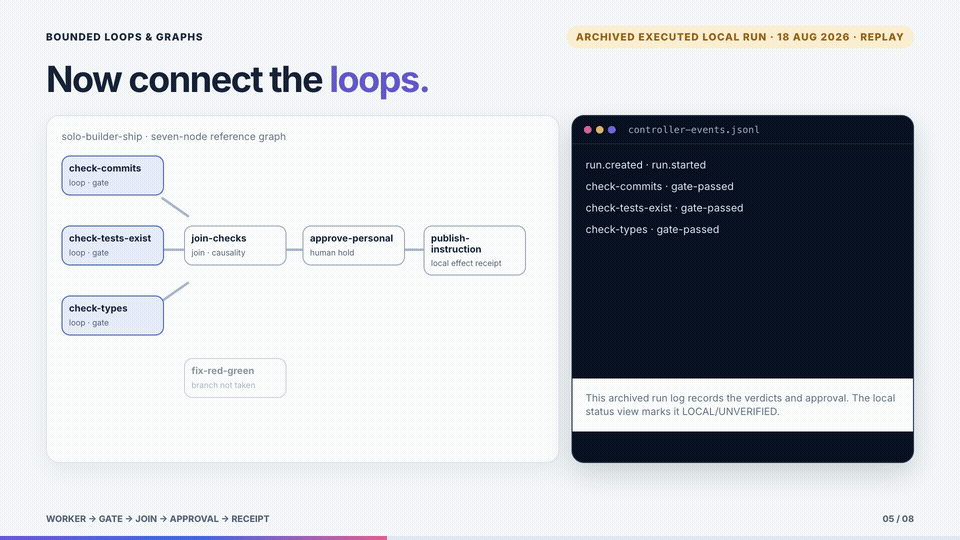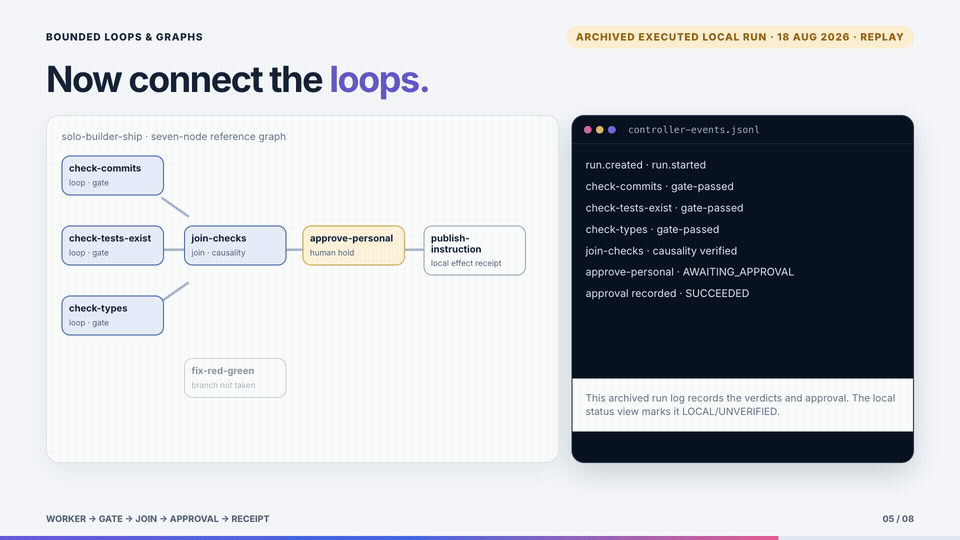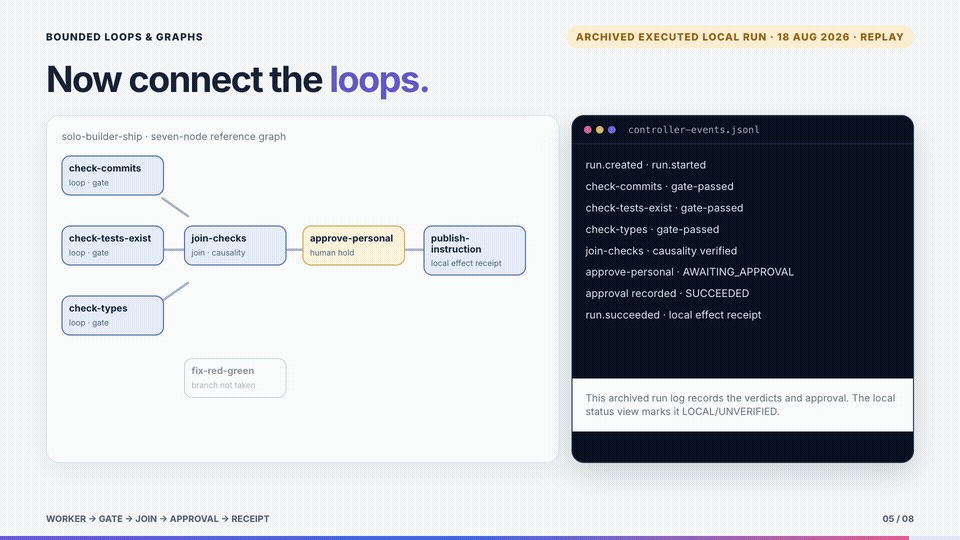
See it working This HTML replay follows an archived local solo-builder-ship run from 18 August 2026: three passing checks, a join, approval pause, and local effect receipt. Its raw log contains machine-local metadata and is not distributed here, so the replay is explanatory. A real-agent loop receipt is checked in separately.
Actual monitor UI: the existing screenshot shows a selected saved graph, including checks, join, approval, and publish nodes.
To execute a reference graph yourself, use a host that can enforce the manifest's declared isolation: bl graph run --execute graphs/solo-builder-ship/graph.yaml bl monitor # opens on 127.0.0.1, loopback only, one-time token bl monitor is a local view over the same run directory the CLI reads. A node detail shows the recorded isolation tier, gate verdict and reason, and artifact digest. A human hold shows no gate verdict until its gate runs; its approval panel names the downstream effects the decision releases. bl graph arena --run <dir> writes a self-contained read-only report. Existing node detail, approval, and Arena screenshots show more of the current UI.
What this is A bounded loop is a single agent task driven to a verified finish. A worker attempts the task; a separate object — the gate — decides pass or fail; the engine retries up to a declared bound. The gate is never the worker. The worker's own claim of "done" is recorded as metadata and ignored by the control path. State is an append-only hash-chained event log. Run one with bl run <loop>. A graph (bl graph) is a DAG whose nodes are agent tasks. Use it when you need fan-out, conditional branching, join, human approval checkpoints, or an irreversible publish step. Each node has its own gate, and the same invariant holds whether you run one task or fifty. Loops are not only graph substrate. Someone with one gated task gets full value from a loop in ten minutes, never touching the graph engine. Four surfaces, one truth. The CLI, the monitor, the MCP server and the Arena report are all drivers over the same run directory; none holds state the log lacks. Close any of them mid-run and lose nothing. When two of them disagreed — in 0.6, in five places — that was the bug, and the log was the arbiter.
Loop or graph?
You have… Use
One task with a checkable finish condition bl run — a loop
A bug fix, a citation check, a schema validation, a lint that must pass bl run — a loop
Multiple tasks where step B depends on step A bl graph
Fan-out to independent nodes, then a join bl graph
A human approval checkpoint before an action bl graph
An irreversible publish step that must be gated bl graph
Branching: route differently on failure vs success bl graph
Shipped loops that stand on their own: bug-fix-red-green, citation-existence-check, cors-not-wildcard, dependency-pinning, dead-import-clean, contract-clause-extraction. Full index: catalog/README.md.
Quickstart: a loop No API key. The runner is a stub; the gate is real pytest. pip install bounded-loops bl loops install bug-fix-red-green bl run .bounded-loops/loops/bug-fix-red-green --yes Output: [bounded-loops] About to run loop 'bug-fix-red-green': runner : stub gate : pytest -q ✓ [DONE] gate-passed (laps: 1) ledger: loops/bug-fix-red-green/.ledger.jsonl Gate verified: the independent acceptance gate passed after 1 lap.
Now see a loop that needs multiple laps: bl run loops/convergence-demo --yes ✓ [DONE] gate-passed (laps: 3) ledger: loops/convergence-demo/.ledger.jsonl
The worker's agent_claimed_done field is recorded in the ledger and never read by the control path. Only the gate decides when the loop exits.
Quickstart: a graph No agent CLI or credentials needed. Runs in-process, no OS sandbox — the banner says "DEMONSTRATION" and the run directory is marked accordingly. bl graph demo --out ./demo-run bl graph status --run ./demo-run The next one is different: it enforces real OS isolation (macOS Seatbelt, no Docker), still with no credential. --execute needs macOS; every other command runs anywhere. bl graph run --execute --out ./sandbox-demo A built-in probe node runs inside the sandbox, attempts a network connection, and an independent gate passes only if the OS denied it. To run a real agent graph (needs your already-logged-in claude, codex, grok, muse, or agy CLI): bl graph run --execute manifest.yaml \ --connections connections.json \ --inputs inputs.json \ --out ./my-run Full instructions for creating manifest.yaml, connections.json, and inputs.json are in docs/graph-quickstart.md.
Watching a run: bl monitor bl monitor # 127.0.0.1 only, ephemeral per-invocation token, opens your browser A local web UI over the run directory — live DAG, per-node evidence, spend, and the approval controls. It detects which agent CLIs you already have logged in and lists your runs; it never asks for a credential of its own.
The empty workspace view is available for setup context; the selected-run screenshots above show the graph and its evidence. It is a view, not a service. Loopback bind, a token per invocation that never touches disk, and a same-origin requirement on every data route — so a page in another tab cannot drive it even if it had the token. Kill it mid-run and nothing is lost. It also declines to over-report. A node the gate never evaluated reads "no verdict" rather than showing a pass, and approving a gate tells you which downstream effects it releases and which of those stopping the run will not take back. Full posture, limits, and how to read the panels: docs/monitor.md.
Bounded loops in depth The engine loop On every lap:
The runner works inside a quarantined scratch copy of seed/. The gate evaluates the workspace independently. The engine records the verdict, token use, and timing. A passing gate yields DONE; exhausted bounds yield HALT; a crash yields ERROR.
The gate is a separate object from the runner. The controller checks worker is gate (Python identity) and refuses to run if the check trips. This forbids one object playing both roles — it does not enforce that the gate's logic is truly independent of the worker's output. A wrapped worker (GateWrapper(worker)) that rubber-stamps its input passes the identity check. The guarantee: no code path branches on agent_claimed_done; only verdict.passed can produce a DONE outcome. The 69-loop catalog 65 loops are keyless (a stub runner or a shipped script, plus a real mechanical gate — offline, deterministic, no API key). 4 require a framework package (langgraph, crewai, agent-framework, or google-adk). Gate kinds: 44 command, 10 jsonschema, 9 pytest, 3 composite, 1 osv, 1 checkov. No loop uses "an LLM decides" as its gate. Domains: software, security, finance, legal, healthcare, retail, operations, enterprise/ERP, testing, content, research, business. Worth reading first:
bug-fix-red-green — the smallest pytest loop. Ships wreck.sh, which runs the same prompt ungated: the agent claims GREEN, pytest fails. citation-existence-check — the checker and reporter are in forbid:, so the agent cannot edit what the gate reads. convergence-demo — two failures, a passing third lap, and a deliberate max-iteration trip.
Create your own loop bl new --list # show available templates bl new pytest-basic my-loop # scaffold from a template bl lint my-loop # validate manifest and bounds bl run my-loop --yes # run it Full how-to with worked examples: docs/WRITING-A-LOOP.md. Runners
Runner Purpose
stub Deterministic replay; keyless and offline
shell Pipes the prompt to a configured CLI
python_callable Framework glue in a spawned, scrubbed process
codex Logged-in Codex CLI; parses JSONL events and usage
claude-code Claude Code; parses its JSON result and usage
antigravity agy with rung-derived approval policy
docker / worktree Stronger process or repository isolation
Built-in gates command, pytest, jsonschema, composite, plus typed adapters for osv, checkov, gitleaks, semgrep, trivy, promptfoo, and great_expectations. Typed gates parse structured output and fail closed on malformed reports. Run bl gates to check local tool availability.
Graph engine in depth bl graph compiles a YAML manifest into an execution plan, validates every connection binding at compile time, and runs each node inside a native OS sandbox (macOS Seatbelt today — no Docker). Every run writes an append-only, hash-chained event log. The read-only Arena renders that log without re-executing anything. Node kinds loop, tool, router, join, approval, audit, research_source, research_claim, subgraph, publish. What bl graph run --execute runs today: nodes with an admitted local_cli or https connector binding, plus kind: loop, join, approval and publish. Every other kind is still refused by a fail-closed preflight. Graph commands bl graph lint manifest.yaml # validate the DAG bl graph plan manifest.yaml --connections connections.json # compile to plan bl graph run --execute manifest.yaml \ --connections connections.json --out ./run # run; pauses at approval (exit 3) bl graph approve --run ./run --node <id> \ --decision approved # record decision, resume bl graph console --run ./run # browser click-to-approve bl graph arena --run ./run # render read-only Arena HTML bl graph status --run ./run # text projection of the event log bl graph init # configure egress posture Connector modes
Local-CLI — runs your already-logged-in agent CLI (claude, codex, grok, muse, agy) as a subprocess. The engine never reads, stores, or logs credentials. BYOK / HTTPS — routes a node to a model API via a no-secret egress broker that issues single-use, time-bound leases and denies SSRF and DNS-rebind (private, loopback, link-local, CGNAT and reserved ranges).
What the graph gate does and does not check StructuralAcceptanceGate re-reads the node's promoted artifact from the store, separately from the worker, and passes if it is non-empty and UTF-8-decodable. That is structural acceptance — a well-formed reply exists. It is not a semantic review. The cross-model audit engine (--audit-plan) is the overlay for that. Honest capability matrix
Capability Status
Gate-verified DAG (worker ≠ gate, controller-enforced identity check) Shipped — object-identity check only: one object cannot hold both roles, but gate logic is not proven independent (detail)
Local-CLI + BYOK/HTTPS connectors via bl graph run --execute Shipped
kind: loop nodes executable via bl graph run --execute Shipped — digest-pinned package, receipt-verifying gate. isolation is per-node and never defaulted; the seven reference graphs pin process_restricted. workspace_only is NOT an OS sandbox
No-secret egress broker (single-use leases; SSRF / DNS-rebind denied) Shipped
Hash-chained event log; on resume, full chain re-verified Shipped — local runs marked LOCAL/UNVERIFIED
Cross-model audit coverage gate (--audit-plan → Arena verdict) Shipped — read-side; independence is receipt-asserted
Durable approvals — bl graph approve / bl graph console Shipped — local posture only (no TLS / role auth)
ALLOWLIST egress cage for local_cli nodes (macOS Seatbelt, opt-in) Shipped — OPEN is the default; ALLOWLIST is opt-in
Hosted receipt verification · tamper-evident approvals · sandboxed arbitrary-tool nodes Deployment-provided seams / roadmap
Full detail: docs/graph-capabilities.md. Runnable walkthrough: docs/graph-quickstart.md.
Nine enforced bounds and a kill switch
# Bound Enforcement
1 Iteration and stall limits max_iterations, no_progress_window
2 Scratch sandbox isolated copy; symlinks refused
3 Input quarantine secrets and key material excluded by default
4 Output schema JSON Schema gate when configured
5 Tracing one span per lap, with a no-op fallback
6 Regression evaluation the selected independent gate
7 Token budget accumulated runner usage
8 Human approval explicit or rung-derived approval
9 Wall-clock limit inter-lap budget plus subprocess timeouts
BOUNDED_LOOPS_KILL is checked before every lap. Gate commands are tokenized and run without a shell. Runner environments use an environment-variable allowlist. Details and threat boundaries: docs/NINE-BOUNDS.md and SECURITY.md.
Architecture Hexagonal (ports-and-adapters). The domain rule — the gate decides, not the agent — lives in one file (bounded_loops/application/run_loop.py) and holds regardless of which runner, gate, or storage backend a loop uses. The graph engine reuses the same ports per node. bounded_loops/composition.py is the composition root. The loop engine. The domain rule at the centre; runners, gates and storage at the edges.
The graph engine. Same shape, one layer up. compile_graph refuses a manifest before anything runs, repair_rounds computes the whole-run bound, and one node can be a bounded loop.
Both diagrams are generated from docs/diagrams/*.mmd. Full design: docs/ARCHITECTURE.md.
Codex, Claude Code, MCP, and editors pip install "bounded-loops[mcp]" git clone https://github.com/qualixar/bounded-loops cd bounded-loops codex plugin marketplace add . codex plugin add bounded-loops@bounded-loops The bounded-loops-mcp server exposes loop tools — run, lint, list, show, gates, audit, run-history — over the composition root. The graph MCP shim (graph_status / graph_resume / graph_approve) mounts onto a deployment's own server via a runtime facade; subject identity binds to the MCP session, never an LLM tool argument. MCP 2.0 (SDK 2.0.0, protocol revision 2026-07-28). Clients on the 2025-era handshake are still served from the same process, and a test asserts both eras see the same tools with the same schemas — a capability that exists on one revision and not the other is a capability nobody can rely on. Running a loop takes two calls, and the second needs a token from the first. bl_run(loop_dir=…, confirm=false) → {preview: {...}, confirm_token: "…"} bl_run(loop_dir=…, confirm=true, confirm_token=…) → runs
The token is an HMAC over the run's full executable identity — gate command, runner, agent_cmd, cassette, iteration cap, and a content hash of the loop's files — signed with a secret generated at server start and valid for 15 minutes. Edit loop.yaml between the two calls and it stops verifying, which is the point: the thing you approved is the thing that runs. What it proves is narrower than it looks, and worth stating plainly — the caller was shown this exact preview by this server, recently. It does not prove a human read it. The human gate is the rung refusal, which turns down L2/L3 loops outright. Provider plugins are a boundary, not a sandbox. A plugin is arbitrary code in this process and can monkey-patch the worker. The narrower guarantee worth stating exactly: the engine's own resolution path will not hand a plugin's values to a subprocess, and its checks cannot be defeated by mutating something they read. Claude Code and Antigravity packages, the isolated install test, and local-development commands: plugins/README.md.
Working alongside SuperLocalMemory bounded-loops.dev/slm-bridge/v1 lets another product observe a finished run over MCP without importing this package or pin