Decisions over large option sets, where the prompt stops scaling.
Memory-driven System 1 for AI agents
Decisions over large option sets, where the prompt stops scaling.
Which intent, product, entity or tool, out of thousands or millions? Does this ticket match a known issue? Does the policy say yes? With a handful of options, prompt an LLM. With too many to list, MahaBodi keeps them in memory, retrieves a shortlist, and decides in one forward pass with Laya's typed decision models, grounded in your documents and labelled past decisions, in one Rust engine (measured so far to 100K candidates; 5.9M loaded in PostgreSQL, results pending).
Get startedSee the benchmarksDownload the one-pager (PDF)
choices · yes/no · routingRust corePython · Node · Java · C# · GoMIT licensedno text generation
From agent to decision
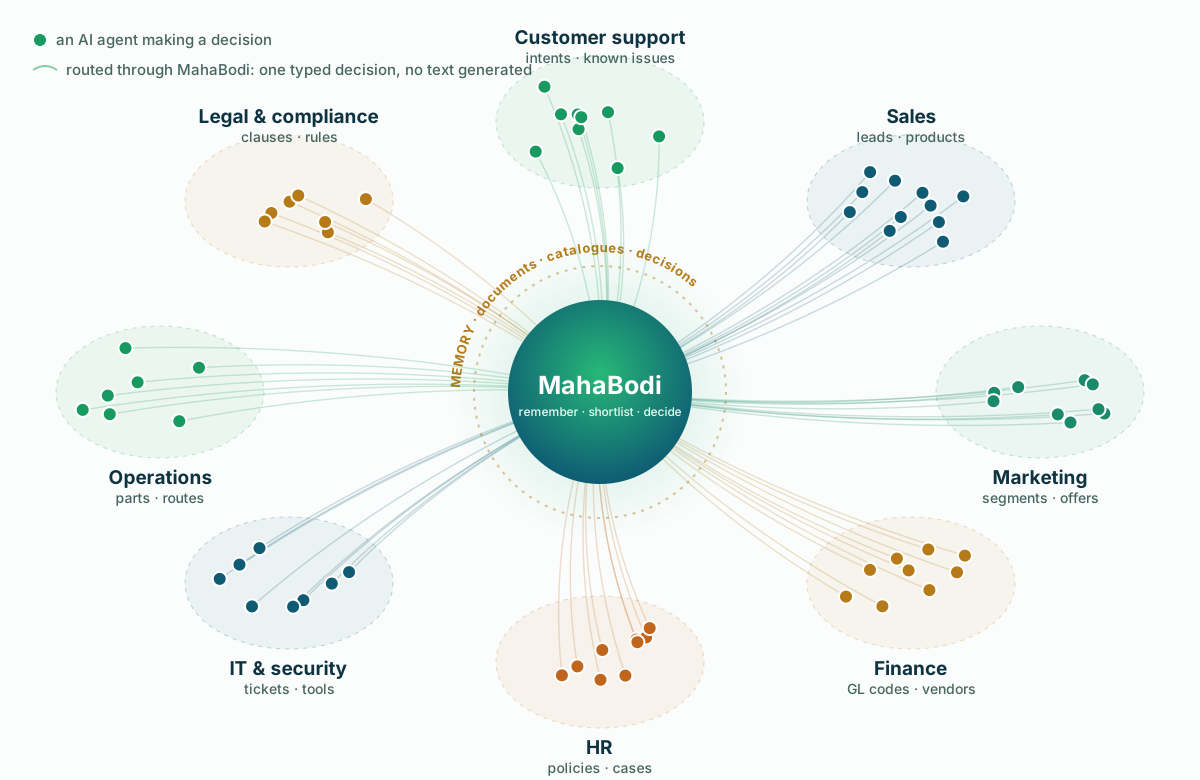
Agents across the business send typed requests. MahaBodi remembers, shortlists and decides in one pass, then sends a typed answer back, and it learns from labelled outcomes without retraining. Illustrative uses; measured results are below.
One tree, four parts
Each part of the tree is a component you can test on its own, and every result below traces back to one of them.
Roots
fastmemory graph
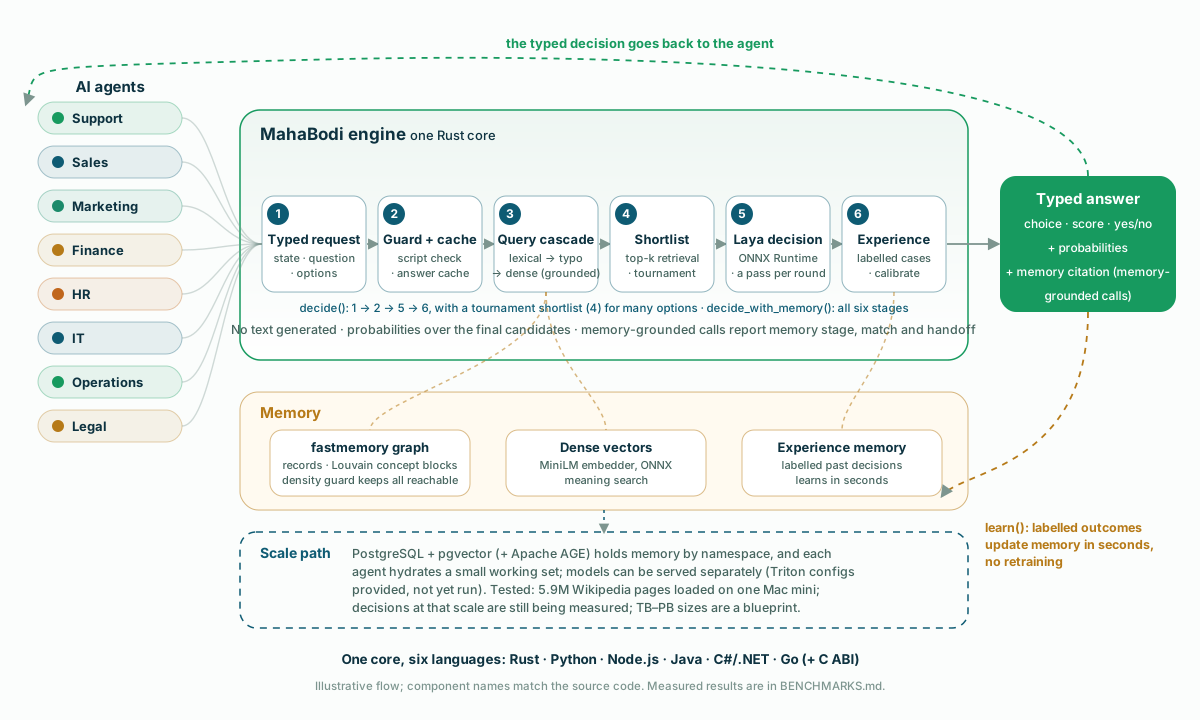
Documents become a topology of actions, data and concepts. A density check keeps every record reachable, and hybrid keyword-plus-meaning search finds it again, even through typos.
Trunk
The MahaBodi engine
One Rust core: a query cascade with handoff flags, tournament shortlisting for many options, experience memory, and a script guard.
Branches
Six languages
The same engine and the same JSON API from Rust, Python, Node.js, Java, C#/.NET and Go, all tested against the real model.
Leaves
Laya decisions
Typed `choice`, `score` and yes/no answers with calibrated probabilities, in one forward pass. Nothing is generated, so nothing needs parsing.
When to use it
The benchmarks point to one rule.
Small fixed label sets (2–77 tested), GPU and labelled data
Fine-tune a classifier
A fully fine-tuned Laya beats MahaBodi on 4 of 6 suites. Where training is affordable and labels are stable, fine-tune.
Small label sets, no training step
MahaBodi, or a plain kNN
MahaBodi learns from labelled cases in seconds on a CPU and is never below Laya as shipped on 5 fresh suites (3 beats, 2 ties). A plain kNN is a strong alternative: at default settings it beats MahaBodi on Banking77 (0.892 vs 0.832; on another fresh sample, the opt-in `calibrate=200` ties kNN at 0.882 vs 0.876).
Thousands to millions of options
What the memory remembers and retrieves
Measured once (AIDA entity linking, 10K–100K pages): a simple remembered prior beat every system, MahaBodi included (0.78 vs 0.18 at 100K). Against Laya with a dense shortlist, MahaBodi tied at 10K and won at 100K through better retrieval. Laya can't read 10,000 options at once. What the memory retrieves and remembers matters more than the decision model.
Measured, not promised
Same machine, same Laya checkpoint on both sides, seeded test samples, and an exact McNemar test on the same items. A result counts as a win only at p < 0.05.
150
intents routed (CLINC150)
0.736 vs 0.708 for Laya with a MiniLM shortlist, the fair baseline (p = 0.027, one run); Laya alone 0.538. Re-tested on fresh items with an out-of-scope gate given to every system: 0.786 vs 0.756 (p = 0.014), out-of-scope recall 72 %.
+16.8 pts
on 77-intent Banking77
0.660 vs 0.492 zero-shot, through tournament shortlisting. It ties Laya's MiniLM-shortlist mitigation.
0.78
BoolQ answered from memory
From 0.42 with the question only, and above always-yes (0.63). Confident errors fall from 45 % to 17 %. The oracle passage reaches 0.85.
| Result | Laya / baseline | MahaBodi | Verdict | | ------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------- | ----------------------------- | ------------------------------------------------------------------------------- | | MASSIVE intent, 51 languages, zero-shot | 0.366 · 45/51 | 0.405 · 47/51 | beat | | CLINC150 re-test on fresh items, same out-of-scope gate for every system | 0.756 (Laya + MiniLM shortlist + gate) | 0.786 | beat (p = 0.014; the gate lifts out-of-scope recall to 68–72 % for all systems) | | Entity linking, 100K candidate Wikipedia pages (AIDA, 1,000 mentions; pre-registered) | 0.121 (Laya + dense shortlist) · Laya alone cannot run | 0.177 | beat (p = 0.0002; a retrieval gain: the deciders tie on the same shortlist) | | Entity linking, 10K candidate pages | 0.387 (Laya + dense shortlist) | 0.384 | tie (p = 0.92) | | Entity linking vs a context-free alias prior (the entity a name usually means), 10K / 100K / 5.9M | prior: 0.800 / 0.784 / 0.772 | 0.384 / 0.177 / pending | loss (the prior beats every context-reading system) | | Against Laya fully fine-tuned on the same 2,000 examples (encoder + head) | Emotion 0.916 · SST-5 0.558 · prompt-inj. 0.974 · Banking77 0.852 | 0.648 · 0.426 · 0.767 · 0.806 | loss on 4 of 6 · tie AG News, BoolQ · Banking77 ties with calibrate=200 | | Against Laya with its head fine-tuned on the same 2,000 examples (fresh items) | Emotion 0.598 · Banking77 0.598 · SST-5 0.530 | 0.648 · 0.806 · 0.426 | beat on Emotion, Banking77 · tie AG News · loss on SST-5 | | CLINC150, 150 intents + out-of-scope, zero-shot | 0.708 (Laya + MiniLM shortlist) · Laya alone 0.538 | 0.736 | beat (p = 0.027, one run; in-scope only: out-of-scope recall 3 %) | | Banking77, 77 intents, zero-shot | 0.492 | 0.660 | beat (ties Laya + MiniLM shortlist) | | Banking77 with 2,000 labelled examples (default settings, fresh items) | 0.462 (zero-shot) | 0.832 | beat (but a plain kNN on the same labels: 0.892, a loss) | | Same, with opt-in calibrate=200 (third fresh sample) | 0.446 · plain kNN 0.876 | 0.882 | beat Laya · ties kNN (p = 0.63); never below Laya or kNN on 5 suites | | Latency, p50, CPU only (one Ubuntu i9-9900X, 8 threads, batch 1) | Laya PyTorch: 165 ms (4 options) · 379 ms (77) | 125 ms · 730 ms | faster on 4 (mostly ONNX Runtime) · 1.9× slower on 77 (tournament) | | Calibration (ECE after the same temperature refit), 6 suites | Banking77 0.159 | Banking77 0.050 | beat on Banking77 only (tournament); tie on 5 | | Experience memory, default settings, 5 suites, fresh items | Laya zero-shot | no suite below Laya | 3 beats, 2 ties | | Laya's near-ties (top-2 within 0.10), Banking77 | 26 % correct | 91 % with labelled memory | beat | | BoolQ answered from memory | 0.424 question only · 0.626 always-yes | 0.782 | beat (oracle passage: 0.846) | | Misspelled keyword search (SQuAD, 300 paragraphs) | BM25: 0.05 recall@5 | 0.61 | beat | | Six other Laya suites (AG News, Emotion, SST-5, …) | \= | \= | tie: exact parity | | Keyword search at 2,000 paragraphs | BM25: 0.684 | 0.660 | loss |
Scorecard against Laya's 10 published benchmarks, zero-shot: 2 beats, 6 ties; all 10 are now measured. Calibration is scored per suite: better on Banking77 only, identical on the other 5. Latency is faster on 4 options (mostly from ONNX Runtime) and slower on 77 (the tournament). Neither counts as a beat. MahaBodi runs Laya's own models: the wins come from how it uses them, not from a new model. Full tables and per-item predictions →
What it does, and what it doesn't
We report ties and losses next to wins. Here is where MahaBodi stands today.
Strong at
- Decisions with many options: 77 and 150 intents, and entity linking over 100K Wikipedia pages, where its retrieval beats a dense shortlist
- Learning from labelled examples instantly, with no retraining
- Grounding decisions in your own documents, with citations
- Typo-tolerant memory search
- One forward pass and zero tokens per decision, however many options
- It is not a new model; on six suites it matches Laya exactly
- Not yet compared with an LLM given every option in its context; the claim is cost and speed, not accuracy
- Out-of-scope detection needs the opt-in similarity gate (off by default): about 72 % recall on fresh CLINC150 items in the benchmark, at some cost to in-scope accuracy. `decide()` reproduces the benchmark exactly (all 1,600 items on Ubuntu with the final build).
- A fully fine-tuned Laya beats it on 4 of 6 small-label suites (e.g. Emotion 0.916 vs 0.648); with a fine-tuned head only, SST-5 is still a loss (0.530 vs 0.426)
- On entity linking, a simple remembered alias prior (0.78) beats every context-reading system, MahaBodi included (0.18 at 100K pages)
- Tool routing across hundreds of tools is planned, not yet measured
- With default settings, a plain kNN beats it on labelled Banking77 (0.892 vs 0.832). The opt-in `calibrate` step closes that gap to a tie by switching to kNN.
- Retrieval can still be confidently wrong on hard, misspelled queries
- 5.9M Wikipedia pages (23M passages) are loaded in the PostgreSQL store on one Mac mini; decisions at that scale are still being measured, and TB–PB is a blueprint (Enterprise)
- Prebuilt packages (0.1.2) for Linux x86\_64 and macOS x86\_64 only, on crates.io, PyPI, npm and NuGet; Java is not on Maven Central
Not yet
Scale it, or build with it
Deploy memory on PostgreSQL + Apache AGE with models on your own GPUs, or start coding in six languages today.