LabBench: Can AI agents decide what experiment to run next?
September 28, 2026 · Ben Reilly, Leah Damon, Daniel McKinnon
LabBench: Can AI agents decide what experiment to run next?
From our preprint, LabBench: Benchmarking AI wet lab experimental design and decision-making for AI Agents (PDF). Partner with us.
Accelerating biological experimentation relies on quickly deciding which experiment comes next. Picking the test that can fastest invalidate or support a hypothesis is a skill only human experts perform reliably today. To scale discovery past human capability, we have to evaluate and improve AI agents on it.
LabBench is 20 held-out tasks built from real wet-lab records in drug discovery and genomics. Each is a snapshot in time: the agent gets the records that existed at a decision point, and the lab’s interpretation and decision are withheld. It must commit to the next step, graded against 20–22 binary criteria tied to what the lab actually decided.
From lab archive to graded task
1. MineFind recorded decisions and their evidence. 2. AssembleGive the records; withhold the decision. 3. Rubric20–22 binary criteria from the true answer. 4. HardenRework tasks a solver passes trivially. 5. ReviewBiologists verify every task.
The tasks come from real lab data unlikely to be recalled from the open internet. We expect the agent to navigate the evidence as a real researcher would, without the brief pointing to what matters.
Results
Five frontier agents each ran once per task in their vendor’s harness.
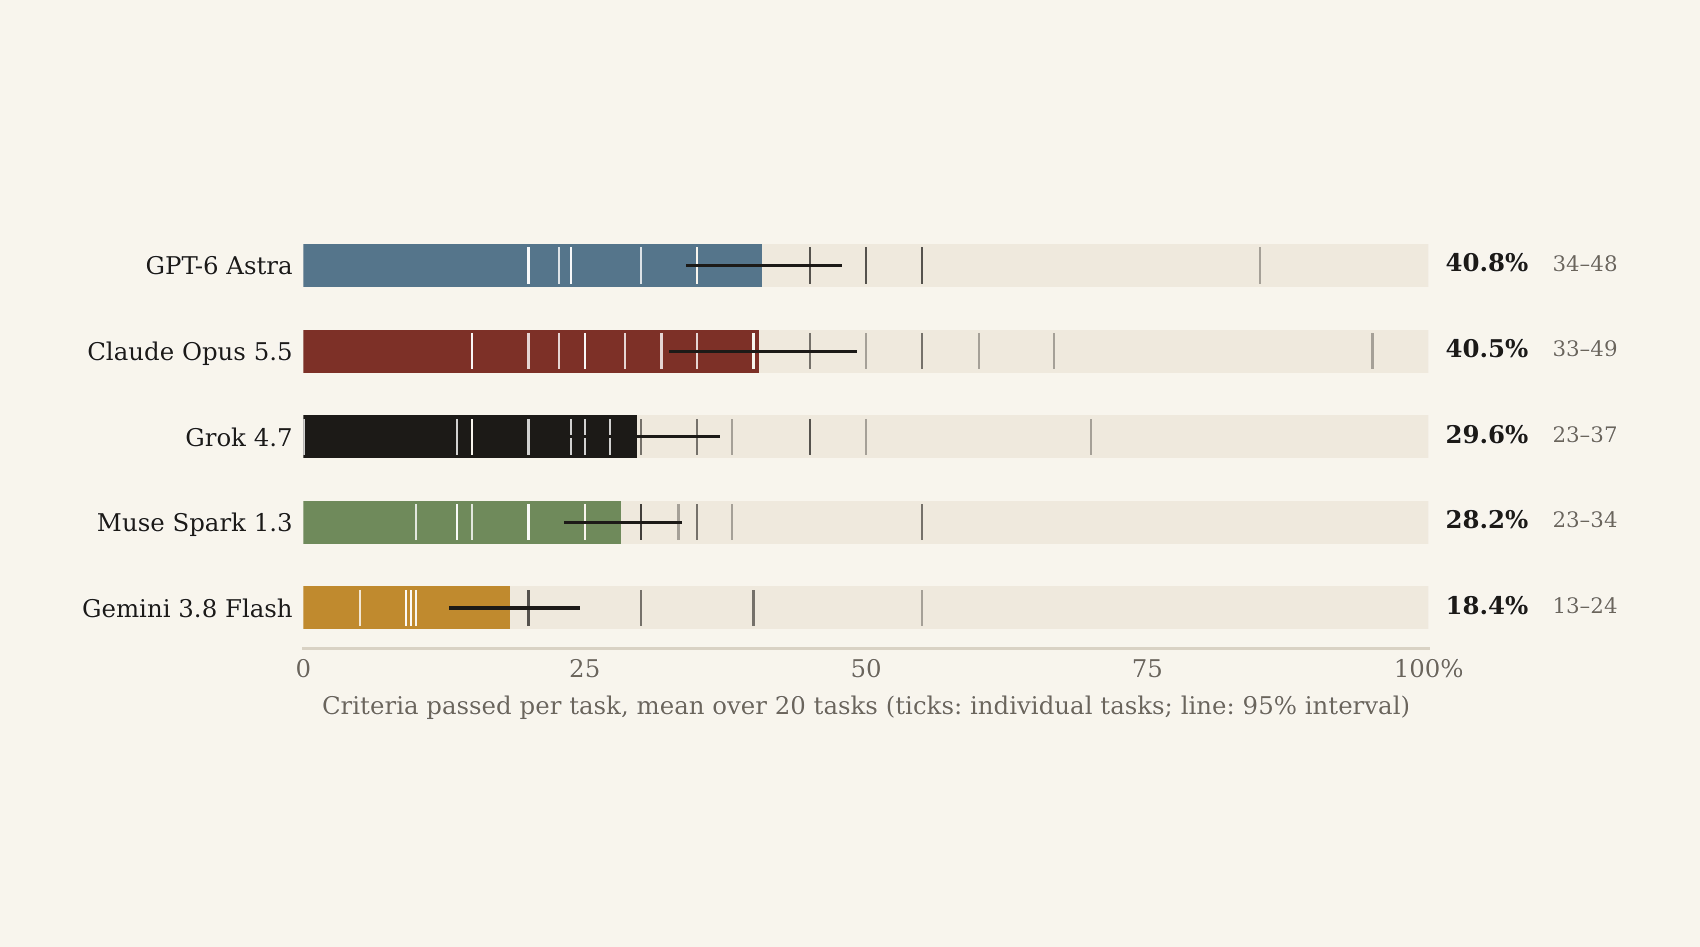
The best agents pass two in five criteria
Mean share of criteria passed; line is the 95% interval.
GPT-6 Astra40.8%34–48
Claude Opus 5.540.5%33–49
Grok 4.729.6%23–37
Muse Spark 1.328.2%23–34
Gemini 3.8 Flash18.4%13–24
0255075100%
GPT-6 Astra and Claude Opus 5.5 tie, but Astra took a median 5 minutes per task to Opus’s 35.
Same score, seven times faster
Score against median minutes per task (log scale).
0%20%40%60%
GPT-6 Astra40.8% · 5 minClaude Opus 5.540.5% · 34.6 minGrok 4.729.6% · 14.2 minMuse Spark 1.328.2% · 4.5 minGemini 3.8 Flash18.4% · 13.3 min
35102040
GPT-6 Astra 40.8%, 5 minClaude Opus 5.5 40.5%, 35 minGrok 4.7 29.6%, 14 minMuse Spark 1.3 28.2%, 4.5 minGemini 3.8 Flash 18.4%, 13 min
Agents fail the same criteria
182 of 406 criteria were passed by no agent; 31 by all five. What one frontier agent misses, the others usually miss too.
45% of criteria were passed by no agent
Criteria by number of agents passing them.
182
55
40
45
53
31
none1234all 5
They interpret; they don’t choose
Agents excel at interpreting previous experiments: saying what a measurement is, declining an overclaim, reconstructing an analysis. Criteria that require choosing, committing or ranking pass 21% of the time, against 47% for identifying what something is. No agent passed any of the 13 criteria on which experiment should come first.
Choosing is the hardest move
Pass rate by what the criterion asks; “none” = share no agent passed.
Identify what something is47%none: 32%
Reconstruct or explain38%none: 37%
Qualify a claim33%none: 39%
Integrate evidence31%none: 38%
Quantify or read out30%none: 46%
Choose, commit or rank21%none: 64%
0255075100%
Where agents differ
Astra leads on core decisions (52%), Opus on evidence integration (53%). On experiment design, the best agent passes 9%.
No agent can design the next experiment
% of each skill’s criteria passed (criteria count beside skill).
GPT-6 AstraClaude Opus 5.5Grok 4.7Muse Spark 1.3Gemini 3.8 FlashMethod reconstruction 425043383338Measurement semantics 435644403328Evidential status 415149443912Comparison & baseline 404850323530Confounds & data quality 273752443315Scope & generalization 294852243121Quantitative reading 554542403116Core decision 235243302617Evidence integration 364753223611Experiment design 7039033
Deciding is harder than analyzing
% of criteria passed, by theme and task type.
GPT-6 AstraClaude Opus 5.5Grok 4.7Muse Spark 1.3Gemini 3.8 Flash
Nascent transcriptionn=42
Gene regulationn=60
3D genomen=62
Drug responsen=101
Hit-to-lead chemistryn=40
Target validationn=41
Assay developmentn=60
Analyze tasksn=261
Review tasksn=84
Design tasksn=61
0204060%
The knowledge is latent
A common issue with hard benchmarks is unreasonable criteria that make tasks effectively impossible. We tested this directly. On five core decisions no agent passed, we appended one sentence pointing at evidence GPT-6 Astra already had, without stating the answer. It passed all five.
One sentence flips the decision
GPT-6 Astra’s task score. The core decision flipped from fail to pass in all five.
Benchmark runWith one added sentence
Next two experimentsdrug response20% → 75%
Chromosome model review3D genome23% → 64%
Candidate coding transcriptsnascent transcription50% → 82%
Motif evidence across datasetsgene regulation35% → 60%
Library preparation choiceassay development35% → 40%
0255075100%
One run per hinted task.
#### Drug response
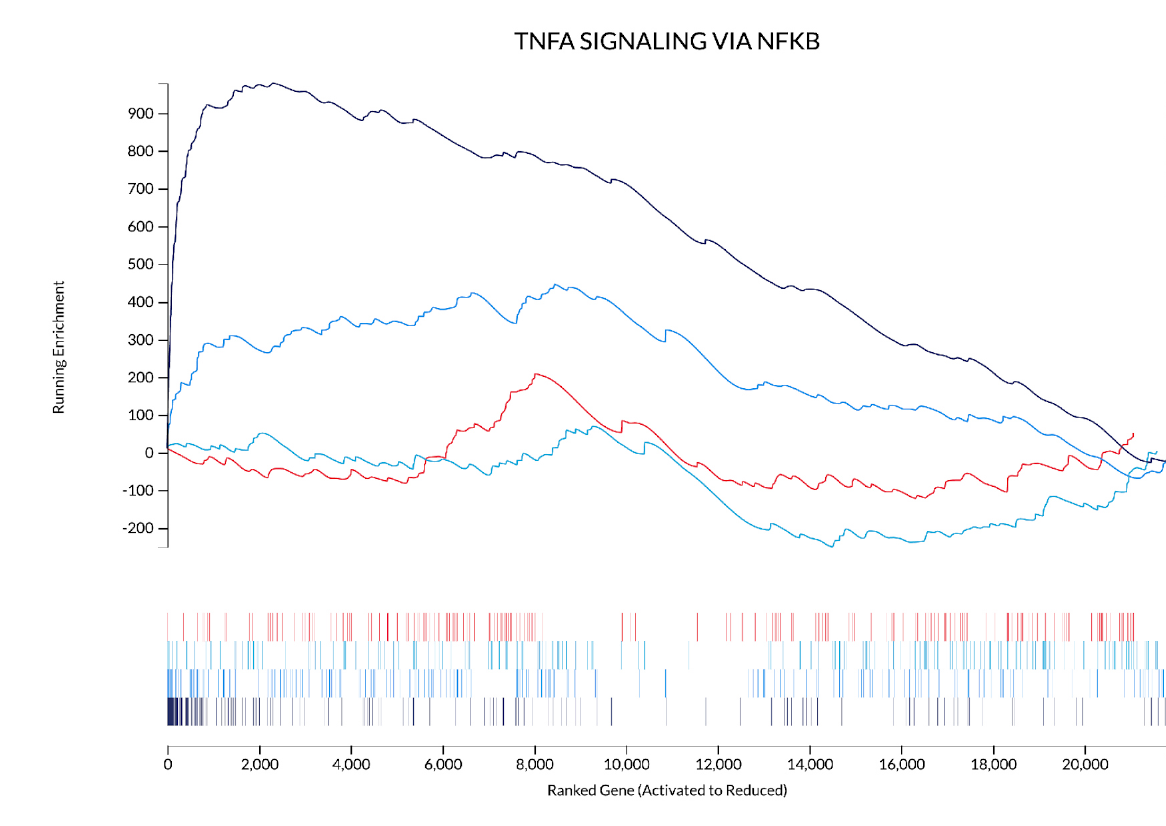
NF-κB signaling at 15 minutes under four death inducers, from the task’s records (compound names withheld).
Evidence A compound triggers the strongest early NF-κB signature of four death inducers; nothing tests whether it drives death.
Agents Four of five designed the NF-κB test, then ranked it second.
Hint “Rank first the experiment that could tell a cause from a bystander.” Score: 4/20 → 15/20.
#### Assay development
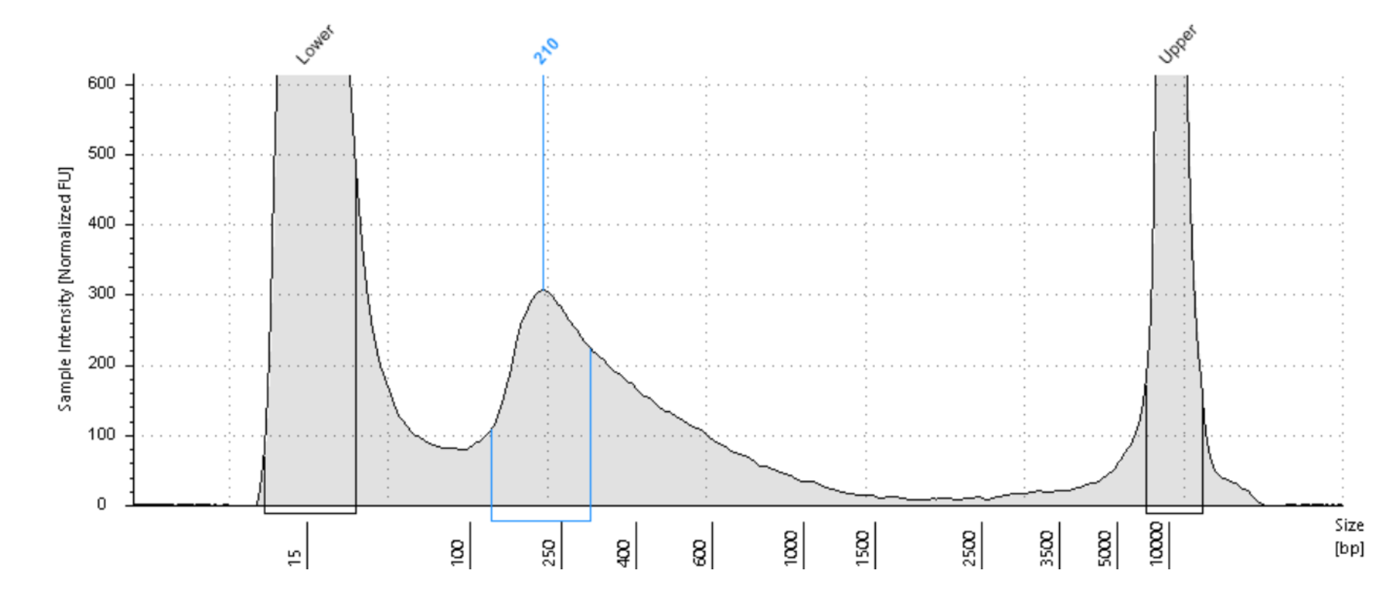
5 µL Tn5, 2 min: peak 210 bp, clean tail. The lab’s choice.
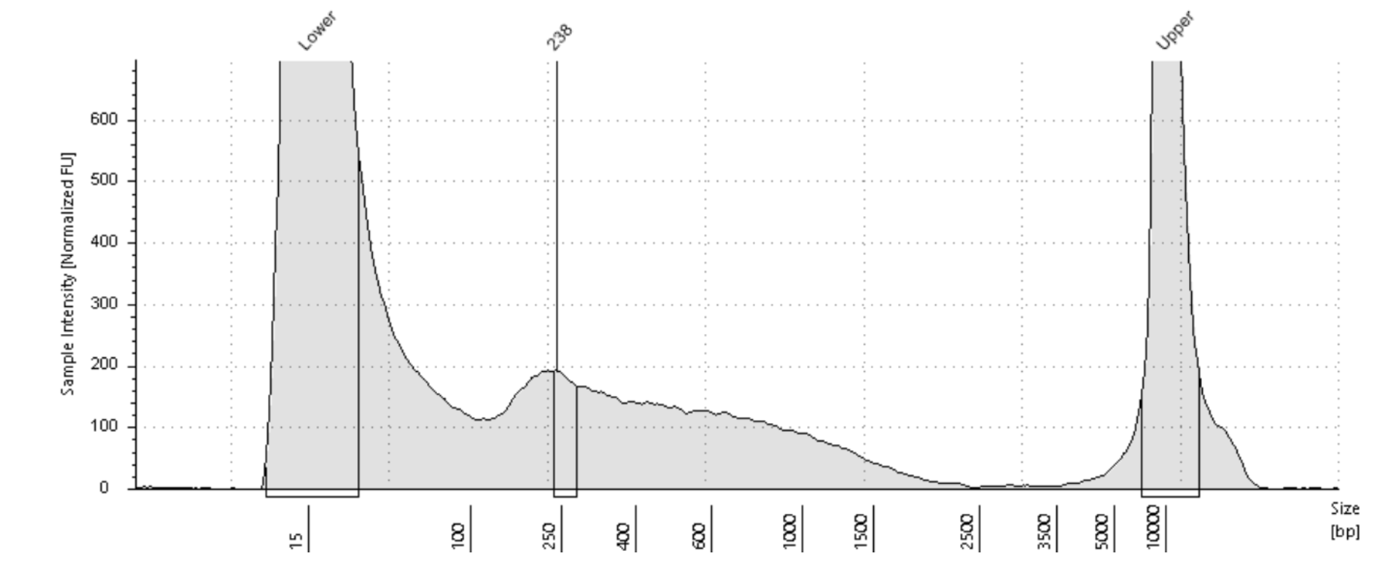
2.5 µL Tn5, 5 min: peak 238 bp, broad large-fragment shoulder. Every agent’s choice.
Agents All five chose the larger 238 bp peak and ignored the shoulder of uncut DNA.
Hint “Judge each tagmentation trace by its whole size distribution…” The agent chose the lab’s condition.
The hints add no biology; they redirect attention. The models have the knowledge but do not reliably recall it.
A reasoning bottleneck
Frontier agents know enough biology to work alongside expert biologists when experimental design stays with humans. Their ability to design experiments independently is weak: they fail to commit to an experiment and to discriminate the best one from the alternatives.
In real biological experimentation, wall-clock time is irreducible. Cells grow, differentiate and respond on their own schedules, and each experiment consumes weeks and material. Autonomous and correct experimental design is arguably the single most important capability for making AI agents superhuman at these tasks.
LabBench measures this directly. Improved results should indicate agents that can carry out supervised, autonomous wet-lab experimentation, and eventually run full programs themselves. To get there, models must develop a more cohesive world model of what experiments cost and of the specific evidence that would count against a hypothesis.
Work with us
Gamow Labs is uniquely equipped to produce data at the frontier of AI and biological experimentation. We are capable of producing the aforementioned tasks at scale. Reach out.
Full methods are in the preprint. We’re also hiring.