
AT0M : A private, System One Decision AI that runs locally.
// a decision model you own, not an API you rent · v0 to evaluate, v1 to deploy
AT0M : A private, System One Decision AI that runs locally.
Give it a state and a set of questions — choice, score, or yes-no. It returns one probability per option, in a single forward pass.
No tokens and no free text, so it cannot answer outside your candidate set. It runs as a single local executable, which keeps inference inside your perimeter.
Try AT0MJoin the waitlist Explore the evidence
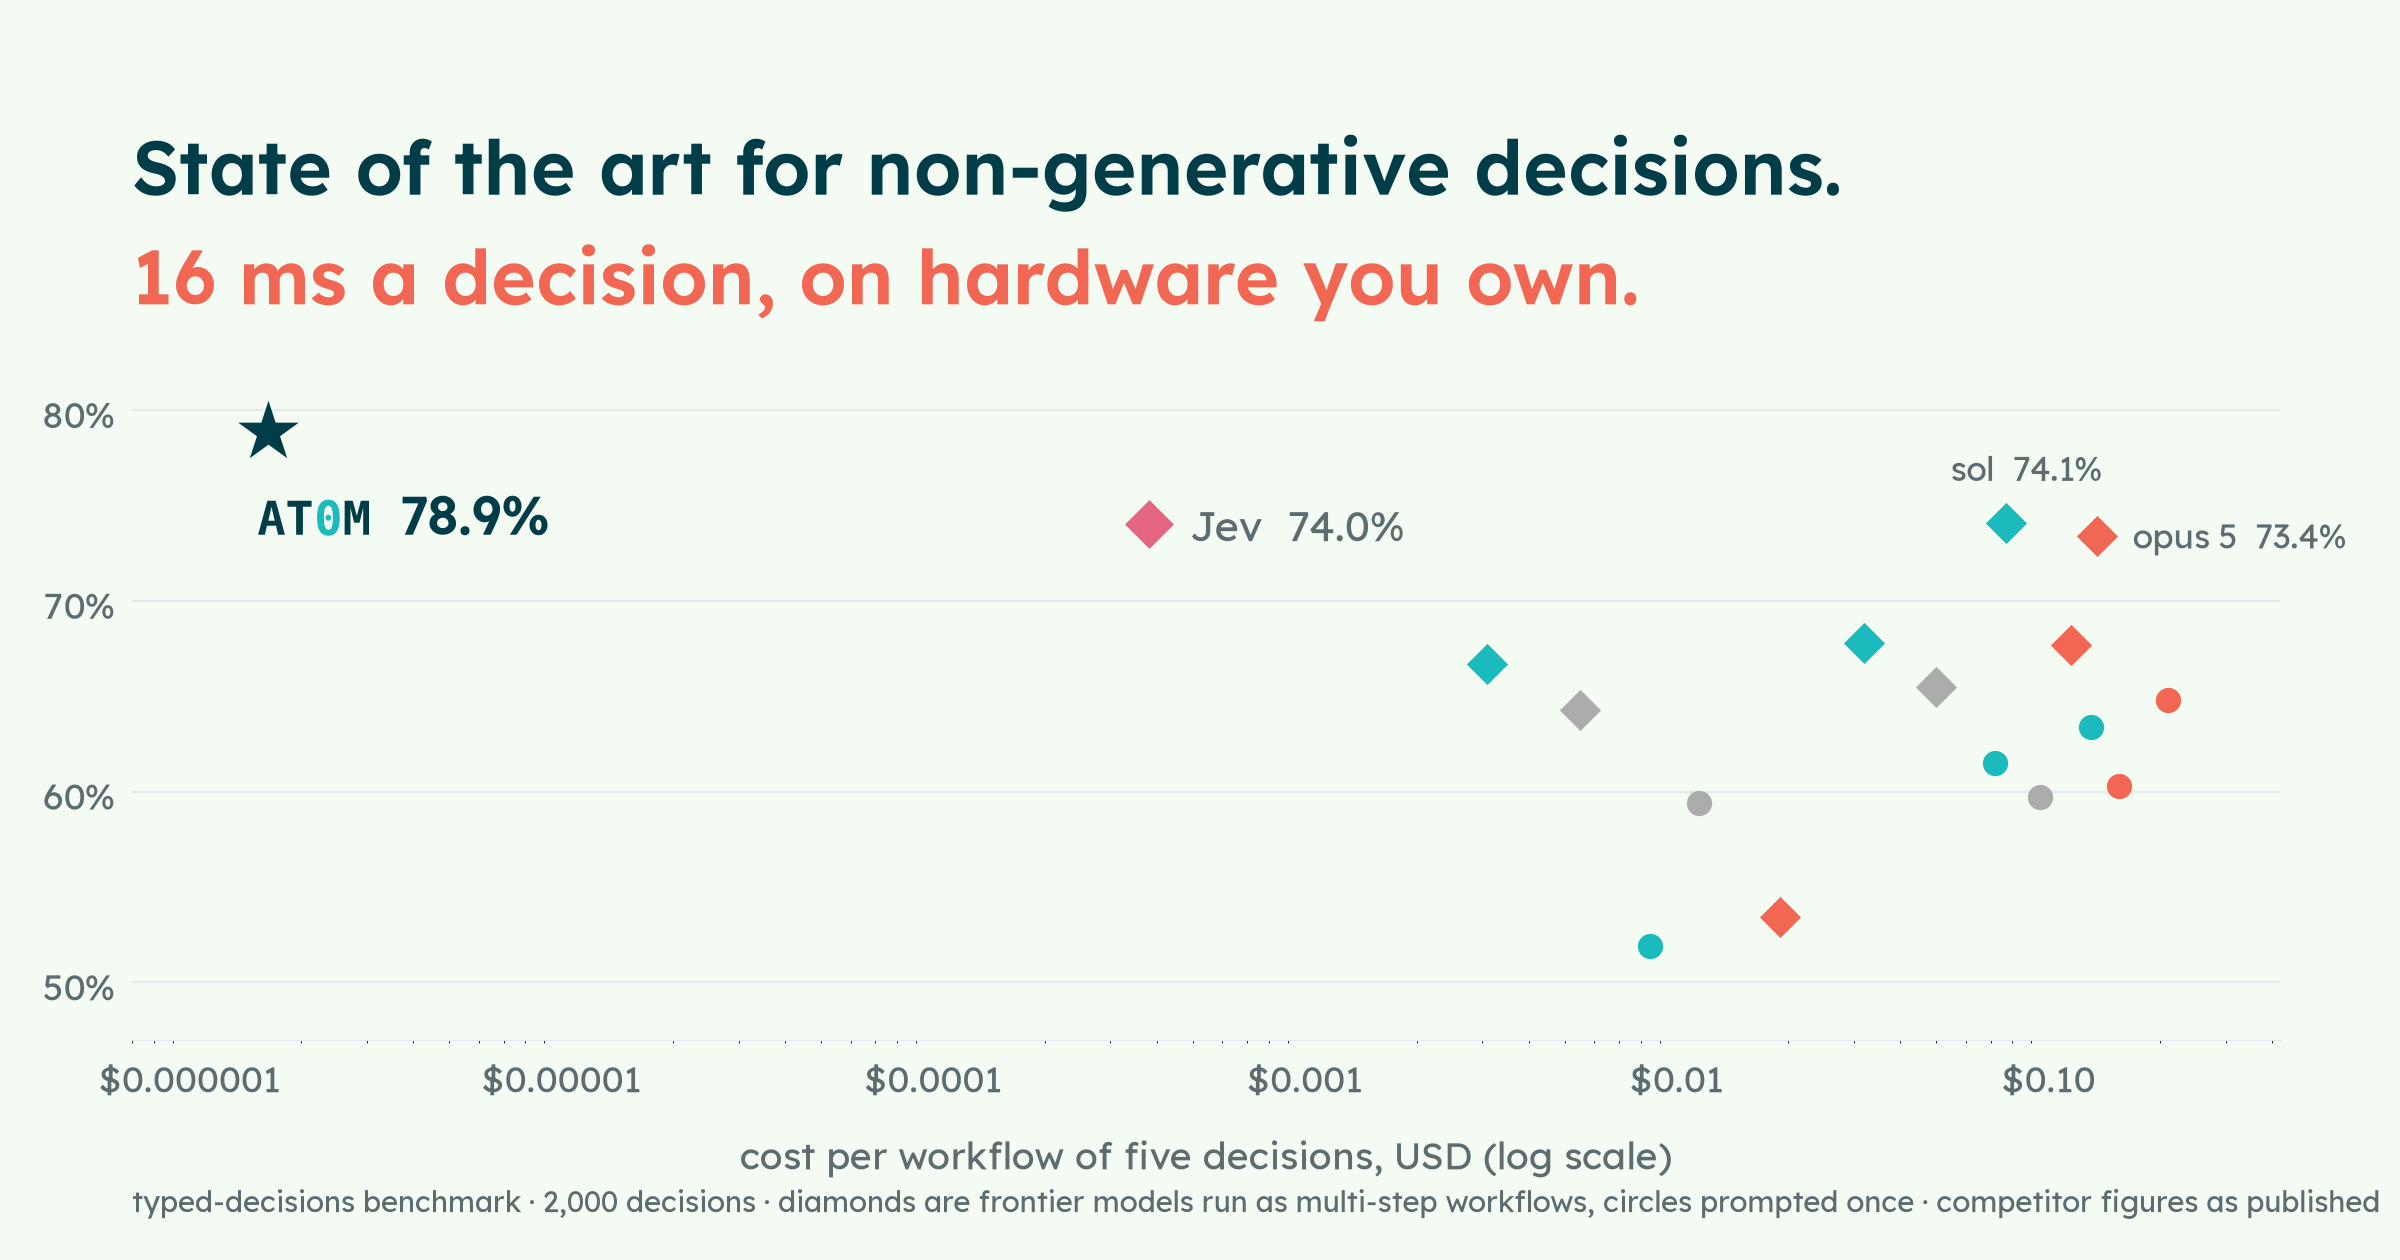
45% 50% 55% 60% 65% 70% 75% 80% 85% $0.000001 $0.00001 $0.0001 $0.001 $0.01 $0.10 cost per workflow of five decisions, USD (log scale) accuracy on typed-decisions AT0M Jev others, as a workflow others, prompted terra sol opus 5 Jev · 74.0% 78.9%
↔ swipe the chart
78.9%
typed-decisions, 2,000 decisions
16 ms
response on a T4
5.6%
calibration error, nothing fitted
Accuracy against what a decision costs. A workflow is five typed decisions about one record. Competitor accuracies and prices are as published; ours is measured over all 2,000 test decisions and priced from a laptop’s measured throughput plus its amortised system cost. The full basis is in the report.
60M trainable parameters deterministic choice · score · noul bounded output calibrated, no temp fitting single Rust binary · CPU / Metal / CUDA runs in your perimeter
// how you deploy it
The executable is the product.
AT0M will ship as a single self-contained Rust binary — no Python at inference, no service in the path, nothing to rent. That is the deployment, and it will be the only thing that ends up in your perimeter.
The hosted endpoint exists for one reason: so you can check every number on this page before you download anything.
Evaluate firstv0 · hosted
One POST carries a record and as many questions as you like, answered together in the same pass. No SDK, no client library. Currently an evaluation build; the release will improve on it.
POST /decide/v0 — evaluation endpoint
$ curl -s -X POST \\ https://at0m.pienomial.com/decide/v0 \\ -H 'Content-Type: application/json' \\ -d '{"state": "Our production API has been down since 6 AM.", "questions": { "queue": {"type":"choice", "criteria": {...}}, "urgent": {"type":"noul", "instructions":"Needs action today."}}}' → queue: infrastructure (p=0.999) → urgent: true (p=0.892)
To be releasedv1
Run a file of decisions, or serve the same API on your own machine. Self-hosted end to end — this is what a production deployment looks like.
./at0m — your machine, your perimeter
\# score a file of decisions, no server $ ./at0m decide \--in decisions.json \# or serve the same API yourself $ ./at0m serve \--port 8080 \--device metal listening on :8080 · metal · 54 dec/s $ curl -s localhost:8080/decide \\ \-d @decisions.json → no network, no provider, no per-decision fee
v0 is the evaluation endpoint; v1 is the executable release — the hosted service is a way to try the model, not a way to run it. Every figure on this page was measured against v0, the evaluation build, so they are the floor rather than the ceiling: v1 is expected to be more accurate, and we will republish every number on this page when it ships.
// how it works
What the model actually does.
- Non-generative. It scores your supplied options, it doesn't write text. The output is a probability per option — so a malformed or out-of-list answer is structurally impossible, not just discouraged.
- Calibrated by construction. Probabilities mean what they say without post-hoc temperature fitting: 5.6% ECE on typed-decisions, 3.7% on its choices, 3.7% on Enron spam. Set an escalation threshold, auto-act above it, route the rest to a human.
- Local inference. Runs as a standalone Rust binary on CPU, Apple Metal or CUDA. Inference stays in your perimeter — no required third-party API in the path, so no per-decision network round-trip.
- Trainable on your own decisions. Ten thousand of your own records, five questions each, is about two hours on a laptop. No datacentre GPU, no cluster time.
- Bounded output — can't answer off your candidate set. (A generative model can; that's the failure mode this design removes.)
- Calibration without temperature fitting — thresholds you can trust straight out of the model.
- Local inference — the model is an artifact you run in your perimeter, not an API you rent, and there's no per-decision round-trip.
- Cost structure, not a discount — nothing is generated, so there are no output tokens to pay for. The marginal cost of the next decision is electricity.
- Deterministic — send the same request twice and you get the same probabilities, to the last digit. Two full re-runs of every set on this page, 38,862 decisions each, came back identical on every metric: accuracy, calibration error, mean confidence, F1. The headline survives load as well — typed-decisions scores 0.7885 whether you send it one request at a time or five hundred at once. The one thing that moves is the split underneath that total: batched beside different neighbours, an item sitting on a decision boundary can land the other way, so per-primitive figures wander by a decision or two in 2,000 while the total holds. Re-run it and you get our numbers.
- Reproducibility — the endpoint that produced these numbers is the same one you can point your own eval at.
// the numbers, with their measurement conditions
Benchmark results.
One configuration across every public test set — no per-dataset tuning or prompt tweaks. 38,862 decisions, scored in one sweep.
Two things we'd flag before you read the numbers. The public typed-decisions benchmark's labels are noisy — they self-agree \~65% of the time against a \~73% teacher-model ceiling — so we don't read small margins near the top as meaningful, ours included. And every AT0M figure here came from a single sweep through one harness, while the competitor figures come from their own write-ups under their own conditions — so read the table as "each number with its source," not a single scoreboard.
| Benchmark | AT0M | Laya | Jev | Condition | | ------------------------------ | ------------- | ------- | ----------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | typed-decisions (2,000) | 0.789 | 0.766 | 0.740 | ahead of Laya by 2.3pt, marginally outside the ±1.8pt sampling error | | calibration (ECE) | 0.056 | 0.081\* | 0.121–0.161 | \*Laya after fitting a temperature, and from its specialist checkpoint; Jev is the spread across four independent studies — TypeSafe publishes none. Jev and AT0M are general models, one configuration for every row; AT0M fits no temperature | | DAIR Emotion | 0.921 | 0.595 | 0.480 | bare labels | | Banking77 (77 intents) | 0.853 | 0.425 | 0.870 | Jev on 72 labels — not the same label space. Ours moves between 85% and 88% with how the intents are worded, so read the margin here as a band, not a point | | AG News | 0.896 | 0.950 | 0.910 | the one clean multi-way we trail | | CLINC150 + out-of-scope | 0.795 | — | — | 151 candidates, scored in full | | Enron spam / held-out phishing | 0.955 / 0.805 | — | — | phishing never trained on — the honest transfer test | | toxicity guardrail (F1) | 0.626 | — | — | 7.1% positive — answering "no" to everything scores 92.9% accuracy and catches nothing |
Laya figures, and Jev's on the classification sets, are as reported in the Laya write-up. Jev's typed-decisions figure is DecisionEval's independent rerun. On calibration, TypeSafe publishes no figure at all, so Jev's range is assembled from four independent studies, none temperature-fitted.
// what we'd actually defend
The parts that don't depend on the benchmark.
The accuracy number is near the top but sits inside admitted label noise, so we don't hang the pitch on it. The claims we'd stand behind under scrutiny are architectural:
And the parts we wouldn't: it compares a value to a threshold well, but not one field of a record against another, so compute those predicates in code. Calibration decays off-distribution — 0.037 on spam it has seen, 0.171 on phishing it hasn't. Both are measured below.
Verify the benchmark yourself.
Every figure on this page came from a public test split scored through this endpoint. Point the same benchmark at it and check. One POST carries a record and as many questions as you like, all answered in the same pass — no SDK, no client library.
Evaluating for your organization?
We'll help you scope a local-training or private-deployment evaluation against your own decisions — and share the full technical report.
Join the waitlist Request an evaluation Get the technical report
or email info@pienomial.com
$ curl -s -X POST https://at0m.pienomial.com/decide/v0 \\ -H 'Content-Type: application/json' \\ -d '{ "state": "Charged twice for the same card payment this morning.", "questions": { "queue": {"type":"choice", "instructions":"Which team should handle this?", "criteria": {"billing":"invoices, charges, refunds", "technical":"outages, bugs, deploys", "fraud":"unauthorised or suspicious activity"}}, "urgent": {"type":"noul", "instructions":"Needs action today."}}, "email\_id": "you@example.com"}' → queue: billing (p=0.981) urgent: true (0.774) 10.9 ms
// for engineers & procurement
The full evidence, when you want it.
A comparative evidence inventory across AT0M, Jev 1.13.0 and Laya, carried from the technical paper. It is not a harmonized three-model benchmark: figures were obtained under different conditions, and each is tagged with its source and how it was measured.
Full technical comparison: AT0M · Jev · Laya — collapsed by default ▸
\[S1\] Pienomial test report — AT0M results, measured by us against the public endpoint and reproducible by anyone: the same script run against the same endpoint returns the same figures. \[L1/L2\] Convai Laya model cards — vendor-reported; specialist and routed results kept distinct. \[I1\] DecisionEval — independent Jev 1.13.0 rerun on a frozen test. \[J1/J2\] TypeSafe documentation — product spec, subject to change. \[B1\] Public typed-decisions leaderboard.
A1 · Architecture & interface
| Parameter | AT0M | Laya | Jev 1.13.0 | | ------------------- | ------------------------------------------------------------------- | ----------------------------------------------------- | ----------------------------------- | | Developer | Pienomial | Convai Innovations | TypeSafe AI | | Delivery form | Standalone Rust binary; HTTP / CLI / JSON-file | Open weights; Python SDK / Jev-compatible HTTP server | Managed API | | Backbone | Not disclosed in report | ModernBERT-large 421M; mmBERT-base 322M | Not disclosed | | Primitives | choice · score · noul | choice · score · noul | choice · score · noul | | Inference | Non-autoregressive; no free text | Non-autoregressive; no free text | Non-autoregressive; no free text | | Multi-question call | Yes | Yes | Yes | | Max context | 32k request — the verification server caps requests at 4,096 tokens | 512 EN / 1,024 TD, multi 1,024 | 32k state + longest Q / 64k request | | Model selection | One configuration across all tests | Router: EN / multilingual / specialist | One managed version |
A2 · Accuracy & benchmark quality
| Measure | AT0M \[S1\] | Laya \[L2\] | Jev \[I1\] | | ---------------------------------- | ------------------------------ | --------------------------------- | -------------------------- | | TD overall | 0.789 | 0.766 specialist | 0.740 (0.727 older \[B1\]) | | TD choice | 0.755 | 0.733 | 0.738 | | TD score | 0.763 | 0.723 | 0.705 | | TD noul | 0.857 | 0.857 | 0.787 | | Invoice / service / obs / security | .846 / .786 / .764 / .758 | .804 / .764 / .730 / .766 | .786 / .788 / .640 / .744 | | AG News | 0.896 described | 0.950 routed | 0.910 (secondary) | | DAIR Emotion | 0.921 bare | 0.595 routed | 0.480 (secondary) | | Banking77 | 0.853 / 77 labels | 0.425 / 77 labels | 0.870 / 72 labels ≠ | | Held-out phishing | 0.802 (excluded from training) | — | — | | CLINC150 + out-of-scope | 0.794 / 151 choices | — | — | | Base vs specialist | One config throughout | General EN checkpoint 0.362 on TD | Zero-shot general weights |
A3 · Calibration & reliability
| Measure | AT0M | Laya | Jev | | ----------------- | ------------------------------------------------- | ------------------------------ | ----------------------------------------------- | | TD ECE (10-bin) | 0.057 no temp fitted \[S1\] | 0.213 raw specialist \[L2\] | 0.121–0.161 across four independent studies | | Per-type ECE | choice .052 · score .086 · noul .057 | 0.081 after temperature \[L1\] | TypeSafe publishes none | | Brier | Not provided | 0.062 specialist | 0.148 independent | | Confidence gating | Full coverage curve not published | No matched curve | ≥0.7 → 57.6% kept @ 86.4%; ≥0.9 → 24.5% @ 93.7% | | Option-order | 98% stable | Not established | Not established | | Counterfactual | 13/15 directional; identifier-repeat pair fails | — | — | | Empty record | Confidence falls 0.723→0.616; still no abstention | Not measured | Not measured |
A4 · Inference & throughput
| Metric | AT0M | Laya | Jev | | ------------------- | --------------------------------- | ------------------------------- | -------------------------------- | | 5-question, T4 | 82 ms server time | 84.5 ms EN / 40.1 ms multi | 687 ms p50, network incl. \[I1\] | | 1-question, T4 | 16 ms T4 server; 22.1 ms M1 Max | 39.5 ms EN / 32.8 ms multi | older 236–276 ms hosted | | Throughput | M1 Max \~41→54 dps (1→32 clients) | 103–332 q/s batched, T4 | Provider-managed | | 77 / 151 candidates | 92.7 ms / 165.5 ms, M1 Max | Budget competition on options | Not matched | | Hardware | CPU · Apple Metal · CUDA | CPU / GPU self-host | Provider-managed | | Network | Server figure excludes round-trip | Inference; network not included | 687 ms explicitly end-to-end |
A5 · Enterprise ownership
| Parameter | AT0M | Laya | Jev | | ------------------ | ------------------------------------------------------------- | ---------------------------------- | -------------------------------------------- | | Weights | Training emits own weights; distribution terms per engagement | Apache-2.0 downloadable | Proprietary; no download | | Self-hosting | Standalone executable | Python / HTTP server | Not offered publicly | | Data transmission | Local inference stays in perimeter | Local inference stays in perimeter | Sent to provider unless contracted otherwise | | Version management | Export validation; customer handles rollout | Pin model hashes / runtime | Versioned IDs / alias pinning | | Audit trail | Raw probabilities; app owns the log | Opt-in prediction hooks | Version returned; app logs decisions |
A6 · Economics
| Item | AT0M | Laya | Jev | | --------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ---------------------------- | ------------------------------------- | | Published price | Commercials will be released with v1. What do you think they should be? Please let us know at info@pienomial.com | Apache-2.0; hosting not free | $0.042 / 1M input tokens; output free | | Recurring cost | Local hardware; no per-decision token fee | Self-host compute + ops | Per-token input charges | | Correct unit | Normalized cost per verified useful decision = (inference HW + service ops + adaptation amortization + review + provider fees) ÷ verified useful decisions. No party publishes a hardware-normalized total — do not infer a universal lowest cost. | | |
Sources: \[S1\] Pienomial AT0M benchmark report v1.0, 27 Sep 2026 · \[L1/L2\] Convai Laya model cards · \[I1\] DecisionEval Jev 1.13.0 independent rerun, 20 Sep 2026 · \[J1/J2\] TypeSafe documentation · \[B1\] public typed-decisions leaderboard. Latencies are not hardware- or network-normalized; pricing and availability may change after the report date. "Not disclosed" means the cited sources don't establish the item — not that it's unavailable.
×
Join the waitlist
V1 is the single binary you run on your own hardware. Leave an address and we'll tell you when it ships — nothing else, and no one else gets it.
Join the waitlist
One email when V1 ships. No newsletter.