Rho
Rho
A Foundation for Efficiently Adaptable VLA Models
Rho team1
Simran Bagaria, Daphne Chen, Dean Fortier, Jianlong Fu, Michael Harrison, Tess Hellebrekers, Neel Joshi†(VLM lead), Andrey Kolobov♠∗(Project lead, Data lead), Dalton Moore, Galen Mullins‡(Engineering lead), Michael Murray§(Training lead), Eduardo Salinas, Reuben Tan
Microsoft Research
Area leads:∗Data§Training‡Engineering†VLM♠Project lead
1Authors are listed alphabetically.
Rho is a family of open-weights, 5B-parameter vision-language-action models for bimanual robotic manipulation, designed for data-light adaptation. One foundation model, Rho-base, is midtrained into ready-to-adapt variants for three common dual-arm robots — YAM Box, UR AI Trainer, and FR3 Duo — and a task policy derived from any of them can keep improving after deployment from a handful of human corrections.
Technical report↗Code↗Models↗Data↗
Model size5B params
Robot-ready variants3 embodiments
Pretraining data3,200+ hours
Midtrained Rho variants for…
I²RT
YAM Box
Portable platform common in research labs.
Universal Robots
UR AI Trainer
Emerging industrial dual-arm standard.
Franka
FR3 Duo
Straddles research and industry use.
Overview
Adaptation is the bottleneck. Rho is built for it.
Vision-language-action models (VLAs) promise general-purpose robot manipulation, but their zero-shot success on unseen tasks and in new environments is still low. In practice, adaptation — turning a pretrained model into one that works on a particular robot for a particular task — is the crucial step, and it is data-hungry.
The reason is that pretraining exposes a model to a broad but shallow mix of robots, tasks, and environments. It never masters the sensing, kinematics, action space, and data conventions of any one platform. So when a pretrained model is finetuned on a new task, the demonstrations have to teach it the robot and the task at the same time. Rho's premise is that a model should master the robot before task adaptation begins. Its training recipe separates adaptation to an embodiment from adaptation to a task, and absorbs the first, expensive part into the released checkpoints.
01
One foundation, three robot-ready variants
A single pretrained model, Rho-base, is midtrained into Rho-YAM-Box, Rho-UR-AI-Trainer, and Rho-FR3-Duo — reusable starting points for many downstream tasks on each robot. All four are open weights.
02
Midtraining halves the task data you need
In controlled experiments, a midtrained variant reaches a given success rate with half as much finetuning data as Rho-base. After finetuning on the same demonstrations, the variants match or outperform π0.5, GR00T N1.7, and MolmoAct2 on three physical robots.
03
Keeps learning after deployment
A lightweight latent policy inside every Rho model learns from corrective feedback while the rest stays frozen. Online adaptation with FlowDAgger on just 15 episode corrections lifted test-tube assembly on FR3 Duo from 30% to 70% success on the hardest task configurations.
Training recipe
Regularized progressive adaptation, stage by stage
Rho task policies are produced by a recipe consisting of four offline stages and an optional fifth that runs after deployment. Each stage adds a capability — physical understanding, continuous control, one robot's conventions, one task, then corrections from use — while taking care not to erase what the previous stages built: vision-language batches stay in the mix through pretraining and midtraining, and online adaptation touches only a small internal module. That is the "regularized" in regularized progressive adaptation.
01Ground
Phi-Phy
Physically grounded VLM
A 4.68B-parameter Phi-family vision-language model gets extra robotics-relevant grounding, pointing, spatial-reasoning, and multi-image VQA training, so it understands physical scenes before it is asked to control anything.
Data≈36M physical-grounding records in a 100M-record SFT mix
MixtureGeneral VLM data + physical grounding
OutputPhi-Phy backbone (no actions yet)
→
02Pretrain
Rho-base
Multi-embodiment VLA
A 542M-parameter flow-matching action expert is attached and trained with the backbone on Rho-Tomyum: 3,200+ hours from more than a dozen robots, mostly dual-arm, plus VQA data that keeps the backbone grounded.
Data3,200+ robot hours · 48 B200 GPUs
Mixture90% robot data · 10% vision-language
OutputRho-base: the shared foundation
→
03Midtrain
Rho-⟨robot⟩
Embodiment-specific VLA
Rho-base is trained for two epochs on \~300 hours of one robot's data across dozens of task families. The goal is to learn the robot — cameras, kinematics, workspace, control conventions — not to master any one task.
Data≈280–300 hours of one robot · 19–65 task families
Mixture90% target robot · 10% vision-language
OutputRho-YAM-Box · Rho-UR-AI-Trainer · Rho-FR3-Duo
→
04Finetune
Task policy
Offline task adaptation
A midtrained variant is finetuned on demonstrations of the target task: same flow-matching objective, all parameters trainable, robot data only. Because the robot is already familiar, a few hundred demonstrations go a long way.
Data≈100–300 demonstrations per task on physical robots
Mixture100% target-task demonstrations
OutputDeployable task policy
→
05Correct
Online adaptation
Learning from corrections
After deployment, a small latent policy inside the model learns from human corrective takeovers while the backbone and action expert stay frozen. It changes only where action generation starts, so the offline-learned behavior is preserved.
Data15 corrected episodes per task on FR3 Duo
MixtureCorrective takeovers only; rest of the model frozen
OutputThe stage-04 task policy, improved in place
Stage 02 · What Rho-base is pretrained on
XMI (UMI-style): 22.1% · 520 h @ 30 HzYAM Box (in the wild): 17.5% · 1,004 h @ 30 HzYAM Box: 9.5% · 449 h @ 30 HzYAM Station: 6.2% · 290 h @ 30 HzUR AI Trainer: 17.4% · 263 h @ 50 HzFR3 Duo: 11.0% · 278 h @ 30 HzTrossen Stationary AI: 2.9% · 72 h @ 30 HzOXE Amuse Bouche: 2.7% · 292 h @ 3–30 HzOmniReset UR AI Trainer (sim): 0.7% · 36 h @ 50 HzVision-language data: 10.0% · RoboPoint + RefSpatial VQA, 5% each3,203 hrobot data
- XMI (UMI-style)520 h @ 30 Hz22.1%
- YAM Box (in the wild)1,004 h @ 30 Hz17.5%
- YAM Box449 h @ 30 Hz9.5%
- YAM Station290 h @ 30 Hz6.2%
- UR AI Trainer263 h @ 50 Hz17.4%
- FR3 Duo278 h @ 30 Hz11.0%
- Trossen Stationary AI72 h @ 30 Hz2.9%
- OXE Amuse Bouche292 h @ 3–30 Hz2.7%
- OmniReset UR AI Trainer (sim)36 h @ 50 Hz0.7%
- Vision-language dataRoboPoint + RefSpatial VQA, 5% each10.0%
- YAM Box (lab)45.5%
- YAM Box (in the wild)44.5%
- Vision-language data10.0%
- UR AI Trainer79.3%
- OmniReset (sim)10.7%
- Vision-language data10.0%
- FR3 Duo90.0%
- Vision-language data10.0%
- Rho-base (pretrained only)
- Rho-RoboTwin (midtrained)
- Rho-YAM-Box
- π0.5
- GR00T N1.7
- MolmoAct2
- Rho-UR-AI-Trainer
- π0.5
- GR00T N1.7
- Rho-FR3-Duo
- π0.5
- GR00T N1.7
- Rho-base
- π0.5
- GR00T N1.7
- MolmoAct2
The Rho-Tomyum mixture. Shares are of training updates: 90% robot and UMI-style data, 10% vision-language data. All robot data is bimanual except the small OXE "Amuse Bouche" subset. Every source is standardized to chunk-relative end-effector deltas with 6D rotations (10 dimensions per arm) over about one second of motion, and demonstration segments labeled as errors are removed.
Stage 03 · What each variant is midtrained on
Rho-YAM-Box65 task families · 2,617 instructions
YAM Box (lab): 45.5% · 146 hYAM Box (in the wild): 44.5% · 143 hVision-language data: 10.0%289 h
Lab and in-the-wild YAM Box data, sampled evenly at the episode level.
Rho-UR-AI-Trainer31 task families · 40,220 instructions
UR AI Trainer: 79.3% · 263 hOmniReset (sim): 10.7% · 36 hVision-language data: 10.0%299 h
Physical demonstrations plus Isaac Sim rollouts on the same robot and cameras.
Rho-FR3-Duo19 task families · 33,883 instructions
FR3 Duo: 90.0% · 278 hVision-language data: 10.0%278 h
Cleaning, folding, sorting, pouring, packing, cable insertion.
Each mixture averages no more than \~15 hours per task family — not enough to master a high-precision task, but enough to cover a robot's motions, workspace, and camera views. Instruction counts include task and subtask descriptions; the vision-language share is the same RoboPoint and RefSpatial data as in pretraining, 5% each.
Architecture
A compact Phi-family VLM coupled to a flow-matching action expert
At each control step Rho sees one or more camera views, a language instruction, and the robot's proprioceptive state, and outputs a chunk of future actions. Images and text are processed by Phi-Phy; robot state is projected straight into the action expert. The expert learns a velocity field that carries Gaussian noise to an action chunk and integrates it in 10 Euler steps at inference. Every expert block cross-attends to the same intermediate Phi-Phy representation (decoder block 14), which is computed once per query and reused across all flow steps.
The interface is deliberately generic: continuous state and action vectors of up to 32 dimensions, masked when unused, so the same model supports joint-space or end-effector control, delta or absolute targets, and one or two arms. The chunk length and control rate are properties of a training recipe, not of the architecture.
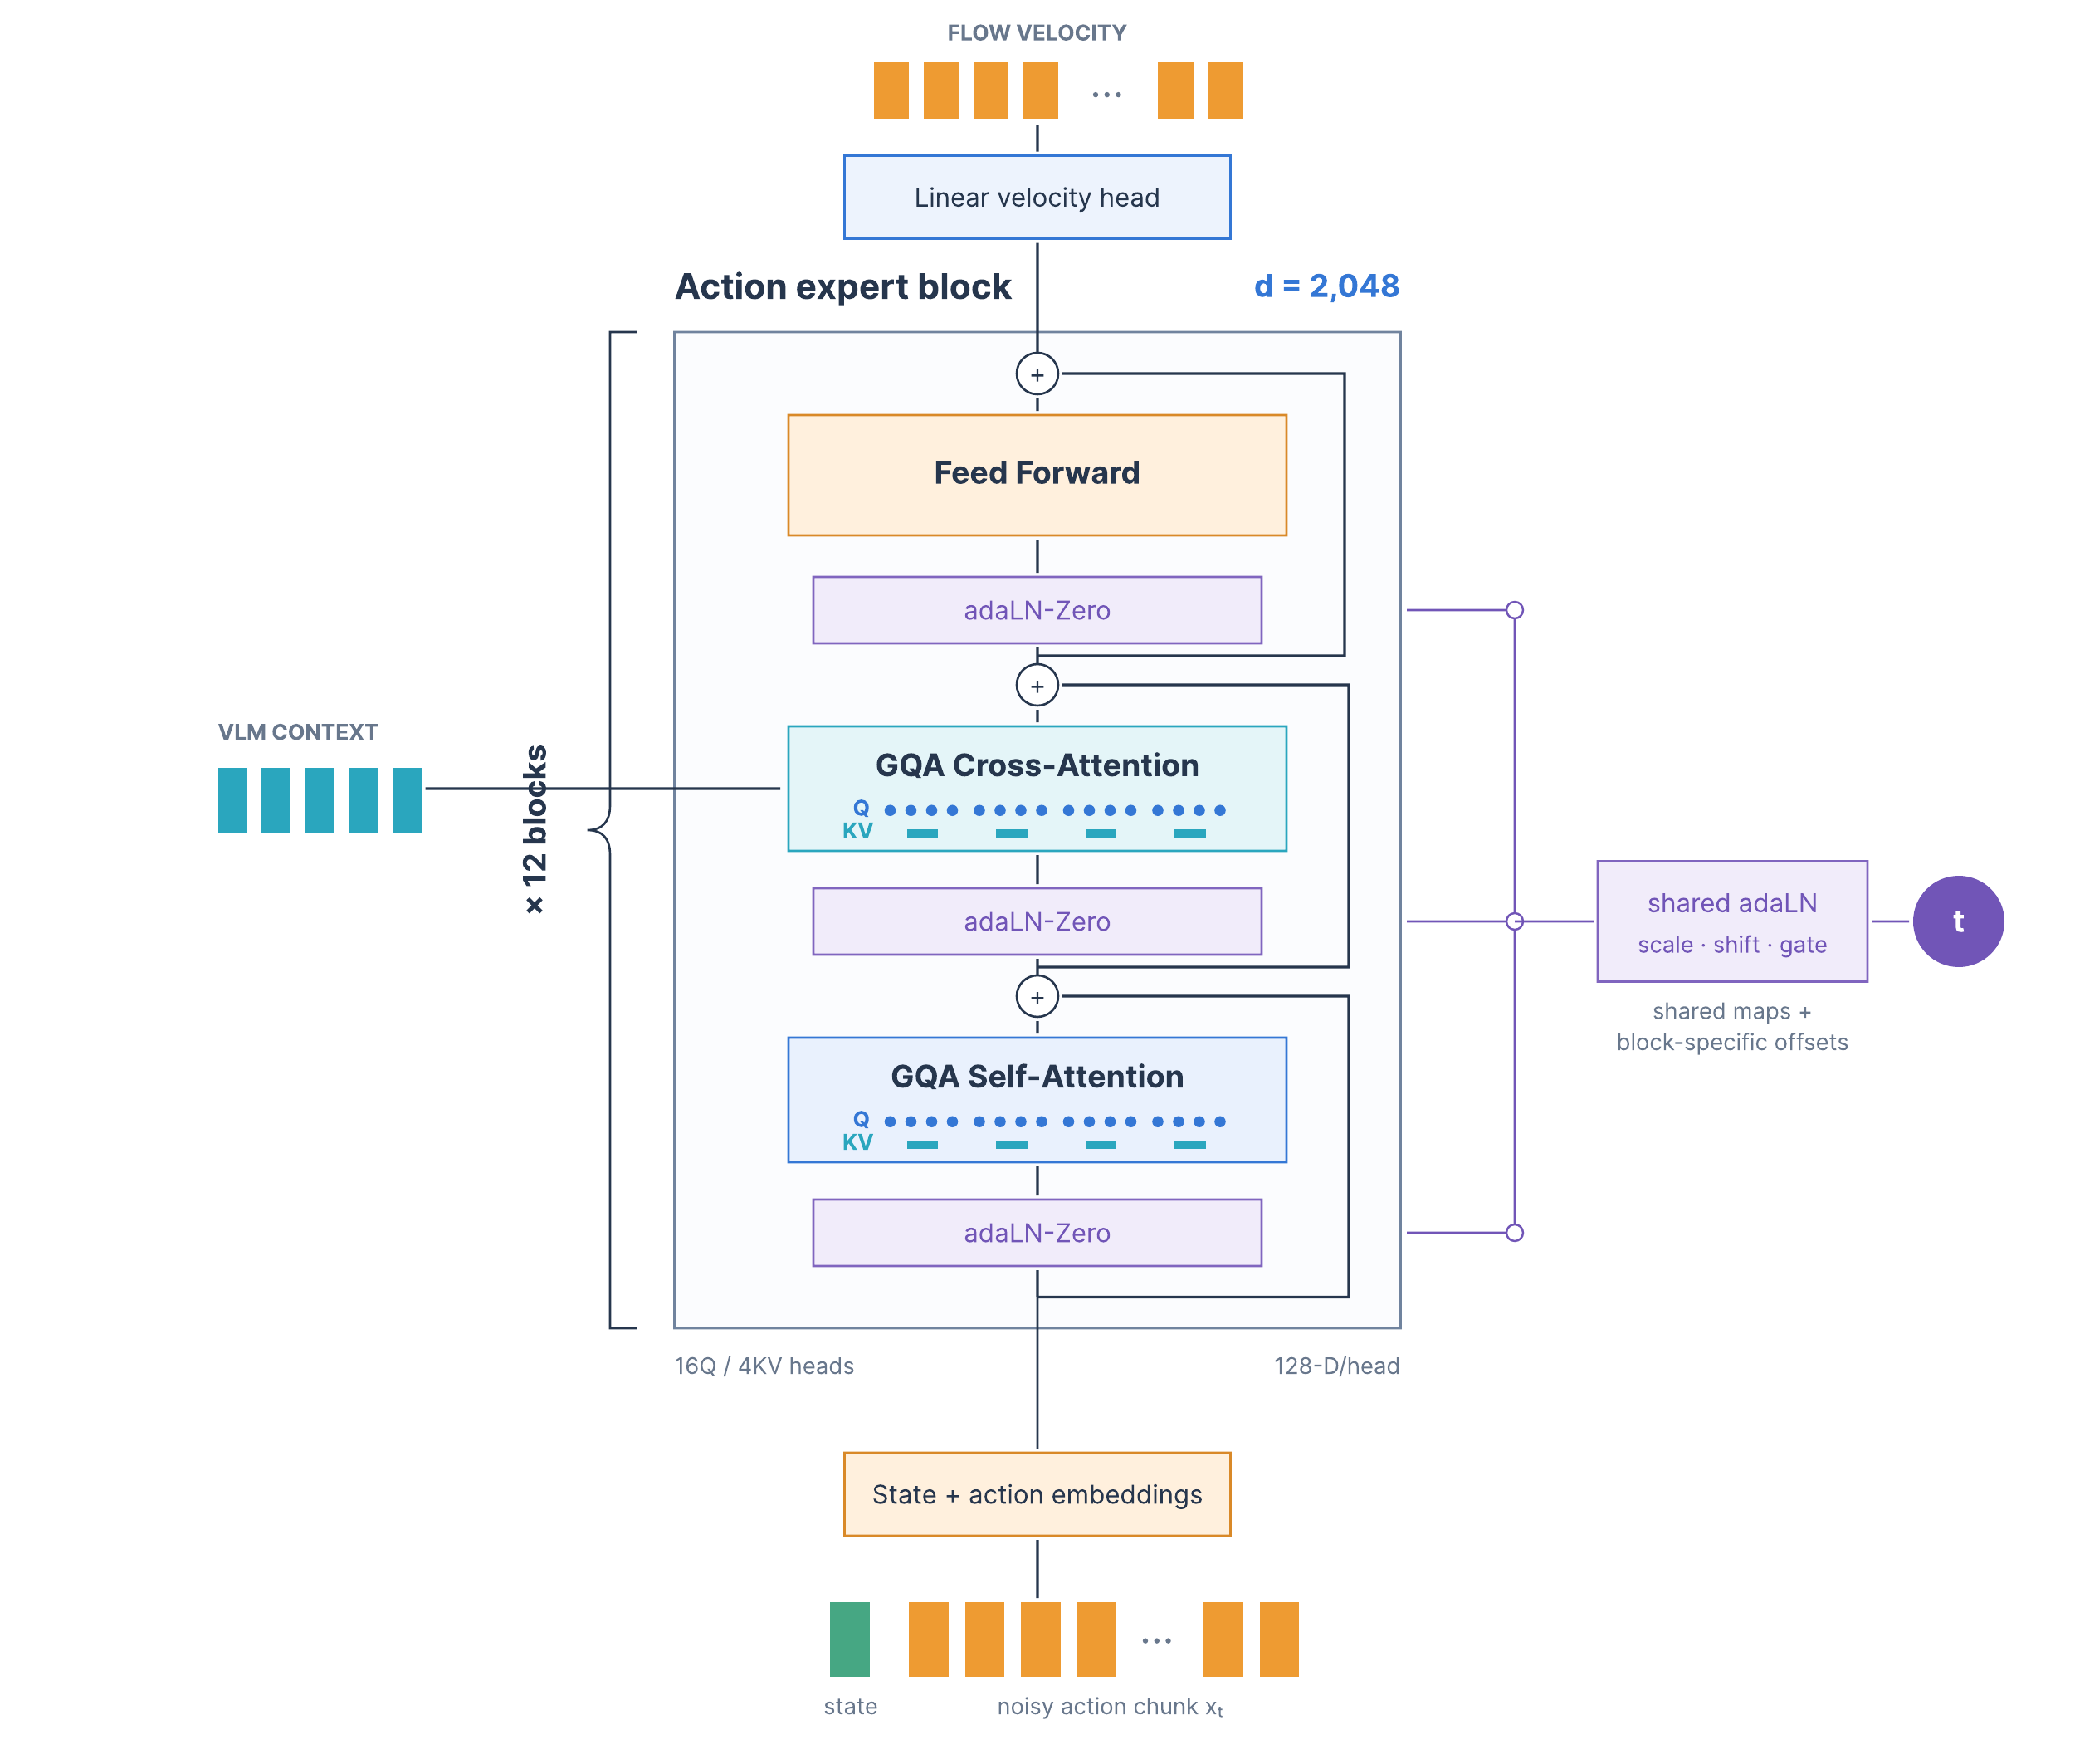
The action expert: state and noisy-action tokens pass through 12 wide transformer blocks with grouped-query self-attention, cross-attention to the VLM context, and feed-forward updates; the flow timestep conditions each block through shared adaLN maps with block-specific offsets.
Phi-Phy backbone
| Full vision-language model | 4.68B parameters | | ---------------------------- | ---------------------------------------------------------------------- | | Language decoder | 32 layers; width 3,072; MLP width 8,192 | | Vision encoder | SigLIP 2 SO400M NaFlex; 428M parameters | | Image representation | 16×16 patches; 256–3,600 visual tokens; camera views padded to 256×256 | | Cross-modal projector | MLP 1,152 → 3,072 → 3,072 with GELU | | Backbone context for actions | Decoder block 14; learned 3,072 → 2,048 projection |
Action expert
| Action expert | 542M parameters | | ---------------------- | ---------------------------------------------------------------------- | | Transformer | 12 blocks; width 2,048; MLP width 4,096 | | Attention | 16 query heads; 4 key/value heads; head dimension 128 | | Block structure | Action self-attention; cross-attention to VLM context; feed-forward | | Flow conditioning | Shared adaLN-single with block-specific offsets | | Flow target | Linear noise–action interpolation; velocity-prediction MSE | | State/action interface | Continuous vectors up to 32 dimensions; padding and loss masks | | Inference solver | 10 explicit Euler steps | | Prediction horizon | Configurable action-chunk length (≈1 s, up to 50 steps in pretraining) |
Phi-Phy starts from Microsoft's Phi family, chosen for capability per parameter. Its physical grounding adds public robotics-relevant sets (MGrounding, RefSpatial, XVR, RoboPoint), multi-image grounding, pointing, OCR, and counting data, and synthetic difference-spotting and odd-one-out questions to the general vision-language mix.
Embodiment midtraining
Midtraining halves the task data a robot needs
Two controlled experiments isolate what the midtraining stage buys. The first varies the amount of task data and holds compute fixed; the second holds the task data fixed and varies the amount of midtraining.
RoboTwin / Easy
Success rate (%)
0
20
40
60
80
100
28.1
40.6
42.9
50
52.5
58.1
65.2
65.6
12.5%
25%
50%
100%
Share of the finetuning dataset used
| RoboTwin Easy: success by finetuning data budget — Success rate (%)| Share of the finetuning dataset used | Rho-base (pretrained only) | Rho-RoboTwin (midtrained) | | ---------------------------------------------------------------------------------------------------------- | -------------------------- | ------------------------- | | 12.5% | 28.1% ± 1.3 | 40.6% ± 1 | | 25% | 42.9% ± 2.1 | 50% ± 3.8 | | 50% | 52.5% ± 2 | 58.1% ± 0.4 | | 100% | 65.2% ± 1.9 | 65.6% ± 2.2 |
RoboTwin / Hard
Success rate (%)
0
20
40
60
80
100
30.9
38.9
39.1
46.4
50
56.3
56.9
59.6
12.5%
25%
50%
100%
Share of the finetuning dataset used
| RoboTwin Hard: success by finetuning data budget — Success rate (%)| Share of the finetuning dataset used | Rho-base (pretrained only) | Rho-RoboTwin (midtrained) | | ---------------------------------------------------------------------------------------------------------- | -------------------------- | ------------------------- | | 12.5% | 30.9% ± 2 | 38.9% ± 2 | | 25% | 39.1% ± 2 | 46.4% ± 1.2 | | 50% | 50% ± 1.7 | 56.3% ± 1.4 | | 100% | 56.9% ± 1.2 | 59.6% ± 1.7 |
Success on the five held-out RoboTwin tasks (50 episodes per task) after 40k finetuning steps. Bars are means over seeds and whiskers show ± one standard deviation; the midtraining advantage is largest with little data and shrinks as the finetuning set grows.
60.0%Pretrained onlyRho-base finetuned directly
76.7%1 midtraining epochSame task data and budget
86.7%2 midtraining epochsThe released Rho-FR3-Duo
Bimanual plug insertion on FR3 Duo: success over 30 trials, with identical task data and finetuning budget in every condition.
Experiments on physical robots
Finetuned Rho variants vs. π0.5, GR00T N1.7, and MolmoAct2
The central experiments of the report finetune each midtrained Rho variant and the strongest open-weights VLAs on the same task demonstrations, then evaluate them side by side on the physical robot. Baselines start from their own pretrained checkpoints; MolmoAct2 is included on YAM Box because its training mix contains 720 hours from a similar dual-arm YAM robot. Rollouts follow a paired A/B protocol with matched initial configurations, 30 per task (60 on YAM Box), and no human intervention during a scored trial.
Every video in this section plays in real time. None is sped up.
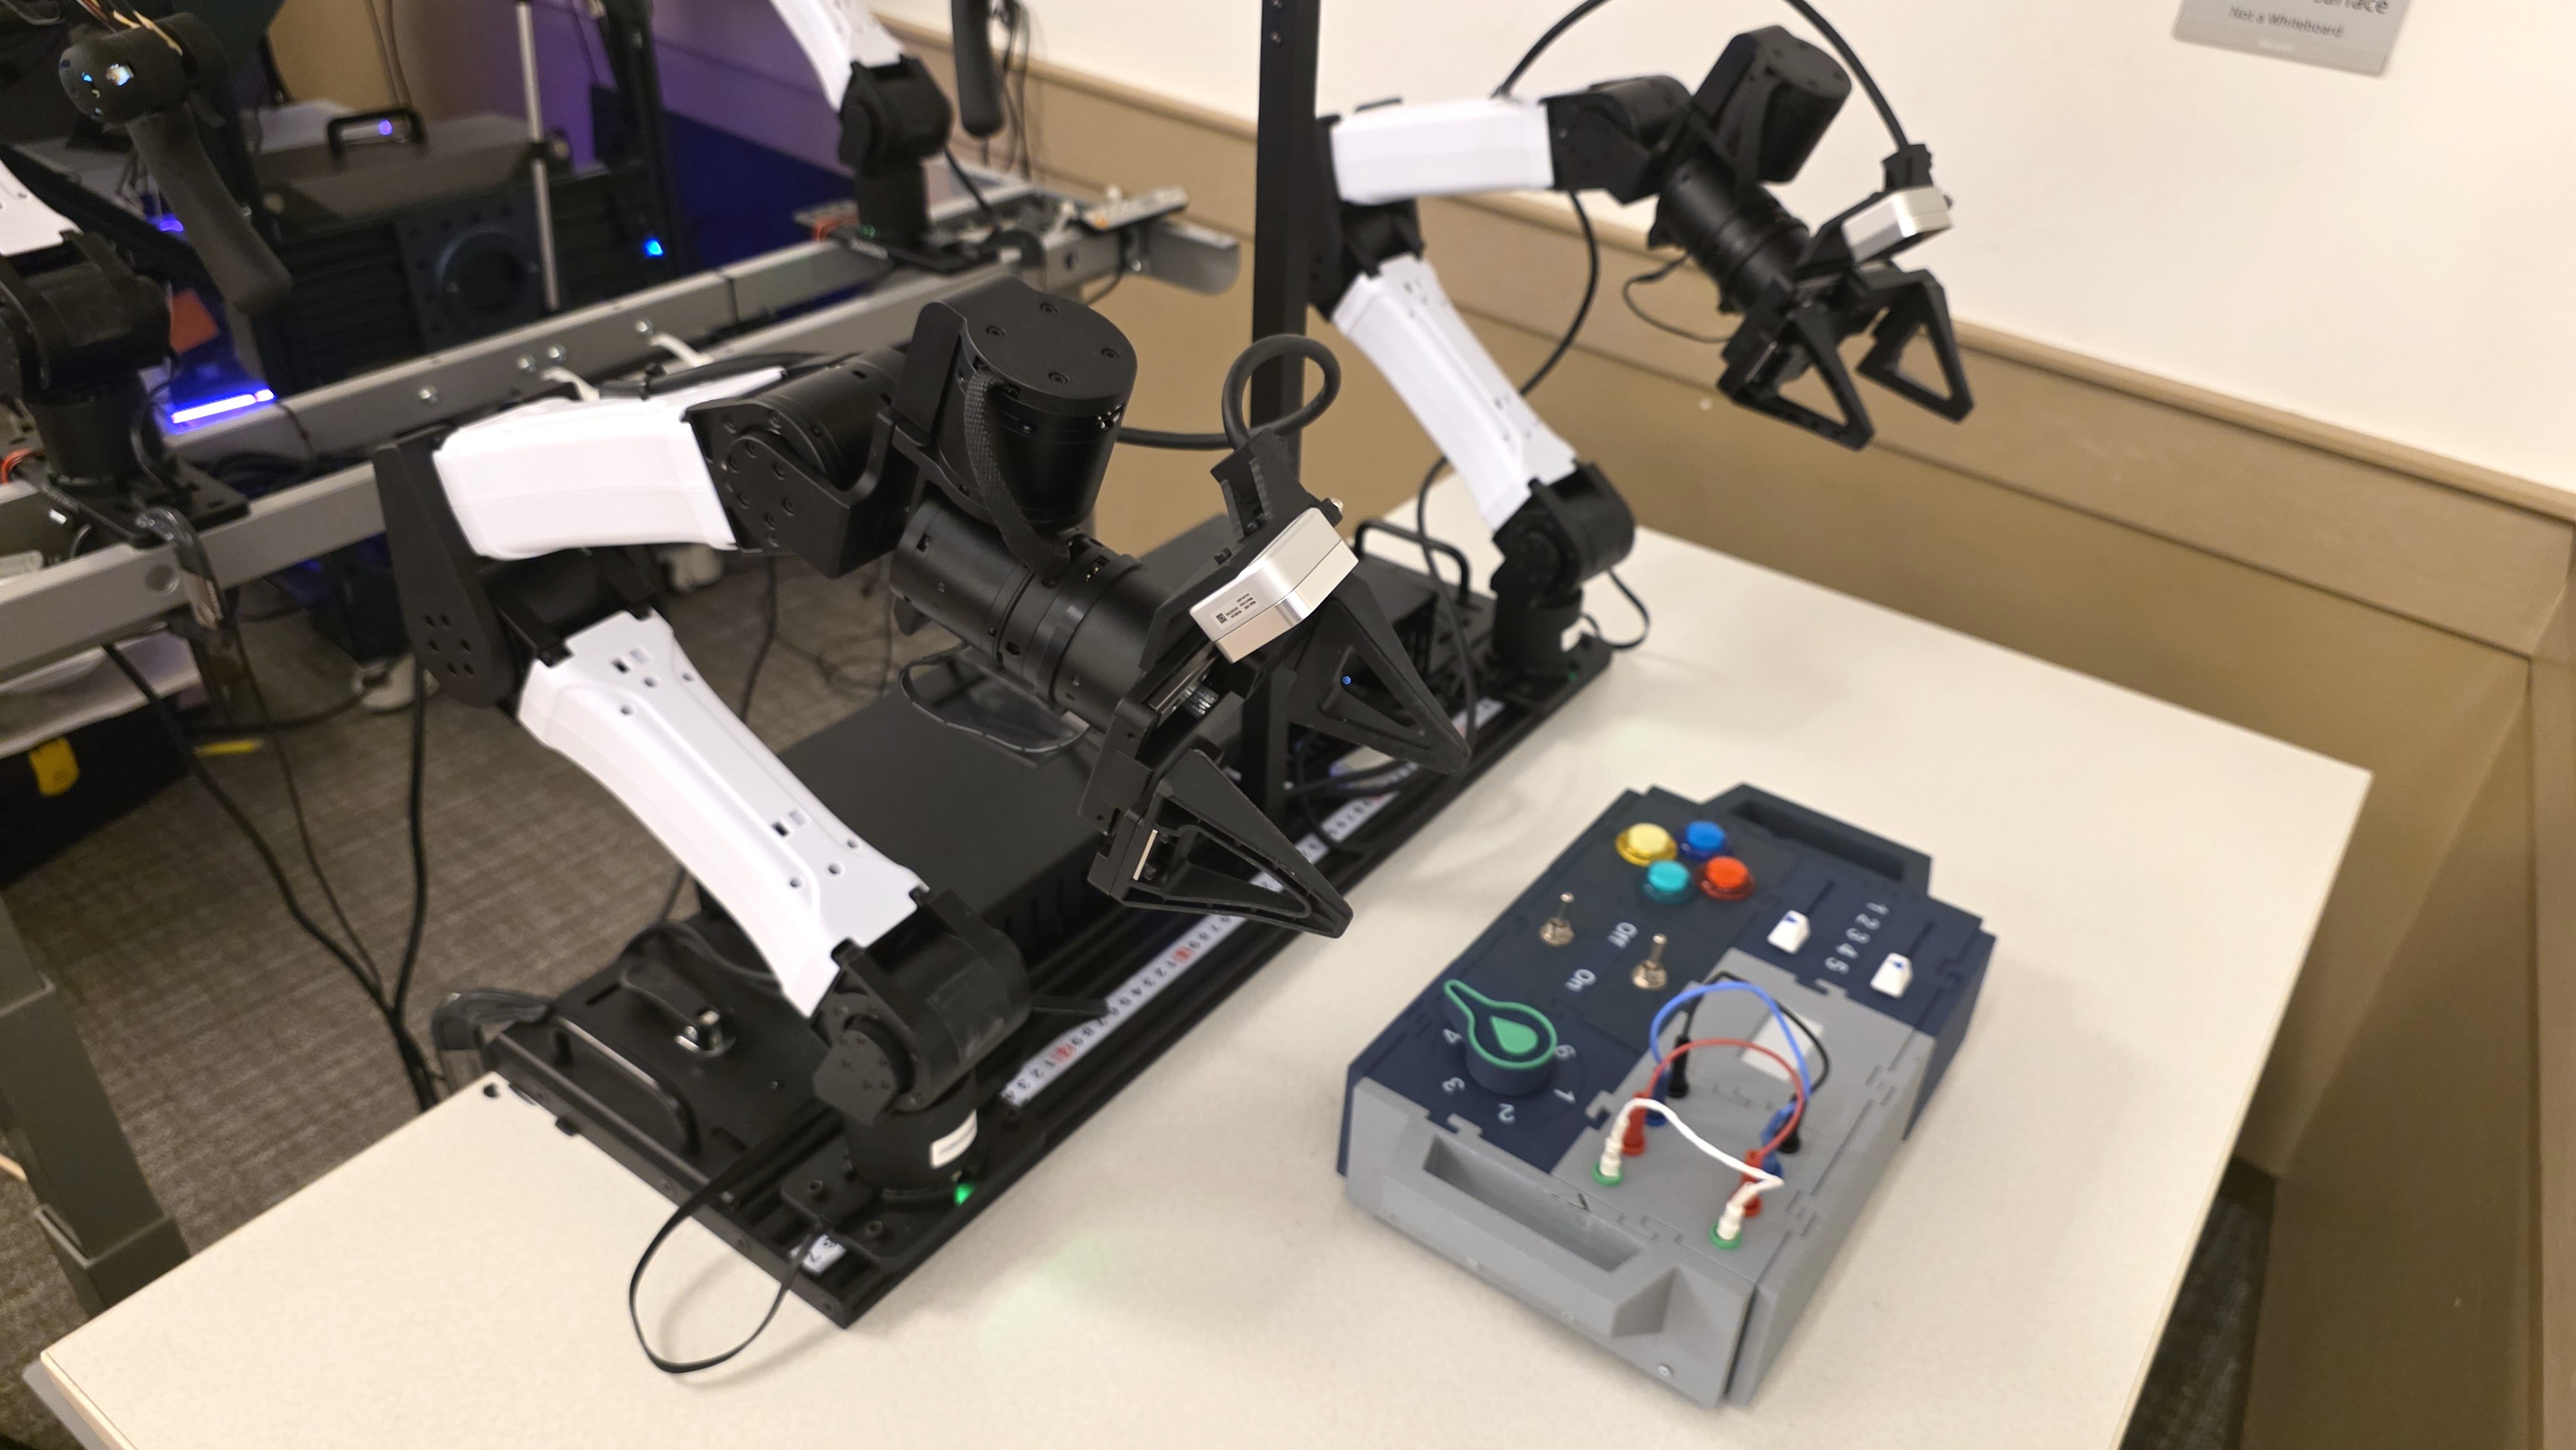
I²RT
YAM Box
2 × 6-DoF YAM arms · parallel-jaw grippers · 3 RealSense cameras.
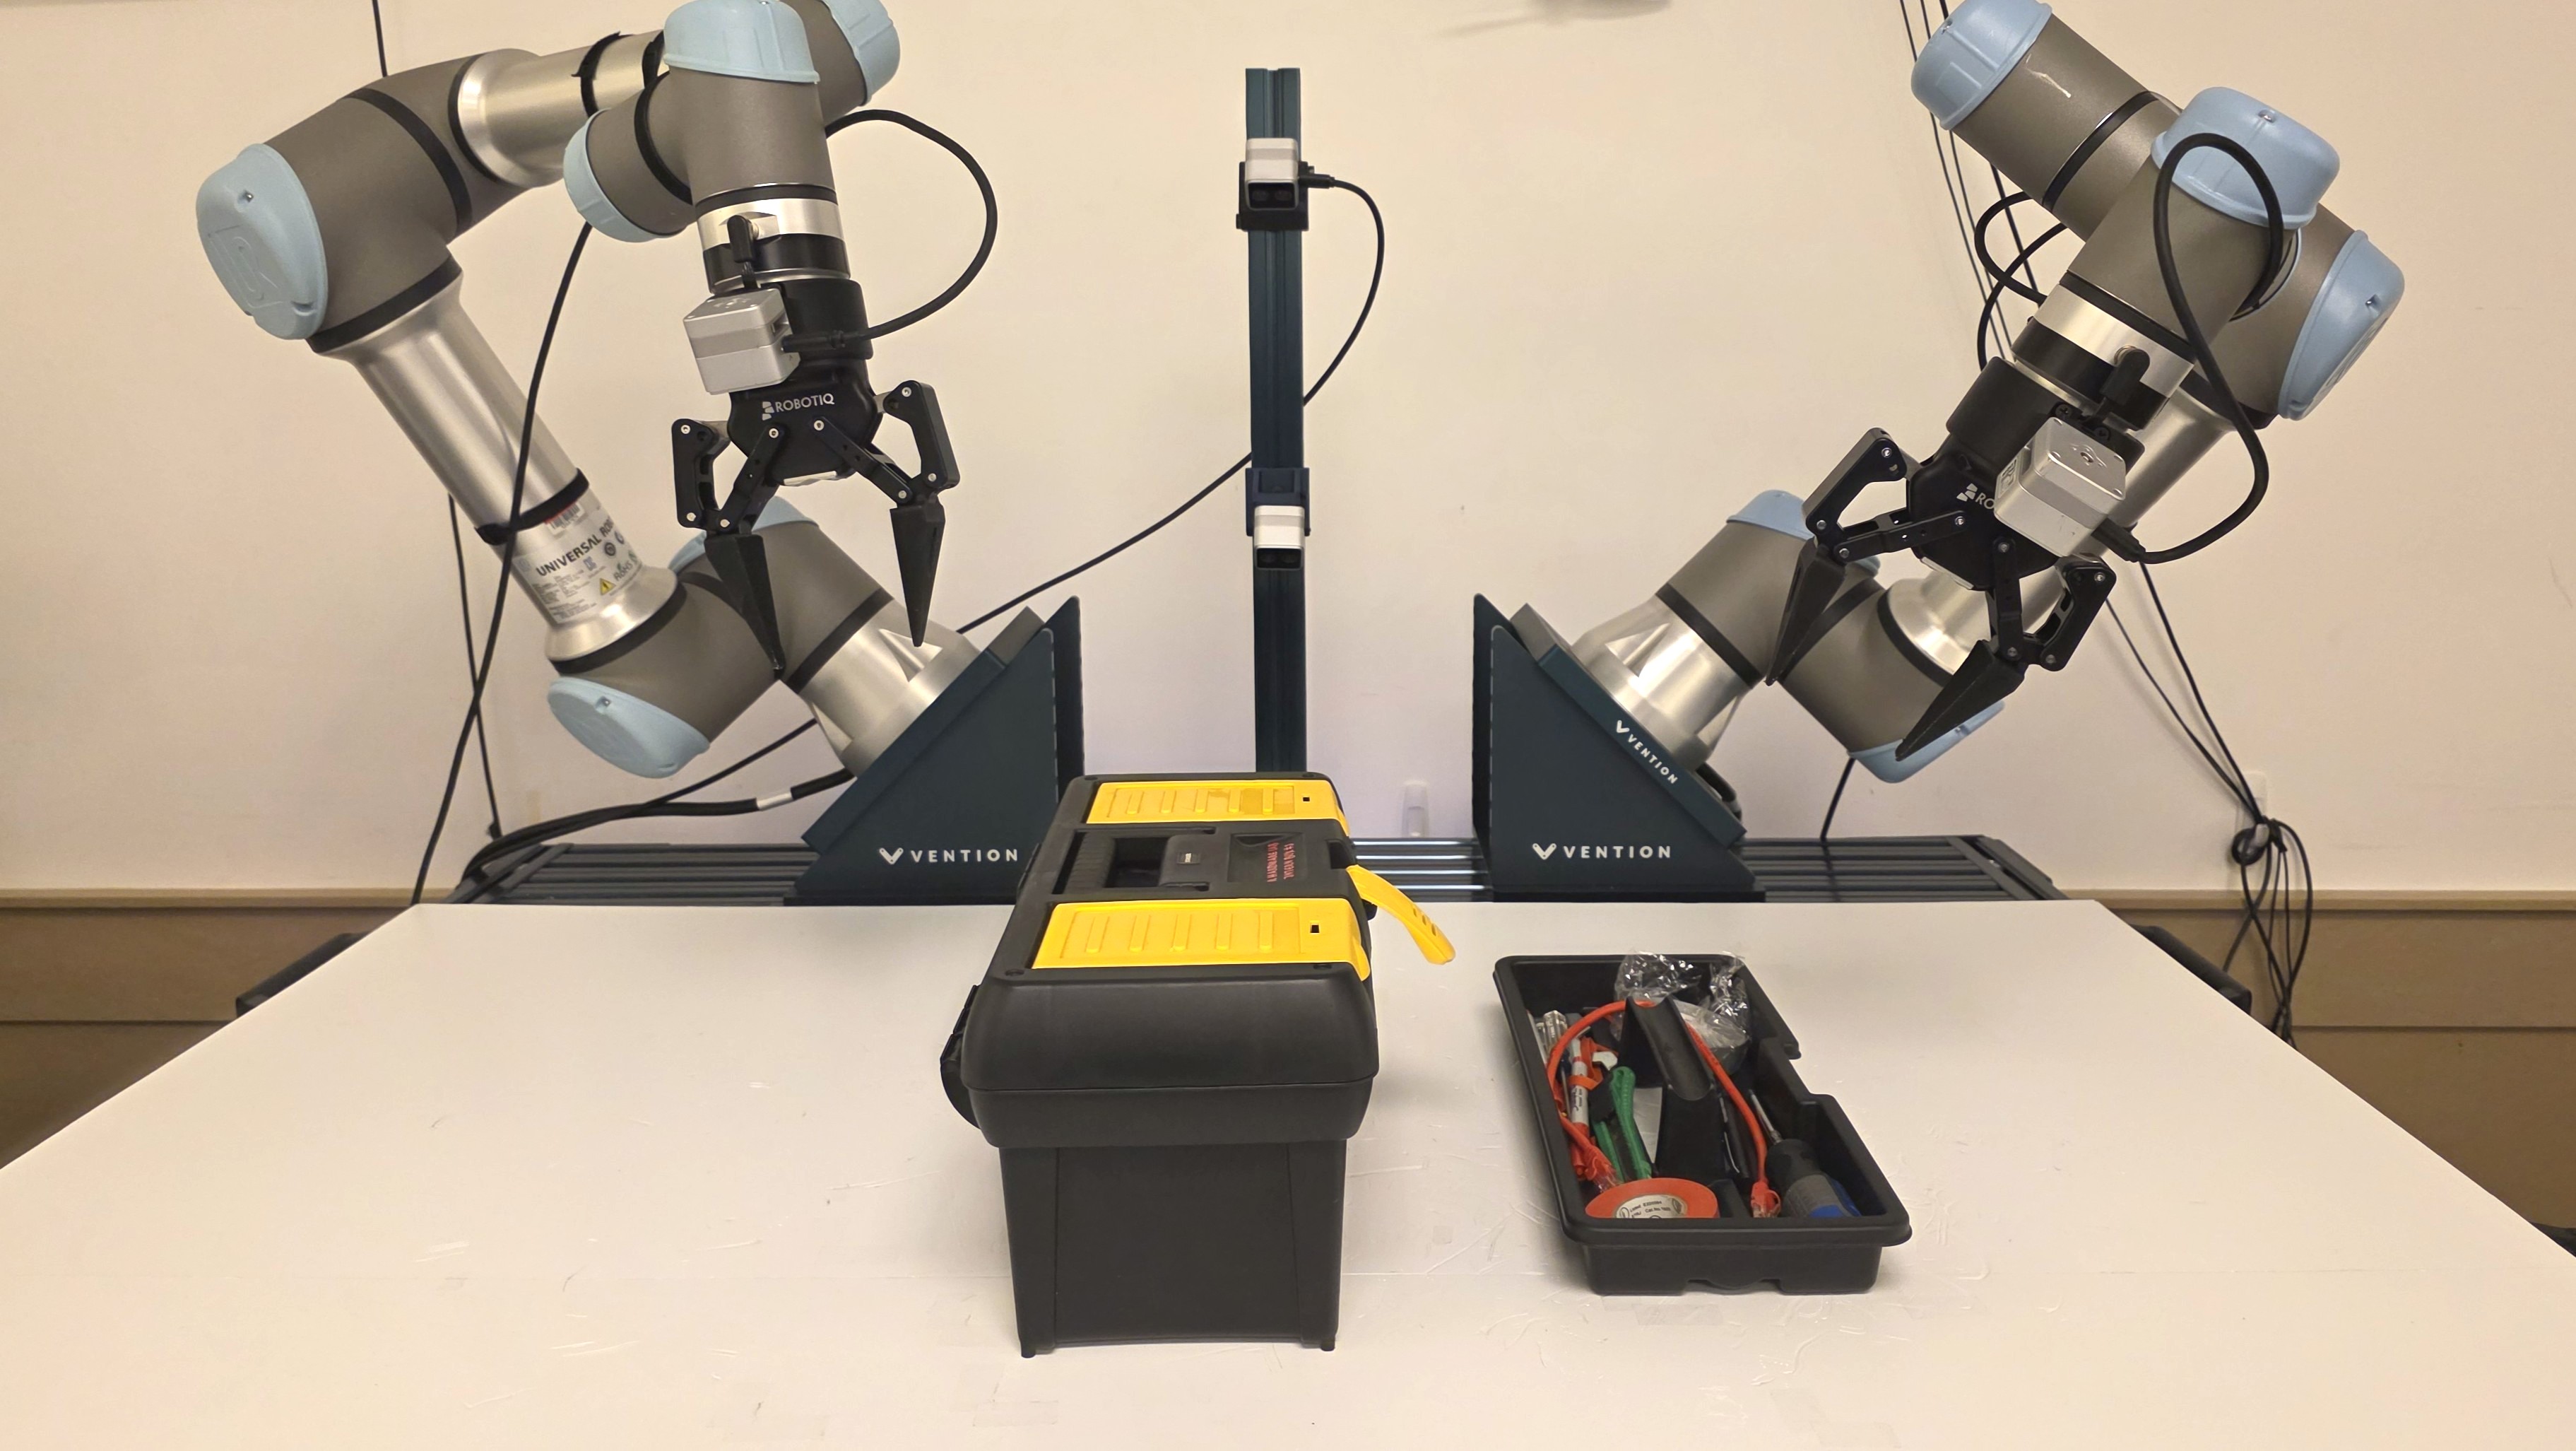
Universal Robots
UR AI Trainer
2 × UR5e arms · Robotiq 2F-85 grippers · 3 Orbbec cameras.
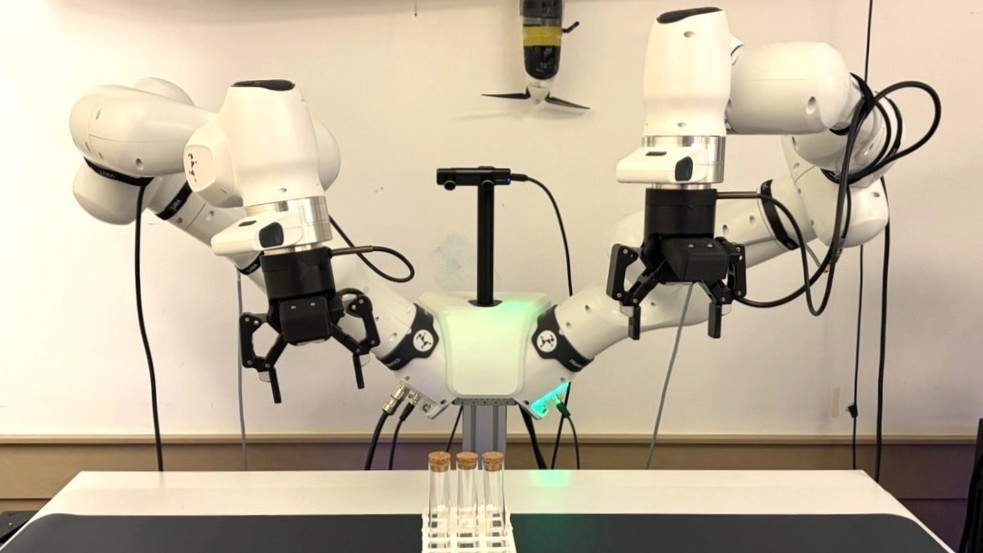
Franka
FR3 Duo
2 × 7-DoF FR3 arms · Robotiq grippers · ZED + 2 RealSense cameras.
On every platform Rho commands bimanual Cartesian end-effector targets (position, 6D orientation, gripper) from three RGB views and the two arm poses; the robot's controller turns them into joint commands.
YAM Box · high-data regime
BusyBox: strong performance with plentiful data
Rho-YAM-Box, π0.5, GR00T N1.7, and MolmoAct2 were each finetuned on about 2,000 demonstrations spanning the six task categories of the BusyBox benchmark — pushing illuminated buttons, flipping switches, moving sliders, turning a knob, pulling wires, and rotating or sliding the whole box — and evaluated over 60 rollouts with varied instructions and box poses. Rho-YAM-Box reaches 90% overall success, tied with π0.5 and ahead of GR00T N1.7 (53%) and MolmoAct2 (43%).
This result validates an important point: when finetuning data is copious, Rho's architecture and training recipe enable adaptation that is at least as robust as that of the strongest open-weights VLAs. π0.5 and MolmoAct2 are already familiar with YAM-Box-like robots from training on large amounts of Aloha-style and dual-YAM demonstrations; even so, finetuned Rho-YAM-Box is on par with π0.5 and ahead of MolmoAct2. Put differently, nothing in Rho's recipe prevents its finetuned policies from reaching high success rates when the dataset affords it. The finetuning dataset is released as microsoft/BusyBox.
Success rate (%)
0
20
40
60
80
100
100
100
90
60
80
100
80
20
90
60
30
50
100
80
30
50
90
100
60
40
80
100
30
40
90
90
53.3
43.3
Buttons
Switches
Sliders
Knob
Wires
Repositioning
Overall
| BusyBox success rate by task category — Success rate (%)| Task | Rho-YAM-Box | π0.5 | GR00T N1.7 | MolmoAct2 | | --------------------------------------------------------------- | ----------- | ---- | ---------- | --------- | | Buttons | 100% | 100% | 90% | 60% | | Switches | 80% | 100% | 80% | 20% | | Sliders | 90% | 60% | 30% | 50% | | Knob | 100% | 80% | 30% | 50% | | Wires | 90% | 100% | 60% | 40% | | Repositioning | 80% | 100% | 30% | 40% | | Overall | 90% | 90% | 53.3% | 43.3% |
Success rate on the six BusyBox task categories and overall; 10 rollouts per category per model.
Pushing buttons real time
Flipping switches (bimanual) real time
Moving sliders real time
Rotating the knob real time
Pulling wires real time
Repositioning the BusyBox real time
UR AI Trainer · low-data regime
Multi-stage tasks from \~150 demonstrations
Two long-horizon tasks, one policy per task: toolbox packing (\~150 demonstrations; lift a tray, fit it into a toolbox without spilling, close the lid, engage the latch) and small-electronics cleanup (\~160 demonstrations; pick two gripper-tip-sized components and place each into an empty tray compartment). Rho-UR-AI-Trainer reaches 53.4% success and 70.0% mean task progress overall, roughly double π0.5 (30.0% success) and well above GR00T N1.7 (15.0%).
Neither baseline has seen much dual-arm UR data, so their finetuning must learn the robot and the task together — the situation midtraining is designed to avoid. On electronics cleanup, π0.5 nearly matches Rho's task progress: it tends to fail at the final placement, while Rho's rarer failures happen at the pick.
Success rate (%)
0
20
40
60
80
100
46.7
20
16.7
60
40
13.3
53.4
30
15
Toolbox packing
Small-electronics cleanup
Overall
| UR AI Trainer success rate — Success rate (%)| Task | Rho-UR-AI-Trainer | π0.5 | GR00T N1.7 | | ---------------------------------------------------- | ----------------- | ---- | ---------- | | Toolbox packing | 46.7% | 20% | 16.7% | | Small-electronics cleanup | 60% | 40% | 13.3% | | Overall | 53.4% | 30% | 15% |
Mean task progress (%)
0
20
40
60
80
100
57.5
27.5
37.5
82.5
80.8
45.8
70
54.1
41.6
Toolbox packing
Small-electronics cleanup
Overall
| UR AI Trainer mean task progress — Mean task progress (%)| Task | Rho-UR-AI-Trainer | π0.5 | GR00T N1.7 | | ---------------------------------------------------------------- | ----------------- | ----- | ---------- | | Toolbox packing | 57.5% | 27.5% | 37.5% | | Small-electronics cleanup | 82.5% | 80.8% | 45.8% | | Overall | 70% | 54.1% | 41.6% |
Success rate (left) and mean task progress (right) over 30 rollouts per task. Task progress credits each completed stage of a task.
Toolbox packing real time
Small-electronics cleanup real time
FR3 Duo · precision and coordination
Five contact-rich task variants, 80% success
Three finetuning datasets yield five evaluation variants: plug insertion (\~150 demonstrations), tumbler stacking and unstacking (\~100), and test-tube racking and unracking (\~300). Rho-FR3-Duo achieves 80.0% success and 88.7% task progress overall, against 50.0% / 71.3% for GR00T N1.7 and 46.7% / 64.5% for π0.5, and leads on every variant. A likely explanation: a task's finetuning demonstration set covers only a narrow slice of the robot's workspace, so a model finetuned from a general checkpoint must infer the robot's reach and motion geometry from that slice while learning the task. Midtraining has already shown Rho-FR3-Duo a far broader range of poses and motions, which gives it a stronger start when, at deployment time, objects sit near the edge of, or outside, the configurations in the finetuning data.
Stacking and racking are harder than their reverses for every model, because they require holding precise alignment under contact. Rho's largest margins are exactly there: +33.3 points on tumbler stacking and +30.0 on racking over the best baseline, plus +20.0 on plug insertion.
Success rate (%)
0
20
40
60
80
100
80
40
60
70
26.7
36.7
93.3
53.3
56.7
63.3
33.3
23.3
93.3
80
73.3
80
46.7
50
Plug insertion
Tumbler stacking
Tumbler unstacking
Test-tube racking
Test-tube unracking
Overall
| FR3 Duo success rate — Success rate (%)| Task | Rho-FR3-Duo | π0.5 | GR00T N1.7 | | ---------------------------------------------- | ----------- | ----- | ---------- | | Plug insertion | 80% | 40% | 60% | | Tumbler stacking | 70% | 26.7% | 36.7% | | Tumbler unstacking | 93.3% | 53.3% | 56.7% | | Test-tube racking | 63.3% | 33.3% | 23.3% | | Test-tube unracking | 93.3% | 80% | 73.3% | | Overall | 80% | 46.7% | 50% |
Mean task progress (%)
0
20
40
60
80
100
90
70
80
85.8
45
70
95
60
68.3
75
63.3
48.9
97.8
84.4
89.4
88.7
64.5
71.3
Plug insertion
Tumbler stacking
Tumbler unstacking
Test-tube racking
Test-tube unracking
Overall
| FR3 Duo mean task progress — Mean task progress (%)| Task | Rho-FR3-Duo | π0.5 | GR00T N1.7 | | ---------------------------------------------------------- | ----------- | ----- | ---------- | | Plug insertion | 90% | 70% | 80% | | Tumbler stacking | 85.8% | 45% | 70% | | Tumbler unstacking | 95% | 60% | 68.3% | | Test-tube racking | 75% | 63.3% | 48.9% | | Test-tube unracking | 97.8% | 84.4% | 89.4% | | Overall | 88.7% | 64.5% | 71.3% |
Success rate (top) and mean task progress (bottom) over 30 matched initial configurations per variant.
Plug insertion real time
Tumbler stacking real time
Tumbler unstacking real time
Test-tube racking real time
Test-tube unracking real time
Online adaptation
After deployment, Rho keeps learning from corrections
A policy finetuned offline is only as good as the states in its demonstrations; once deployed, it will meet configurations where it is unreliable. Rho addresses this with an optional internal latent policy. Normally the action generator G starts its flow from Gaussian noise z; with the latent policy enabled, it starts from a learned, observation-conditioned z \= π(o) instead, so a \= G(o, π(o)). The backbone and action expert stay frozen; only this small module is trained, and it is stored and served inside the same checkpoint.
Training data comes from corrective takeovers (the FlowDAgger recipe): when a human — or, in simulation, a scripted expert — takes over, the actions actually executed are assembled into a chunk, inverted through the frozen flow to recover the latent that would have produced them, and used as a regression target for π. Online learning therefore changes where generation starts, while every action is still produced by the unchanged offline-trained model.
Meta-World (simulation)
A deliberately under-trained Rho policy on all 50 Meta-World tasks, adapted on six hard tasks with 50 scripted-expert episodes each. Success over 100 rollouts per task.
| Task | Offline | \+ Online | Gain | | ---------------- | ------- | --------- | ----- | | Assembly | 45.0% | 78.0% | +33.0 | | Stick pull | 58.0% | 78.0% | +20.0 | | Pick out of hole | 22.0% | 37.0% | +15.0 | | Hand insert | 73.0% | 86.0% | +13.0 | | Hammer | 92.0% | 100.0% | +8.0 | | Basketball | 55.0% | 61.0% | +6.0 | | Average | 57.5% | 73.3% | +15.8 |
FR3 Duo (physical robot)
Rho-FR3-Duo policies finetuned offline on 150 demonstrations per task, then adapted from 15 human-supervised episodes — a tenth of the offline budget — and evaluated on 10 hard configurations at the edge of the workspace, three trials each.
| Task · metric | Offline | \+ Online | Gain | | ----------------------------- | ------- | --------- | ----- | | Test-tube assembly · success | 30.0% | 70.0% | +40.0 | | Test-tube assembly · progress | 56.7% | 81.7% | +25.0 | | Plug insertion · success | 66.7% | 93.3% | +26.6 | | Plug insertion · progress | 83.3% | 96.7% | +13.4 |
Corrections on FR3 Duo are given with a SpaceMouse while the operator keeps emergency-stop authority; the learned policy can only change a bounded latent, and every generated action remains subject to the controller's joint, workspace, and action limits.
Simulation benchmarks
Rho-base on LIBERO and RoboEval
The simulation comparisons start from Rho-base rather than a midtrained variant and follow each benchmark's standard protocol, finetuning on the benchmark's own data. Rho's policies are adapted for 40k steps at batch size 128; success is averaged over three evaluation seeds or passes.
| Model | Spatial | Object | Goal | Long | Average | | --------------------------------------------------------- | ------- | ------ | ---- | ---- | ------- | | OpenVLA | 84.7 | 88.4 | 79.2 | 53.7 | 76.5 | | π0 | 96.8 | 98.8 | 95.8 | 85.2 | 94.2 | | MolmoAct-7B-D | 87.0 | 95.4 | 87.6 | 77.2 | 86.6 | | GR00T N1.7 | 95.0 | 100.0 | 98.0 | 93.0 | 96.5 | | π0.5 | 98.8 | 98.2 | 98.0 | 92.4 | 96.9 | | MolmoAct2 | 97.8 | 100.0 | 97.8 | 93.2 | 97.2 | | Rho | 98.3 | 99.6 | 97.6 | 95.9 | 97.9 |
Success rates in percent. Baseline values are taken from each model's report or official release, so adaptation and evaluation protocols may differ; Rho is the mean over three seeds.
Success rate (%)
0
20
40
60
80
100
Lift Pot
Lift Tray
Pack Box
Pick Book
Rotate Valve
Stack Book Shelf
Stack 2 Blocks
Cube Handover
Overall
| RoboEval success rate by task — Success rate (%)| Task | Rho-base | π0.5 | GR00T N1.7 | MolmoAct2 | | ------------------------------------------------------- | ----------- | ----------- | ------------ | ----------- | | Lift Pot | 71.3% ± 2.5 | 72% ± 1.7 | 72.3% ± 4.7 | 57.3% ± 3.1 | | Lift Tray | 98.7% ± 0.6 | 99.7% ± 0.6 | 96.7% ± 1.5 | 96.3% ± 0.6 | | Pack Box | 50.3% ± 6.3 | 53% ± 3.6 | 42.7% ± 6.4 | 28.3% ± 1.5 | | Pick Book | 84.7% ± 3.5 | 71.7% ± 3.8 | 60.7% ± 5.8 | 69% ± 3 | | Rotate Valve | 69.3% ± 1.5 | 57.3% ± 5.1 | 55.7% ± 6 | 59.7% ± 8.1 | | Stack Book Shelf | 77.3% ± 4 | 60.7% ± 2.5 | 37.3% ± 2.1 | 41.7% ± 5.1 | | Stack 2 Blocks | 55% ± 4.6 | 43.3% ± 2.9 | 53.7% ± 10.1 | 47% ± 9.8 | | Cube Handover | 80.3% ± 9.4 | 79.3% ± 3.2 | 64% ± 2.6 | 85.7% ± 1.5 | | Overall | 73.4% ± 1.2 | 67.1% ± 0.8 | 60.4% ± 2.6 | 60.6% ± 1.6 |
RoboEval task-level and overall success for Rho-base, π0.5, GR00T N1.7, and MolmoAct2. Whiskers show ± one standard deviation over three evaluation passes; hover a bar for its value.
RoboEval success rates as a table
| Task | Rho-base | π0.5 | GR00T N1.7 | MolmoAct2 | | ---------------- | ---------- | ---------- | ----------- | ---------- | | Lift Pot | 71.3 ± 2.5 | 72.0 ± 1.7 | 72.3 ± 4.7 | 57.3 ± 3.1 | | Lift Tray | 98.7 ± 0.6 | 99.7 ± 0.6 | 96.7 ± 1.5 | 96.3 ± 0.6 | | Pack Box | 50.3 ± 6.3 | 53.0 ± 3.6 | 42.7 ± 6.4 | 28.3 ± 1.5 | | Pick Book | 84.7 ± 3.5 | 71.7 ± 3.8 | 60.7 ± 5.8 | 69.0 ± 3.0 | | Rotate Valve | 69.3 ± 1.5 | 57.3 ± 5.1 | 55.7 ± 6.0 | 59.7 ± 8.1 | | Stack Book Shelf | 77.3 ± 4.0 | 60.7 ± 2.5 | 37.3 ± 2.1 | 41.7 ± 5.1 | | Stack 2 Blocks | 55.0 ± 4.6 | 43.3 ± 2.9 | 53.7 ± 10.1 | 47.0 ± 9.8 | | Cube Handover | 80.3 ± 9.4 | 79.3 ± 3.2 | 64.0 ± 2.6 | 85.7 ± 1.5 | | Overall | 73.4 ± 1.2 | 67.1 ± 0.8 | 60.4 ± 2.6 | 60.6 ± 1.6 |
0.85Task progressionHighest of the compared models
1.41 mCartesian path lengthShortest of the compared models
7.70 / 4.69 radJoint / orientation path lengthShortest of the compared models
Beyond success, RoboEval reports behavioral metrics. Rho leads on five of nine; π0.5 has the fewest environment collisions, and MolmoAct2 the lowest gripper-height difference, self-collision count, and slip count.
Ablations
Why Rho is built the way it is
Architecture design choices were selected on RoboEval, where each candidate was pretrained on a 15% subset of Rho-Tomyum and then adapted for 40k steps; success is the mean over eight tasks and three evaluation passes. Two dimensions mattered: 128-dimensional attention heads beat both smaller and larger heads at either width, and width 2,048 beat 1,024 even when the narrower expert was made twice as deep. The gains concentrate on contact and precision tasks — lifting a flat book, stacking blocks, shelving a book — where successful action chunks occupy a narrow region of action space and the velocity field must be resolved finely around it.
Shape sweep (RoboEval success after 40k adaptation steps)
| Width | Heads | Head dim. | Blocks | Success | | ----- | ----- | --------- | ------ | ------- | | 1,024 | 16 | 64 | 16 | 61.7% | | 1,024 | 8 | 128 | 16 | 64.0% | | 1,024 | 8 | 128 | 32 | 64.2% | | 2,048 | 8 | 256 | 16 | 62.3% | | 2,048 | 16 | 128 | 16 | 67.3% |
Compression (width 2,048 and head dim. 128 kept fixed)
| Variant | Q / KV heads | Blocks | Params | Success | | -------------------------- | ------------ | ------ | ------ | ------- | | Wide baseline | 16 / 16 | 16 | 1.649B | 67.3% | | \+ shared adaLN | 16 / 16 | 16 | 882M | 67.3% | | \+ grouped-query attention | 16 / 4 | 16 | 693M | 67.2% | | \+ 12 blocks (Rho) | 16 / 4 | 12 | 542M | 67.1% |
Sharing the adaLN modulation maps, grouped-query attention, and a 12-block depth cut the expert from 1.65B to 542M parameters — about two thirds — at the same success rate. Routing successive blocks to different backbone layers was also tried and was worse (60.5% vs 67.3%), so every block reads decoder block 14.
Pretraining recipe
Keeping vision-language batches in the pretraining mix helps most on tasks with semantic and temporal structure: on LIBERO at 20k adaptation steps it lifts the Goal suite from 94.7% to 97.7% and the Long suite from 92.7% to 96.0% relative to robot-only pretraining. A learning-rate sweep for the action expert selected 10⁻⁴; the choice affects the quality of the transferred initialization, not just early adaptation speed.
67.3%Robot + vision-language pretrainingRho's recipe
65.2%Robot-only pretrainingSame robot data, no VQA batches
61.0%No pretrainingGrounded backbone, fresh action expert
RoboEval success rate after 40k adaptation steps; the pretrained variants use the same 15% subset as the ablations above. Pretraining on robot data lifts success by about four points over a fresh action expert, and keeping vision-language batches in the mix adds two more.
Release
Models, data, code, technical report
We release Rho-base together with the three embodiment-midtrained checkpoints, code to finetune them offline and adapt them online, and the BusyBox finetuning dataset collected on YAM Box.
Code and paper
rhoboticsFinetuning, online adaptation, and evaluation codeTechnical reportFull recipe, protocols, and ablations (arXiv)
Citation
If you use Rho in your research, please cite the technical report:
@article{rhoteam2026rhofoundationefficientlyadaptable,
      title={Rho: A Foundation for Efficiently Adaptable VLA Models},
      author={Rho Team and Simran Bagaria and Daphne Chen and Dean Fortier and Jianlong Fu and Michael Harrison and Tess Hellebrekers and Neel Joshi and Andrey Kolobov and Dalton Moore and Galen Mullins and Michael Murray and Eduardo Salinas and Reuben Tan},
      year={2026},
      journal={arXiv preprint arXiv:2609.38164},
      url={https://arxiv.org/abs/2609.38164}
}
Models
Start from a midtrained checkpoint if you have one of the three robots; start from Rho-base to midtrain a new platform or to adapt to a different one directly.
rho-basePretrained foundation modelrho-yam-boxMidtrained for I²RT YAM Boxrho-ur-ai-trainerMidtrained for Universal Robots AI Trainerrho-fr3-duoMidtrained for Franka FR3 Duorho-liberoRho-base finetuned on LIBEROrho-roboevalRho-base finetuned on RoboEval
Data
roboeval-data-for-rhoRoboEval finetuning data from Rho experimentslibero-data-for-rhoLIBERO finetuning data from Rho experimentsBusyBox dataset\~2,000 YAM Box demonstrations across six task categories; the finetuning set used in the YAM Box experiments
Scope and responsible use. The strongest-model claims hold for the baselines, budgets, and protocols in the report; results on three platforms and a handful of benchmarks do not establish universal generalization. Offline adaptation still depends on representative demonstrations, and online adaptation should run under human supervision with platform-specific safeguards, workspace constraints, and evaluation gates before deployment.