POSITRON
$875MSeries C
$5BValuation
Co-Led byNEA · Atreides Management · Valor Equity Partners · Andra Capital · Dylan Patel's SemiAnalysis Capital · Jim Clark

POSITRON

Accelerating Intelligence
Purpose-built hardware for the age of generative AI
Delivering the highest performance, lowest power, and best TCO for Transformer model inference at any scale.
Our Products
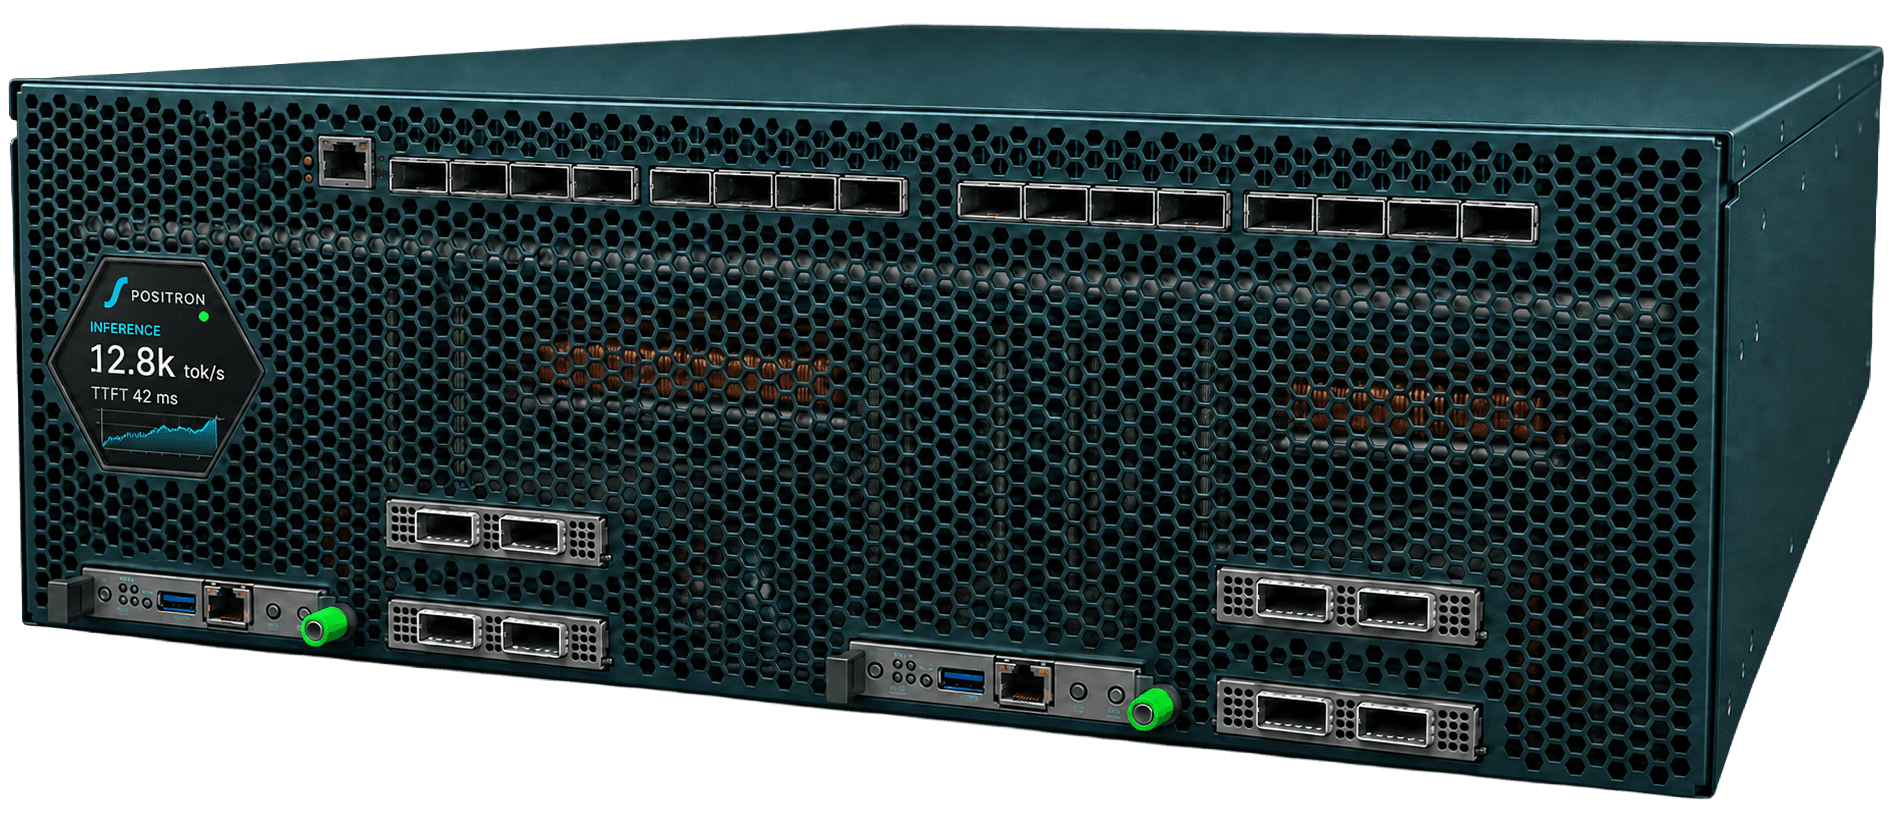
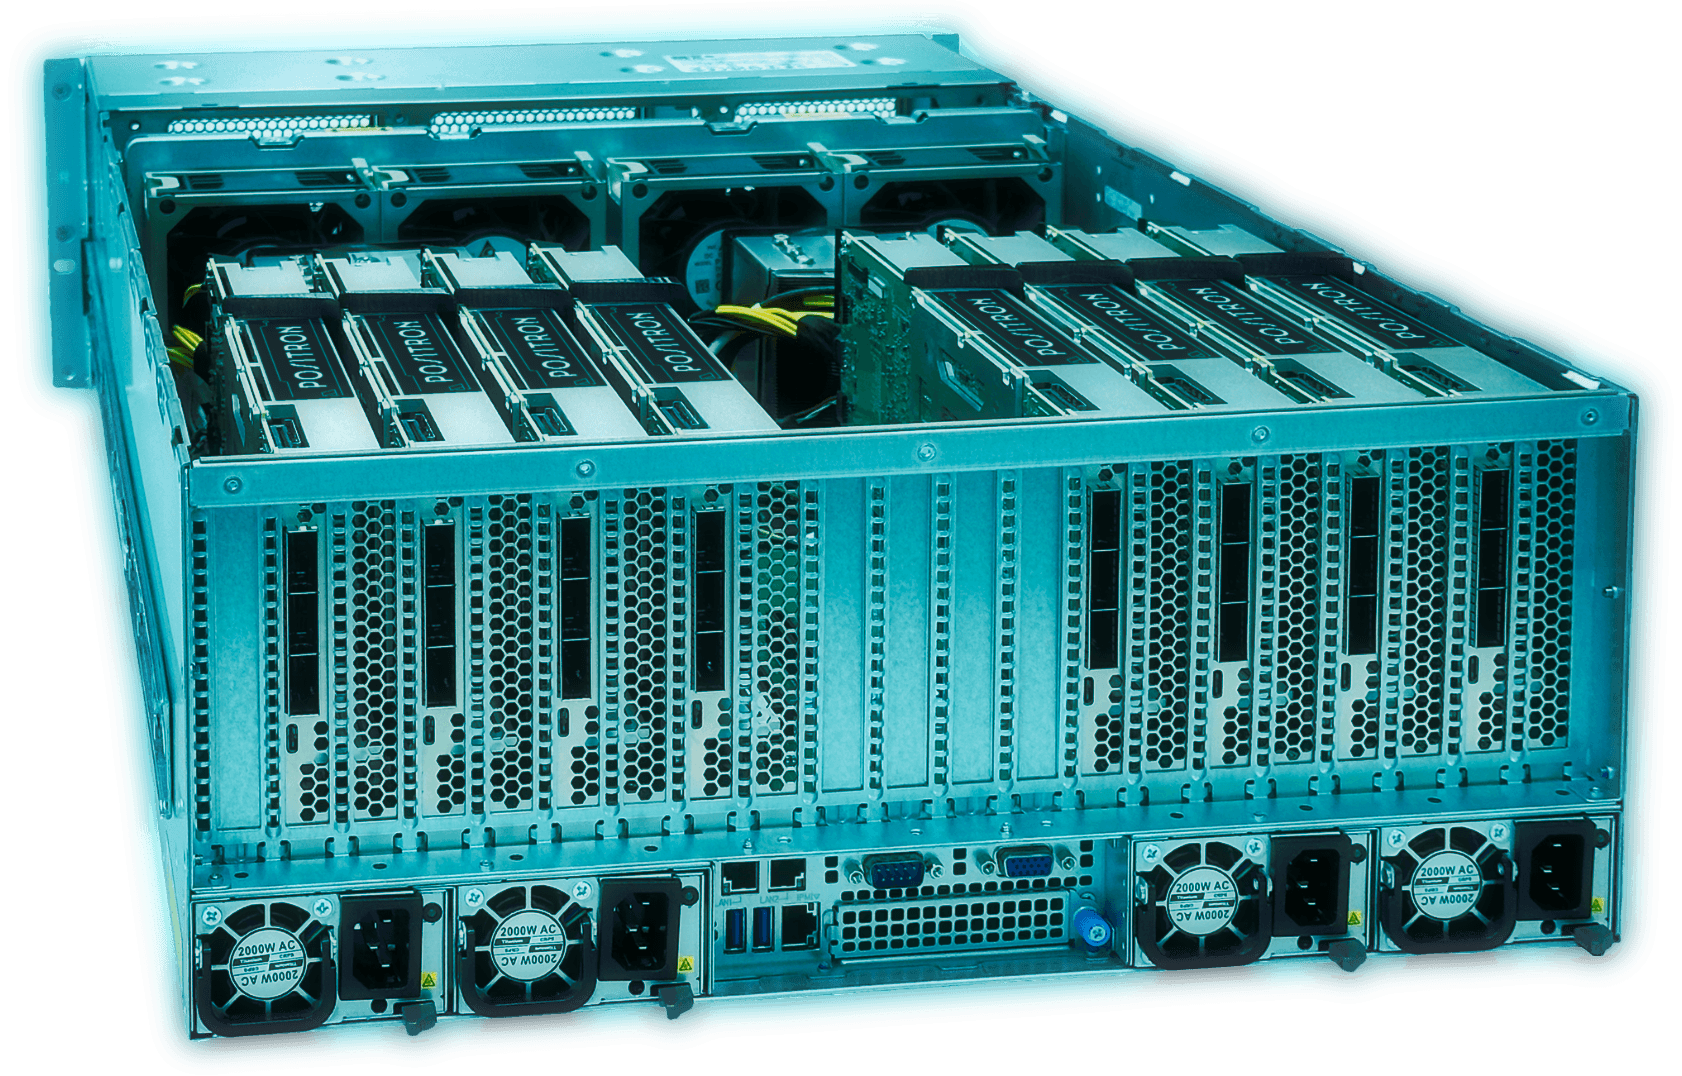 Shipping Now
 Production-ready inference appliance supporting up to 500B Parameter Models
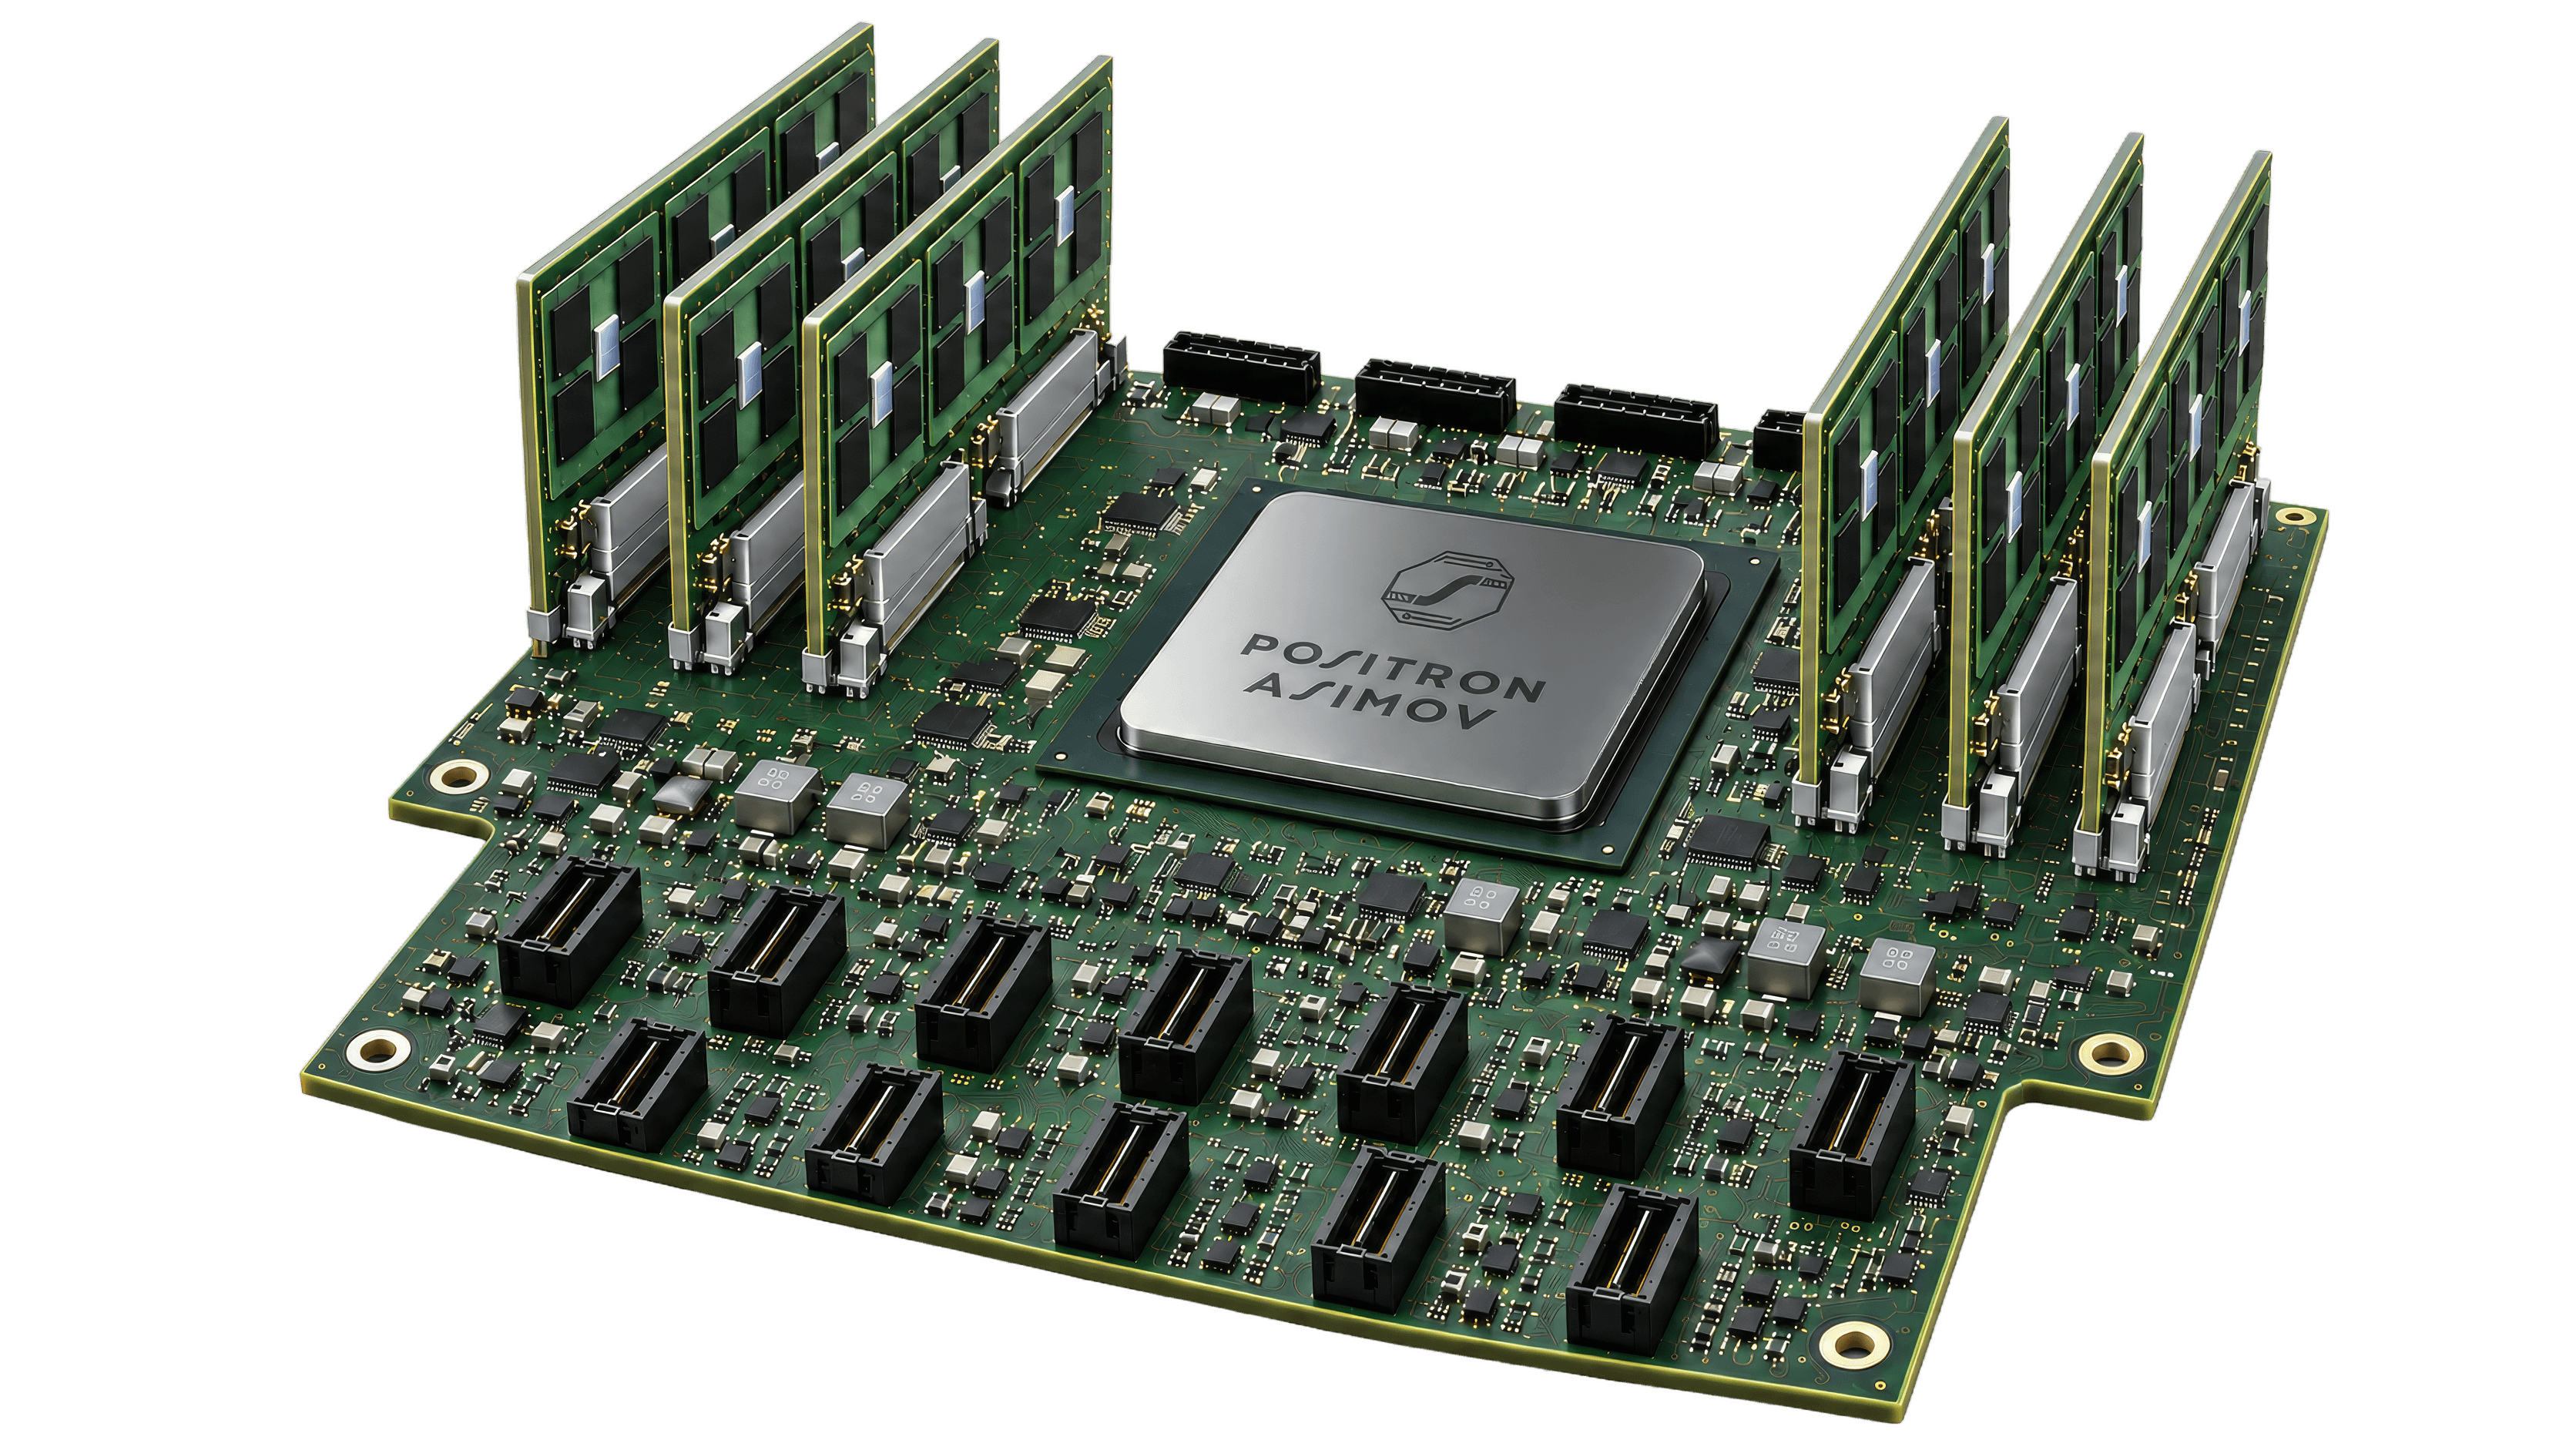
 Coming in 2027
 Superintelligence-in-a-Box with up to 18.4TB Asimov memory, powered by 4 or 8 Asimov chips
 Coming in 2027
 Purpose-built AI inference accelerator silicon with up to 2.3TB memory per chip
 Our VisionThe Positronic BrainOur worldview on AI infrastructure and the future we're building
Every Transformer Runs on Positron
Supports all Transformer models seamlessly with zero time and zero effort
Positron maps any trained HuggingFace Transformers Library model directly onto hardware for maximum performance and ease of use
Step 1

.pt
.safetensors
Develop or procure a model using the HuggingFace Transformers Library
Step 2
Drag & Drop to Upload
or
BROWSE FILES
Upload or link trained model file (.pt or .safetensors) to Positron Model Manager
Step 3
from openai import OpenAI client = OpenAI(uri="api.positron.ai")
client.chat.completions .create( model="my_model" )
Update client applications to use Positron's OpenAI API-compliant endpoint
Positron Delivers
24.8×
revenue per TCO dollar
Faster tokens.
Greater earning potential.Asimov at 400 vs. Blackwell at 170 tokens/sec/user, assuming a 2× token selling price for the faster tier.
Faster inference already commands premium token pricing: Claude Fast Mode charges 2× standard rates, and GPT-5.5 launched with Priority processing at 2.5×.
Total tokens per dollar vs. interactivity
DeepSeek R1 0528 671B · FP4 · 8K input / 1K output
Per $Per MW
Positron Asimov TitanRack (Simulated)NVIDIA Blackwell GB300 NVL72
Total tokens per dollar vs. generation speedPositron Asimov TitanRack cycle-accurate simulations versus NVIDIA Blackwell GB300 NVL72. Both axes use linear scales and actual units, focused on 75 to 450 tokens per second per user. Points one and two compare efficiency at 100 and 170 tokens per second per user. Point three compares speed at equal tokens per dollar. At 400 tokens per second per user, Asimov is approximately 4.1 times as fast at that efficiency.Total tokens per TCO dollar02M4M6M8M10M75100170250350450Generation speed (tokens/sec/user)123
① At 100 tokens/sec/user
2.4×
tokens per dollar
5.7M vs. 2.4M tokens/$
② At 170 tokens/sec/user
26×
tokens per dollar
5.7M vs. 221K tokens/$ @ Blackwell’s maximum shown speed
③ At 400 tokens/sec/user
4.1×
faster tokens at equal cost per token
400 vs. 97 tokens/sec/user at 2.7M tokens/$.
Asimov performance is based on cycle-accurate simulations. GPU data: SemiAnalysis InferenceX.
Comparisons, pricing assumptions & sources
Points 1 and 2 compare the devices at equal generation speed. Point 2 is near Blackwell’s maximum shown interactivity. Point 3 holds the Y-axis value constant and compares Asimov at 400 tokens/sec/user with the point on Blackwell’s curve at the same efficiency. The Point 3 callout lists both generation speeds and their shared efficiency.
The dollar view uses total tokens per modeled TCO dollar (capital and operating costs) under neocloud ownership assumptions. The power view uses token throughput per all-in utility MW. Axes use actual units and linear scales. The chart focuses on 75–450 tokens/sec/user; the Y axis starts at zero and scales to the values in that range.
The premium-tier scenario compares Asimov at 400 tokens/sec/user with Blackwell at its maximum shown speed of 170 tokens/sec/user. Revenue gain = token efficiency at those operating points × a 2× selling-price multiplier. It assumes the same 8K/1K token mix and the same sold share of generated tokens, with both input and output prices doubled for the faster tier. No absolute selling price is assumed. These are revenue ratios, not profit margins or additional speed gains.
As a market reference, Anthropic lists Claude Opus 5 and 4.8 Fast Mode at $10 input / $50 output per million tokens, versus $5 / $25 standard, and advertises up to 2.5× higher output speed (accessed September 10, 2026). OpenAI also launched GPT-5.5 Priority processing at 2.5× standard rates. These published serving tiers demonstrate premium pricing for faster inference. The revenue comparison above uses a 2× selling-price multiplier.