

Introducing Extract v2.5
Higher accuracy across extraction tasks
- Higher accuracy across extraction tasks
- Long lists
- Records spanning pages
- Scanned forms
- Advanced Citations
- How we built v2.5
- Try v2.5 on your documents
Today we’re introducing Extract v2.5, a new generation of our schema-based document extraction agents. This release brings accuracy improvements across all tiers as well as enhanced grounding capabilities to our highest tiers, Agentic and Agentic Plus. These improvements come with no increase in per-page pricing, ensuring higher performance per dollar no matter which tier you are using.
On ExtractBench, accuracy improved across all three tiers. Cost Effective now outperforms the previous Agentic tier, rising from 87.1 to 93.9 overall value F1, and Agentic outperforms the prior Agentic Plus, improving from 89.8 to 95.8. Agentic Plus, our highest-accuracy tier, rises from 95.1 to 96.4.
VALUE F1 V2.0V2.5 85 90 95 87.1 89.8 95.1 COST EFFECTIVE 93.9 AGENTIC 95.8 AGENTIC PLUS 96.4 $0.00$0.02$0.04$0.06$0.08$0.10 AVERAGE COST PER PAGE (USD)
Under the hood, we made architectural enhancements that contribute to these performance improvements, including a new agent harness, purpose-built for document extraction. We took inspiration from the latest coding agents, and hyper-tuned everything around the models to handle the real failure modes in document extraction, across vision, reasoning, and verification. The result is a specialized agent that can cross-reference context from multiple pages, and ground values in exact sources.
The first change is Structural Reasoning. We use structural reasoningover document representations for more efficient and tailored extraction based on document type, layout, and information density. Extract will adaptively reason and spend effort for your more complex docs to deliver maximum accuracy. For the less complex docs, it’ll process with lower latency and target its effort.
This release introduces Advanced Citations for Agentic and Agentic Plus, helping locate supporting evidence for extracted values. ExtractBench grounding scores rise from 46.8 to 80.6 for Agentic and from 46.4 to 82.2 for Agentic Plus, which means more correct and well fit bounding boxes for even your most complex layouts and extractions.
SCORE EXTRACTION APISLLMSV2.0V2.5 0 20 40 60 80 44.3 46.8 46.4 SONNET 5.5 63.2GPT-6 SOL 77.6OPUS 5.5 77.5REDUCTO DEEP EXTRACT 50.8EXTEND MAX 21.8 COST EFFECTIVE 54.3 AGENTIC 80.6 AGENTIC PLUS 82.2 $0.00$0.02$0.04$0.06$0.08$0.10$0.12$0.14$0.16 AVERAGE COST PER PAGE (USD)
Higher accuracy across extraction tasks
These improvements show up across ExtractBench challenges, including long lists, records spanning pages, and scanned forms. The following show some examples of how extraction and grounding improve on these tasks.
Long lists
Long lists can cause even frontier VLMs to stop early or lose track of repeated records. Extract v2.5 uses intermediate representations to work with the full dataset and validate its output against your schema. Across long-list tasks, Cost Effective’s score rises from 82.0 to 92.6, and Agentic’s from 86.1 to 95.5.
LONG LIST ACCURACY V2.0V2.5 COST EFFECTIVE 82.0 92.6AGENTIC 86.1 95.5AGENTIC PLUS 94.5 96.3 7580859095100 SCORE
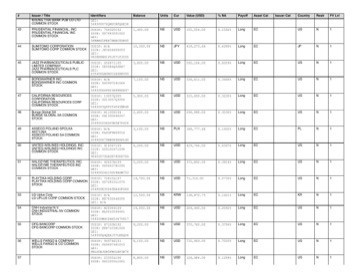
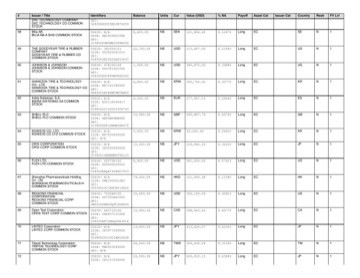
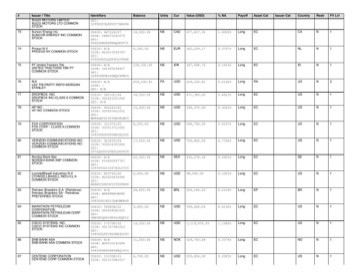
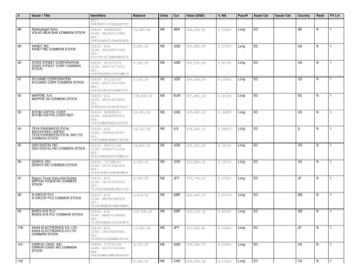
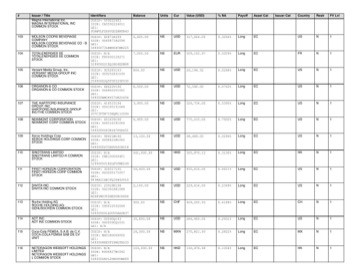
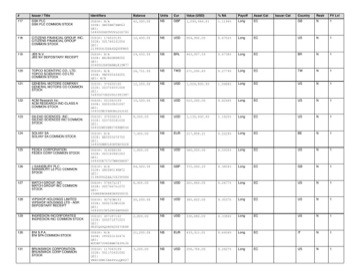
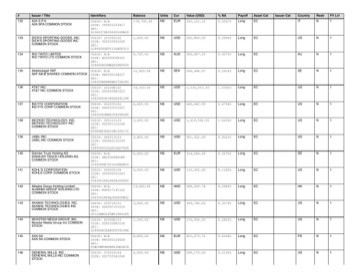
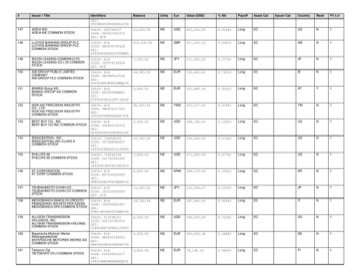
On a 17-page fund filing, Cost Effective previously returned 87 of 238 holdings. Extract v2.5 returns all 238, with the document’s extraction score rising from 52.8 to 98.7.
v2.0 v2.5
238 of 238 holdings ≡ each line is one holding
1. 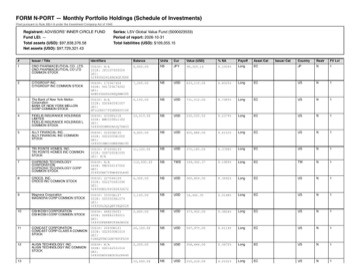 p1 ≡ 12
2.
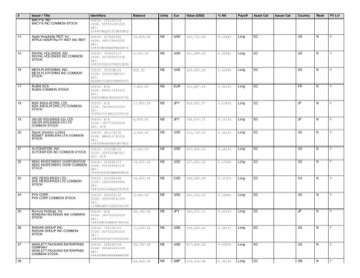 p2 ≡ 15
3.
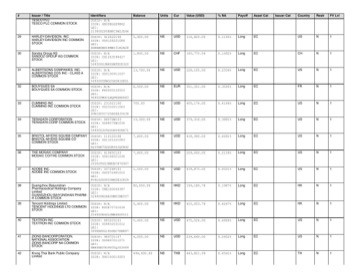 p3 ≡ 15
4.
 p4 ≡ 14
5.
 p5 ≡ 15
6.
 p6 ≡ 16
7.
 p7 ≡ 14
8.
 p8 ≡ 15
9.
 p9 ≡ 15
10.
 p10 ≡ 15
11.
 p11 ≡ 15
12.
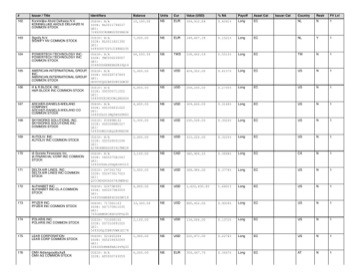 p12 ≡ 15
13.
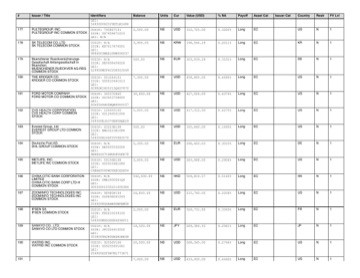 p13 ≡ 14
14.
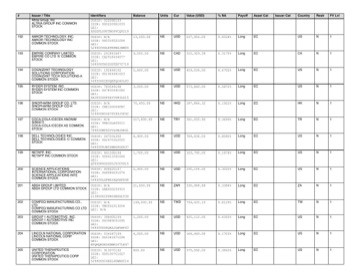 p14 ≡ 15
15.
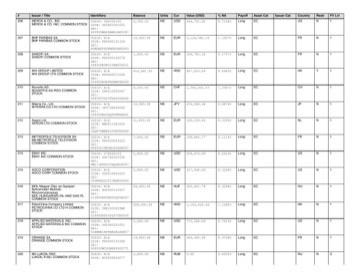 p15 ≡ 15
16.
 p16 ≡ 14
17.
 p17 ≡ 4
holdings: \[
… { issuer\_name: "CENTENE CORPORATION", value\_usd: 203604.00 }, 87 holdings
{ issuer\_name: "Aktiebolaget Volvo", value\_usd: 552328.91 }, { issuer\_name: "AVNET, INC.", value\_usd: 361862.00 }, … 151 missed
238 holdings
\]
Records spanning pages
In real world documents, extraction must reason across pages. Content on one page might span multiple pages, or be joined with an appendix many pages later. Extract v2.5 is better at preserving the relationship between the fields as it builds the output.
CROSS-PAGE RECORDS ACCURACY V2.0V2.5 COST EFFECTIVE 80.3 92.0AGENTIC 85.5 96.5AGENTIC PLUS 93.6 96.7 7580859095100 SCORE
In this grant schedule, Agentic v2.0 stopped at the page break, leaving the grant’s purpose and address incomplete. Extract v2.5 includes the continuation from the next page in the same record.
v2.0 v2.5
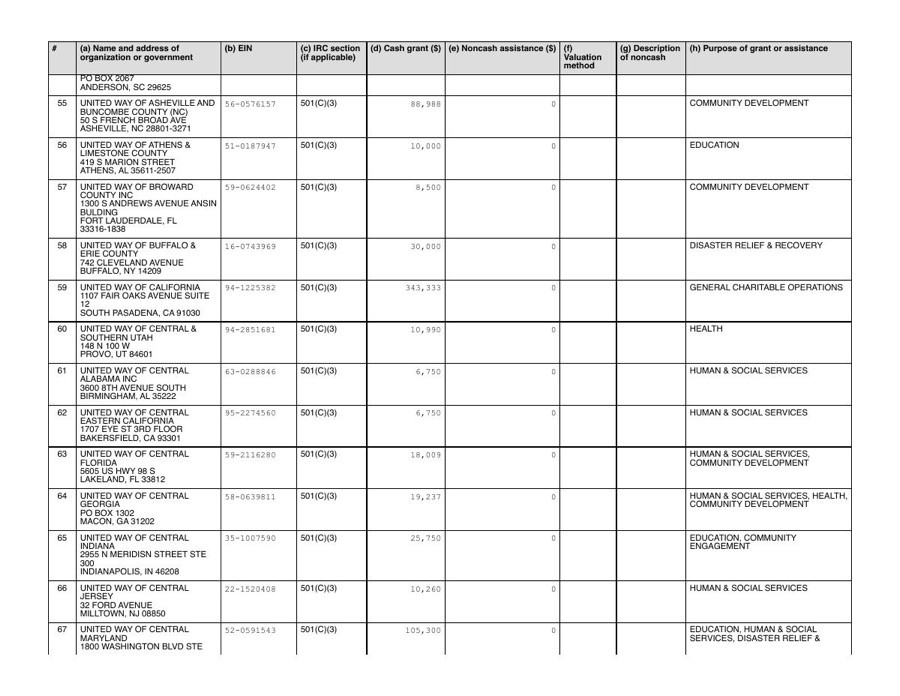 5
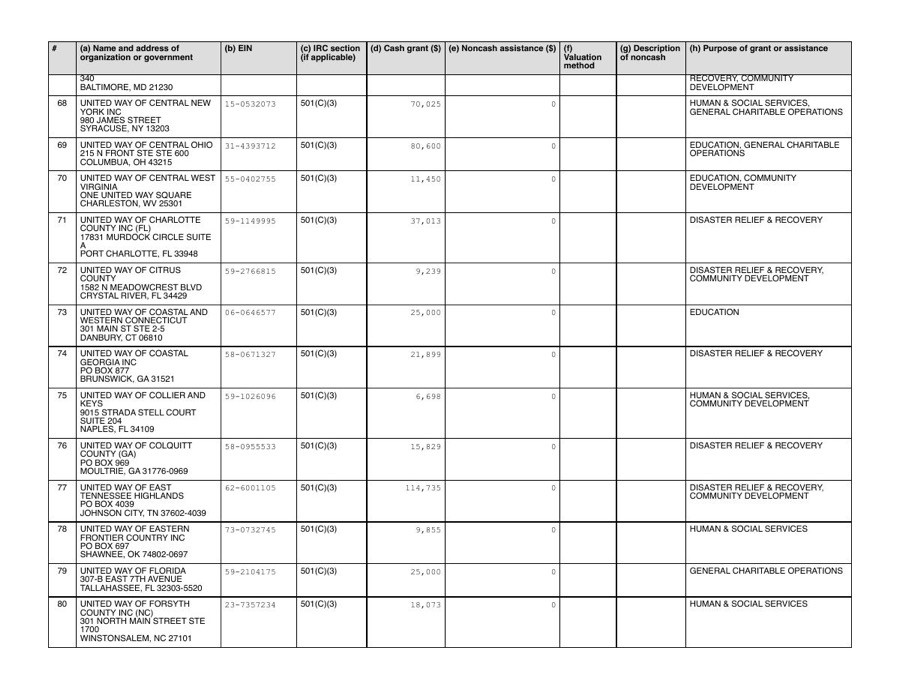 6
Expand
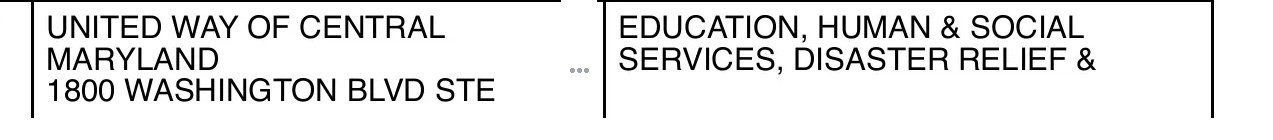
page break
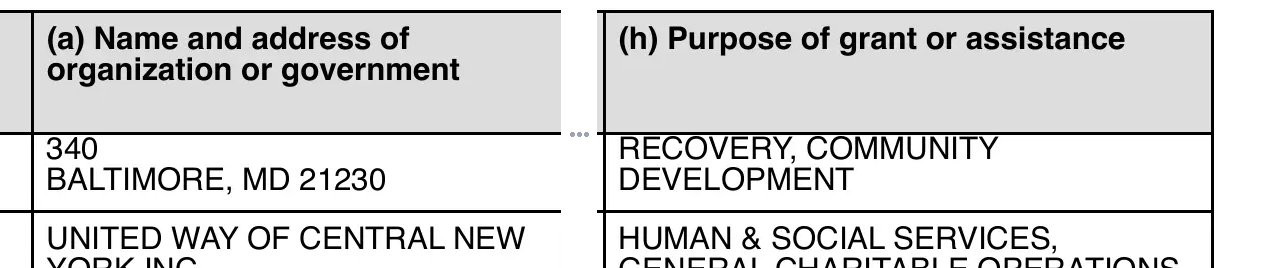
address\_line1 1800 WASHINGTON BLVD STE 340
city, state, zip\_code "" → BALTIMORE MD 21230
purpose\_of\_grant EDUCATION, HUMAN & SOCIAL SERVICES, DISASTER RELIEF & RECOVERY, COMMUNITY DEVELOPMENT
×
Page 5
Page 6
Scanned forms
Scanned forms often mix printed fields, overlaid text, handwriting, and reviewer annotations. Scan noise common in such forms can make these layers even harder to distinguish. A printed value might be crossed out and hand corrected after printing. Extract v2.5 is better at visually interpreting the field in context and separating the requested value from the surrounding marks. It’s now also much better at grounding the extracted value back to the source document for cross checking and reference.
SCANNED FORMS ACCURACY V2.0V2.5 COST EFFECTIVE 89.6 93.9AGENTIC 90.9 95.7AGENTIC PLUS 94.4 96.1 7580859095100 SCORE
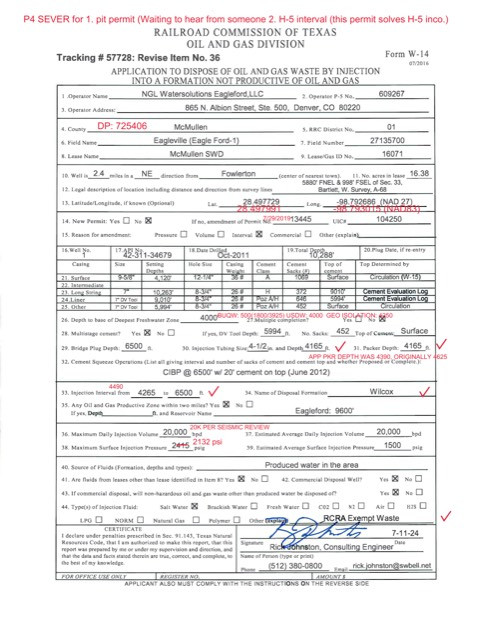
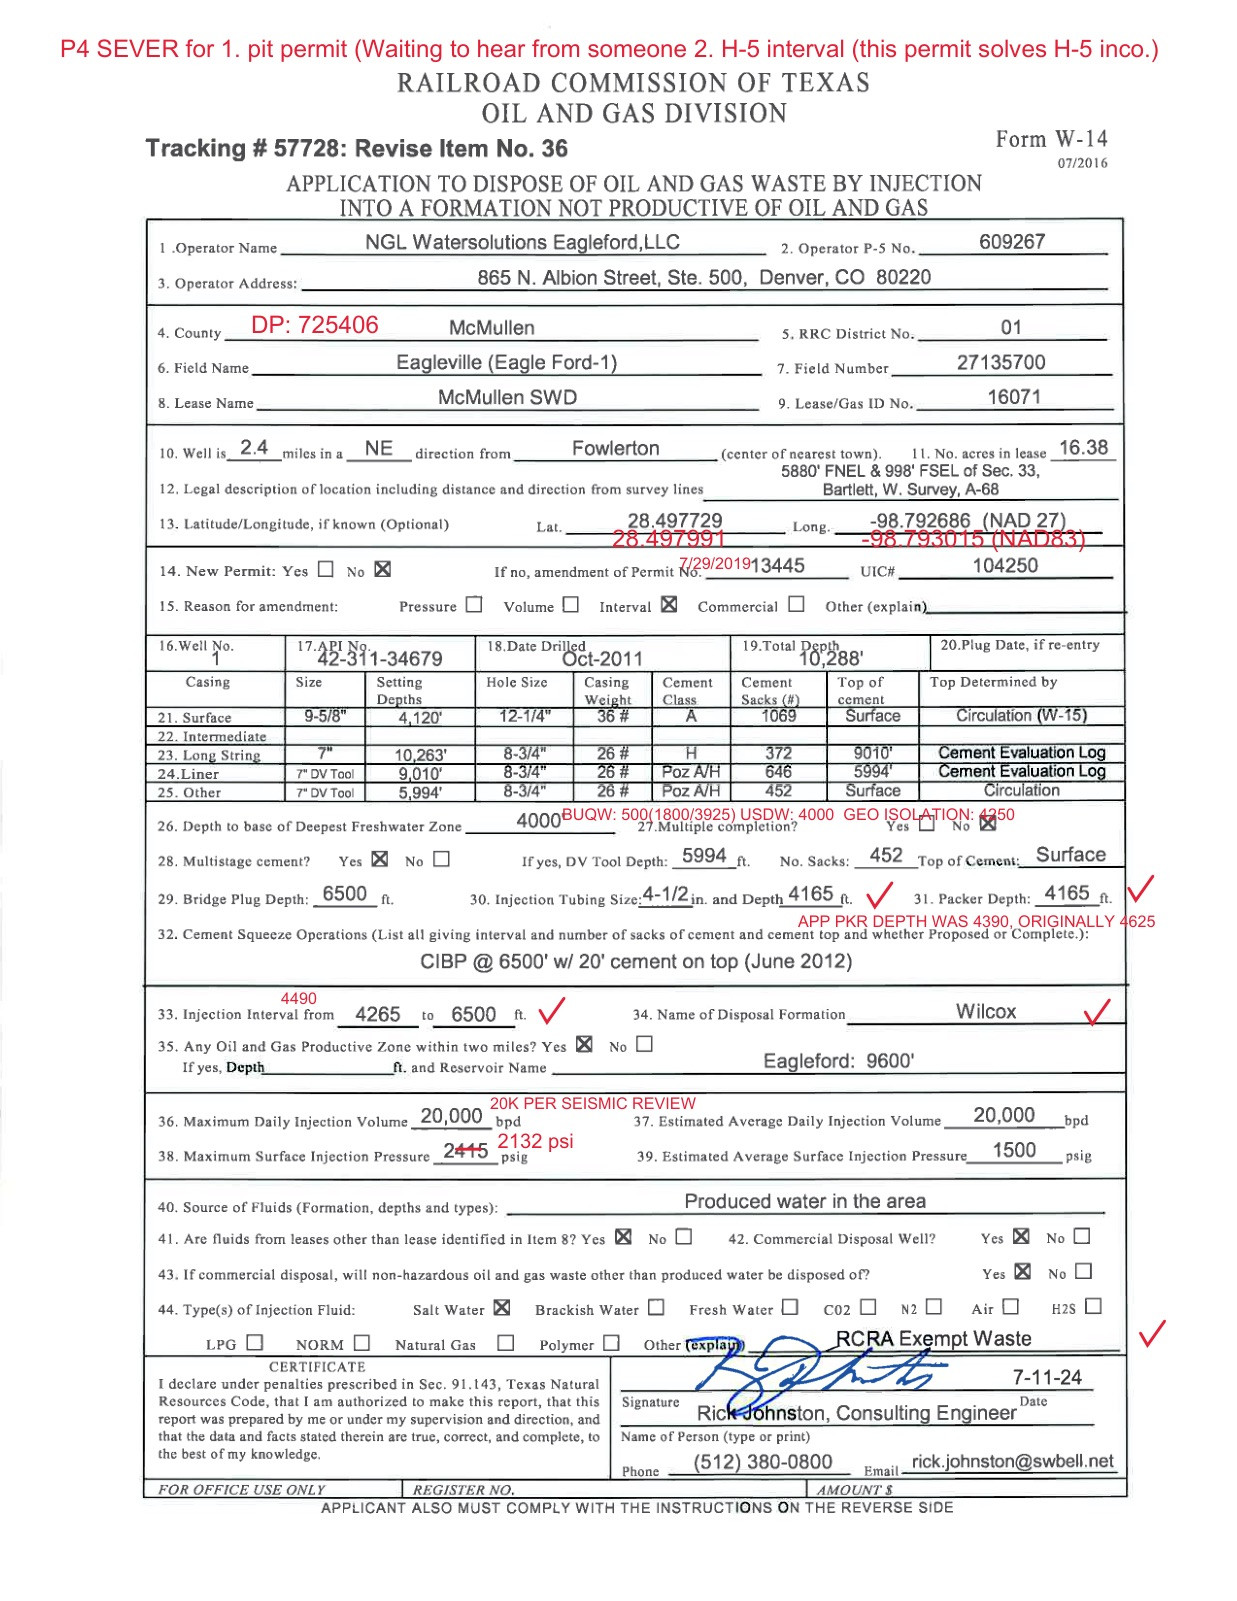
On this annotated permit, Agentic previously combined a reviewer’s date with the permit number and appended a reviewer note to the freshwater depth. Extract v2.5 separates the original values from the annotations into the fields requested by the schema.
v2.0 v2.5
 Expand

amendment\_permit\_no "7/29/2019 13445" → "13445"
amendment\_permit\_no\_review null → "7/29/2019"

deepest\_freshwater\_zone "4000 BUQW: 500(1800/3925) USDW: 4000 GEO ISOLATION: 4250" → "4000"
deepest\_freshwater\_zone\_review "4000 BUQW: 500(1800/3925) USDW: 4000 GEO ISOLATION: 4250" → "BUQW: 500(1800/3925) USDW: 4000 GEO ISOLATION: 4250"
×
Advanced Citations
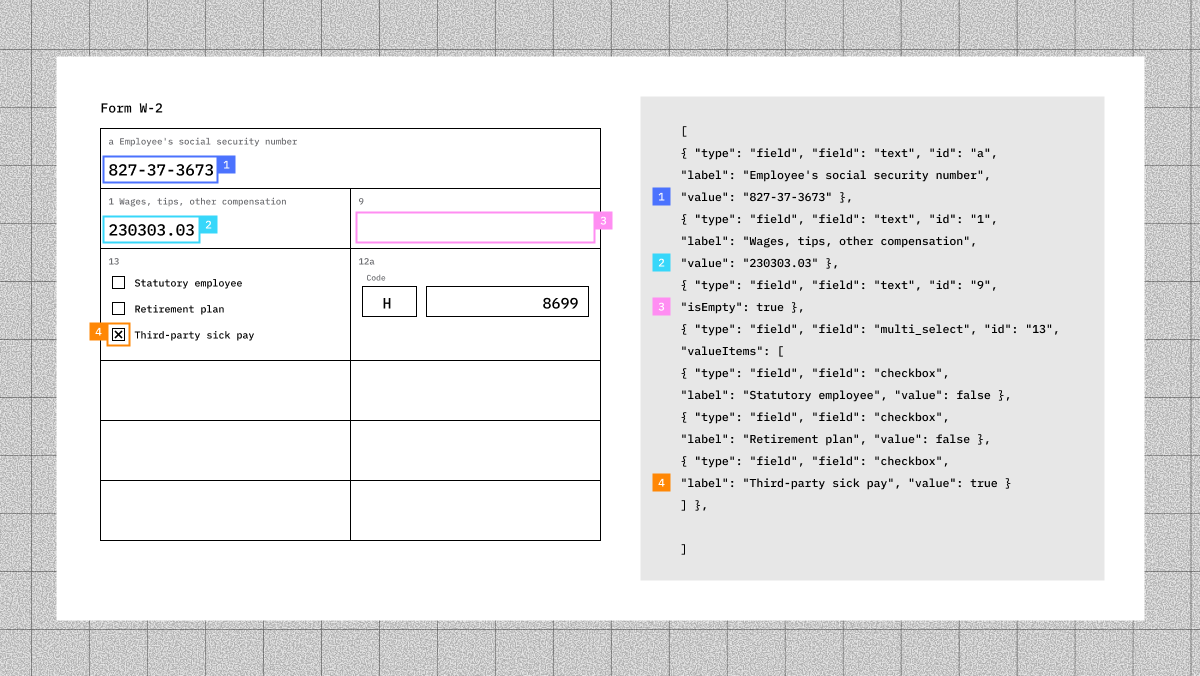
Advanced Citations locate bounding boxes of supporting evidence for difficult fields, including values that don’t appear word for word in the document. An initial version was previously available in Agentic Plus. With v2.5, we’ve improved its grounding accuracy further and extended it to Agentic.
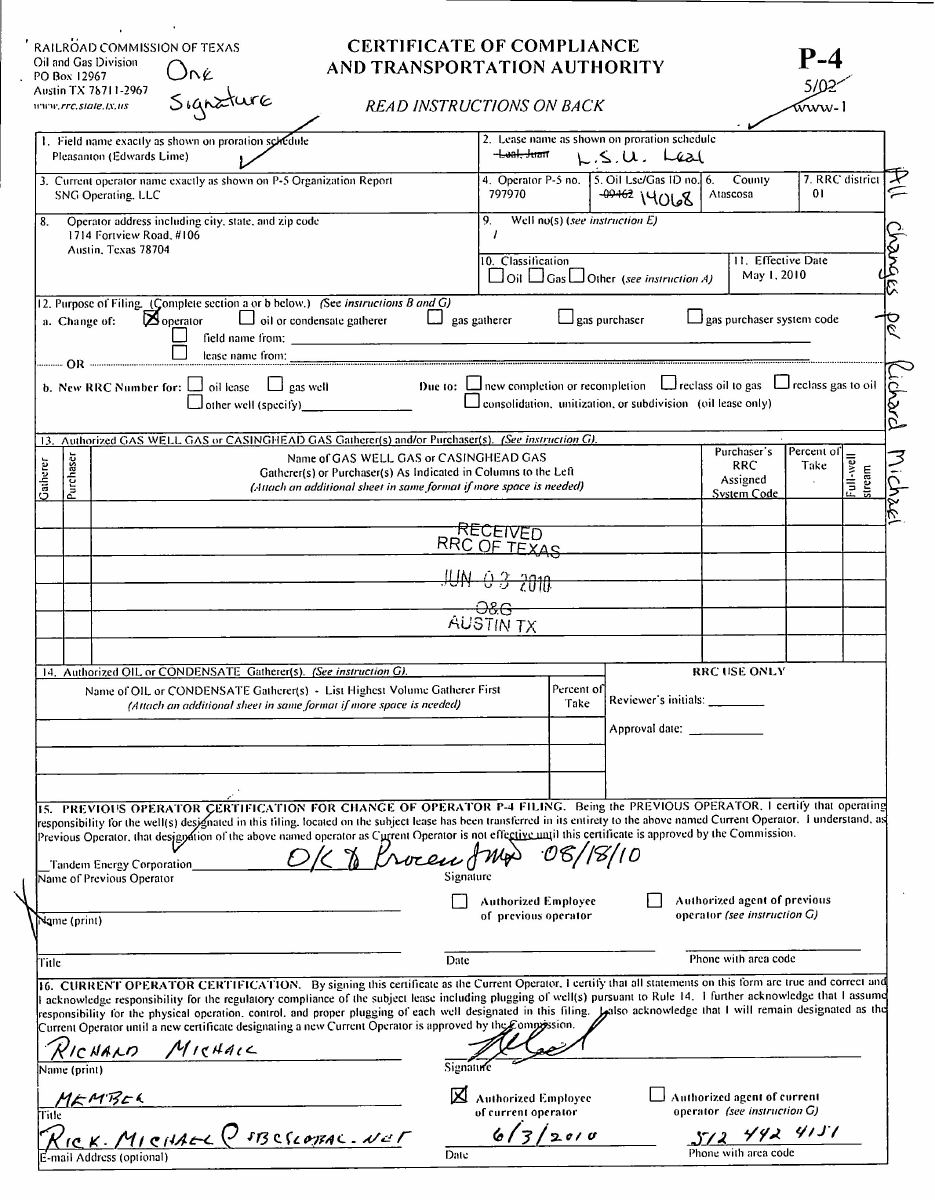 field\_name Pleasanton (Edwards Lime) lease\_name L.S.U. Leal current\_operator\_name SNG Operating, LLC operator\_p5\_no 797970 oil\_lse\_gas\_id\_no 14068 county Atascosa operator\_address 1714 Fortview Road, #106 Austin, Texas 78704 well\_nos 1 classification\_oil false classification\_gas false classification\_other false effective\_date May 1, 2010 change\_operator true change\_oil\_condensate\_gatherer false change\_gas\_gatherer false change\_gas\_purchaser false change\_gas\_purchaser\_system\_code false change\_field\_name false change\_lease\_name false new\_rrc\_oil\_lease false new\_rrc\_gas\_well false new\_rrc\_other\_well false due\_new\_completion\_recompletion false due\_reclass\_gas\_to\_oil false due\_reclass\_oil\_to\_gas false due\_consolidation false
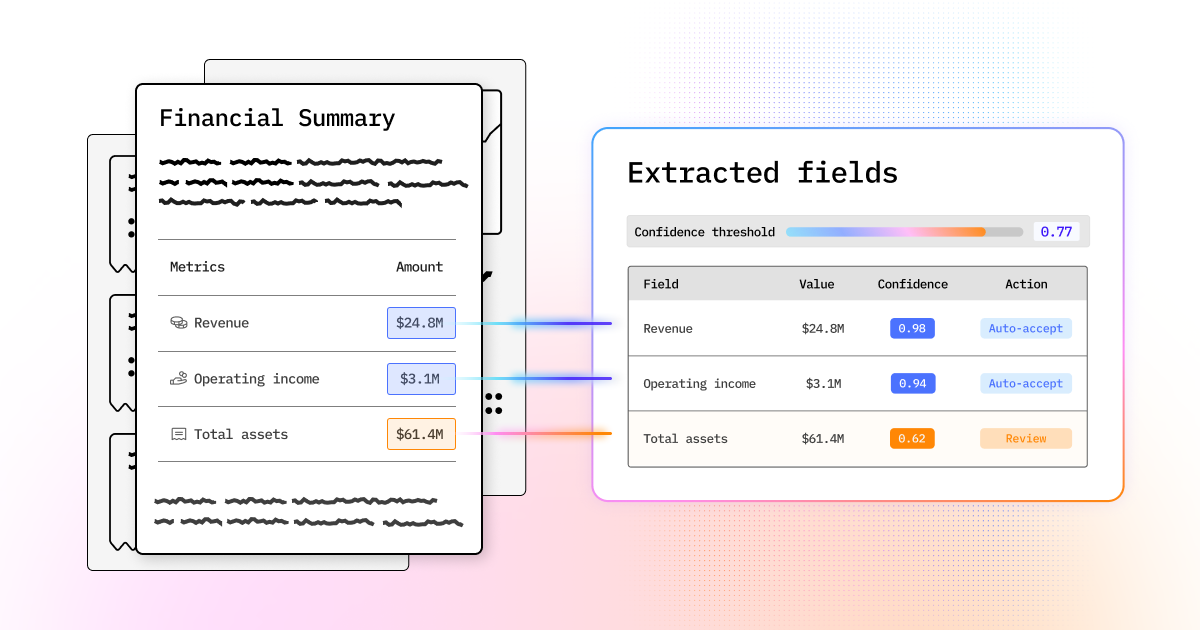
Bounding box citations combine well with confidence scores. Confidence scores help teams decide which values can proceed automatically and which need a closer look. Reviewers can then use citations to check those values against the original document in human-in-the-loop workflows. Our confidence-score guide explains how to evaluate this on your own documents.
How we built v2.5
At LlamaIndex, we know documents deeply. We’ve built that expertise into tools our extraction agents can call to read, transform, and locate information in documents. Those tools draw on purpose-built models and document processing methods to handle inconsistent file formats, ambiguous layouts, and source coordinates.
Reading order, table structure, and the relationship between text and its position on the page all affect extraction. Our tools give agents ways to work with these structures and return to the source as they build the output.
For v2.5, we brought the harness behind Agentic Plus to Cost Effective and Agentic, adapting its tools and extraction strategies to each tier’s cost constraints. We refined how to organize the task, what context to give the agent, and when it should inspect the document more closely.
Getting those choices right took extensive testing. An approach that works well for a short form may struggle with hundreds of repeated records. We evaluated document representations, tools, and model configurations across these tasks, weighing accuracy gains against the time and processing they require.
We also worked on how agents follow your schema and extraction instructions, including tasks with up to 3,200 fields. If record IDs are essential for matching extracted records to your database, for example, call that out in your prompt so the agent can give them extra attention.
We’ve also added native spreadsheet extraction. In spreadsheet mode, agents work directly with workbook cells rather than a flattened representation, giving them another way to work with structured data. You can enable it in your extraction configuration.
Try v2.5 on your documents
Try v2.5 on documents representative of your workflow, using your existing schemas. We think this version will be a significant step up in extraction quality, especially for documents that previously needed manual cleanup or weren’t reliable enough to automate. We’re looking forward to seeing what you build.
Open LlamaCloud (opens in a new tab)↗ Use the CLI+ Connect your agent+
Extract documents from your terminal.
CLI · requires Go
`go install github.com/run-llama/llama-parse-cli/cmd/llp@latest` Copy
Set LLAMA\_CLOUD\_API\_KEY before using llp.
CLI setup (opens in a new tab) ↗
Extract documents with your agent.
MCP client Claude Code Codex
`claude mcp add --transport http llamaparse https://mcp.llamaindex.ai/mcp` Copy
Sign in when prompted.
`codex mcp add llamaparse --url https://mcp.llamaindex.ai/mcp` Copy
Sign in when prompted.
MCP setup and other clients (opens in a new tab) ↗
Python SDK
`python -m pip install -U llama-cloud` Copy
Run the example and enter your API key when prompted. It downloads the sample PDF for you.
job = client.extract.run(
    file_input=file.id,
    configuration={
        "tier": "agentic",
        "version": "2.5",
        "extraction_target": "per_doc",
        "data_schema": Invoice.model_json_schema(),
        "cite_sources": True,
        "confidence_scores": True,
    },
)
from getpass import getpass
import httpx
from llama_cloud import LlamaCloud
from pydantic import BaseModelclass Invoice(BaseModel):
total_amount: float
client = LlamaCloud(api_key=getpass("LlamaCloud API key: "))
sample_url = (
"https://huggingface.co/datasets/llamaindex/ExtractBench/"
"resolve/f6180e917a050a84582e6366cff85b7dc1e84e58/"
"docs/short/aclu_cdwg_invoice.pdf"
)
pdf = httpx.get(sample_url, follow_redirects=True, timeout=60)
pdf.raise_for_status()
file = client.files.create(
file=("invoice.pdf", pdf.content, "application/pdf"),
purpose="extract",
)
job = client.extract.run(
file_input=file.id,
configuration={
"tier": "agentic",
"version": "2.5",
"extraction_target": "per_doc",
"data_schema": Invoice.model_json_schema(),
"confidence_scores": True,
"cite_sources": True,
},
)
result = client.extract.get(job.id, expand=["extract_metadata"])
print(result.extract_result)
print(result.extract_metadata.field_metadata.document_metadata)
Related articles