
GPU view-adaptive crack-free subdivision of Bézier surfaces
Share on Bluesky Share on Mastadon Share on LinkedIn Share on Twitter/X Share on Reddit Share on Facebook Share on Whatsapp Share via Email
GPU view-adaptive crack-free subdivision of Bézier surfaces
Originally posted: August 6, 2026
Bastian Kuth
Quirin Meyer
Smooth surface tessellation
Bézier surfaces are a standard representation for smooth geometry in computer graphics. Car bodies, organic character shapes, and many other smooth objects can all be conveniently expressed as collections of bicubic Bézier patches, where each patch consists of 16 control points. To render them efficiently, those patches can be broken down into triangles. This post gives a brief look at the ideas behind our paper presented at the Eurographics Symposium on Rendering (2026) on doing exactly that, fast and crack-free, using GPU work graphs.
JPG (1920x1080)
JPG (1920x1080)
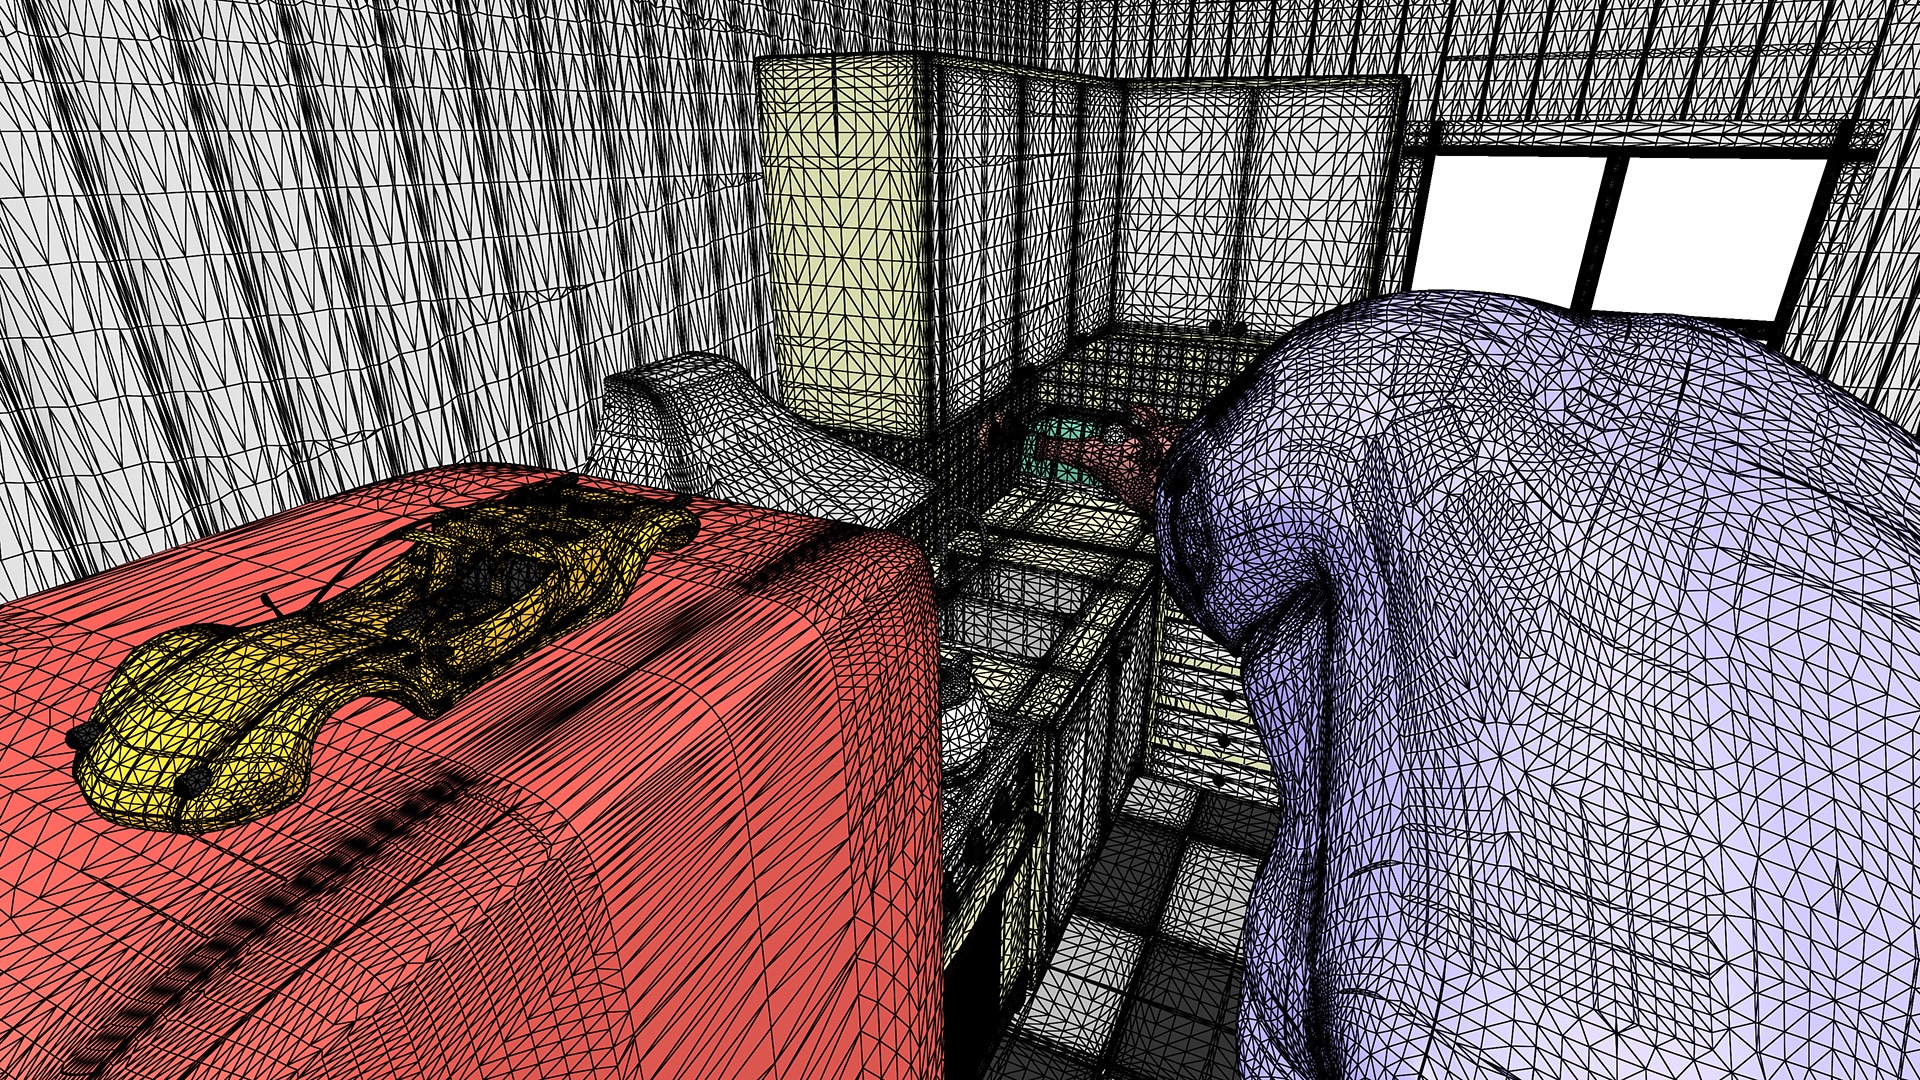
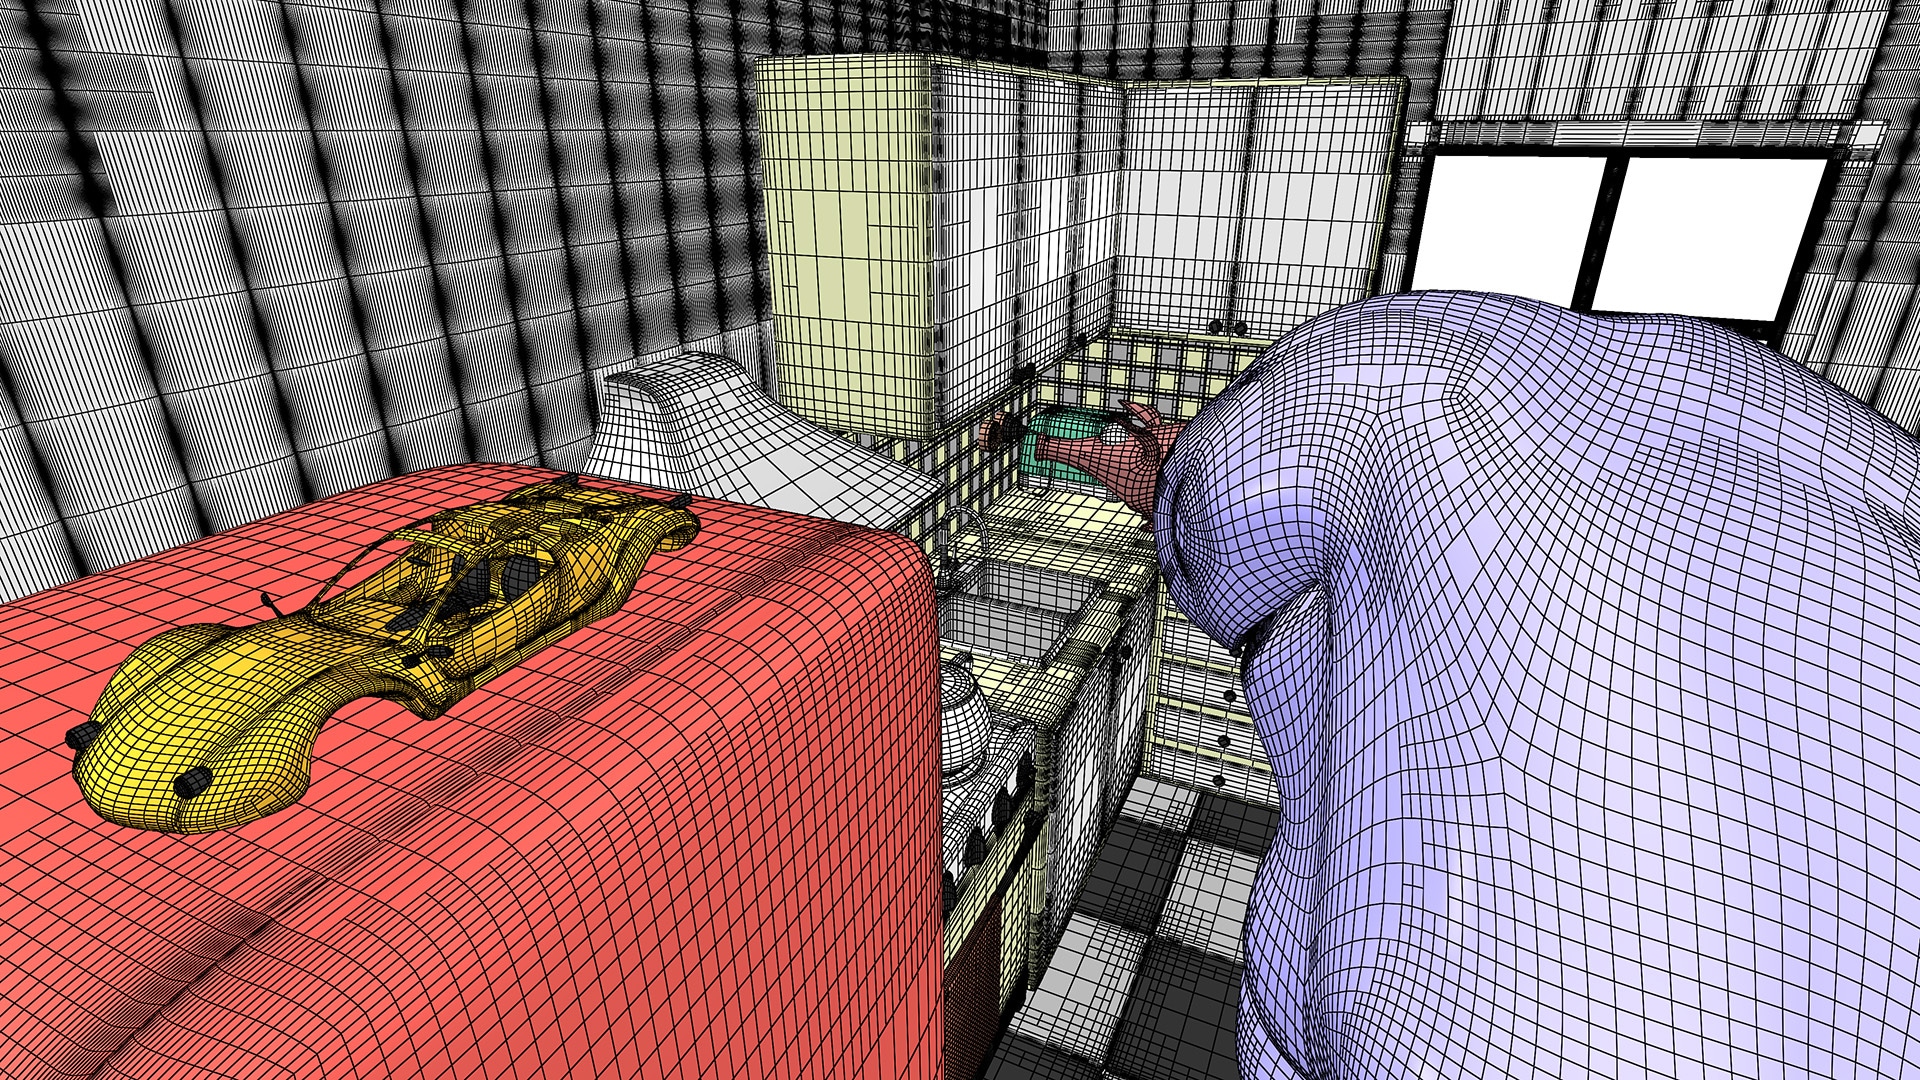
Hardware tessellation handles the conversion to triangles directly. It works by assigning tessellation factors to each patch: two inner factors controlling the interior grid density in u and v, and four outer factors that must match the neighboring patches to prevent cracks along shared edges. The factors can be made view-adaptive based on projected screen size or patch curvature. The problem is that the two inner factors dictate the entire patch uniformly. A patch that curves sharply in one corner and is nearly flat everywhere else still gets a uniform grid of triangles across its whole surface, producing more triangles than the image requires.
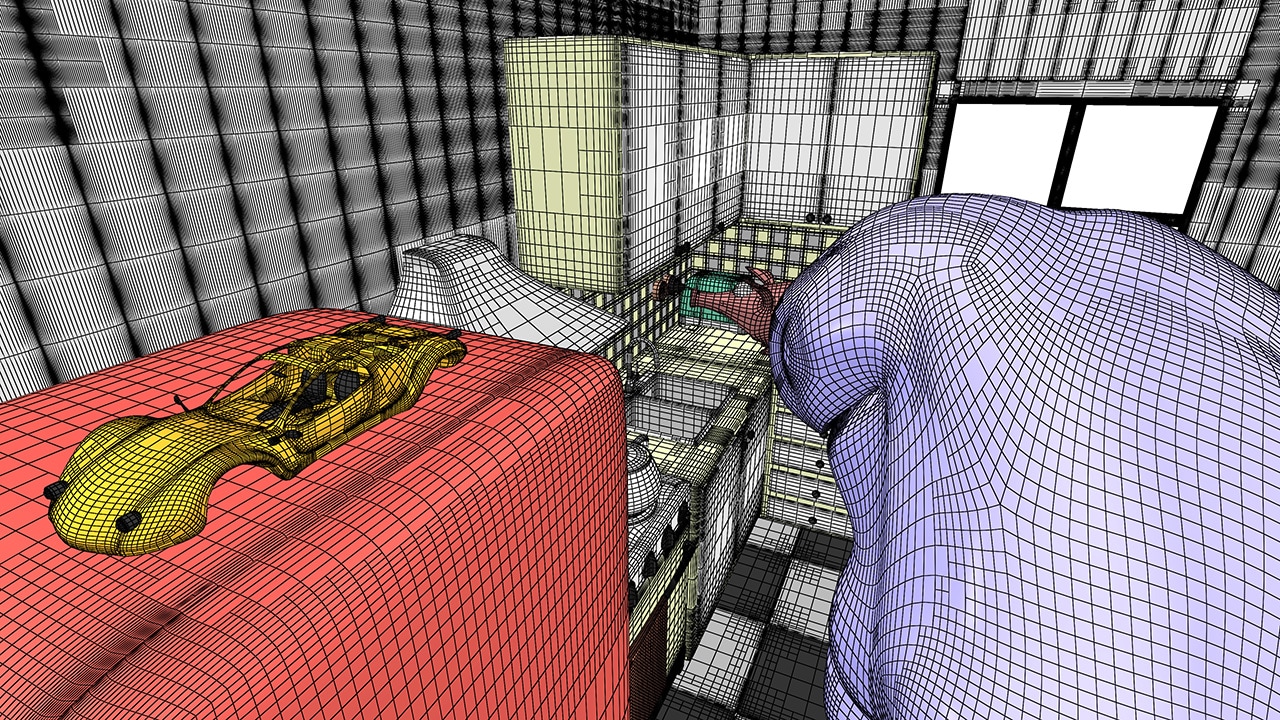
To avoid this, the conversion can be expressed as a recursive problem. You ask: is this patch flat enough to approximate as two triangles? If yes, draw it. If not, split it into four sub-patches and ask again. The result adapts naturally to curvature and distance from the camera, concentrating triangles only where they matter. Drag the slider above to compare the two wireframes side by side.
Implementing recursive subdivision
Recursive subdivision is difficult to implement efficiently on a GPU. Conventional compute-based approaches spread the recursion across multiple dispatches with explicit synchronization barriers between levels. Worse, they require large worst-case buffers, since the GPU must pre-allocate memory for the maximum possible number of sub-patches, even if most patches terminate early. Memory quickly becomes the bottleneck.
Our paper introduces several techniques that work together to address this. Rather than storing all 16 Bézier control points for every sub-patch (192 bytes each), we represent a sub-patch as just 8 bytes encoding its position in a subdivision quad tree. The actual control points are reconstructed on demand from the base patch using a numerically stable evaluation based on tensor product blossoms. This evaluation is designed so that neighboring patches compute bitwise-identical positions on shared boundaries, which is the key to producing a crack-free result without any communication between patches.
When adjacent patches reach different subdivision depths, cracks would normally appear along their shared edges. We close them with small wedge triangles that each patch generates independently.
The following figure shows our Work Graph:
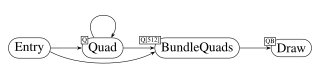
The Entry node starts the process, dispatching one thread per base-patch. If a patch needs subdivision, Entry emits four child records to the Quad node, one per sub-patch. Quad performs the same job recursively: it reconstructs the sub-patch control points on demand, tests the flatness criterion, and either splits further by enqueuing itself again via work graphs’ trivial recursion, or passes the finished patch to BundleQuads. BundleQuads collects up to 512 patches at a time and forwards the batch as a single record to the Draw mesh node, which outputs the triangles and wedges directly to the rasterizer. A single CPU dispatch drives all of this. There are no explicit barriers between levels and no worst-case buffer allocations: the work graphs runtime allocates only what is actually needed.
Your browser does not support the video tag.
GPU view-adaptive crack-free subdivision of Bézier surfaces demo video.
Results
At equivalent image quality, our method renders on par with hardware tessellation while producing significantly fewer triangles across the scene. The work graphs implementation also turned out to be considerably simpler to write than the execute-indirect equivalent: one dispatch on the CPU side, no manual synchronization, and no buffer management between levels. We see this as a broader signal that GPU work graphs are a natural fit for any recursive splitting problem where the amount of work per level is not known in advance. You can see the results in the demo video above.
For more on the subdivision criterion, the watertightness guarantees, and the full performance numbers, read the paper below.
- Download the GPU View-Adaptive Crack-Free Subdivision of Bézier Surfaces paper by Seyedmasih Tabaei, Bastian Kuth, Max Oberberger, and Quirin Meyer.
- See more AMD graphics research on our Research Publications page.
- Watch the presentation recording of this paper from the Eurographics Symposium on Rendering 2026.
- Browse the source code on GitHub from Coburg University.
- Discuss this research on the AMD Developer Community.
- Sign up to our AMD Developer Newsletter for the latest updates.
Footnotes
Links to third party sites are provided for convenience and unless explicitly stated, AMD is not responsible for the contents of such linked sites and no endorsement is implied. GD-97.
Bastian Kuth
After completing his PhD in close collaboration with AMD in the area of Geometry Processing and GPU Work Graphs, Bastian has since joined as an engineer and researcher to work on the future of graphics.
Quirin Meyer
Before becoming a computer graphics professor at Coburg University, Quirin Meyer obtained a Ph.D. in graphics and worked as a software engineer in the industry. His research focuses on real-time geometry processing primarily on GPUs.
Related news and technical articles
 AMD Radeon™ GPU Profiler 2.4 adds support for AMD Radeon™ RX 9000 Series, pure-compute applications, DirectML applications (and more!) Discover the latest Radeon GPU Profiler v2.4, now supporting Radeon RX 9000 Series GPUs and profiling for pure compute and DirectML applications. Enhance your optimization with improved ISA views and Work Graphs support.
 Work Graph Playground a learning framework for GPU Work Graphs Read about our latest sample for D3D12 GPU Work Graphs. We're making Work Graphs more accessible with a tutorial framework.
 GPU Work Graphs mesh nodes in Vulkan® We’ve added mesh nodes to our Vulkan® experimental extension, VK\AMDX\_shader\_enqueue.
 GPU Work Graphs mesh nodes in Microsoft DirectX® 12 Mesh nodes are a new type of leaf node in work graphs that, unlike all other nodes, does not invoke a compute shader, but dispatches a mesh-shader graphics pipeline instead. This blog series covers how to get started with mesh nodes as well as best practices.
 Getting started The second part of this mesh nodes blog series focusses on initial setup of a new mesh nodes project and includes an example of a HelloMeshNodes solution. Tips, tricks, and best practices The final part of this mesh nodes blog series outlines some of the best practices for getting the best performance out of a mesh nodes project. Procedural generation Mesh nodes makes it much simpler to implement a fully procedurally generated world. This blog post examines an example of procedural mesh node sample.
 GDC 2024 Work graphs and draw calls – a match made in heaven! Introducing "mesh nodes", which make draw calls an integral part of the work graph, providing a higher perf alternative to ExecuteIndirect dispatches.
Related videos
 Mesh Shaders – Learning Through Examples (Digital Dragons 2024) – YouTube link Learn about the new Mesh Shader pipeline which can help to create even more better-looking games.
 GDC 2024 - GPU Work Graphs: Welcome to the Future of GPU Programming - YouTube link This talk by Matthäus Chajdas gives a first look at this brand new API and shows how it's going to transform the GPU programming landscape going forward.