Matt Keeter // blog
Beating the compiler
In modern times, everyone knows that writing assembly is a fool's errand: compilers are the result of literal engineer-centuries of work, and they know the processor much better than you do.
And yet – one hears rumors.
Written in ancient tomes, muttered in quiet watering holes, scrawled on the walls of bygone temples, hinted at by mysterious texts; the rumors paint a specific picture:
Compilers are bad at generating code for interpreters, and it's possible to outperform them by writing your interpreter in assembly.
I recently wrote a fast interpreter for the Uxn CPU, a stack-based architecture with 256 opcodes. The interpreter is a simple loop which reads a byte from RAM then selects the appropriate instruction:
impl Uxn {
    /// Runs the VM starting at the given address until it terminates
    #[inline]
    pub fn run<D: Device>(&mut self, dev: &mut D, mut pc: u16) {
        loop {
            let op = self.ram[usize::from(pc)];
            pc = pc.wrapping_add(1);
            let Some(next) = self.op(op, dev, pc) else {
                break;
            };
            pc = next;
        }
    }    /// Executes a single operation
    #[inline]
    fn op<D: Device>(&mut self, op: u8, dev: &mut D, pc: u16) -> Option<u16> {
        match op {
            0x00 => op::brk(self, dev, pc),
            0x01 => op::inc::<0b000>(self, dev, pc),
            0x02 => op::pop::<0b000>(self, dev, pc),
            0x03 => op::nip::<0b000>(self, dev, pc),
            0x04 => op::swp::<0b000>(self, dev, pc),
            0x05 => op::rot::<0b000>(self, dev, pc),
            0x06 => op::dup::<0b000>(self, dev, pc),
            0x07 => op::ovr::<0b000>(self, dev, pc),
            0x08 => op::equ::<0b000>(self, dev, pc),
            0x09 => op::neq::<0b000>(self, dev, pc),
            0x0a => op::gth::<0b000>(self, dev, pc),
            0x0b => op::lth::<0b000>(self, dev, pc),
            0x0c => op::jmp::<0b000>(self, dev, pc),
            0x0d => op::jcn::<0b000>(self, dev, pc),
            0x0e => op::jsr::<0b000>(self, dev, pc),
            // ... etc
        }
    }
}
All of the opcode implementations end up monomorphized and inlined into the body of `Uxn::run(..)`, and the compiler is smart enough to keep key values in registers. This makes it relatively fast; I see 10-20% speedup over the reference implementation.
Let's look at the assembly and see what the compiler is doing – and whether we can do any better. For context, the Uxn CPU has four different memories:
- The data stack, which is a `[u8; 256]` along with a `u8` index
- The return stack, which has the same format
- RAM, which is a `[u8; 65535]`
- Device memory, which we'll ignore for the moment (along with the `D: Device`argument)
During evaluation, we also track the program counter `pc`, which is a `u16` used to index into the RAM. In each cycle, we load a byte from RAM, then call the appropriate opcode. Some opcodes can also read and write to RAM, so self-modifying code is possible!
By examining the assembly, we can reverse-engineer which values are stored where. Consider the `INC` operation, which loads a value from the top of the data stack and increments it:
; INC
0x100002d4c: ldrb w8, [x25]     ; read the current data stack index
0x100002d50: ldrb w9, [x24, x8] ; read a byte from the data stack
0x100002d54: add w9, w9, #1     ; increment that byte
0x100002d58: strb w9, [x24, x8] ; write that byte back to the stack
0x100002d5c: b 0x100002d1c      ; jump back to the dispatch loop
From this assembly, we learn the following:
Similarly, `INCr` – increment the top value in the return stack – teaches us that `x22` and `x23` are the return stack's data and index addresses.
`JMP` shows that our program counter is stored in `w27`:
; JMP
0x100002eac: ldrb w8, [x25]      ; read the current data stack index
0x100002eb0: ldrsb w9, [x24, x8] ; read a signed jump offset from the data stack
0x100002eb4: sub w8, w8, #1      ; decrement the data stack index
0x100002eb8: strb w8, [x25]      ; write back the data stack index
0x100002ebc: add w27, w27, w9    ; apply the jump to our program counter
0x100002ec0: b 0x100002d1c       ; jump back to the dispatch loop
Finally, the dispatch loop itself is worth examining:
0x100002d1c: and x10, x27, #0xffff          ; mask pc to a u16
0x100002d20: ldr x8, [x20, #256]            ; load RAM base from *mut Uxn
0x100002d24: ldrb w10, [x8, x10]            ; load opcode byte from RAM
0x100002d28: add w27, w27, #1               ; increment pc
0x100002d2c: adr x11, #-96                  ; load base for jump
0x100002d30: ldrh w12, [x27, x10, lsl  #1]  ; load per-opcode jump amount
0x100002d34: add x11, x11, x12, lsl #2      ; compute jump location
0x100002d38: br x11                         ; jump into opcode implementation
The compiler has generated a jump table of 256 offsets (each a 2-byte value, indicated by `lsl #1`). It reads an opcode-specific value from this table to compute a jump target, then performs an indirect branch to jump into the opcode's implementation.
We can run this in a debugger and dump the actual jump table:
(lldb) disas -p -c3
raven-cli`raven_uxn::Uxn::run::had9dba0d7d1b5105:
->  0x100002d30 <+236>: ldrh   w12, [x27, x10, lsl  #1]
    0x100002d34 <+240>: add    x11, x11, x12, lsl #2
    0x100002d38 <+244>: br     x11
(lldb) reg read x27
     x27 = 0x0000000100170b10
(lldb) memory read -s2 -fu -c256 0x0000000100170b10
0x100170b10: 2923
0x100170b12: 31
0x100170b14: 36
0x100170b16: 40
0x100170b18: 44
0x100170b1a: 52
0x100170b1c: 28
0x100170b1e: 64
0x100170b20: 70
0x100170b22: 78
0x100170b24: 86
0x100170b26: 94
0x100170b28: 119
0x100170b2a: 102
0x100170b2c: 110
0x100170b2e: 125
; etc...
(indeed, this is how I generated the per-opcode instruction listing)
---
Having looked at the assembly, there are two things that stick out as possible inefficiencies:
Profiling the code, the hottest instructions are all in the dispatch loop; the `ldrh` takes over 1/3 of the total runtime!
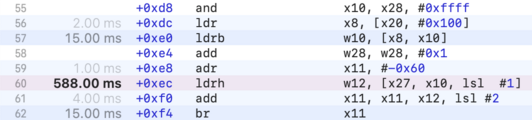
(I'm not confident that the profiler is attributing the time to the correct specific instruction here, but the vibes definitely indicate that dispatch is expensive)
---
LuaJIT is the fast interpreter par excellence, and it's written in assembly. Mike Pall specifically calls outkeeping state in registers and indirect threading as two contributors to its speed, which can only be accomplished reliablyin assembly.
Since persuading our compiler to generate extremely specific patterns is hard, let's get started writing some assembly of our own. My home machine is an M1 Macbook, so all of the assembly will be AArch64-flavored. The implementation uses general-purpose registers; be aware that `w*` and `x*` refer to 32-bit and 64-bit views of the same register.
---
Register assignment
Our first optimization is to store all important data in registers, to avoid superfluous loads and stores. My implementation ends up using 9 registers (`x0-x8`), along with a handful of scratch registers:
; x0 - stack pointer (&mut [u8; 256])
; x1 - stack index (u8)
; x2 - return stack pointer (&mut [u8; 256])
; x3 - return stack index (u8)
; x4 - RAM pointer (&mut [u8; 65536])
; x5 - program counter (u16), offset of the next value in RAM
; x6 - VM pointer (&mut Uxn)
; x7 - Device handle pointer (&DeviceHandle)
; x8 - Jump table pointer
; x9-15 - scratch registers
The AArch64 calling conventiononly gives you 8 input arguments, so we can't call a function directly with all of these values in registers; we'll need a C ABI-flavored entry point (discussed below).
Indirect threading
Our second optimization is using threaded codeto eliminate the dispatch loop. Each opcode's implementation will end with a jump to the next opcode's implementation.
Opcodes are stored as single bytes in VM RAM, with a base address of `x4`. I'll build a separate jump table of function pointers, then pass its address in register `x8`. On the Rust side, here's what that table looks like:
extern "C" {
    fn BRK();
    fn INC();
    fn POP();
    fn NIP();
    fn SWP();
    fn ROT();
    fn DUP();
    fn OVR();
    fn EQU();
    // ...etc
}const JUMP_TABLE: [unsafe extern "C" fn(); 256] = [
    (BRK as unsafe extern "C" fn()),
    (INC as unsafe extern "C" fn()),
    (POP as unsafe extern "C" fn()),
    (NIP as unsafe extern "C" fn()),
    (SWP as unsafe extern "C" fn()),
    (ROT as unsafe extern "C" fn()),
    (DUP as unsafe extern "C" fn()),
    (OVR as unsafe extern "C" fn()),
    (EQU as unsafe extern "C" fn()),
    (NEQ as unsafe extern "C" fn()),
    // ... etc
];
In assembly, we want to read the current byte from VM RAM (`x4`), use it to pick an address in the jump table (`x8`), then jump to that address. I defined a macro to do this dispatch:
.macro next
    ldrb w9, [x4, x5]          ; load the byte from RAM
    add x5, x5, #1             ; increment the program counter
    and x5, x5, #0xffff        ; wrap the program counter
    ldr x10, [x8, x9, lsl #3]  ; load the opcode implementation address
    br x10                     ; jump to the opcode's implementation
.endm
Notice that this is a macro, not a function; we'll add `next` to the end of each opcode, which will expand into this text.
For example, here's `INC`:
.global _INC
_INC:
    ldrb w9, [x0, x1]   ; read the byte from the top of the stack
    add w9, w9, #1      ; increment it
    strb w9, [x0, x1]   ; write it back
    next                ; jump to the next opcode
Unlike LuaJIT, there's no decoding step for instructions; there are no register arguments, and the single-byte opcode uniquely defines program behavior.
Implementation
Implementing the other 255 opcodes is mostly just turning the crank; there's nothing particularly exotic here, just good honest assembly.
In many cases, I'll use helper macros to generate code for a group of instructions:
.macro binary_op op
ldrb w10, [x0, x1] ; read the top value from the data stack
pop ; decrement the data stack index (this is a macro!)
ldrb w11, [x0, x1] ; read the next value from the data stack
\op w10, w11, w10 ; do the actual math operation
strb w10, [x0, x1] ; write the result into the data stack
next
.endm.global _ADD
_ADD:
binary_op add
.global _SUB
_SUB:
binary_op sub
.global _MUL
_MUL:
binary_op mul
.global _DIV
_DIV:
binary_op udiv
The whole implementation ends up being about 2400 lines. It sounds like a lot, but only about half of that is unique: most opcodes come in two flavors (with and without the `RET` flag), which only differ in which stack is used.
C Shims
Of course, my whole program isn't hand-written in assembly. We need a way to call our assembly function from the rest of our (Rust) implementation. This looks like a (Rust) `entry` function, which calls into an (assembly) `aarch64_entry` point (which is compatible with the C ABI):
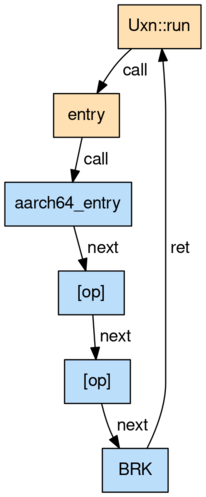
What do we actually pass into `aarch64_entry`? We have too much state to pass in function argument registers (`x0-x7`), so I defined a helper object which contains everything we need:
#[repr(C)]
pub(crate) struct EntryHandle {
    stack_data: *mut u8,
    stack_index: *mut u8,
    ret_data: *mut u8,
    ret_index: *mut u8,
    ram: *mut u8,
    vm: *mut core::ffi::c_void,  // *Uxn
    dev: *mut core::ffi::c_void, // *DeviceHandle
}struct DeviceHandle<'a>(&'a mut dyn Device);
The `DeviceHandle` is needed because `&mut dyn Device` is a fat pointer, and is therefore not safe to pass into a C function. Like all computer problems, we solve this with an extra level of indirection: put the `&mut dyn Device` into a `DeviceHandle`, then pass its address instead.
Calling into assembly is a simple matter of populating an `EntryHandle` object, then branching into the danger zone:
// Declaration of our entry point, written in assembly
extern "C" {
    pub fn aarch64_entry(
        h: *const EntryHandle,
        pc: u16,
        table: *const unsafe extern "C" fn(),
    ) -> u16;
}pub fn entry(vm: &mut Uxn, dev: &mut dyn Device, pc: u16) -> u16 {
    let mut h = DeviceHandle(dev);
    let mut e = EntryHandle {
        stack_data: vm.stack.data.as_mut_ptr(),
        stack_index: &mut vm.stack.index as *mut _,
        ret_data: vm.ret.data.as_mut_ptr(),
        ret_index: &mut vm.ret.index as *mut _,
        ram: (*vm.ram).as_mut_ptr(),
        vm: vm as *mut  as *mut ,
        dev: &mut h as *mut  as *mut ,
    };    // SAFETY: do you trust me?
    unsafe {
        aarch64::aarch64_entry(&mut e as *mut _, pc, JUMP_TABLE.as_ptr())
    }
}
`aarch64_entry` is a hand-written entry point in the assembly code. It shuffles around registers to put everything in the right place for our opcodes, then begins execution with the usual `next` macro:
.global _aarch64_entry
_aarch64_entry:
    sub sp, sp, #0x200  ; make room in the stack
    stp   x29, x30, [sp, 0x0]   ; store stack and frame pointer
    mov   x29, sp    // Unpack from EntryHandle into registers
    mov x5, x1 ; move PC (before overwriting x1)
    mov x8, x2 ; jump table (before overwriting x2)
    ldr x1, [x0, 0x8]  ; stack index pointer
    ldr x2, [x0, 0x10] ; ret data pointer
    ldr x3, [x0, 0x18] ; ret index pointer
    ldr x4, [x0, 0x20] ; RAM pointer
    ldr x6, [x0, 0x28] ; *mut Uxn
    ldr x7, [x0, 0x30] ; *mut DeviceHandle
    ldr x0, [x0, 0x00] ; stack data pointer (overwriting *EntryHandle)    ; Convert from index pointers to index values in w1 / w3
    stp x1, x3, [sp, 0x10]      ; save stack index pointers
    ldrb w1, [x1]               ; load stack index
    ldrb w3, [x3]               ; load ret index    ; Jump into the instruction list
    next
Finally, when exiting (via the `BRK` opcode), we need to update the data and return stack indices, moving values from registers into the appropriate memory addresses:
.global _BRK
_BRK:
    ; Write index values back through index pointers
    ldp x9, x10, [sp, 0x10]     ; restore stack index pointers
    strb w1, [x9]               ; save data stack index
    strb w3, [x10]              ; save return stack index    ldp   x29, x30, [sp, 0x0]   ; restore stack and frame pointer
    add sp, sp, #0x200          ; undo our stack offset    mov x0, x5 ; return PC from function
    ret
Device IO
The `DEI` and `DEO` opcodes perform "device I/O", which lets you attach arbitrary peripherals to the system. The most common set of peripherals is the Varvara system, which adds everything you need to make the CPU into an actual computer: a screen, keyboard and mouse input, audio, etc.
To keep the Uxn implementation generic, I defined a trait for a device:
/// Trait for a Uxn-compatible device
pub trait Device {
    /// Performs the `DEI` operation for the given target
    ///
    /// This function must write its output byte to `vm.dev[target]`; the CPU
    /// evaluation loop will then copy this value to the stack.
    fn dei(&mut self, vm: &mut Uxn, target: u8);    /// Performs the `DEO` operation on the given target
    ///
    /// The input byte will be written to `vm.dev[target]` before this function
    /// is called, and can be read by the function.
    ///
    /// Returns `true` if the CPU should keep running, `false` if it should
    /// exit.
    #[must_use]
    fn deo(&mut self, vm: &mut Uxn, target: u8) -> bool;
}
The opcode implementation takes a `&mut dyn Device`, i.e. something implementing this trait, and calls trait methods on it:
pub fn deo<const FLAGS: u8>(
    vm: &mut Uxn,
    dev: &mut dyn Device,
    pc: u16,
) -> Option<u16> {
    let mut s = vm.stack_view::<FLAGS>();
    let i = s.pop_byte();
    let mut run = true;
    match s.pop() {
        Value::Short(v) => {
            let [lo, hi] = v.to_le_bytes();
            let j = i.wrapping_add(1);
            vm.dev[usize::from(i)] = hi;
            run &= dev.deo(vm, i);
            vm.dev[usize::from(j)] = lo;
            run &= dev.deo(vm, j);
        }
        Value::Byte(v) => {
            vm.dev[usize::from(i)] = v;
            run &= dev.deo(vm, i);
        }
    }
    if run {
        Some(pc)
    } else {
        None
    }
}
However, this function is not compatible with the C ABI – it's both generic and takes a trait object – so it can't be called directly from the `DEO`opcode in assembly.
To let my opcodes call `DEO` and `DEI` functions, I again wrote a bunch of shims:
#[no_mangle]
extern "C" fn deo_entry(vm: &mut Uxn, dev: &mut DeviceHandle) -> bool {
vm.deo::<0b000>(dev.0, 0).is_some()
}#[no_mangle]
extern "C" fn deo_2_entry(vm: &mut Uxn, dev: &mut DeviceHandle) -> bool {
vm.deo::<0b001>(dev.0, 0).is_some()
}
#[no_mangle]
extern "C" fn deo_r_entry(vm: &mut Uxn, dev: &mut DeviceHandle) -> bool {
vm.deo::<0b010>(dev.0, 0).is_some()
}
// etc, 16 functions in total for all DEI / DEO variants
The full path of the function looks something like this:
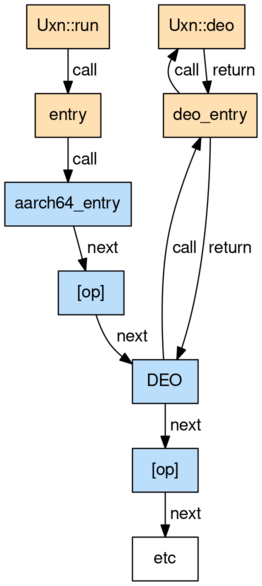
On the assembly side, there's one subtlety: during our normal opcode processing, we keep data and return stack index values in `x1` and `x3` (leaving the original values in the `&mut Uxn` unchanged). We have to write those registers back into the appropriate memory locations in the `&mut Uxn` before calling a function that expects those values to be correct.
Here's the assembly code to call into our shim functions:
.global _DEI
_DEI:
    ; We have to write our stack index pointers back into the &mut Uxn
    ldp x11, x12, [sp, 0x10] ; restore stack index pointers
    strb w1, [x11]   ; modify stack index pointer
    strb w3, [x12]   ; modify return stack index pointer    ; We're using caller-saved registers, so we have to back them up
    stp x0, x1, [sp, #0x20] ; store register state
    stp x2, x3, [sp, #0x30]
    stp x5, x4, [sp, #0x40]
    stp x6, x7, [sp, #0x50]
    str x8,     [sp, #0x60]    ; set up our arguments, then call the shim function:
    mov x0, x6 ; x0 = Uxn pointer
    mov x1, x7 ; x1 = DeviceHandle pointer
    bl _dei_entry    ldp x0, x1, [sp, #0x20] ; restore register state
    ldp x2, x3, [sp, #0x30]
    ldp x5, x4, [sp, #0x40]
    ldp x6, x7, [sp, #0x50]
    ldr x8,     [sp, #0x60]    ; The DEO operation may have changed stack pointers, so reload them here
    ldp x11, x12, [sp, 0x10]
    ldrb w1, [x11]  ; update stack index pointer
    ldrb w3, [x12]  ; update return stack index pointer
    next
Performance
I used two CPU-heavy workloads to test interpreter performance:
Both of these programs do all of their computation at startup, so I added instrumentation to print time spent in the entry vector (at `0x100`).
There are four different implementations being tested here:
Here are the performance numbers that you've been waiting for:
| Interpreter | Target | Fibonacci | Mandelbrot | | -------------------- | ------- | --------- | ---------- | | uxnemu (reference) | AArch64 | 1.57 s | 2.03 s | | raven-uxn (baseline) | AArch64 | 1.38 s | 1.56 s | | raven-uxn (assembly) | AArch64 | 1.00 s | 1.10 s | | raven-uxn (baseline) | wasm32 | 2.54 s | 2.82 s |
There are three clear trends:
Ablation testing
It's not obvious whether the speedup is due to keeping values in registers, or adding dispatch to the end of each opcode (instead of a central branch).
We can easily test for the latter by changing our `next` macro:
.macro next
    b next_dispatch
.endm
next_dispatch:
    ldrb w9, [x4, x5]
    add x5, x5, #1
    and x5, x5, #0xffff
    ldr x10, [x8, x9, lsl #3]
    br x10
Adding these new results to the chart( as "assembly\*"), here's what I see:
| Interpreter | Target | Fibonacci | Mandelbrot | | ---------------------- | ------- | --------- | ---------- | | raven-uxn (baseline) | AArch64 | 1.38 s | 1.56 s | | raven-uxn (assembly) | AArch64 | 1.00 s | 1.10 s | | raven-uxn (assembly\*) | AArch64 | 1.34 s | 1.41 s |
Centralized dispatch is a significant slowdown, and is nearly as slow as the baseline interpreter! It just goes to show: do not taunt happy fun branch predictor.
Things that didn't work
I did a bunch of other experiments, which didn't make things faster:
Conclusion
I've proven to my satisfaction that writing an interpreter in assembly is both fun and performant!
There are strategies to get similar performance in high-level languages: using computed gotoand the Massey Meta Machineare both relevant prior art.
However, neither of these are feasible in Rust; to quote this excellent writeup.
At this time there is no portable way to produce computed gotos or tail call optimization in compiled machine code from Rust.
On a brighter note, it should be relatively easy to port all of the assembly code to x86-64, but I'll leave that as a challenge for someone else!
All of the relevant code is on Github, gated by the `native` feature. The `uxn-cli` and `uxn-gui` executables both accept a `--native` flag to select the assembly interpreter backend.
Have fun!
Post-publication notes
This post was discussed on Hacker News; I particularly enjoyed phire's deep dive into branch predictionon the M1.
Dan Cross managed to persuade the system to branch into `aarch64_entry` from an `asm!` block (instead of calling it as a function), which lets us remove the `EntryHandle` shim. Here's the commit.
He also suggested moving the `JUMP_TABLE` into assembly, implemented here; this is a good change, because it removes a bunch of nominally `extern "C"`functions (which are nothing of the sort) from the Rust code.
On Cliff's's suggestion, I tested prefetching the next opcode from RAM at the beginning of the instruction (for instructions that do not jump or modify RAM), instead of at the end (in `next`). The thought here was to eliminate load-store hazards, since the processor doesn't know that writing to the stack (in `x0`) will not modify RAM (in `x4`). Unfortunately, this was not any faster!
Dan also tested storing the program counter as a (wrapping) pointer in this PR, but reported a slowdown.